
P.S. Free 2026 Amazon Data-Engineer-Associate dumps are available on Google Drive shared by Pass4guide: https://drive.google.com/open?id=1papgNv2lzjlGfsL1o_-ykJQeQcRQXWsl
As we all know, if you want to pass the Data-Engineer-Associate exam, you need to have the right method of study, plenty of preparation time, and targeted test materials. However, most people do not have one or all of these. That is why I want to introduce our Data-Engineer-Associate Original Questions to you. So why not try our Amazon original questions, which will help you maximize your pass rate? Even if you unfortunately fail to pass the exam, we will give you a full refund.
| Section | Weight | Objectives |
|---|---|---|
| Data Store Management | 26% | - Select appropriate data storage solutions - Optimize storage performance and cost |
| Data Operations and Support | 22% | - Monitor and maintain data pipelines - Troubleshoot data workflow issues |
| Data Security and Governance | 18% | - Apply governance and compliance best practices - Implement data security controls |
| Data Ingestion and Transformation | 34% | - Ingest and transform data using AWS services - Build and manage data pipelines |
>> Data-Engineer-Associate Exam Dumps.zip <<
If you want to take Amazon Data-Engineer-Associate exam, Pass4guide Amazon Data-Engineer-Associate exam dumps are your best tools. The dumps can help you pass Data-Engineer-Associate test easily. And the dumps are very highly regarded. With our test questions and test answers, you don't need to worry about Data-Engineer-Associate Certification. Because our dumps can solve all difficult problems you encounter in the process of preparing for the exam. Before you make a decision, you can download our free demo. For this, you will know whether our questions and answers fit to you or not.
NEW QUESTION # 78
A healthcare company stores patient records in an on-premises MySQL database. The company creates an application to access the MySQL database. The company must enforce security protocols to protect the patient records. The company currently rotates database credentials every 30 days to minimize the risk of unauthorized access.
The company wants a solution that does not require the company to modify the application code for each credential rotation.
Which solution will meet this requirement with the least operational overhead?
Answer: D
Explanation:
The correct solution is C: AWS Secrets Manager.
* Why? AWS Secrets Manager is a fully managed service that helps you protect access to your applications, services, and IT resources without the upfront cost and complexity of managing your own hardware security module (HSM) infrastructure.
* It allows for automatic rotation of secrets without requiring changes to the application code, meeting the requirement of minimal operational overhead.
* Applications can securely retrieve credentials using Secrets Manager APIs, and the service integrates with AWS Identity and Access Management (IAM) to control access to secrets.
"You can use Secrets Manager to store credentials and to configure automatic rotation." Reference: AWS Certified Data Engineer - Associate Study Guide, Chapter 7 - Data Security and GovernanceAlso verified in AWS Documentation: https://docs.aws.amazon.com/secretsmanager/latest
/userguide/rotating-secrets.html
NEW QUESTION # 79
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?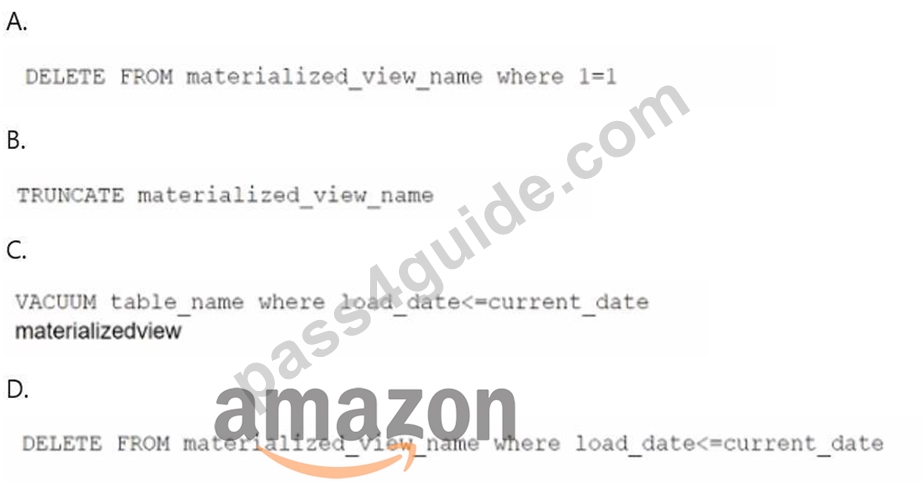
Answer: C
Explanation:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use aDELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as1=1.This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
* Option A: DELETE FROM materialized_view_name WHERE 1=1;This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
References:
Amazon Redshift Materialized Views Documentation
Deleting Data from Redshift
NEW QUESTION # 80
A company needs a solution to store and query product data that has variable attributes. The solution must support unpredictable and high-volume queries with single-digit millisecond latency, even during sudden traffic spikes. The solution must retrieve items by a primary identifier named Product ID. The solution must allow flexible queries by secondary attributes named Category and Brand.
Which solution will meet these requirements?
Answer: A
Explanation:
Option A is the correct design for single-digit millisecond latency with unpredictable spikes and variable attributes. The study material describes Amazon DynamoDB as a NoSQL database "designed for highly dynamic datasets with frequent read and write operations," providing low-latency performance at any scale
-which directly matches the latency and traffic-spike requirements.
DynamoDB's key-value and document model fits "product data that has variable attributes" because items can contain different attributes without needing schema migrations typical of relational databases. The requirement to retrieve items by Product ID maps naturally to DynamoDB's primary key access pattern.
The requirement for flexible queries on Category and Brand is met by creating global secondary indexes (GSIs) on those attributes so queries can be served efficiently without scanning the whole table.
Option B (Aurora) can scale reads, but it is not typically the best fit for sustained single-digit millisecond performance during sudden spikes without careful capacity planning. Option C is optimized for search and text/query relevance rather than primary-key transactional access patterns.
Option D uses Athena (interactive SQL over S3) which is not designed for millisecond-latency, high- QPS query workloads.
NEW QUESTION # 81
A media company wants to improve a system that recommends media content to customer based on user behavior and preferences. To improve the recommendation system, the company needs to incorporate insights from third-party datasets into the company's existing analytics platform.
The company wants to minimize the effort and time required to incorporate third-party datasets.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: D
Explanation:
AWS Data Exchange is a service that makes it easy to find, subscribe to, and use third-party data in the cloud. It provides a secure and reliable way to access and integrate data from various sources, such as data providers, public datasets, or AWS services. Using AWS Data Exchange, you can browse and subscribe to data products that suit your needs, and then use API calls or the AWS Management Console to export the data to Amazon S3, where you can use it with your existing analytics platform. This solution minimizes the effort and time required to incorporate third-party datasets, as you do not need to set up and manage data pipelines, storage, or access controls. You also benefit from the data quality and freshness provided by the data providers, who can update their data products as frequently as needed12.
The other options are not optimal for the following reasons:
B . Use API calls to access and integrate third-party datasets from AWS. This option is vague and does not specify which AWS service or feature is used to access and integrate third-party datasets. AWS offers a variety of services and features that can help with data ingestion, processing, and analysis, but not all of them are suitable for the given scenario. For example, AWS Glue is a serverless data integration service that can help you discover, prepare, and combine data from various sources, but it requires you to create and run data extraction, transformation, and loading (ETL) jobs, which can add operational overhead3.
C . Use Amazon Kinesis Data Streams to access and integrate third-party datasets from AWS CodeCommit repositories. This option is not feasible, as AWS CodeCommit is a source control service that hosts secure Git-based repositories, not a data source that can be accessed by Amazon Kinesis Data Streams. Amazon Kinesis Data Streams is a service that enables you to capture, process, and analyze data streams in real time, such as clickstream data, application logs, or IoT telemetry. It does not support accessing and integrating data from AWS CodeCommit repositories, which are meant for storing and managing code, not data .
D . Use Amazon Kinesis Data Streams to access and integrate third-party datasets from Amazon Elastic Container Registry (Amazon ECR). This option is also not feasible, as Amazon ECR is a fully managed container registry service that stores, manages, and deploys container images, not a data source that can be accessed by Amazon Kinesis Data Streams. Amazon Kinesis Data Streams does not support accessing and integrating data from Amazon ECR, which is meant for storing and managing container images, not data .
Reference:
1: AWS Data Exchange User Guide
2: AWS Data Exchange FAQs
3: AWS Glue Developer Guide
: AWS CodeCommit User Guide
: Amazon Kinesis Data Streams Developer Guide
: Amazon Elastic Container Registry User Guide
: Build a Continuous Delivery Pipeline for Your Container Images with Amazon ECR as Source
NEW QUESTION # 82
A data engineer uploads unpredictable volumes of unstructured data to an Amazon S3 bucket throughout the day. The data engineer needs to transform the data by using complex processing logic that takes from 5 to 30 minutes to complete. The solution must automatically scale with incoming data volume and process each uploaded file only one time.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: C
Explanation:
The correct answer is B because the workload requires complex processing that can run for 5 to 30 minutes, automatic scaling, and exactly-once-style avoidance of reprocessing source files. AWS Glue jobs are designed for serverless ETL processing over S3 data, and job bookmarks track previously processed source data so the job processes only new data on later runs. AWS documentation states that Glue job bookmarks help prevent reprocessing of old data and can track S3 source files for supported formats. Lambda is a poor fit because it has execution-duration limits and is not ideal for 30-minute complex transformations. EMR and EC2 polling add cluster and infrastructure management. Glue jobs with bookmarks provide the least operational overhead for this data engineering pattern.
NEW QUESTION # 83
......
Our company has collected the frequent-tested knowledge into our practice materials for your reference according to our experts’ years of diligent work. So our Data-Engineer-Associate exam materials are triumph of their endeavor. By resorting to our Data-Engineer-Associate Practice Guide, we can absolutely reap more than you have imagined before. We have clear data collected from customers who chose our Data-Engineer-Associate training engine, the passing rate is 98-100 percent.
Latest Data-Engineer-Associate Exam Topics: https://www.pass4guide.com/Data-Engineer-Associate-exam-guide-torrent.html
What's more, part of that Pass4guide Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1papgNv2lzjlGfsL1o_-ykJQeQcRQXWsl