ちなみに、CertJuken DP-100の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1-RchVwpqtO53emEu6zTyaeq4rV1W1vuA
学習資料が時代に遅れないようにしながら、DP-100学習の質問をより専門的にするために多数の専門家を選択しました。もちろん、必要な情報を取得するためにすべてを行っており、より迅速に進めることができます。また、DP-100試験トレーニングプロフェッショナルからいつでもサポートを受けることができます。私たちは、DP-100テストガイドの専門家の助けを借りて、確実に非常に良い経験を得ることを確信できます。優れた材料と方法は、より少ない労力でより多くの成果を上げるのに役立ちます。 DP-100テストガイドを選択して、成功に近づけましょう!
DP-100試験は、Azureでデータサイエンスソリューションを設計および実装する候補者の能力の包括的な評価です。この試験では、データの調査と準備、モデリング、機能エンジニアリング、機械学習アルゴリズム、展開など、幅広いトピックをカバーしています。この試験では、Azure Machine Learning、Azure Databricks、Azure Cognitive ServicesなどのAzureサービスを扱う候補者の能力もテストしています。
Microsoft DP-100試験は、Azureツールとサービスを使用してエンドツーエンドのデータサイエンスソリューションを構築する候補者の習熟度を測定するように設計されています。この試験では、データの摂取と処理、データストレージと管理、モデルトレーニングと評価、モデルの展開と管理など、幅広いトピックをカバーしています。候補者は、Azure Machine Learningを使用してモデルを作成および展開する能力と、Azure Data Factory、Azure Databricks、Azure Stream Analyticsなどの他のAzureサービスに関する知識を実証する必要があります。
>> Microsoft DP-100日本語版受験参考書 <<
調査によると、当社の高く評価されているDP-100テスト問題の成功は、簡単に操作できる練習システムへの尽力によるものです。候補者から寄せられたフィードバックのほとんどは、DP-100ガイド急流が優れたプラクティスとシステムを実装し、より競争力のある新しい製品を発売する能力を強化していることを物語っています。 DP-100試験ダンプに伴い、Q&Aはそれほど複雑ではありませんが、より重要な情報で受験者を教育します。これにより、DP-100試験に合格するための知識を深め、自己啓発を強化できます。
Microsoft DP-100認定試験は、データサイエンスの分野における候補者の知識と専門知識の包括的な評価です。この試験では、データの探索と準備、モデリング、機能エンジニアリング、トレーニングとチューニングモデル、Microsoft Azureのモデルの展開と管理など、幅広いトピックをカバーしています。この試験は、Azure Machine Learning、Azure Databricks、Azure HdinsightなどのMicrosoft Azure Data Servicesを使用して、データサイエンスソリューションを設計および実装する候補者の能力をテストするように設計されています。
質問 # 210
You run an experiment that uses an AutoMLConfig class to define an automated machine learning task with a maximum of ten model training iterations. The task will attempt to find the best performing model based on a metric named accuracy.
You submit the experiment with the following code:
You need to create Python code that returns the best model that is generated by the automated machine learning task. Which code segment should you use?
A)
B)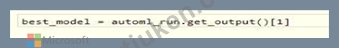
C)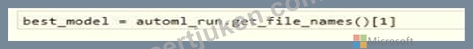
D)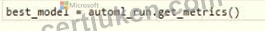
正解:D
質問 # 211
You are using Azure Machine Learning to train machine learning models. You need a compute target on which to remotely run the training script. You run the following Python code: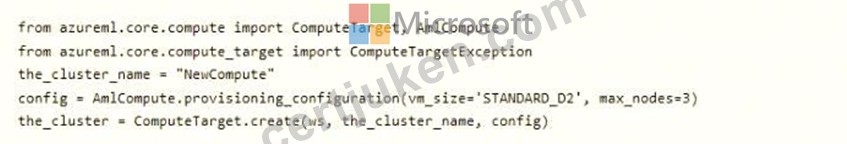
正解:
解説: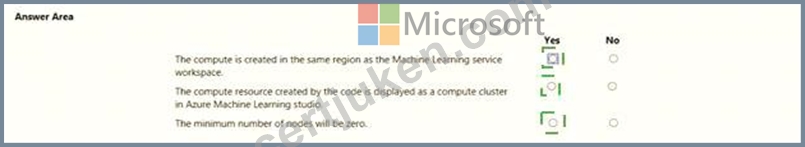
Explanation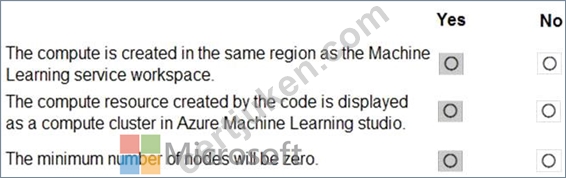
Box 1: Yes
The compute is created within your workspace region as a resource that can be shared with other users.
Box 2: Yes
It is displayed as a compute cluster.
View compute targets
1. To see all compute targets for your workspace, use the following steps:
2. Navigate to Azure Machine Learning studio.
3. Under Manage, select Compute.
4. Select tabs at the top to show each type of compute target.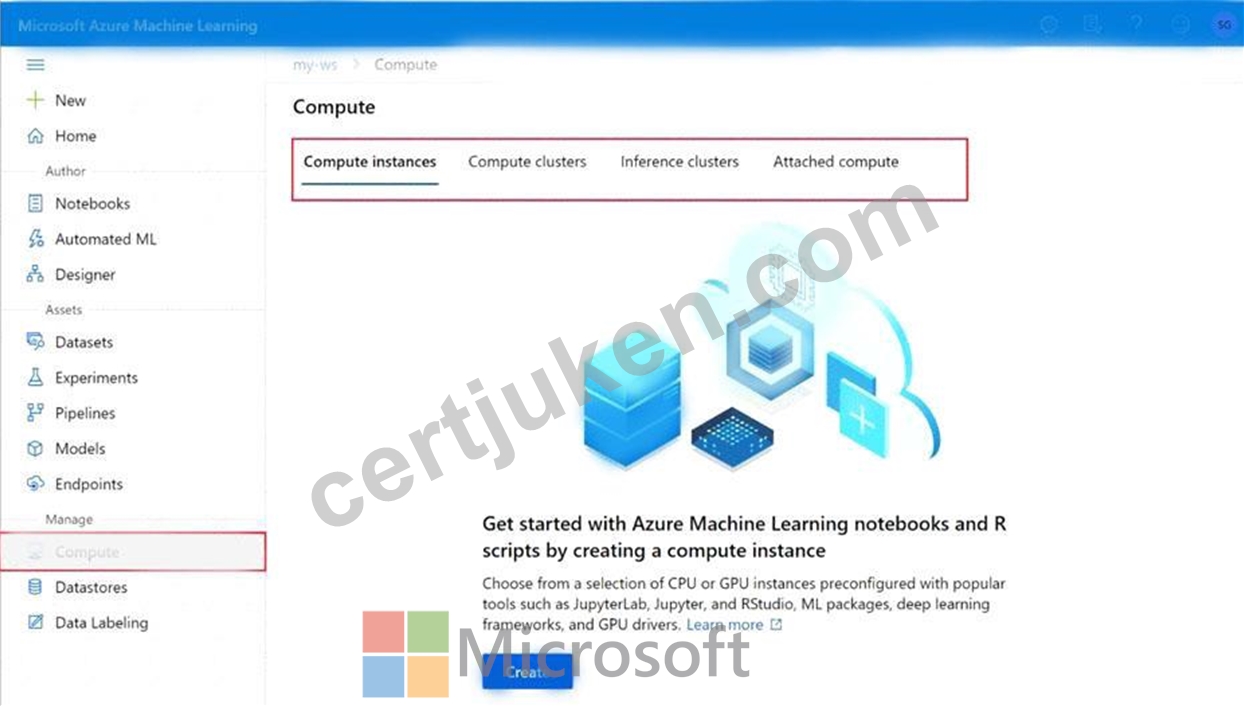
Box 3: Yes
min_nodes is not specified, so it defaults to 0.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-core/azureml.core.compute.amlcompute.amlcomputeprovis
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-create-attach-compute-studio
質問 # 212
You create an Azure Machine Learning dataset containing automobile price dat a. The dataset includes 10.000 rows and 10 columns. You use the Azure Machine Learning designer to transform the dataset by using an Execute Python Script component and custom code.
The code must combine three columns to create a new column.
You need to configure the code function.
Which configurations should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.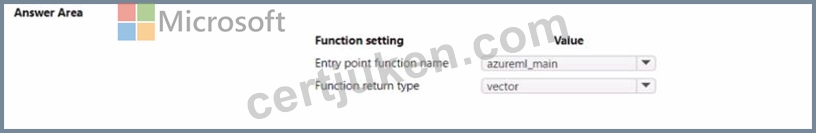
正解:
解説: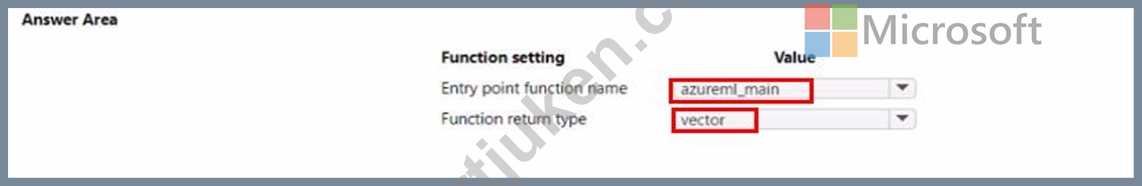
質問 # 213
You are performing sentiment analysis using a CSV file that includes 12,000 customer reviews written in a short sentence format. You add the CSV file to Azure Machine Learning Studio and configure it as the starting point dataset of an experiment. You add the Extract N-Gram Features from Text module to the experiment to extract key phrases from the customer review column in the dataset.
You must create a new n-gram dictionary from the customer review text and set the maximum n-gram size to trigrams.
What should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.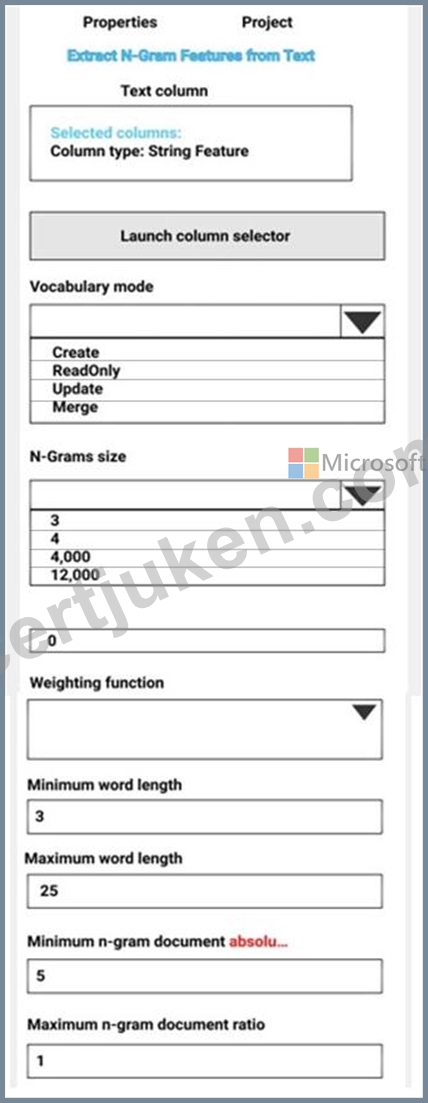
正解:
解説: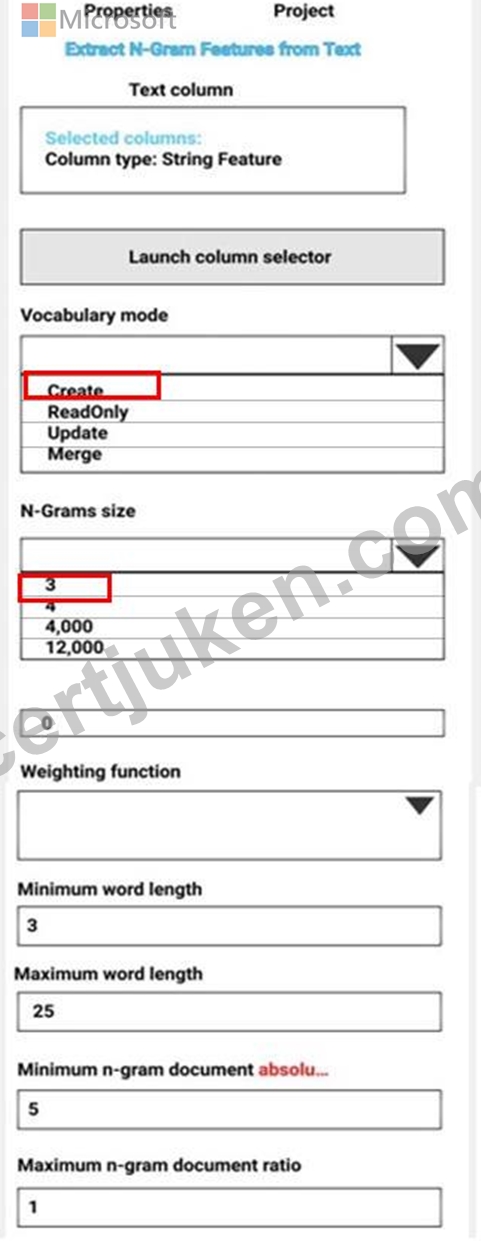
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/extract-n-gram-features-from-text
質問 # 214
You need to define a modeling strategy for ad response.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.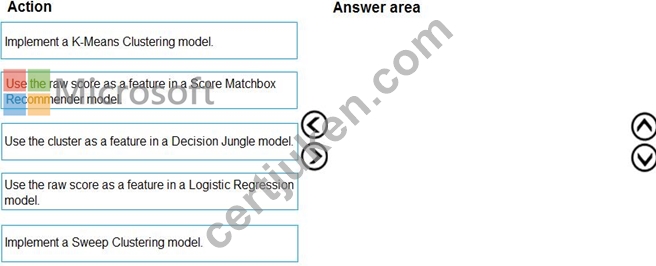
正解:
解説: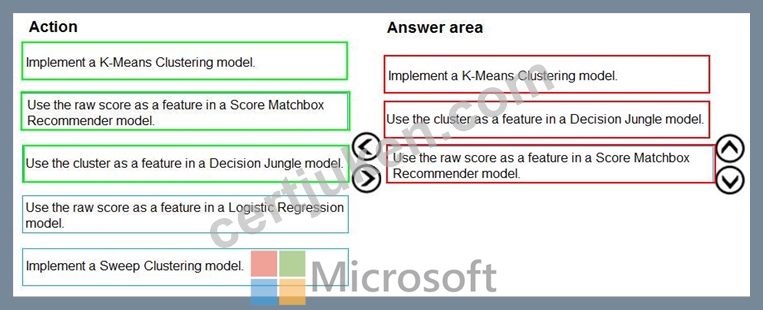
Explanation:
Step 1: Implement a K-Means Clustering model
Step 2: Use the cluster as a feature in a Decision jungle model.
Decision jungles are non-parametric models, which can represent non-linear decision boundaries.
Step 3: Use the raw score as a feature in a Score Matchbox Recommender model The goal of creating a recommendation system is to recommend one or more "items" to "users" of the system. Examples of an item could be a movie, restaurant, book, or song. A user could be a person, group of persons, or other entity with item preferences.
Scenario:
Ad response rated declined.
Ad response models must be trained at the beginning of each event and applied during the sporting event.
Market segmentation models must optimize for similar ad response history.
Ad response models must support non-linear boundaries of features.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/multiclass-decision-jungle
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/score-matchbox-recommender
質問 # 215
......
DP-100日本語版試験解答: https://www.certjuken.com/DP-100-exam.html
無料でクラウドストレージから最新のCertJuken DP-100 PDFダンプをダウンロードする:https://drive.google.com/open?id=1-RchVwpqtO53emEu6zTyaeq4rV1W1vuA