Our DP-800 study guide boosts both the high passing rate which is about 98%-100% and the high hit rate to have few difficulties to pass the test. Our DP-800 exam simulation is compiled based on the resources from the authorized experts’ diligent working and the Real DP-800 Exam and confer to the past years’ exam papers thus they are very practical. The content of the questions and answers of DP-800 exam quiz is refined and focuses on the most important information.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Developing AI-Enabled Database Solutions |
| Exam Number: | DP-800 |
| Exam Format: | Multiple select, Case studies, Multiple choice, Drag and drop, Build list |
| Related Certifications: | Microsoft Certified: SQL AI Developer Associate |
| Real Exam Qty: | 40-60 |
| Exam Price: | $165 USD |
| Available Languages: | Chinese (Simplified), Italian, French, Chinese (Traditional), Japanese, Korean, Portuguese (Brazil), Arabic (Saudi Arabia), German, Indonesian (Indonesia), English, Spanish |
| Exam Duration: | 100 minutes |
| Passing Score: | 700 |
| Certificate Validity Period: | 1 year |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or in-person at a testing center |
| Pre Condition: | No specific prerequisites, but candidates should have experience with SQL and a basic understanding of Azure services. Familiarity with AI or machine learning concepts is recommended. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/exams/dp-800/ |
Passing the DP-800 exam rests squarely on the knowledge of exam questions and exam skills. Our DP-800 training quiz has bountiful content that can fulfill your aims at the same time. We know high efficient DP-800 practice materials play crucial roles in your review. Our experts also collect with the newest contents of DP-800 Study Guide and have been researching where the exam trend is heading and what it really want to examine you.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 85
You have a SQL database in Microsoft Fabric that contains a table named WebSite. Logs. WebSite.Logs stores application telemetry data. Website.Logs contains a nvarehar(iMx) column named log that stores JSON documents You have a daily report that filters by the $.severity JSON property and returns Logld. LogDateTime, and log.
The report frequently causes full table scans.
You need to modify Website. Logs to support efficient filtering by $. severity and avoid key lookups for the columns returned by the report.
How should you complete the Transact-SQL code to avoid full table scans? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.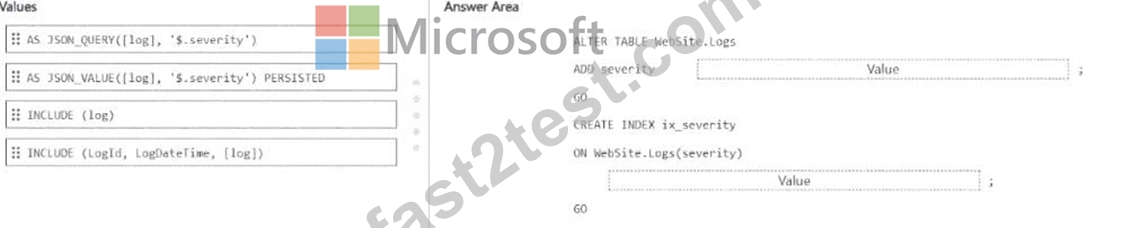
Answer:
Explanation: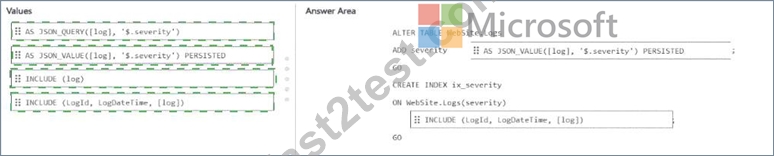
Explanation: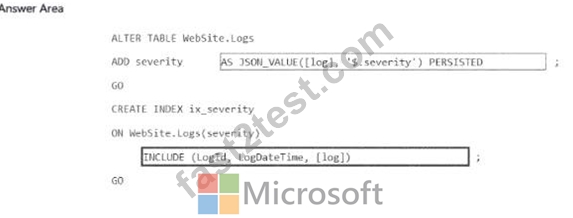
The correct way to avoid full table scans here is to add a computed column that extracts the JSON scalar property with JSON_VALUE , and then create a nonclustered index on that computed column with the report's returned columns in the INCLUDE list. Microsoft's JSON indexing guidance specifically recommends creating a computed column that exposes the JSON property you filter on, using the same expression as in the query, and then indexing that computed column.
So the computed column must be:
AS JSON_VALUE([log], ' $.severity ' ) PERSISTED
This is correct because $.severity is a scalar JSON value, so JSON_VALUE is the proper function.
JSON_QUERY would be for extracting an object or array, not a scalar property. Microsoft also notes that persisted computed columns can improve access speed for JSON-derived values.
The index should then include:
INCLUDE (LogId, LogDateTime, [log])
That is the right covering strategy because the report filters by severity but returns LogId, LogDateTime, and log. Microsoft's guidance on included columns explains that nonkey included columns let a nonclustered index cover more queries and reduce extra lookups to the base table.
So the completed code is:
ALTER TABLE WebSite.Logs
ADD severity AS JSON_VALUE([log], ' $.severity ' ) PERSISTED;
GO
CREATE INDEX ix_severity
ON WebSite.Logs(severity)
INCLUDE (LogId, LogDateTime, [log]);
GO
NEW QUESTION # 86
You are creating a table that will store customer profiles.
You have the following Transact-SQL code.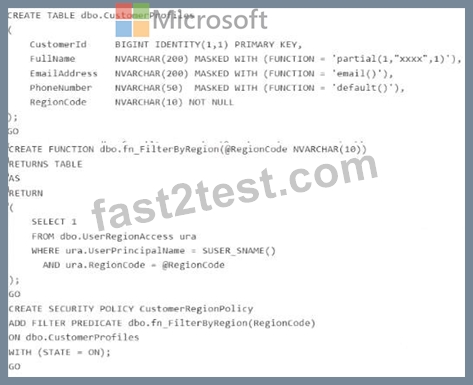
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection Is worth one point.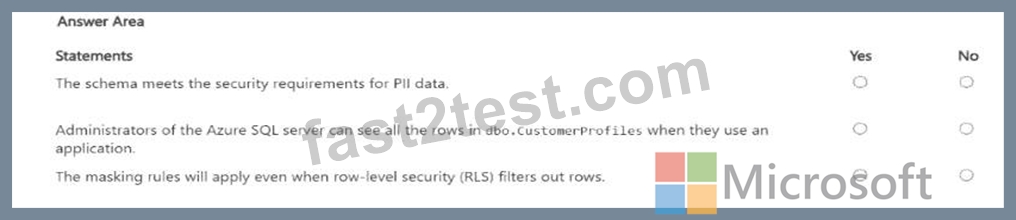
Answer:
Explanation: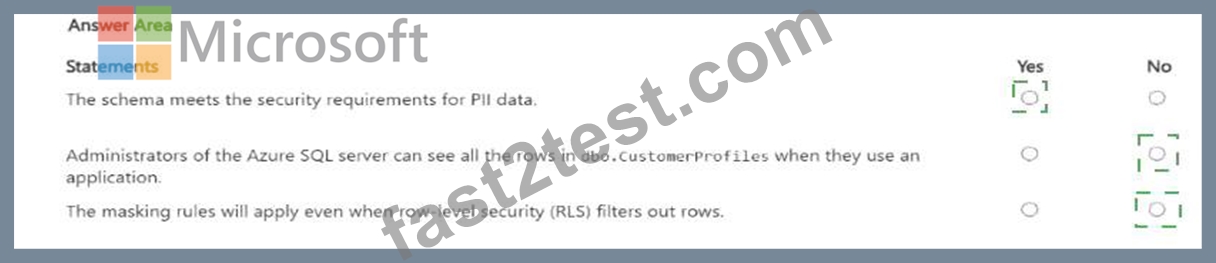
Explanation:
* The schema meets the security requirements for PII data. # Yes
* Administrators of the Azure SQL server can see all the rows in dbo.CustomerProfiles when they use an application. # No
* The masking rules will apply even when row-level security (RLS) filters out rows. # No The first statement is Yes because the design combines two relevant SQL security controls for personally identifiable information: Dynamic Data Masking (DDM) on sensitive columns such as FullName, EmailAddress, and PhoneNumber, and Row-Level Security (RLS) to restrict which rows a user can access based on RegionCode. Microsoft documents that DDM limits sensitive data exposure for nonprivileged users
, while RLS restricts row access according to the user executing the query. Together, these are valid and appropriate controls for protecting PII in Azure SQL Database.
The second statement is No . Administrative users can view unmasked data because administrative roles effectively have CONTROL, which includes UNMASK. However, that does not mean they automatically see all rows through the application query path defined by the RLS policy. The security policy filters rows based on SUSER_SNAME() and matching RegionCode, so row visibility is governed by the predicate unless the policy is altered or bypassed administratively. DDM and RLS solve different problems: DDM affects how returned values are shown, while RLS affects which rows are returned at all.
The third statement is No because masking only applies to data that is actually returned in the query result set.
Microsoft describes DDM as hiding sensitive data in the result set of a query . If RLS filters a row out, that row is not returned, so there is nothing left for masking to act on. In other words, RLS eliminates inaccessible rows first from the user's perspective, and DDM masks sensitive column values only on rows the user is allowed to see.
NEW QUESTION # 87
You have an Azure SQL database that contains a table named dbo.Orders.
You have an application that calls a stored procedure named dbo.usp_tresteOrder to insert rows into dbo.
Orders.
When an insert fails, the application receives inconsistent error details.
You need to implement error handling to ensure that any failures inside the procedure abort the transaction and return a consistent error to the caller.
How should you complete the stored procedure? To answer, drag the appropriate values to the correct targets, tach value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.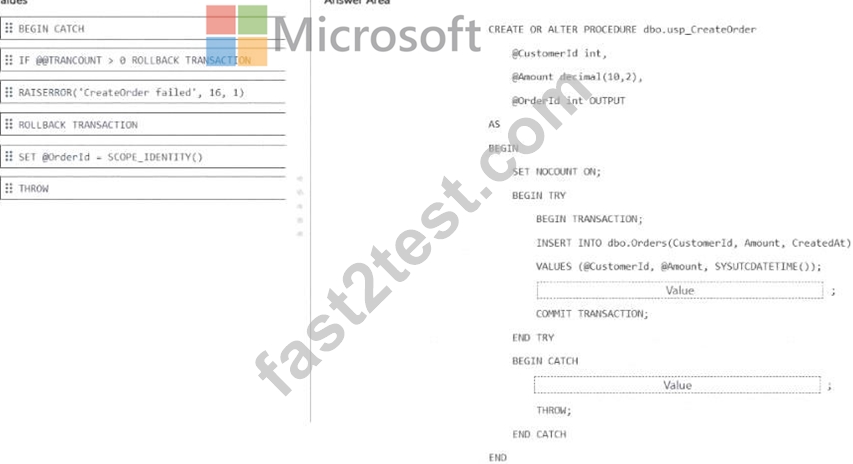
Answer:
Explanation: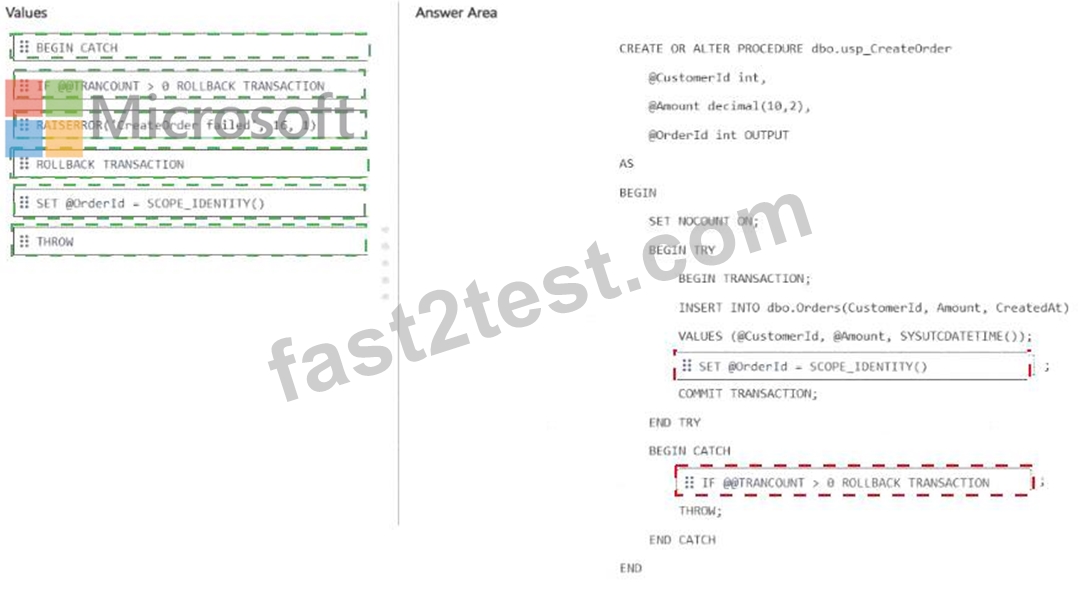
Explanation:
* After the INSERT # SET @OrderId = SCOPE_IDENTITY()
* Inside CATCH # IF @@TRANCOUNT > 0 ROLLBACK TRANSACTION
The correct drag-and-drop choices are:
* SET @OrderId = SCOPE_IDENTITY()
* IF @@TRANCOUNT > 0 ROLLBACK TRANSACTION
After the INSERT, the procedure should assign the newly generated identity value to the output parameter by using SCOPE_IDENTITY() . Microsoft documents that SCOPE_IDENTITY() returns the last identity value inserted in the same scope, which makes it the correct choice for returning the new OrderId from the procedure.
Inside the CATCH block, the procedure should use IF @@TRANCOUNT > 0 ROLLBACK TRANSACTION before THROW. This ensures any open transaction is rolled back only when one actually exists, which prevents transaction-state issues and guarantees the failure aborts the transaction cleanly.
Keeping THROW after the rollback is also the correct modern pattern because THROW re-raises the error to the caller with the original error information intact, giving consistent error behavior. This matches SQL Server best practice for TRY...CATCH transaction handling.
NEW QUESTION # 88
You have an Azure SQL database named DB1 that contains two tables named knowledgebase and query_cache. knowledge_base contains support articles and embeddings. query_cache contains chat questions, responses, and embeddings DB1 supports an Al-enabled chat agent.
You need to design a solution that meets the following requirements:
* Serializes the retrieved rows from knowledee_base
* Extracts the answer field from the response
* Extracts the embeddings to store in query_cache
You will call the external large language model (LLM) by using the sp_irwoke_external_re standpoint stored procedure.
Which Transact-SGL commands should you use for each requirement? To answer, drag the appropriate commands to the correct requirements. Each command may be used once, mote than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.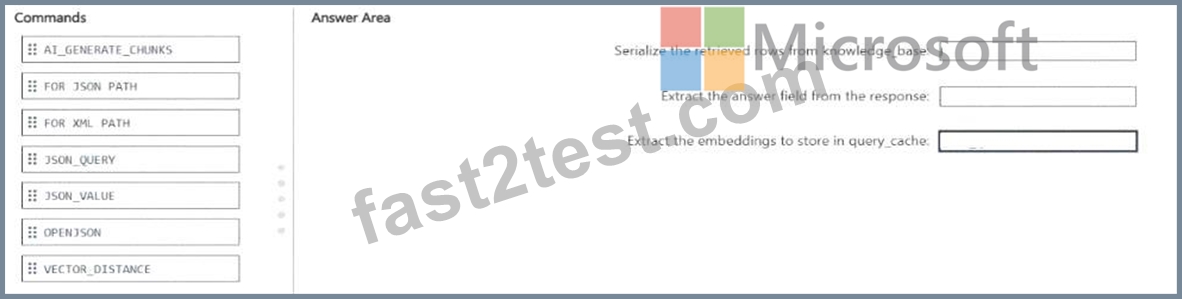
Answer:
Explanation: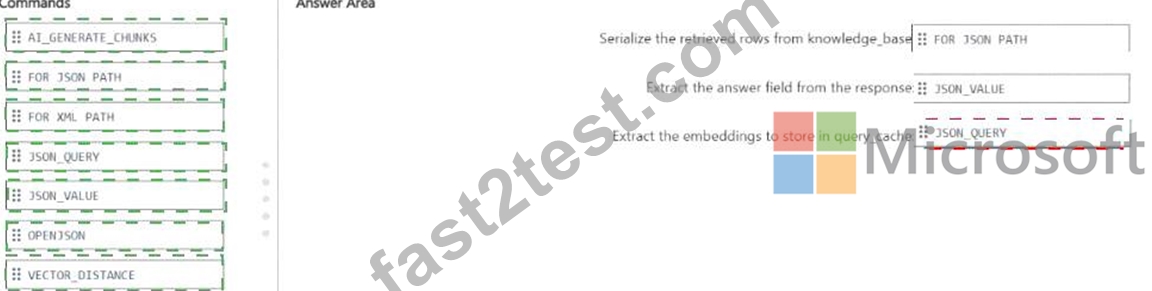
Explanation: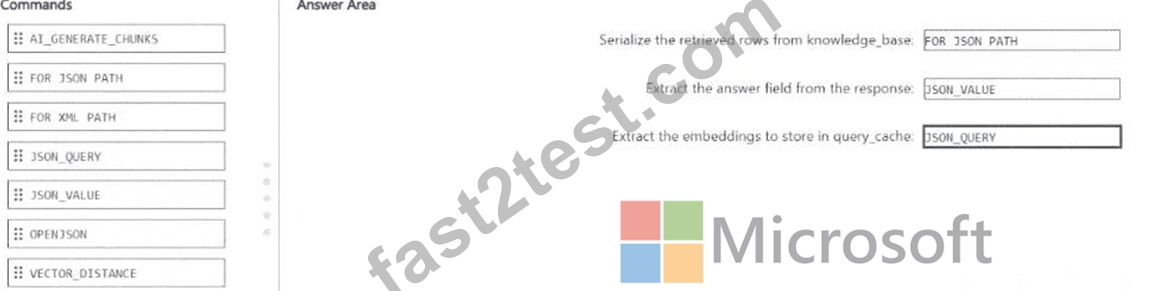
The correct mapping is:
* FOR JSON PATH
* JSON_VALUE
* JSON_QUERY
To serialize the retrieved rows from knowledge_base , the correct command is FOR JSON PATH .
Microsoft documents that FOR JSON formats query results as JSON, and PATH mode is the standard way to shape relational rows into JSON for downstream application or AI use.
To extract the answer field from the response , the correct command is JSON_VALUE because answer is a single scalar field . Microsoft states that JSON_VALUE is used to extract a scalar value from JSON text.
To extract the embeddings to store in query_cache , the correct command is JSON_QUERY because embeddings are returned as a JSON array , not a scalar. Microsoft states that JSON_QUERY extracts an object or array from JSON text, which is exactly the right behavior for an embeddings payload.
The unused options are not the best fit here:
* OPENJSON is mainly for shredding JSON into rows and columns.
* AI_GENERATE_CHUNKS is for chunking text, not extracting fields from a response payload.
* VECTOR_DISTANCE computes similarity between vectors and is unrelated to JSON extraction.
* FOR XML PATH produces XML, not JSON.
NEW QUESTION # 89
You are developing an Azure SQL database solution from a locally cloned GitHub repository by using Microsoft Visual Studio Code and GitHub Copilot Chat.
You need to ensure that GitHub Copilot Chat can call the hosted GitHub MCP Server tools by using OAuth. The MCP server configuration must be scoped to the repository.
What should you do in Visual Studio Code?
Answer: A
Explanation:
To connect GitHub Copilot Chat to an Azure SQL Database using a hosted GitHub MCP (Model Context Protocol) Server, follow these steps. This setup ensures that Copilot can interact directly with your repository and database schema using OAuth.
Step 1: Configure the MCP Server in VS Code
You must set the scope to the Workspace level to ensure the server is restricted to your specific repository.
Open your locally cloned GitHub repository in VS Code.
Open the Command Palette (Ctrl+Shift+P or Cmd+Shift+P).
Type and select: MCP: Add Server.
Select HTTP (HTTP or Server-Sent Events).
Enter the URL: https://api.githubcopilot.com/mcp/
Crucial: When prompted for the configuration scope, select Workspace Settings.
This saves the config to .vscode/settings.json, binding the server to this repo.
Step 2: Authenticate via OAuth
Once the server is added, Copilot needs permission to act on your behalf.
Open the GitHub Copilot Chat panel.
You will see a notification or a prompt within the chat asking to Authorize the MCP server.
Follow the browser prompts to sign in and grant OAuth permissions.
This allows the hosted MCP server to "see" your repository's code and metadata.
Reference:
https://skywork.ai/skypage/en/The-Ultimate-Guide-to-GitHub's-MCP-Server:-Bridging-AI-and- Your-Codebase/1970685991323758592
NEW QUESTION # 90
......
DP-800 Reliable Exam Test: https://www.fast2test.com/DP-800-premium-file.html