BONUS!!! Download part of Prep4SureReview AI-200 dumps for free: https://drive.google.com/open?id=15w53A_nOm-T-vF2chYDku9tgs1BRJpJ-
There is no doubt that if you pass the AI-200 exam certification test, which means that your ability and professional knowledge are acknowledged by the authority field, we suggest that you can try our AI-200 reliable exam dumps. Although it is difficult to prepare the exam for most people, as long as you are attempting our AI-200 Exam Dumps, you will find that it is not as hard as you think. What you will never worry about is that the quality of AI-200 exam dumps, because once you haven’t passed exam, we will have a 100% money back guarantee. You can easily pass the exam only if you spend some spare time studying our AI-200 materials.
| Section | Objectives |
|---|---|
| Plan and manage Azure AI solutions | - Plan security and compliance requirements - Monitor and optimize AI solutions - Select appropriate Azure AI services |
| Implement Azure AI solutions | - Implement knowledge mining with Azure AI Search - Implement generative AI solutions using Azure OpenAI - Implement natural language processing solutions - Implement computer vision solutions |
| Implement and monitor AI workloads | - Deploy AI models and services - Monitor performance and troubleshoot issues |
>> Reliable AI-200 Exam Cram <<
Our experts update the AI-200 training materials every day and provide the latest update timely to you. If you have the doubts or the questions about our product and the purchase procedures you can contact our online customer service personnel at any time. We provide the discounts to the old client and you can have a free download and tryout of our AI-200 Test Question before your purchase. So there are many merits of our product. Read the introduction of the characteristics and the functions of our AI-200 practice test as follow carefully before you purchase our product.
NEW QUESTION # 126
You need to address the known issue resulting from vector similarity queries.
Which two actions should you perform? Each correct answer presents part of the solution. Choose two.
NOTE: Each correct selection is worth one point.
Answer: B,D
Explanation:
Detailed Explanation: The objective is to reduce RU consumption from vector similarity queries. Microsoft guidance identifies vector numeric precision and vector-index selection as major cost and performance levers.
Using a lower supported vector precision can reduce storage and processing cost, while quantizedFlat and DiskANN are designed to reduce latency and RU consumption compared with flat search for appropriate data sizes. Strong consistency would increase resource cost rather than solve vector-search efficiency. A regular composite index is not a substitute for the vector index. Option B should be read as reducing vector numeric precision, not changing a generic "indexing precision" setting.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector search in Azure Cosmos DB | Optimize Cosmos DB vector search performance
Topic 1 : Proseware Inc. Case Study 7
Topic 2 : Fabrikam Inc 8
Topic 3 : Standalone Questions Set 127
TOTAL 142
Topic 1, Proseware Inc. Case Study
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers. The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring:
* Telemetry generated by Azure resources is sent to Azure Monitor.
* A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
* Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version- controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known issues
RU consumption spikes during vector similarity queries.
NEW QUESTION # 127
You develop an ASP.NET Core app that uses Azure App Configuration. You also create an App Configuration containing 100 settings. The app must meet the following requirements:
* Ensure the consistency of all configuration data when changes to individual settings occur.
* Handle configuration data changes dynamically without causing the application to restart.
* Reduce the overall number of requests made to App Configuration APIs
You must implement dynamic configuration updates in the app.
What are two ways to achieve this goal? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: C,D
Explanation:
Detailed Explanation: A sentinel key allows the application to check one value and refresh all related configuration only when that sentinel changes, preserving a consistent set of settings instead of refreshing 100 keys independently. Increasing the refresh/cache interval reduces how frequently the application contacts App Configuration APIs. Together these measures support dynamic refresh without application restart while controlling request volume. Registering every key separately or decreasing the cache interval would increase API traffic, and Key Vault/environment variables do not solve coordinated App Configuration refresh.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Dynamic configuration in ASP.NET Core
NEW QUESTION # 128
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You are using Azure Monitor Application Insights to investigate a production API. You open the Logs blade and set the time range to Last 24 hours.
An engineer recommends the following query to count requests by result code and sort the results from most frequent to least frequent:
requests
| summarize request_count = count() by resultCode
| order by request_count desc
You need to determine whether the query returns the number of requests grouped by result code and sorted from most to least frequent.
Solution: The result codes are sorted alphabetically.
Does the solution meet the goal?
Answer: B
Explanation:
Correct:
* The query returns one row per unique resultCode value with the number of requests in each group.
The Kusto Query Language (KQL) query uses the summarize operator, which acts as a grouping and aggregation mechanism.
summarize request_count = count() by resultCode
This groups all the individual rows in the requests table by their unique resultCode. It then counts the total number of logs within each group and places that value into a new column called request_count.
order by request_count desc: This sorts those aggregated rows so that the resultCode with the highest number of requests appears at the top.
Incorrect:
* The result codes are sorted alphabetically.
* The query lists every individual request along with its result code.
Reference:
https://learn.microsoft.com/en-us/azure/azure-monitor/reference/tables/apprequests
NEW QUESTION # 129
You are developing an application that must extract structured field data (invoice number, total, vendor name) from scanned invoices in multiple layouts.
You need a solution that requires no custom model training.
What should you use?
Answer: B
Explanation:
Use the Azure AI Document Intelligence prebuilt invoice model . The prebuilt invoice model is specifically designed to analyze invoices and extract structured fields and line items without requiring an organization to train a custom model. Microsoft documents support for fields including InvoiceId , VendorName , InvoiceTotal , InvoiceDate, CustomerName, AmountDue, tax information, addresses, and invoice line items.
Because the model is pretrained to recognize common invoice structures, it can process invoices that use different layouts and formats while returning normalized structured output. This directly satisfies the requirement to extract invoice number, total, and vendor information from scanned documents while minimizing development and training effort.
The Azure AI Vision Read API performs OCR and can extract printed or handwritten text, but it does not provide invoice-specific semantic field extraction. Custom named entity recognition would require training and is designed for text entity extraction rather than document-layout understanding. A Document Intelligence custom neural model can handle organization-specific forms and layouts, but it requires custom model training, directly violating the requirement.
Therefore, the prebuilt invoice model provides the required combination of OCR, document understanding, structured extraction, and zero custom training.
Study Guide references: Azure AI Document Intelligence # prebuilt invoice model; structured field extraction; OCR; invoice fields and line items.
NEW QUESTION # 130
You are configuring sampling for a distributed application that sends traces to Azure Monitor. The solution must:
* Preserve upstream sampling decisions across distributed traces
* Capture all spans during local testing.
* Sample 10 percent of traces in production.
You need to apply the appropriate sampling configuration for each requirement.
What should you do? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once or not at all. You may need to move the split bar Between panes or scroll to view content.
NOTE: Each correct selection is worth one point.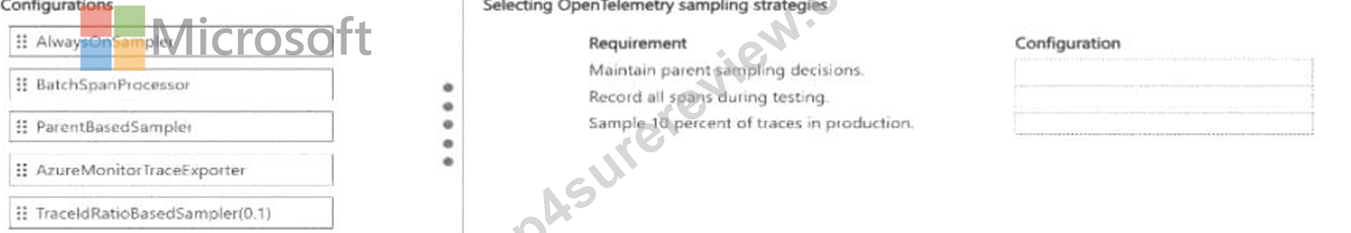
Answer:
Explanation: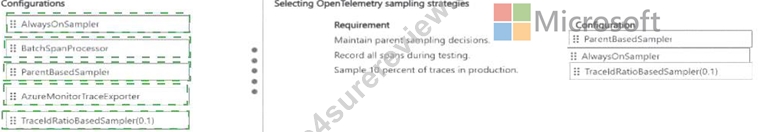
Explanation: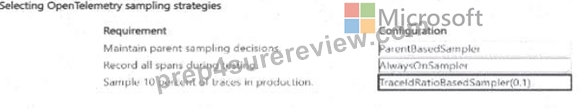
Verified Answer: Preserve parent sampling decisions: ParentBasedSampler. Capture all spans locally:
AlwaysOnSampler. Sample 10% in production: TraceIdRatioBasedSampler(0.1).
Detailed Explanation: Parent-based sampling propagates the sampling decision from the upstream parent, preventing broken sampling decisions across a distributed trace. AlwaysOnSampler records every span, which is suitable for local test environments where complete trace visibility is more important than telemetry volume. TraceIdRatioBasedSampler with 0.1 selects approximately ten percent of traces based on trace identifiers, providing deterministic fixed-ratio sampling for production. A batch span processor and an exporter control processing/export, not the sampling decision itself.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | OpenTelemetry sampling in Azure Monitor | Enable Azure Monitor OpenTelemetry
NEW QUESTION # 131
......
In the 21st century, all kinds of examinations are filled with the life of every student or worker. We need to pass some exams to get the corresponding certificates like AI-200 certification, so as to get the recognition of enterprises and society. However, passing an AI-200 Exam is not easy, and a large number of people fail to pass it every year, as is the case with the AI-200 exam. But if you choose to buy our AI-200 study materials, you will pass the exam easily.
Formal AI-200 Test: https://www.prep4surereview.com/AI-200-latest-braindumps.html
DOWNLOAD the newest Prep4SureReview AI-200 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=15w53A_nOm-T-vF2chYDku9tgs1BRJpJ-