BONUS!!! Download part of Getcertkey DP-700 dumps for free: https://drive.google.com/open?id=1TZokl0vp682yekL6vgZzCqrl2924iWVu
Getcertkey has a professional team of IT experts and certified trainers who written the DP-700 exam questions and valid exam prep according to the actual test. You can download the Microsoft free demo before you purchase. If you bought our DP-700 Exam PDF, you will be allowed to free update your dumps one-year. You just need to spend one or two days to practice questions and remember answers.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Data Engineering Solutions Using Microsoft Fabric |
| Exam Number: | DP-700 |
| Related Certifications: | Microsoft Certified: Power BI Data Analyst Associate Microsoft Certified: Azure Data Engineer Associate |
| Available Languages: | German, Spanish, Korean, English, Portuguese (Brazil), Japanese, French, Chinese (Simplified) |
| Exam Duration: | 100 minutes |
| Passing Score: | 700 (scaled score 100–1000) |
| Exam Price: | $165 USD |
| Real Exam Qty: | 50–60 |
| Exam Format: | Multiple select, Multiple choice, Scenario-based, Interactive items, Case studies |
| Certificate Validity Period: | 1 year |
| Recommended Training: | Microsoft Fabric Documentation Microsoft Learn: Implementing Data Engineering Solutions Using Microsoft Fabric |
| Exam Registration: | Microsoft Official Exam Registration Pearson VUE Registration |
| Sample Questions: | Microsoft DP-700 Sample Questions |
| Exam Way: | Online proctored or onsite testing center |
| Pre Condition: | No mandatory prerequisites; recommended experience with data integration, transformation, SQL, PySpark, KQL, and Microsoft Fabric |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/resources/study-guides/dp-700 |
It is an incredible opportunity among all candidates fighting for the desirable exam outcome to have our DP-700 practice materials. With the help of our hardworking experts, our DP-700 exam braindumps have been on the front-front of this industry and help exam candidates around the world win in valuable time. With years of experience dealing with exam, they have thorough grasp of knowledge which appears clearly in our DP-700 Actual Exam. To choose us is to choose success!
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 36
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.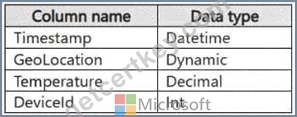
Reference contains reference data in the following format.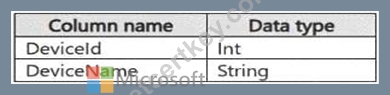
Both tables contain millions of rows.
You have the following KQL queryset.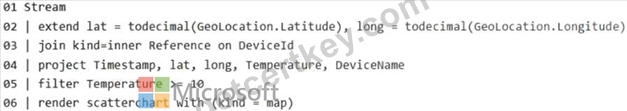
You need to reduce how long it takes to run the KQL queryset.
Solution: You move the filter to line 02.
Does this meet the goal?
Answer: B
Explanation:
Moving the filter to line 02: Filtering the Stream table before performing the join operation reduces the number of rows that need to be processed during the join. This is an effective optimization technique for queries involving large datasets.
NEW QUESTION # 37
HOTSPOT
You have a Fabric workspace that contains a warehouse named Warehouse1. Warehouse1 contains the following tables and columns.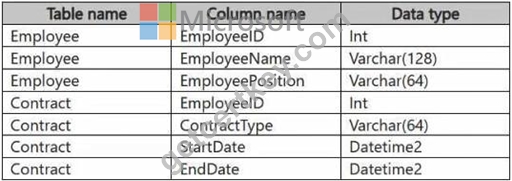
You need to denormalize the tables and include the ContractType and StartDate columns in the Employee table. The solution must meet the following requirements:
Ensure that the StartDate column is of the date data type.
Ensure that all the rows from the Employee table are preserved and include any matching rows from the Contract table.
Ensure that the result set displays the total number of employees per contract type for all the contract types that have more than two employees.
How should you complete the statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.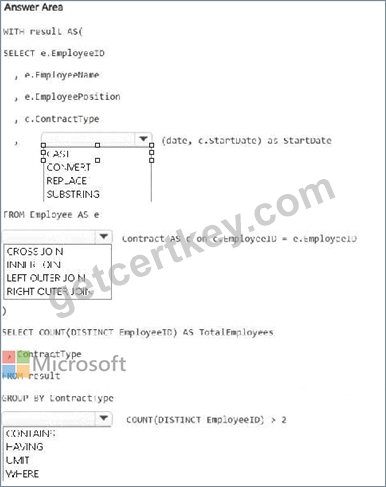
Answer:
Explanation: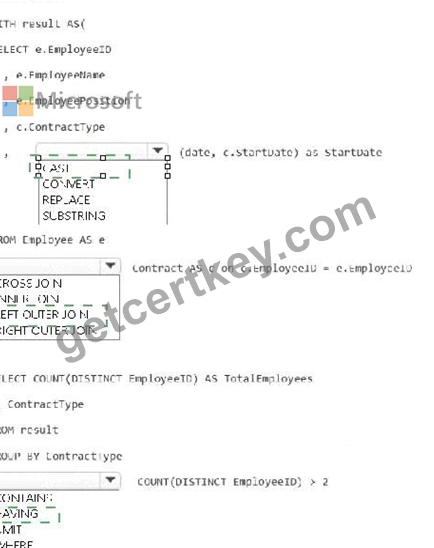
Explanation: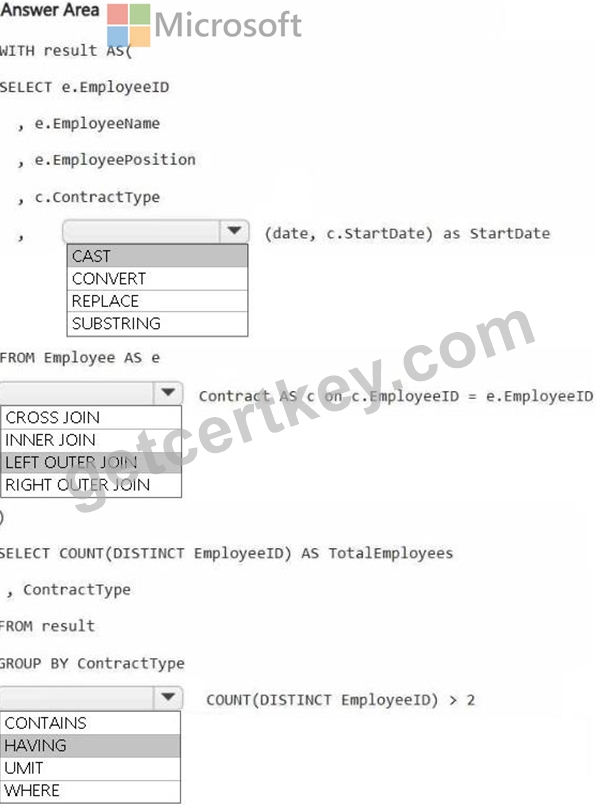
NEW QUESTION # 38
You have two Fabric notebooks named Load_Salesperson and Load_Orders that read data from Parquet files in a lakehouse. Load_Salesperson writes to a Delta table named dim_salesperson. Load.Orders writes to a Delta table named fact_orders and is dependent on the successful execution of Load_Salesperson.
You need to implement a pattern to dynamically execute Load_Salesperson and Load_Orders in the appropriate order by using a notebook.
How should you complete the code? To answer, drag the appropriate values the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.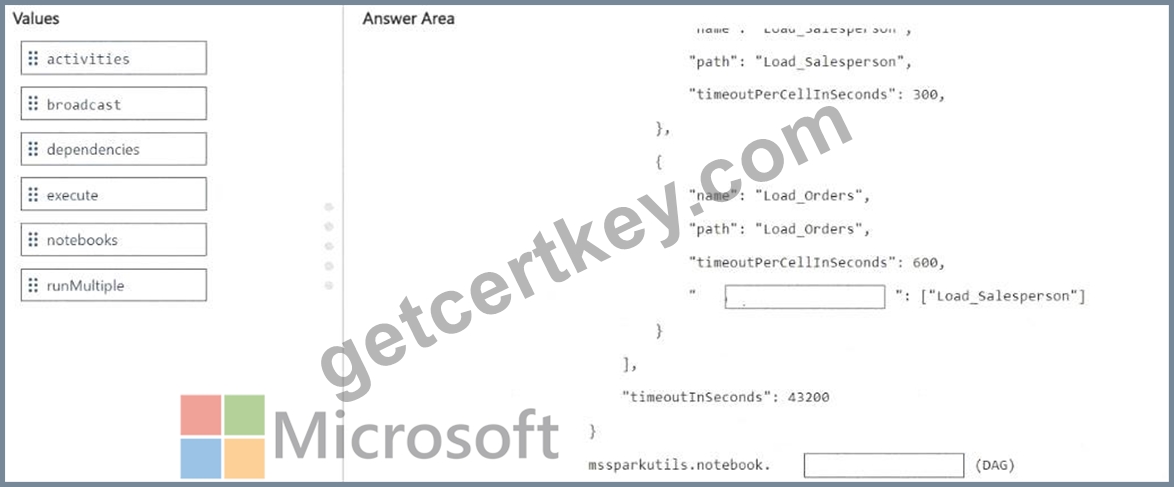
Answer:
Explanation: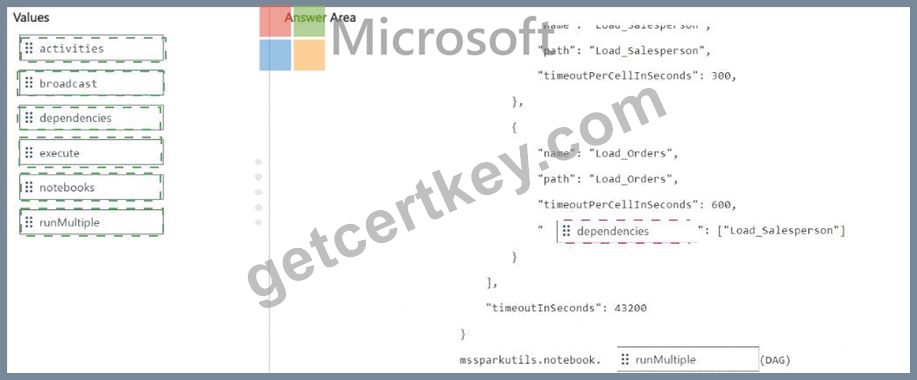
Explanation: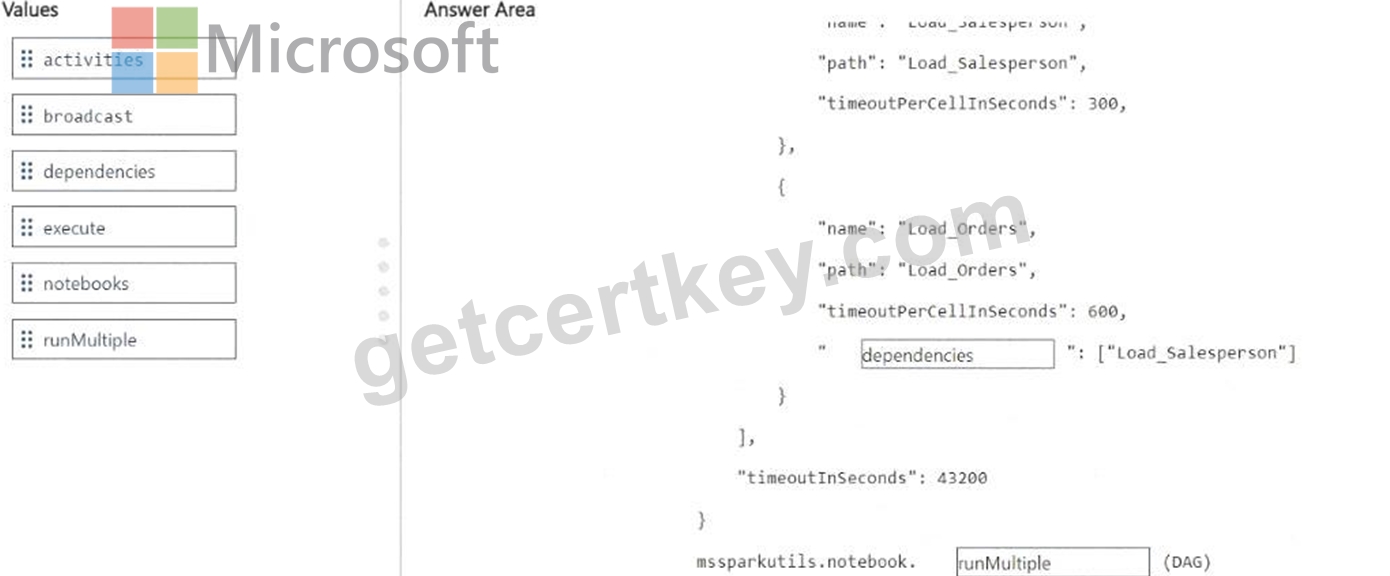
Topic 2, Contoso, LtdCase Study
This is a case study. Case studies are not timed separately. You can use as much exam time as you would like to complete each case. However, there may be additional case studies and sections on this exam. You must manage your time to ensure that you are able to complete all questions included on this exam in the time provided.
To answer the questions included in a case study, you will need to reference information that is provided in the case study. Case studies might contain exhibits and other resources that provide more information about the scenario that is described in the case study. Each question is independent of the other questions in this case study.
At the end of this case study, a review screen will appear. This screen allows you to review your answers and to make changes before you move to the next section of the exam. After you begin a new section, you cannot return to this section.
To start the case study
To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment, and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Overview. Company Overview
Contoso, Ltd. is an online retail company that wants to modernize its analytics platform by moving to Fabric.
The company plans to begin using Fabric for marketing analytics.
Overview. IT Structure
The company's IT department has a team of data analysts and a team of data engineers that use analytics systems.
The data engineers perform the ingestion, transformation, and loading of data. They prefer to use Python or SQL to transform the data.
The data analysts query data and create semantic models and reports. They are qualified to write queries in Power Query and T-SQL.
Existing Environment. Fabric
Contoso has an F64 capacity named Cap1. All Fabric users are allowed to create items.
Contoso has two workspaces named WorkspaceA and WorkspaceB that currently use Pro license mode.
Existing Environment. Source Systems
Contoso has a point of sale (POS) system named POS1 that uses an instance of SQL Server on Azure Virtual Machines in the same Microsoft Entra tenant as Fabric. The host virtual machine is on a private virtual network that has public access blocked. POS1 contains all the sales transactions that were processed on the company's website.
The company has a software as a service (SaaS) online marketing app named MAR1. MAR1 has seven entities. The entities contain data that relates to email open rates and interaction rates, as well as website interactions. The data can be exported from MAR1 by calling REST APIs. Each entity has a different endpoint.
Contoso has been using MAR1 for one year. Data from prior years is stored in Parquet files in an Amazon Simple Storage Service (Amazon S3) bucket. There are 12 files that range in size from 300 MB to 900 MB and relate to email interactions.
Existing Environment. Product Data
POS1 contains a product list and related data. The data comes from the following three tables:
Products
ProductCategories
ProductSubcategories
In the data, products are related to product subcategories, and subcategories are related to product categories.
Existing Environment. Azure
Contoso has a Microsoft Entra tenant that has the following mail-enabled security groups:
DataAnalysts: Contains the data analysts
DataEngineers: Contains the data engineers
Contoso has an Azure subscription.
The company has an existing Azure DevOps organization and creates a new project for repositories that relate to Fabric.
Existing Environment. User Problems
The VP of marketing at Contoso requires analysis on the effectiveness of different types of email content. It typically takes a week to manually compile and analyze the data. Contoso wants to reduce the time to less than one day by using Fabric.
The data engineering team has successfully exported data from MAR1. The team experiences transient connectivity errors, which causes the data exports to fail.
Requirements. Planned Changes
Contoso plans to create the following two lakehouses:
Lakehouse1: Will store both raw and cleansed data from the sources
Lakehouse2: Will serve data in a dimensional model to users for analytical queries Additional items will be added to facilitate data ingestion and transformation.
Contoso plans to use Azure Repos for source control in Fabric.
Requirements. Technical Requirements
The new lakehouses must follow a medallion architecture by using the following three layers: bronze, silver, and gold. There will be extensive data cleansing required to populate the MAR1 data in the silver layer, including deduplication, the handling of missing values, and the standardizing of capitalization.
Each layer must be fully populated before moving on to the next layer. If any step in populating the lakehouses fails, an email must be sent to the data engineers.
Data imports must run simultaneously, when possible.
The use of email data from the Amazon S3 bucket must meet the following requirements:
Minimize egress costs associated with cross-cloud data access.
Prevent saving a copy of the raw data in the lakehouses.
Items that relate to data ingestion must meet the following requirements:
The items must be source controlled alongside other workspace items.
Ingested data must land in the bronze layer of Lakehouse1 in the Delta format.
No changes other than changes to the file formats must be implemented before the data lands in the bronze layer.
Development effort must be minimized and a built-in connection must be used to import the source data.
In the event of a connectivity error, the ingestion processes must attempt the connection again.
Lakehouses, data pipelines, and notebooks must be stored in WorkspaceA. Semantic models, reports, and dataflows must be stored in WorkspaceB.
Once a week, old files that are no longer referenced by a Delta table log must be removed.
Requirements. Data Transformation
In the POS1 product data, ProductID values are unique. The product dimension in the gold layer must include only active products from product list. Active products are identified by an IsActive value of 1.
Some product categories and subcategories are NOT assigned to any product. They are NOT analytically relevant and must be omitted from the product dimension in the gold layer.
Requirements. Data Security
Security in Fabric must meet the following requirements:
The data engineers must have read and write access to all the lakehouses, including the underlying files.
The data analysts must only have read access to the Delta tables in the gold layer.
The data analysts must NOT have access to the data in the bronze and silver layers.
The data engineers must be able to commit changes to source control in WorkspaceA.
NEW QUESTION # 39
You have a Google Cloud Storage (GCS) container named storage1 that contains the files shown in the following table.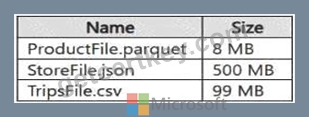
You have a Fabric workspace named Workspace1 that has the cache for shortcuts enabled. Workspace1 contains a lakehouse named Lakehouse1. Lakehouse1 has the shortcuts shown in the following table.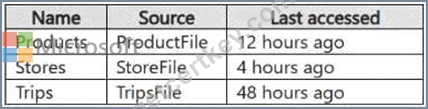
You need to read data from all the shortcuts.
Which shortcuts will retrieve data from the cache?
Answer: A
Explanation:
When reading data from shortcuts in Fabric (in this case, from a lakehouse like Lakehouse1), the cache for shortcuts helps by storing the data locally for quick access. The last accessed timestamp and the cache expiration rules determine whether data is fetched from the cache or from the source (Google Cloud Storage, in this case).
Products: The ProductFile.parquet was last accessed 12 hours ago. Since the cache has data available for up to
12 hours, it is likely that this data will be retrieved from the cache, as it hasn't been too long since it was last accessed.
Stores: The StoreFile.json was last accessed 4 hours ago, which is within the cache retention period.
Therefore, this data will also be retrieved from the cache.
Trips: The TripsFile.csv was last accessed 48 hours ago. Given that it's outside the typical caching window (assuming the cache has a maximum retention period of around 24 hours), it would not be retrieved from the cache. Instead, it will likely require a fresh read from the source.
NEW QUESTION # 40
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric eventstream that loads data into a table named Bike_Location in a KQL database. The table contains the following columns:
BikepointID
Street
Neighbourhood
No_Bikes
No_Empty_Docks
Timestamp
You need to apply transformation and filter logic to prepare the data for consumption. The solution must return data for a neighbourhood named Sands End when No_Bikes is at least 15. The results must be ordered by No_Bikes in ascending order.
Solution: You use the following code segment: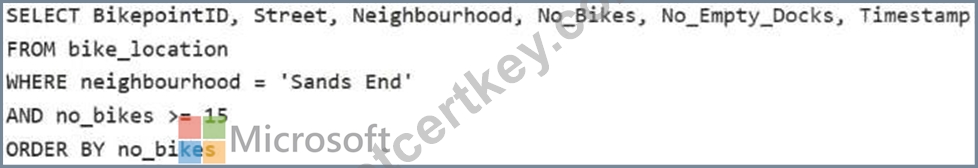
Does this meet the goal?
Answer: B
Explanation:
This code does not meet the goal because this is an SQL-like query and cannot be executed in KQL, which is required for the database.
Correct code should look like: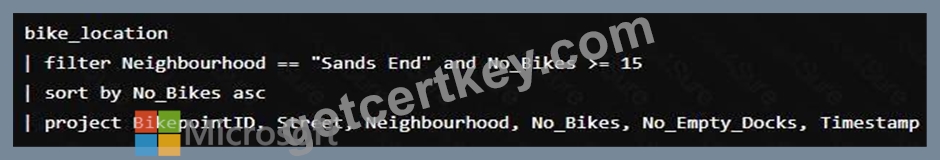
NEW QUESTION # 41
......
DP-700 Reliable Exam Materials: https://www.getcertkey.com/DP-700_braindumps.html
BONUS!!! Download part of Getcertkey DP-700 dumps for free: https://drive.google.com/open?id=1TZokl0vp682yekL6vgZzCqrl2924iWVu