P.S. VCESoft在Google Drive上分享了免費的2026 Databricks Databricks-Certified-Professional-Data-Engineer考試題庫:https://drive.google.com/open?id=1UviwYnMjoMi_6dh-bb0spI8xGOqEFGmT
不要再因為準備一個考試浪費太多的時間了。快點購買VCESoft的Databricks-Certified-Professional-Data-Engineer考古題吧。有了這個考古題,你將更好地知道該怎麼準備考試才更有效率。這是一個可以讓你輕鬆就通過考試的難得的工具,錯過這個機會你將會後悔。所以,不要犹豫赶紧行动吧。
考試由多選題和實踐任務組成,測試候選人在Databricks方面的實際知識。考試涵蓋了各種主題,如數據工程、數據處理、ETL、數據建模、數據倉儲、數據治理和數據安全。考試旨在評估候選人使用Databricks設計和實施可擴展數據管道的能力。
Databricks 認證專業數據工程師 (Databricks-Certified-Professional-Data-Engineer) 考試是數據工程行業中極受尊重的認證。此認證專為對數據工程原則、實踐和技術有深入理解的專業人員而設計。獲得此認證後,數據工程師可以展示他們在設計和構建數據管道、管理數據工作流以及使用 Databricks 實施數據分析解決方案的專業知識。
>> Databricks-Certified-Professional-Data-Engineer認證題庫 <<
我受不了現在的生活和工作了,想做別的工作。你現在有這樣的想法嗎?但是,怎樣才能做更好的工作呢?你喜歡IT嗎?想通過IT來證明自己的實力嗎?如果你想從事IT方面的工作,那麼參加IT認定考試,取得認證資格是非常有必要的。你現在要做的就是參加被普遍認可的、有價值的IT資格考試。從而打開你職業生涯的新的大門。關於Databricks的Databricks-Certified-Professional-Data-Engineer考試,你一定不陌生吧。取得這個資格可以讓你在找工作的時候得到一份助力。什麼?沒有信心參加這個考試嗎?沒關係,你可以使用VCESoft的Databricks-Certified-Professional-Data-Engineer考試資料。
Databricks-Certified-Professional-Data-Engineer考試包括多選題和實際場景的操作,測試候選人在Databricks上設計、構建和部署數據管道的能力。考試涵蓋多個主題,包括數據工程概念、Databricks架構、使用Spark進行數據處理以及與其他系統集成的數據整合。認證計劃提供全面的學習體驗,準備候選人成為熟練的數據工程師,并為他們在就業市場上提供競爭優勢。
問題 #49
A data engineer is creating a daily reporting job. There are two reporting notebooks-one for weekdays and one for weekends. An "if/else condition" task is configured as {{job.start_time.is_weekday}} == true to route the job to either the weekday or weekend notebook tasks. The same job would be used across multiple time zones.
Which action should a senior data engineer take upon reviewing the job to merge or reject the pull request?
答案:B
解題說明:
Databricks parameter templates like {{job.start_time.is_weekday}} evaluate in UTC time by default, not in local workspace or regional time zones. Therefore, when jobs are configured to run across different time zones, relying on is_weekday using UTC may cause scheduling and task routing mismatches (for example, triggering the weekday notebook in one region while it's still the weekend locally).
Databricks recommends adjusting conditional logic or pipeline parameters explicitly to handle time zone conversions if business requirements depend on local times. Because the engineer's configuration does not account for this behavior, a senior data engineer should reject the pull request and suggest time-zone-aware logic before merging.
問題 #50
A Delta Lake table was created with the below query: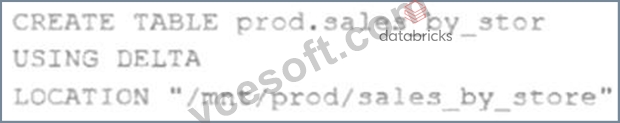
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
答案:E
解題說明:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An externaltable can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "ALTER TABLE RENAME TO" section; Databricks Documentation, under "Metastore" section; Databricks Documentation, under "Managed and external tables" section.
問題 #51
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
答案:D
解題說明:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.
Reference: Databricks documentation on Delta Lake optimization techniques, including data skipping and statistics collection (https://docs.databricks.com/delta/optimizations/index.html).
問題 #52
The Databricks CLI is used to trigger a run of an existing job by passing the job_id parameter. The response indicating the job run request was submitted successfully includes a field run_id. Which statement describes what the number alongside this field represents?
答案:C
解題說明:
* Exact extract: "run_id: The canonical identifier of a run."
References: Databricks Jobs API/CLI response fields.
問題 #53
A data engineer needs to provide access to a group named manufacturing-team. The team needs privileges to create tables in the quality schema.
Which set of SQL commands will grant a group named manufacturing-team to create tables in a schema named production with the parent catalog named manufacturing with the least privileges?
答案:C
解題說明:
To create a table within a schema, a principal must have CREATE TABLE on the schema, USE SCHEMA on that schema, and USE CATALOG on the parent catalog. This combination ensures the group has just enough privileges to create objects in that schema without excessive permissions like CREATE SCHEMA or CREATE CATALOG.
Reference Source: Databricks Unity Catalog Privilege Model - "Privileges Required to Create a Table."
問題 #54
......
Databricks-Certified-Professional-Data-Engineer認證: https://www.vcesoft.com/Databricks-Certified-Professional-Data-Engineer-pdf.html
順便提一下,可以從雲存儲中下載VCESoft Databricks-Certified-Professional-Data-Engineer考試題庫的完整版:https://drive.google.com/open?id=1UviwYnMjoMi_6dh-bb0spI8xGOqEFGmT