試験の準備方法-更新するDatabricks-Certified-Professional-Data-Engineer全真問題集試験-一番優秀なDatabricks-Certified-Professional-Data-Engineer日本語独学書籍

さらに、Tech4Exam Databricks-Certified-Professional-Data-Engineerダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1uFvc_Sm3NB2Tr2FdG2COs5ckQnCjM8zo
昇進の機会を得て仕事に就きたいと考えているなら、当社からDatabricks-Certified-Professional-Data-Engineer学習問題を選択するのが最良の選択のチャンスになります。なぜなら、Databricks-Certified-Professional-Data-Engineer学習教材には、あなたが自分自身を改善し、他の人よりも優れたものにするのに役立つ十分な能力があるからです。当社のDatabricks-Certified-Professional-Data-Engineer学習教材は、多くの人々が認定を取得し、夢を実現するのに役立ちました。また、当社のDatabricks-Certified-Professional-Data-Engineerテストガイドに連絡する機会もあります。
Databricks Databricks-Certified-Professional-Data-Engineer Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Delta Lake | 20-25% | - Delta Lake operations
- 1. Merge, update, delete operations
- 2. Delta Live Tables
- 3. Schema evolution and enforcement
- Delta Lake fundamentals
- 1. Time travel and data versioning
- 2. Optimize and Z-order
- 3. ACID transactions
|
| Topic 2: Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
- 1. Window functions
- 2. Spark SQL queries and functions
- 3. DataFrame operations and transformations
- Python and SQL for data engineering
- 1. Spark APIs in Python
- 2. Performance optimization techniques
- 3. Built-in and user-defined functions
|
| Topic 3: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Data governance fundamentals
- 2. Differences between data lake, data warehouse, and lakehouse
- 3. Bronze, silver, gold data layers
|
| Topic 4: Data Ingestion | 15-20% | - Streaming ingestion
- 1. Kafka integration
- 2. Structured streaming fundamentals
- Batch ingestion methods
- 1. Integration with external systems
- 2. Spark APIs for ingestion
- 3. DBR autoloader
|
| Topic 5: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Task dependencies and orchestration
- 2. Monitoring and alerting
- 3. Jobs and job scheduling
|
>> Databricks-Certified-Professional-Data-Engineer全真問題集 <<
有効的なDatabricks-Certified-Professional-Data-Engineer全真問題集一回合格-素晴らしいDatabricks-Certified-Professional-Data-Engineer日本語独学書籍
我々Tech4Examは最高のアフターサービスを提供いたします。DatabricksのDatabricks-Certified-Professional-Data-Engineer試験ソフトを買ったあなたは一年間の無料更新サービスを得られて、DatabricksのDatabricks-Certified-Professional-Data-Engineerの最新の問題集を了解して、試験の合格に自信を持つことができます。あなたはDatabricksのDatabricks-Certified-Professional-Data-Engineer試験に失敗したら、弊社は原因に関わらずあなたの経済の損失を減少するためにもらった費用を全額で返しています。
Databricks Certified Professional Data Engineer Exam 認定 Databricks-Certified-Professional-Data-Engineer 試験問題 (Q201-Q206):
質問 # 201
A data engineer is configuring a Databricks Asset Bundle to deploy a job with granular permissions. The requirements are:
* Grant the data-engineers group CAN_MANAGE access to the job.
* Ensure the auditors' group can view the job but not modify/run it.
* Avoid granting unintended permissions to other users/groups.
How should the data engineer deploy the job while meeting the requirements?
- A. resources:
jobs:
my-job:
name: data-pipeline
tasks: [...]
job_clusters: [...]
permissions:
- group_name: data-engineers
level: CAN_MANAGE
- group_name: auditors
level: CAN_VIEW
- group_name: admin-team
level: IS_OWNER - B. permissions:
- group_name: data-engineers
level: CAN_MANAGE
- group_name: auditors
level: CAN_VIEW
resources:
jobs:
my-job:
name: data-pipeline
tasks: [...]
job_clusters: [...] - C. resources:
jobs:
my-job:
name: data-pipeline
tasks: [...]
job: [...]
permissions:
- group_name: data-engineers
level: CAN_MANAGE
permissions:
- group_name: auditors
level: CAN_VIEW - D. resources:
jobs:
my-job:
name: data-pipeline
tasks: [...]
job_clusters: [...]
permissions:
- group_name: data-engineers
level: CAN_MANAGE
- group_name: auditors
level: CAN_VIEW
正解:D
解説:
Databricks Asset Bundles (DABs) allow jobs, clusters, and permissions to be defined as code in YAML configuration files. According to the Databricks documentation on job permissions and bundle deployment, when defining permissions within a job resource, they must be scoped directly under that specific job's definition. This ensures that permissions are applied only to the intended job resource and not inadvertently propagated to other jobs or resources.
In this scenario, the data engineer must grant the data-engineers group CAN_MANAGE access, allowing them to configure, edit, and manage the job, while the auditors group should only have CAN_VIEW, giving them read-only access to see configurations and results without the ability to modify or execute. Importantly, no additional groups should be granted permissions, in order to follow the principle of least privilege.
Options A and B introduce unnecessary or unintended groups (like admin-team in A) or define permissions outside of the job scope (as in B). Option C improperly separates the permissions block outside the job resource, which is not aligned with Databricks bundle best practices.
Option D is the correct approach because it defines the job resource my-job with its name, tasks, clusters, and the exact intended permissions (CAN_MANAGE for data-engineers and CAN_VIEW for auditors). This aligns with Databricks' principle of least privilege and ensures compliance with governance standards in Unity Catalog-enabled workspaces.
Reference: Databricks Asset Bundles documentation - Managing Jobs and Permissions
質問 # 202
Drop the customers database and associated tables and data, all of the tables inside the database are managed tables. Which of the following SQL commands will help you accomplish this?
- A. All the tables must be dropped first before dropping database
- B. DROP DATABASE customers CASCADE
- C. DROP DELTA DATABSE customers
- D. DROP DATABASE customers INCLUDE
- E. DROP DATABASE customers FORCE
正解:D
解説:
Explanation
The answer is DROP DATABASE customers CASCADE
Drop database with cascade option drops all the tables, since all of the tables inside the database are managed tables we do not need to perform any additional steps to clean the data in the storage.
質問 # 203
A DLT pipeline includes the following streaming tables:
Raw_lot ingest raw device measurement data from a heart rate tracking device.
Bgm_stats incrementally computes user statistics based on BPM measurements from raw_lot.
How can the data engineer configure this pipeline to be able to retain manually deleted or updated records in the raw_iot table while recomputing the downstream table when a pipeline update is run?
- A. Set the pipelines, reset, allowed property to false on bpm_stats
- B. Set the SkipChangeCommits flag to true raw_lot
- C. Set the skipChangeCommits flag to true on bpm_stats
- D. Set the pipelines, reset, allowed property to false on raw_iot
正解:D
解説:
In Databricks Lakehouse, to retain manually deleted or updated records in the raw_iot table while recomputing downstream tables when a pipeline update is run, the property pipelines.reset.allowed should be set to false. This property prevents the system from resetting the state of the table, which includes the removal of the history of changes, during a pipeline update. By keeping this property as false, any changes to the raw_iot table, including manual deletes or updates, are retained, and recomputation of downstream tables, such as bpm_stats, can occur with the full history of data changes intact.
Reference:
Databricks documentation on DLT pipelines: https://docs.databricks.com/data-engineering/delta-live-tables/delta-live-tables-overview.html
質問 # 204
A nightly job ingests data into a Delta Lake table using the following code:
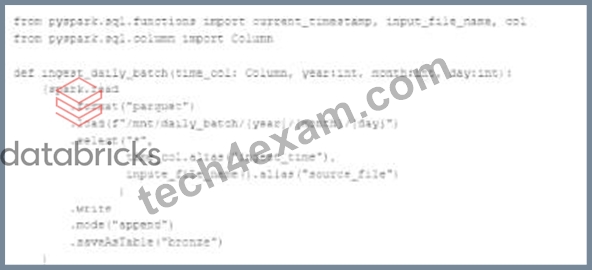
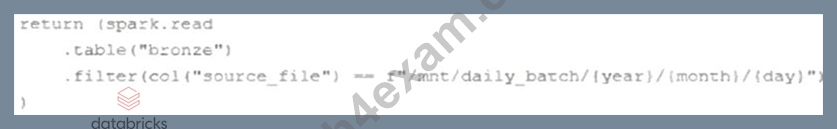
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
- A. return spark.readStream.table("bronze")
- B. return spark.read.option("readChangeFeed", "true").table ("bronze")
- C.
- D. return spark.readStream.load("bronze")
正解:C
解説:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
質問 # 205
The data science team has created and logged a production using MLFlow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, load the customer table containing the customer_id key column into a Dataframe, and defines the feature columns needed for the model.
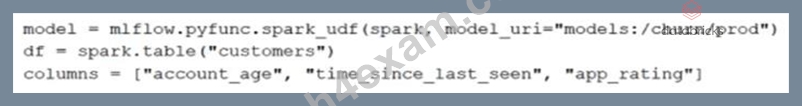
Which code block will output DataFrame with the schema ' ' customer_id LONG, predictions DOUBLE ' ' ?
- A. Df.apply(model, columns). Select ( ' ' customer_id, prediction ' '
- B. Model, predict (df, columns)
- C. Df. Select ( ' ' customer_id ' ' .
Model ( ' ' columns) alias ( ' ' predictions ' ' ) - D. Df, map (lambda k:midel (x [columns]) ,select ( ' ' customer_id predictions ' ' )
正解:B
解説:
Given the information that the model is registered with MLflow and assuming predict is the method used to apply the model to a set of columns, we use the model.predict() function to apply the model to the DataFrame df using the specified columns . The model.predict() function is designed to take in a DataFrame and a list of column names as arguments, applying the trained model to these features to produce a predictions column. When working with PySpark, this predictions column needs to be selected alongside the customer_id to create a new DataFrame with the schema customer_id LONG, predictions DOUBLE .
References:
MLflow documentation on using Python function models: https://www.mlflow.org/docs/latest/models.
html#python-function-python
PySpark MLlib documentation on model prediction: https://spark.apache.org/docs/latest/ml-pipeline.
html#pipeline
質問 # 206
......
Databricks-Certified-Professional-Data-Engineer試験に合格して関連認定を取得する場合、試験の準備をするための信頼できる試験ツールを見つける必要があります。それが、Databricks-Certified-Professional-Data-Engineer準備ガイドをお勧めしたい理由です。これがあなたが探しているものだと信じているからです。さらに、データ保護法を提供し、Databricks-Certified-Professional-Data-Engineerガイド急流を購入した後、ウイルスの侵入や情報漏えいに悩まされないことをDatabricks保証します。最後になりましたが、ダウンロードと分割払いに関するガイダンスをリモートで提供するDatabricks Certified Professional Data Engineer Exam専門家グループがあります。
Databricks-Certified-Professional-Data-Engineer日本語独学書籍: https://www.tech4exam.com/Databricks-Certified-Professional-Data-Engineer-pass-shiken.html
- Databricks-Certified-Professional-Data-Engineer資格模擬 🌷 Databricks-Certified-Professional-Data-Engineer資格模擬 🌰 Databricks-Certified-Professional-Data-Engineer資格模擬 🤞 ウェブサイト✔ www.japancert.com ️✔️から➥ Databricks-Certified-Professional-Data-Engineer 🡄を開いて検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer問題無料
- 試験Databricks Databricks-Certified-Professional-Data-Engineer全真問題集 - 一生懸命にDatabricks-Certified-Professional-Data-Engineer日本語独学書籍 | 信頼的なDatabricks-Certified-Professional-Data-Engineer PDF 👧 ✔ www.goshiken.com ️✔️は、《 Databricks-Certified-Professional-Data-Engineer 》を無料でダウンロードするのに最適なサイトですDatabricks-Certified-Professional-Data-Engineer問題無料
- Databricks-Certified-Professional-Data-Engineer参考書内容 🔆 Databricks-Certified-Professional-Data-Engineerテスト対策書 👊 Databricks-Certified-Professional-Data-Engineer関連日本語版問題集 🏍 ➥ www.passtest.jp 🡄には無料の▷ Databricks-Certified-Professional-Data-Engineer ◁問題集がありますDatabricks-Certified-Professional-Data-Engineer学習範囲
- ハイパスレートのDatabricks-Certified-Professional-Data-Engineer全真問題集 - 合格スムーズDatabricks-Certified-Professional-Data-Engineer日本語独学書籍 | 効果的なDatabricks-Certified-Professional-Data-Engineer PDF ☸ ➠ www.goshiken.com 🠰サイトにて最新[ Databricks-Certified-Professional-Data-Engineer ]問題集をダウンロードDatabricks-Certified-Professional-Data-Engineer参考書内容
- 最高のDatabricks Databricks-Certified-Professional-Data-Engineer全真問題集 - 合格スムーズDatabricks-Certified-Professional-Data-Engineer日本語独学書籍 | 真実的なDatabricks-Certified-Professional-Data-Engineer PDF 💐 時間限定無料で使える⮆ Databricks-Certified-Professional-Data-Engineer ⮄の試験問題は➤ www.topexam.jp ⮘サイトで検索Databricks-Certified-Professional-Data-Engineer練習問題
- Databricks-Certified-Professional-Data-Engineerダウンロード 🗽 Databricks-Certified-Professional-Data-Engineer日本語講座 🍎 Databricks-Certified-Professional-Data-Engineer資格取得 🧂 URL ▶ www.goshiken.com ◀をコピーして開き、⏩ Databricks-Certified-Professional-Data-Engineer ⏪を検索して無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer復習内容
- 信頼できるDatabricks-Certified-Professional-Data-Engineer全真問題集 - 合格スムーズDatabricks-Certified-Professional-Data-Engineer日本語独学書籍 | 大人気Databricks-Certified-Professional-Data-Engineer PDF 📝 最新“ Databricks-Certified-Professional-Data-Engineer ”問題集ファイルは“ www.passtest.jp ”にて検索Databricks-Certified-Professional-Data-Engineerダウンロード
- Databricks-Certified-Professional-Data-Engineer的中問題集 🍗 Databricks-Certified-Professional-Data-Engineer資格取得 ⏹ Databricks-Certified-Professional-Data-Engineerダウンロード 🦮 今すぐ➠ www.goshiken.com 🠰を開き、{ Databricks-Certified-Professional-Data-Engineer }を検索して無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer受験準備
- Databricks-Certified-Professional-Data-Engineer復習内容 😏 Databricks-Certified-Professional-Data-Engineer資格認証攻略 🔍 Databricks-Certified-Professional-Data-Engineer資格取得 👗 ⮆ Databricks-Certified-Professional-Data-Engineer ⮄の試験問題は▷ www.mogiexam.com ◁で無料配信中Databricks-Certified-Professional-Data-Engineer関連日本語版問題集
- 試験の準備方法-実用的なDatabricks-Certified-Professional-Data-Engineer全真問題集試験-一番優秀なDatabricks-Certified-Professional-Data-Engineer日本語独学書籍 📚 今すぐ“ www.goshiken.com ”を開き、( Databricks-Certified-Professional-Data-Engineer )を検索して無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer問題サンプル
- Databricks-Certified-Professional-Data-Engineerダウンロード 🧜 Databricks-Certified-Professional-Data-Engineerトレーリング学習 ▶ Databricks-Certified-Professional-Data-Engineer復習内容 😺 検索するだけで▶ www.goshiken.com ◀から➡ Databricks-Certified-Professional-Data-Engineer ️⬅️を無料でダウンロードDatabricks-Certified-Professional-Data-Engineer復習教材
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, ccitonline.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, mayagriffiths253.blogspot.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026年Tech4Examの最新Databricks-Certified-Professional-Data-Engineer PDFダンプおよびDatabricks-Certified-Professional-Data-Engineer試験エンジンの無料共有:https://drive.google.com/open?id=1uFvc_Sm3NB2Tr2FdG2COs5ckQnCjM8zo