The high quality and high efficiency of DP-750 study guide make it stand out in the products of the same industry. Our DP-750 exam materials have always been considered for the users. If you choose our products, you will become a better self. DP-750 Actual Exam want to contribute to your brilliant future. With our DP-750 learning braindumps, you can not only get the certification but also learn a lot of the professional knowledge.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
>> DP-750 Exam Sample Online <<
Purchasing our DP-750 training test is not complicated, there are mainly four steps: first, you can choose corresponding version according to the needs you like. Next, you need to fill in the correct email address. And if the user changes the email during the subsequent release, you need to update the email. Then, the user needs to enter the payment page of the DP-750 Learning Materials to buy it. Finally, within ten minutes of payment, the system automatically sends the DP-750 study materials to the user's email address. And then you can quickly study and pass the DP-750 exam.
NEW QUESTION # 24
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a complex job named Job1 that contains eight tasks. Job1 takes multiple hours to complete.
During the last job run, the final task fails due to a transient issue.
You need to retry the last task without rerunning tasks that have already completed.
What should you do?
Answer: B
Explanation:
Repairing the current job run allows Lakeflow Jobs to rerun the failed task while preserving the successful status of tasks that already completed. This prevents several hours of successful processing from being repeated and reduces both recovery time and compute consumption. If downstream tasks had been skipped because of the failure, they can also be included in the repair operation as appropriate. Updating job parameters changes configuration but does not retry the failed task in the existing run. Restarting Job1 creates a new run and ordinarily executes the workflow again from its beginning. Disabling and reenabling the schedule only changes whether future scheduled runs can start; it does not repair the failed execution. Repair Run is specifically designed for recovering selected failed or skipped tasks in a multi-task workflow.
NEW QUESTION # 25
You use Databricks Asset Bundles to manage two jobs and an app.
You need to deploy the bundle to development and production environments. The solution must meet the following requirements:
- Deploy the app to both environments.
- Deploy only one job to development.
- Minimize administrative effort.
What should you use?
Answer: C
Explanation:
To meet your deployment needs with minimal administrative overhead, you should use Databricks Asset Bundle (DAB) targets combined with resource overrides or conditional lookups using Go template syntax in your databricks.yml file.
Instead of creating separate bundles or complex CI/CD logic, you can declare both jobs and the app inside the main resources block, and then filter or modify them per target environment.
Implementation Options
Depending on your preference for keeping configuration declarative or fully conditional, choose one of the two standard patterns:
*-> Option 1: Resource Overrides via targets (Recommended)
Define all components globally, but use the targets block to remove or empty out the configuration of the job you want to skip in development.yamlbundle:
name: my-unified-bundle
apps:
my_app:
# App configurations go here...
jobs:
job_shared:
# Configurations for the job deployed to BOTH dev and prod...
job_prod_only:
name: Only for Production
# Production configurations...
targets:
dev:
mode: development
workspace:
host: https://dev-workspace.cloud.databricks.com
# Keep administrative work low by overriding the prod job to null/empty resources:
jobs:
job_prod_only: !null
prod:
mode: production
workspace:
host: https://prod-workspace.cloud.databricks.com
Option 2: Go Template Conditional LogicIf you prefer not to use !null overrides, you can evaluate the target environment dynamically at deployment time using standard Go templates.
Reference:
https://docs.databricks.com/aws/en/dev-tools/bundles/workspace-deploy
NEW QUESTION # 26
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
- The schemas and tables can be queried in Databricks.
- The schemas and tables appear alongside other Unity Catalog objects.
- The data is NOT copied into Databricks-managed storage.
Solution: You create a new native catalog in Unity Catalog.
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You create a foreign catalog in Catalog Explorer.
You should create a Foreign Catalog using Lakehouse Federation.
Data Copying: Lakehouse Federation queries data directly in the source SQL Server without moving or copying it.
Seamless Integration: The database schemas and tables appear right inside Unity Catalog alongside your other data objects.Real-time Access: It provides immediate access to live SQL Server data.
Incorrect:
* You create a Databricks access connector.
* You create a Lakeflow Connect pipeline and connect it to DB1.
Data Copying: Lakeflow Connect is an ingestion tool that physically replicates and copies data into Databricks-managed storage (Delta tables).
Storage Costs: It violates your requirement to keep data out of Databricks storage.
* You create a new native catalog in Unity Catalog.
Note:
To expose the external SQL Server database in Unity Catalog without copying the data, you must use Lakehouse Federation.
Here are the step-by-step actions you need to take:
1. Create a Connection
Create a securable object in Unity Catalog that specifies the path and credentials to access the SQL Server database.
Go to Catalog Explorer or use SQL.
Select External Data > Connections.
Create a connection using the SQL Server connection details (URL, host, port, and database credentials).
*-> 2. Create a Foreign Catalog
Create a specific type of catalog in Unity Catalog that mirrors the external database.
Use the CREATE FOREIGN CATALOG SQL command or the Catalog Explorer UI.
Link this foreign catalog directly to the connection you created in step 1.
3. Query the DataOnce the foreign catalog is created, Unity Catalog automatically syncs the schemas and tables from SQL Server.
Reference:
https://docs.databricks.com/gcp/en/database-objects/
NEW QUESTION # 27
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to implement a data lifecycle and expiration solution that meets the following requirements:
- Transaction logs and deleted data files that are older than 90 days
must be removed from Delta tables to reclaim storage.
- All the tables must remain available for querying during the cleanup
process.
- Administrative effort must be minimized.
What should you do for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.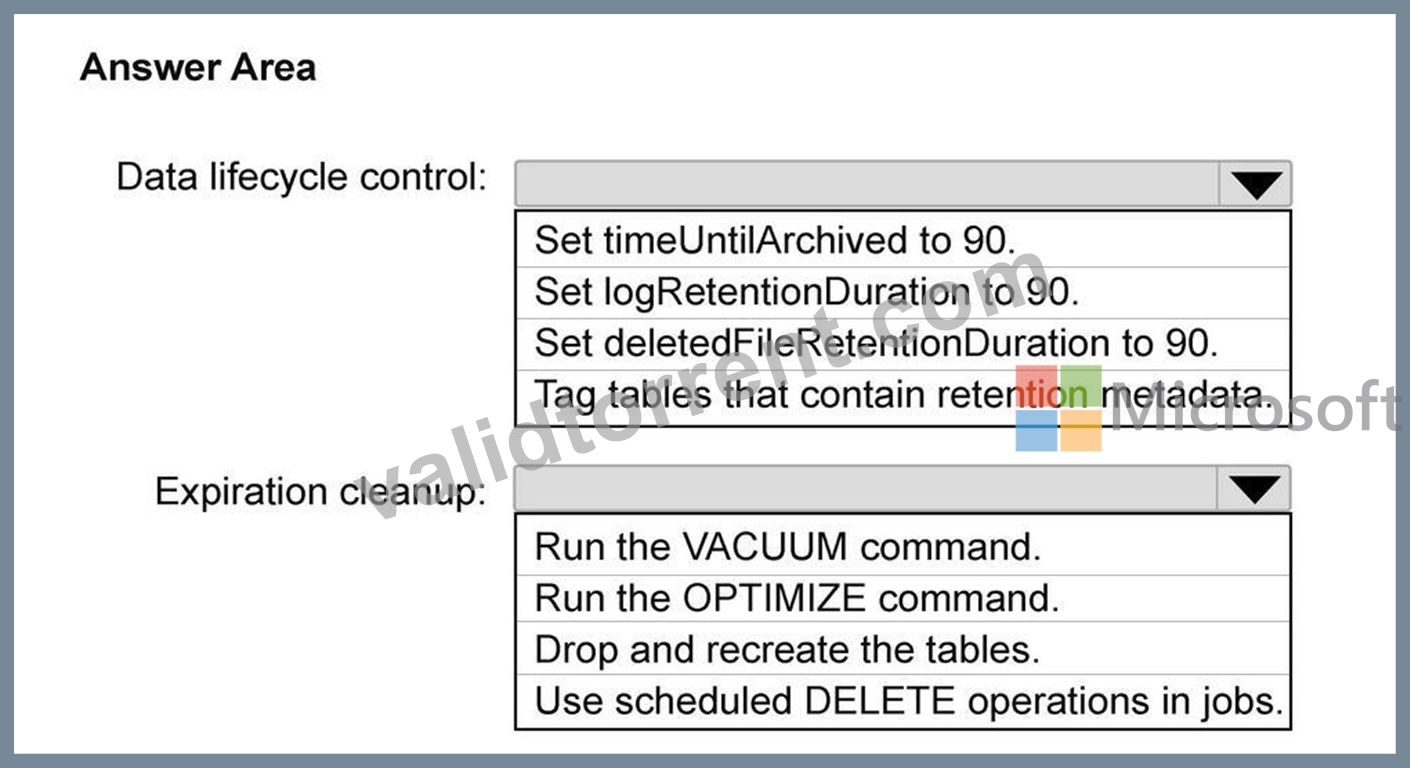
Answer:
Explanation:
NEW QUESTION # 28
You have an Azure Databricks workspace that contains a Delta table named Customer.
A job named Job1 performs frequent upserts into Customer.
You discover that Job1 has created many small Parquet files in Customer, and the small files are degrading query performance.
You need to improve query performance for the current data already stored in Customer. The solution must not affect the travel for the Customer table.
What should you do?
Answer: C
Explanation:
The OPTIMIZE command performs bin-packing compaction, combining the Customer table's existing small Parquet files into fewer, larger files. This reduces file-open overhead and improves data-skipping efficiency without changing the logical table contents. Enabling optimized writes affects future write operations but does not compact the small files already stored. VACUUM removes unreferenced data files that are older than the configured retention threshold; it does not reorganize active small files and can restrict time-travel availability. Reducing delta.deletedFileRetentionDuration changes how long obsolete files remain available and can directly reduce the time-travel window, contrary to the requirement. OPTIMIZE is therefore the correct operation for improving the physical layout of current data while preserving Delta table semantics and history. Microsoft Learn
NEW QUESTION # 29
......
In ValidTorrent's website you can free download study guide, some exercises and answers about Microsoft Certification DP-750 Exam as an attempt.
Exam DP-750 Cram: https://www.validtorrent.com/DP-750-valid-exam-torrent.html