P.S. Free & New DP-100 dumps are available on Google Drive shared by DumpsValid: https://drive.google.com/open?id=14jHspYMWYpJotbDNz8ACBlptpUiS78kt
Our company has been putting emphasis on the development and improvement of DP-100 test prep over ten year without archaic content at all. So we are bravely breaking the stereotype of similar content materials of the exam, but add what the exam truly tests into our DP-100 Exam Guide. So we have adamant attitude to offer help rather than perfunctory attitude. We esteem your variant choices so all these versions of DP-100 study materials are made for your individual preference and inclination.
Microsoft DP-100 exam covers a range of topics related to data science, including understanding business requirements, data exploration and preparation, modeling, training and evaluation of machine learning models, and deployment and management of models. DP-100 exam also covers topics such as feature engineering, model interpretability, and automation of machine learning workflows. DP-100 exam is designed to test the candidate's ability to design and implement end-to-end machine learning solutions that meet business requirements and are scalable, reliable, and secure.
Earning the DP-100 Certification can help you advance your career in data science and machine learning. It demonstrates to employers that you have the knowledge and skills to design and implement data-driven solutions using Azure services. Additionally, Microsoft offers a variety of other Azure certifications that can complement the DP-100 and help you build a well-rounded skillset in cloud computing.
Microsoft training pdf material is the valid tools which can help you prepare for the DP-100 actual test. DP-100 vce demo gives you the prep hints and important tips, helping you identify areas of weakness and improve both your conceptual knowledge and hands-on skills. With the help of DP-100 study material, you will master the concepts and techniques that ensure you exam success. What’s more, you can receive DP-100 updated study material within one year after purchase. Besides, you can rest assured to enjoy the secure shopping for Microsoft exam dumps on our site, and your personal information will be
The dream of becoming a highly skilled data scientist can turn into a reality with the help of the Microsoft DP-100 Exam. This exam tries to impart an associate-level understanding of data science and machine learning with an aim to generate a skilled workforce of data scientists.
NEW QUESTION # 297
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are creating a model to predict the price of a student's artwork depending on the following variables: the student's length of education, degree type, and art form.
You start by creating a linear regression model.
You need to evaluate the linear regression model.
Solution: Use the following metrics: Mean Absolute Error, Root Mean Absolute Error, Relative Absolute Error, Relative Squared Error, and the Coefficient of Determination.
Does the solution meet the goal?
Answer: A
Explanation:
The following metrics are reported for evaluating regression models. When you compare models, they are ranked by the metric you select for evaluation.
Mean absolute error (MAE) measures how close the predictions are to the actual outcomes; thus, a lower score is better.
Root mean squared error (RMSE) creates a single value that summarizes the error in the model.
By squaring the difference, the metric disregards the difference between over-prediction and under-prediction.
Relative absolute error (RAE) is the relative absolute difference between expected and actual values; relative because the mean difference is divided by the arithmetic mean.
Relative squared error (RSE) similarly normalizes the total squared error of the predicted values by dividing by the total squared error of the actual values.
Mean Zero One Error (MZOE) indicates whether the prediction was correct or not. In other words:
ZeroOneLoss(x,y) = 1 when x!=y; otherwise 0.
Coefficient of determination, often referred to as R2, represents the predictive power of the model as a value between 0 and 1. Zero means the model is random (explains nothing); 1 means there is a perfect fit. However, caution should be used in interpreting R2 values, as low values can be entirely normal and high values can be suspect.
AUC.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/evaluate- model
NEW QUESTION # 298
You have machine learning models produce unfair predictions across sensitive features.
You must use a post-processing technique to apply a constraint to the models to mitigate their unfairness.
You need to select a post-processing technique and model type.
What should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
See below image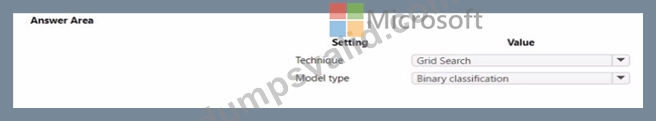
NEW QUESTION # 299
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You plan to use a Python script to run an Azure Machine Learning experiment. The script creates a reference to the experiment run context, loads data from a file, identifies the set of unique values for the label column, and completes the experiment run:
from azureml.core import Run
import pandas as pd
run = Run.get_context()
data = pd.read_csv('data.csv')
label_vals = data['label'].unique()
# Add code to record metrics here
run.complete()
The experiment must record the unique labels in the data as metrics for the run that can be reviewed later.
You must add code to the script to record the unique label values as run metrics at the point indicated by the comment.
Solution: Replace the comment with the following code:
run.upload_file('outputs/labels.csv', './data.csv')
Does the solution meet the goal?
Answer: B
Explanation:
Explanation
label_vals has the unique labels (from the statement label_vals = data['label'].unique()), and it has to be logged.
Note:
Instead use the run_log function to log the contents in label_vals:
for label_val in label_vals:
run.log('Label Values', label_val)
Reference:
https://www.element61.be/en/resource/azure-machine-learning-services-complete-toolbox-ai
NEW QUESTION # 300
You create an Azure Databricks workspace and a linked Azure Machine Learning workspace.
You have the following Python code segment in the Azure Machine Learning workspace:
import mlflow
import mlflow.azureml
import azureml.mlflow
import azureml.core
from azureml.core import Workspace
subscription_id = 'subscription_id'
resourse_group = 'resource_group_name'
workspace_name = 'workspace_name'
ws = Workspace.get(name=workspace_name,
subscription_id=subscription_id,
resource_group=resource_group)
experimentName = "/Users/{user_name}/{experiment_folder}/{experiment_name}" mlflow.set_experiment(experimentName) uri = ws.get_mlflow_tracking_uri() mlflow.set_tracking_uri(uri) Instructions: For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.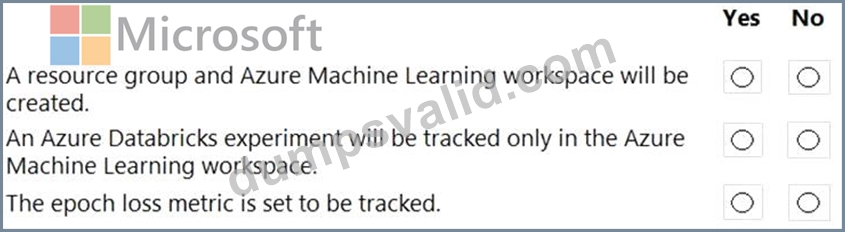
Answer:
Explanation: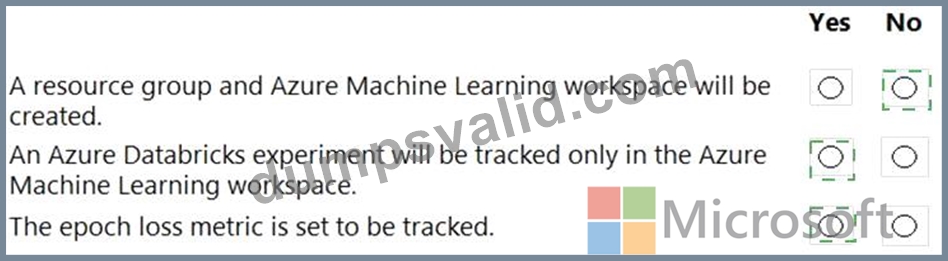
Explanation
A screenshot of a computer Description automatically generated with medium confidence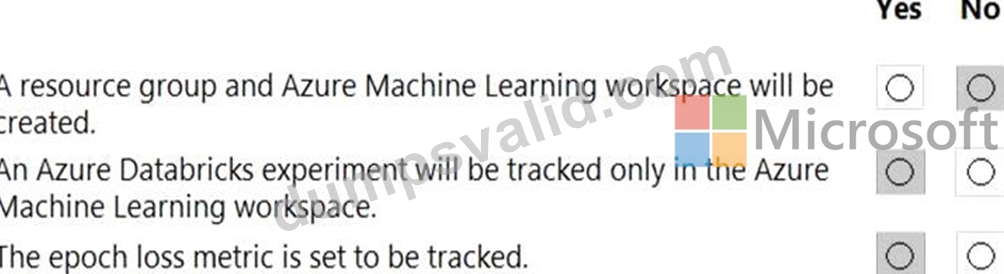
Box 1: No
The Workspace.get method loads an existing workspace without using configuration files.
ws = Workspace.get(name="myworkspace",
subscription_id='<azure-subscription-id>',
resource_group='myresourcegroup')
Box 2: Yes
MLflow Tracking with Azure Machine Learning lets you store the logged metrics and artifacts from your local runs into your Azure Machine Learning workspace.
The get_mlflow_tracking_uri() method assigns a unique tracking URI address to the workspace, ws, and set_tracking_uri() points the MLflow tracking URI to that address.
Box 3: Yes
Note: In Deep Learning, epoch means the total dataset is passed forward and backward in a neural network once.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-core/azureml.core.workspace.workspace
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-use-mlflow
NEW QUESTION # 301
You need to implement a scaling strategy for the local penalty detection data.
Which normalization type should you use?
Answer: D
Explanation:
Explanation
Post batch normalization statistics (PBN) is the Microsoft Cognitive Toolkit (CNTK) version of how to evaluate the population mean and variance of Batch Normalization which could be used in inference Original Paper.
In CNTK, custom networks are defined using the BrainScriptNetworkBuilder and described in the CNTK network description language "BrainScript." Scenario:
Local penalty detection models must be written by using BrainScript.
References:
https://docs.microsoft.com/en-us/cognitive-toolkit/post-batch-normalization-statistics
NEW QUESTION # 302
......
DP-100 Actual Dumps: https://www.dumpsvalid.com/DP-100-still-valid-exam.html
What's more, part of that DumpsValid DP-100 dumps now are free: https://drive.google.com/open?id=14jHspYMWYpJotbDNz8ACBlptpUiS78kt