P.S. Kostenlose und neue MLA-C01 Prüfungsfragen sind auf Google Drive freigegeben von ZertSoft verfügbar: https://drive.google.com/open?id=1PhSQXCyaQMSLql_yqFb0ybwLwQ4uxQi1
Unsere Webseite ZertSoft ist eine Webseite mit langer Geschichte, die Zertifizierungsantworten zur Amazon MLA-C01 Prüfung bietet. Nach langjährigen Bemühungen beträgt die Bestehensrate der Amazon MLA-C01 Zertifizierungsprüfung bereits 100%. Der Inhalt unserer Lehrbücher aktualisieren sich ständig, damit die Schulungsunterlagen zur Amazon MLA-C01 Zertifizierungsprüfung immer korekkt sind. Darüber hinaus können Sie einjährige Aktualisierung genießen, wenn Sie unsere Dumps gekauft haben.
| Thema | Einzelheiten |
|---|---|
| Thema 1 |
|
| Thema 2 |
|
| Thema 3 |
|
| Thema 4 |
|
Wenn Sie die Produkte von ZertSoft kaufen, werden wir mit äußerster Kraft Ihnen helfen, die Amazon MLA-C01 Zertifizierungsprüfung zu bstehen. Außerdem bieten wir Ihnen einen einjährigen kostenlosen Update-Service. Wenn der Prüfungsplan von staatlicher Seite geändert werden, benachrichtigen wir die Kunden sofort. Wenn unsere Software neue Version hat, liefern wir den Kunden sofort. ZertSoft verspricht, dass Sie nur einmal die Amazon MLA-C01 Zertifizierungsprüfung bestehen können.
195. Frage
An ML engineer is developing a neural network to run on new user data. The dataset has dozens of floating- point features. The dataset is stored as CSV objects in an Amazon S3 bucket. Most objects and columns are missing at least one value. All features are relatively uniform except for a small number of extreme outliers.
The ML engineer wants to use Amazon SageMaker Data Wrangler to handle missing values before passing the dataset to the neural network.
Which solution will provide the MOST complete data?
Antwort: B
Begründung:
The primary goal is to produce the most complete dataset while handling missing values and extreme outliers appropriately. Dropping samples (Option A) or columns (Option D) would reduce data completeness and potentially remove valuable information, which contradicts the requirement.
Imputation is therefore the correct approach. Between mean and median imputation, AWS ML best practices recommend using the median when features contain outliers. The mean is sensitive to extreme values and can be skewed significantly, leading to imputed values that are not representative of the typical data distribution.
In contrast, the median is robust to outliers, making it a better statistical estimator for central tendency in such datasets.
Amazon SageMaker Data Wrangler supports median imputation as a built-in transformation, enabling ML engineers to handle missing values consistently across large tabular datasets without custom code. This approach preserves all rows and columns while minimizing distortion caused by extreme values, which is particularly important for neural networks that are sensitive to input distributions.
Therefore, imputing missing values with the median value provides the most complete and statistically appropriate dataset for training.
196. Frage
A company has a large collection of chat recordings from customer interactions after a product release. An ML engineer needs to create an ML model to analyze the chat data. The ML engineer needs to determine the success of the product by reviewing customer sentiments about the product.
Which action should the ML engineer take to complete the evaluation in the LEAST amount of time?
Antwort: B
197. Frage
A company has deployed a model to predict the churn rate for its games by using Amazon SageMaker Studio.
After the model is deployed, the company must monitor the model performance for data drift and inspect the report. Select and order the correct steps from the following list to model monitor actions. Select each step one time. (Select and order THREE.) .
Check the analysis results on the SageMaker Studio console. .
Create a Shapley Additive Explanations (SHAP) baseline for the model by using Amazon SageMaker Clarify.
Schedule an hourly model explainability monitor.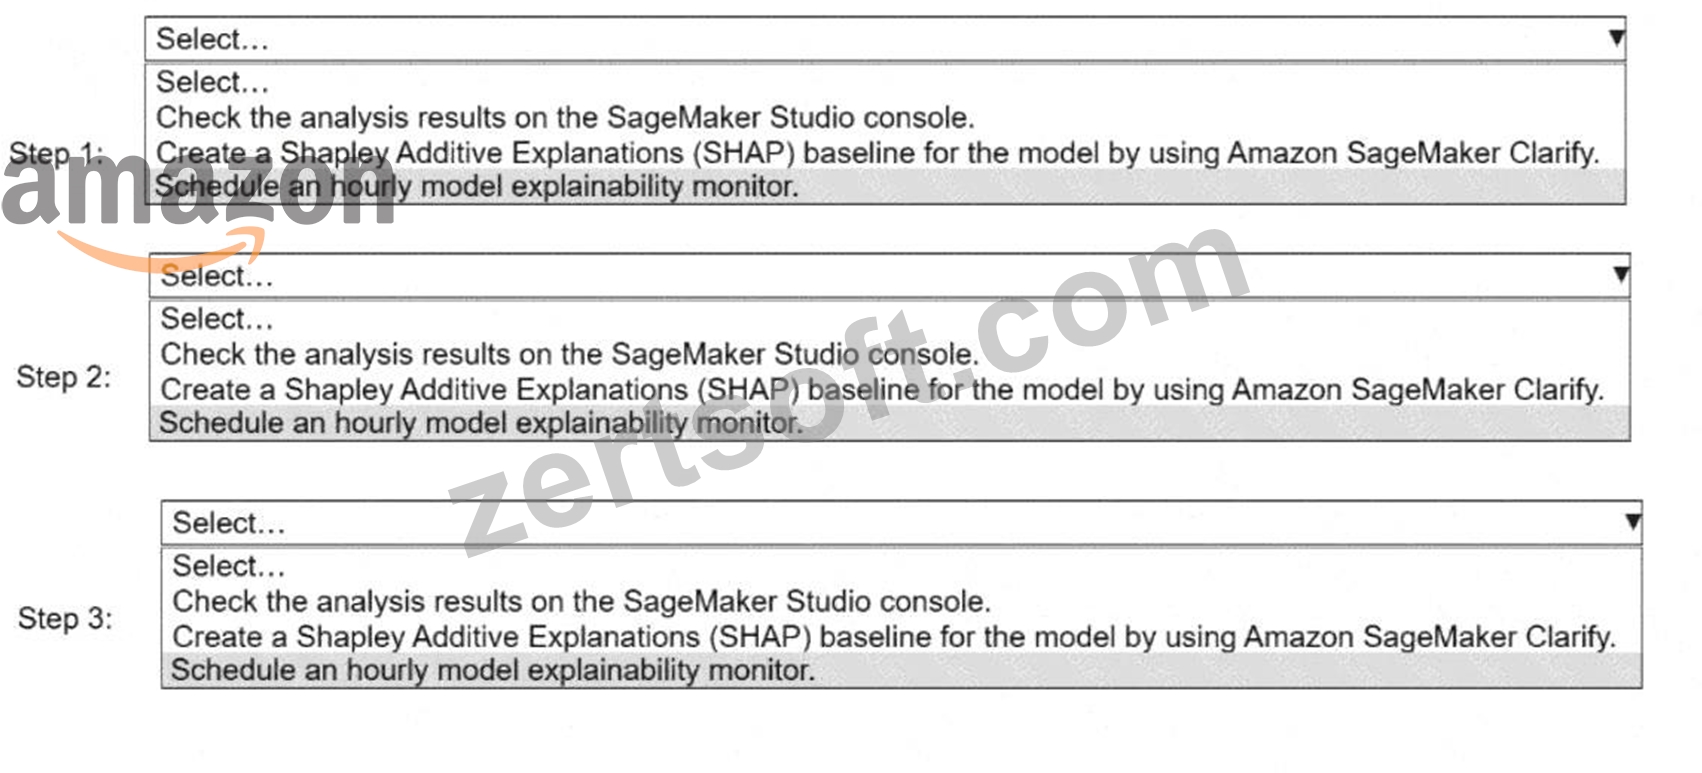
Antwort:
Begründung: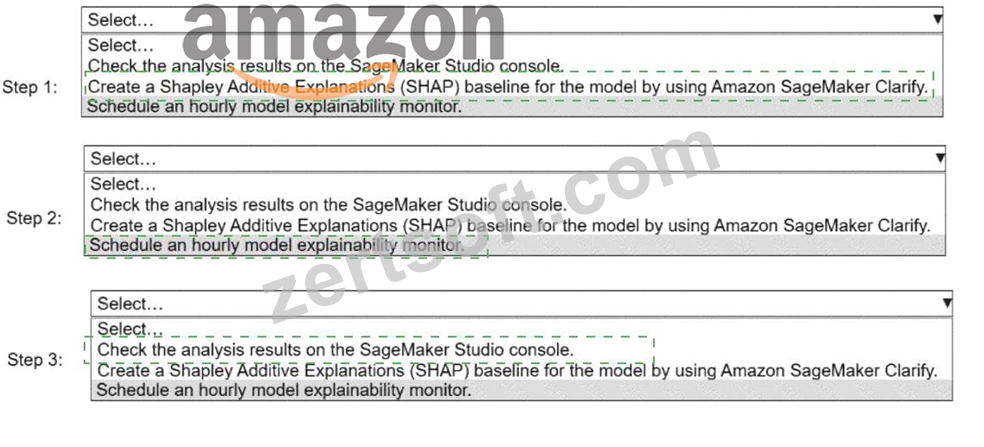
Explanation:
Step 1:
Create a Shapley Additive Explanations (SHAP) baseline for the model by using Amazon SageMaker Clarify.
Step 2:
Schedule an hourly model explainability monitor.
Step 3:
Check the analysis results on the SageMaker Studio console.
When monitoring a deployed model for data drift and explainability, AWS prescribes a specific workflow using SageMaker Clarify and SageMaker Model Monitor:
Create a SHAP baseline (Step 1)Before any monitoring can occur, SageMaker Clarify must establish a baseline explainability configuration. This baseline captures the reference SHAP values for feature importance using training or baseline data. Model Monitor uses this baseline to compare future inferences and detect drift in feature attributions.
Schedule the model explainability monitor (Step 2)After the baseline is created, an explainability monitoring schedule must be configured (hourly in this case). The monitor periodically analyzes inference data, compares it against the SHAP baseline, and generates reports that highlight drift or anomalies in feature contributions.
Inspect results in SageMaker Studio (Step 3)Once monitoring jobs run, SageMaker stores the analysis results in Amazon S3 and surfaces them in the SageMaker Studio console, where engineers can review metrics, violations, and visual reports.
This sequence is mandatory because:
A monitor cannot run without a baseline
Results cannot be reviewed until the monitor executes
198. Frage
A company is using an AWS Lambda function to monitor the metrics from an ML model. An ML engineer needs to implement a solution to send an email message when the metrics breach a threshold.
Which solution will meet this requirement?
Antwort: C
Begründung:
Logging the metrics to Amazon CloudWatch allows the metrics to be tracked and monitored effectively.
CloudWatch Alarms can be configured to trigger when metrics breach a predefined threshold.
The alarm can be set to notify through Amazon Simple Notification Service (SNS), which can send email messages to the configured recipients.
This is the standard and most efficient way to achieve the desired functionality.
199. Frage
A company uses an Amazon EMR cluster to run a data ingestion process for an ML model. An ML engineer notices that the processing time is increasing.
Which solution will reduce the processing time MOST cost-effectively?
Antwort: C
Begründung:
Amazon EMR clusters consist of primary, core, and task nodes, each with a distinct role. The primary node manages the cluster, core nodes store data and run tasks, and task nodes only run tasks without storing data.
AWS documentation recommends using task nodes for scaling compute capacity when workloads are compute-intensive, such as data ingestion and transformation pipelines.
To reduce processing time cost-effectively, AWS strongly advises using Spot Instances for task nodes. Spot Instances provide the same compute capacity as On-Demand Instances but at a significantly reduced cost, often up to 90% lower. Because task nodes do not store HDFS data, they can be safely interrupted without risking data loss.
Increasing the number of primary nodes is not supported by EMR and would not improve performance.
Increasing core nodes affects both storage and compute and is more expensive, especially when using On- Demand Instances. Option D is therefore the least cost-effective.
AWS EMR best practices explicitly state that scaling out with Spot task nodes is the preferred way to improve performance for transient, parallel workloads such as ETL, ingestion, and feature preparation.
Therefore, Option C is the most cost-effective and AWS-recommended solution.
200. Frage
......
Um Ihre Zertifizierungsprüfungen reibungslos erfolgreich zu meistern, brauchen Sie nur unsere Prüfungsfragen und Antworten zu Amazon MLA-C01 (AWS Certified Machine Learning Engineer - Associate)auswendigzulernen. Viel Erfolg!
MLA-C01 Probesfragen: https://www.zertsoft.com/MLA-C01-pruefungsfragen.html
BONUS!!! Laden Sie die vollständige Version der ZertSoft MLA-C01 Prüfungsfragen kostenlos herunter: https://drive.google.com/open?id=1PhSQXCyaQMSLql_yqFb0ybwLwQ4uxQi1