Databricks자격증Certified-Data-Engineer-Professional시험덤프

저희 Pass4Test의 덤프 업데이트시간은 업계에서 가장 빠르다고 많은 덤프구매자 분들께서 전해주셨습니다. Databricks Certified-Data-Engineer-Professional 덤프도 마찬가지 입니다. 저희는 수시로 덤프업데이트 가능성을 체크하여 덤프를 항상 시중에서 가장 최신버전이 될수있도록 최선을 다하고 있습니다. 구매후 1년무료업데이트서비스를 해드리기에 구매후에도 덤프유효성을 최대한 연장해드립니다.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Data Sharing and Federation | - Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Share live Lakehouse data with external computing platforms
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Data Modelling | - Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Optimize data layout using Liquid Clustering
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Cost & Performance Optimisation | - Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Apply data skipping and file pruning techniques
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use row filters and column masks for sensitive data
- 3. Use ACLs to secure workspace objects and enforce least privilege
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Develop unit and integration tests for data processing code
- 2. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 3. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 4. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 5. Use control flow operators in pipeline components
- 6. Use APPLY CHANGES APIs for change data capture
- 7. Configure environments, dependencies, memory, and retry behavior
- 8. Compare streaming tables and materialized views
- Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Manage and troubleshoot third-party library installations and dependencies
|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 2. Use system tables for resource, cost, audit, and workload monitoring
- 3. Use Query Profiler and Spark UI to monitor workloads
- 4. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
|
| Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
- Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Analyze errors and remediate failed job runs
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest data from message buses and cloud storage
|
>> Certified-Data-Engineer-Professional최고품질 덤프문제모음집 <<
퍼펙트한 Certified-Data-Engineer-Professional최고품질 덤프문제모음집 덤프샘플 다운로드
Pass4Test에는 전문적인 업계인사들이Databricks Certified-Data-Engineer-Professional시험문제와 답에 대하여 연구하여, 시험준비중인 여러분들한테 유용하고 필요한 시험가이드를 제공합니다. 만약Pass4Test의 제품을 구매하려면, 우리Pass4Test에서는 아주 디테일 한 설명과 최신버전 최고품질의자료를 즉적중율이 높은 문제와 답을제공합니다.Databricks Certified-Data-Engineer-Professional자료는 충분한 시험대비자료가 될 것입니다. 안심하시고 Pass4Test가 제공하는 상품을 사용하시고, 100%통과 율을 확신합니다.
최신 Databricks Certification Certified-Data-Engineer-Professional 무료샘플문제 (Q53-Q58):
질문 # 53
A data engineer is implementing a job to download multiple PDF files from a third-party provided REST API endpoint by specifying different report types. The REST API is time-consuming and encounters intermittent errors, so the engineer wants to track each download activity to know when it fails and to retry partially, while providing scalable throughput. The engineer needs to download ten report types, and the list can be changed over time. How should the data engineer achieve this?
- A. Define ten Notebook tasks to clearly track which report download failed.
- B. Use a foreach task with a list of report types as its inputs.
- C. Define a list variable within a Notebook to loop through the report types to download them, and print the download results. Execute it as a Notebook tasks.
- D. Use a Delta Lake table to track each report download status as 10 rows, and use it as a source table to execute the download function as a Pandas UDF.
정답:B
설명:
A foreach task allows the job to dynamically iterate over a configurable list of report types, execute downloads in parallel, and track the success or failure of each item independently. This enables scalable throughput, partial retries for failed downloads, and easy updates when the list of report types changes, without hardcoding tasks or introducing unnecessary complexity.
질문 # 54
A data engineering team has a time-consuming data ingestion job with three data sources. Each notebook takes about one hour to load new data. One day, the job fails because a notebook update introduced a new required configuration parameter. The team must quickly fix the issue and load the latest data from the failing source. Which action should the team take?
- A. Update the task by adding the missing task parameter, and manually run the job.
- B. Share the analysis with the failing notebook owner so that they can fix it quickly.
- C. Repair the run with the new parameter.
- D. Repair the run with the new parameter, and update the task by adding the missing task parameter.
정답:D
설명:
The repair run capability in Databricks Jobs allows re-execution of failed tasks without re-running successful ones. When a parameterized job fails due to missing or incorrect task configuration, engineers can perform a repair run to fix inputs or parameters and resume from the failed state.
This approach saves time, reduces cost, and ensures workflow continuity by avoiding unnecessary recomputation. Additionally, updating the task definition with the missing parameter prevents future runs from failing.
Running the job manually (B) loses run context; (C) alone does not prevent recurrence; (D) delays resolution. Thus, A follows the correct operational and recovery practice.
질문 # 55
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
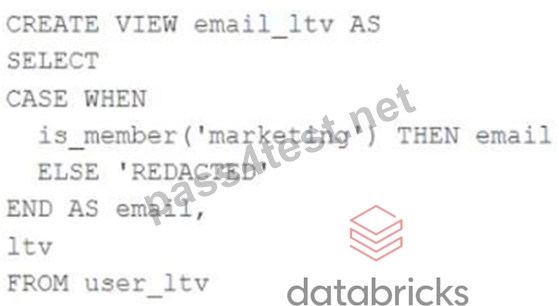
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
- A. Only the email and itv columns will be returned; the email column will contain all null values.
- B. Three columns will be returned, but one column will be named "redacted" and contain only null values.
- C. Only the email and ltv columns will be returned; the email column will contain the string
"REDACTED" in each row. - D. The email, age. and ltv columns will be returned with the values in user ltv.
- E. The email and ltv columns will be returned with the values in user itv.
정답:C
설명:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row.
질문 # 56
Which REST API call can be used to review the notebooks configured to run as tasks in a multi- task job?
- A. /jobs/runs/get
- B. /jobs/runs/list
- C. /jobs/get
- D. /jobs/list
- E. /jobs/runs/get-output
정답:C
설명:
https://docs.databricks.com/api/workspace/jobs/getresponses/settings/tasks/notebook_task/noteb ook_path
질문 # 57
A Data Engineer is building a simple data pipeline using Lakeflow Declarative Pipelines (LDP) in Databricks to ingest customer data. The raw customer data is stored in a cloud storage location in JSON format. The task is to create Lakeflow Declarative Pipelines that read the raw JSON data and write it into a Delta table for further processing. Which code snippet will correctly ingest the raw JSON data and create a Delta table using LDP?
- A. import dlt
@dlt.table
def raw_customers():
return spark.read.format("parquet").load("s3://my-bucket/raw-customers/") - B. import dlt
@dlt.view
def raw_customers():
return spark.format.json("s3://my-bucket/raw-customers/") - C. import dlt
@dlt.table
def raw_customers():
return spark.read.json("s3://my-bucket/raw-customers/") - D. import dlt
@dlt.table
def raw_customers():
return spark.read.format("csv").load("s3://my-bucket/raw-customers/")
정답:C
설명:
The correct method to define a table using Lakeflow Declarative Pipelines (LDP) is with the
@dlt.table decorator, which persists the output as a managed Delta table. When ingesting raw JSON data, spark.read.json() or spark.read.format("json").load() is the standard approach. This reads JSON- formatted files from the source and stores them in Delta format automatically managed by Databricks.
질문 # 58
......
Pass4Test는Databricks Certified-Data-Engineer-Professional인증시험의 촉매제 같은 사이트입니다.Databricks Certified-Data-Engineer-Professional인증시험 관연 덤프가 우리Pass4Test에서 출시되었습니다. 여러분이Databricks Certified-Data-Engineer-Professional인증시험으로 나 자신과 자기만의 뛰어난 지식 면을 증명하고 싶으시다면 우리 Pass4Test의Databricks Certified-Data-Engineer-Professional덤프자료가 많은 도움이 될 것입니다.
Certified-Data-Engineer-Professional최고덤프샘플: https://www.pass4test.net/Certified-Data-Engineer-Professional.html
- Certified-Data-Engineer-Professional인증시험 🚡 Certified-Data-Engineer-Professional최신버전 인기덤프 🩱 Certified-Data-Engineer-Professional최신 시험 공부자료 🏔 ➤ www.exampassdump.com ⮘의 무료 다운로드⮆ Certified-Data-Engineer-Professional ⮄페이지가 지금 열립니다Certified-Data-Engineer-Professional인기덤프자료
- Certified-Data-Engineer-Professional시험대비 최신 덤프모음집 🕉 Certified-Data-Engineer-Professional인증시험 🦃 Certified-Data-Engineer-Professional인증시험 인기덤프 🕞 ☀ www.itdumpskr.com ️☀️의 무료 다운로드▶ Certified-Data-Engineer-Professional ◀페이지가 지금 열립니다Certified-Data-Engineer-Professional최신 인증시험 덤프데모
- Certified-Data-Engineer-Professional최고품질 덤프데모 다운 🚘 Certified-Data-Engineer-Professional최신버전 인기덤프 🎏 Certified-Data-Engineer-Professional퍼펙트 덤프데모문제 🩳 지금⇛ www.dumptop.com ⇚을(를) 열고 무료 다운로드를 위해➽ Certified-Data-Engineer-Professional 🢪를 검색하십시오Certified-Data-Engineer-Professional시험문제모음
- Certified-Data-Engineer-Professional유효한 덤프 😍 Certified-Data-Engineer-Professional인증시험 🌇 Certified-Data-Engineer-Professional유효한 덤프 👯 시험 자료를 무료로 다운로드하려면“ www.itdumpskr.com ”을 통해✔ Certified-Data-Engineer-Professional ️✔️를 검색하십시오Certified-Data-Engineer-Professional최신 인증시험 덤프데모
- 최신버전 Certified-Data-Engineer-Professional최고품질 덤프문제모음집 퍼펙트한 덤프는 시험패스에 가장 좋은 공부자료 🎧 《 www.koreadumps.com 》에서【 Certified-Data-Engineer-Professional 】를 검색하고 무료로 다운로드하세요Certified-Data-Engineer-Professional PDF
- 최신 Certified-Data-Engineer-Professional최고품질 덤프문제모음집 인증공부문제 ⏺ 《 www.itdumpskr.com 》을(를) 열고▶ Certified-Data-Engineer-Professional ◀를 입력하고 무료 다운로드를 받으십시오Certified-Data-Engineer-Professional참고자료
- Certified-Data-Engineer-Professional최신버전 인기덤프 🏥 Certified-Data-Engineer-Professional인증시험 인기덤프 🎶 Certified-Data-Engineer-Professional최신버전 덤프공부 🕐 ⇛ www.exampassdump.com ⇚에서 검색만 하면✔ Certified-Data-Engineer-Professional ️✔️를 무료로 다운로드할 수 있습니다Certified-Data-Engineer-Professional인기덤프자료
- Certified-Data-Engineer-Professional퍼펙트 덤프데모 🌔 Certified-Data-Engineer-Professional최신 시험 공부자료 🗣 Certified-Data-Engineer-Professional시험대비 최신 덤프모음집 🔷 무료 다운로드를 위해▷ Certified-Data-Engineer-Professional ◁를 검색하려면➤ www.itdumpskr.com ⮘을(를) 입력하십시오Certified-Data-Engineer-Professional인증시험
- Certified-Data-Engineer-Professional유효한 최신덤프자료 🦪 Certified-Data-Engineer-Professional최신 시험 공부자료 ☯ Certified-Data-Engineer-Professional유효한 최신덤프자료 👳 무료 다운로드를 위해⏩ Certified-Data-Engineer-Professional ⏪를 검색하려면✔ www.itdumpskr.com ️✔️을(를) 입력하십시오Certified-Data-Engineer-Professional시험문제모음
- Certified-Data-Engineer-Professional최신버전 인기덤프 💬 Certified-Data-Engineer-Professional유효한 덤프 🔁 Certified-Data-Engineer-Professional시험문제모음 🐭 오픈 웹 사이트➤ www.itdumpskr.com ⮘검색⏩ Certified-Data-Engineer-Professional ⏪무료 다운로드Certified-Data-Engineer-Professional시험대비 최신 덤프모음집
- 시험대비 Certified-Data-Engineer-Professional최고품질 덤프문제모음집 덤프자료 📅 지금☀ www.passtip.net ️☀️에서➤ Certified-Data-Engineer-Professional ⮘를 검색하고 무료로 다운로드하세요Certified-Data-Engineer-Professional최신버전 인기덤프
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes