It’s important for the safety of the website while buying the DP-800 Exam Bootcamp online. We have in this business for years and the professional of our team will check the website timely, if you buy the DP-800 exam bootcamp of us, we can ensure the safety of yours, and if you indeed have some problems while operating, you can contact us, we will handle it for you. Safety is very important, it can help you avoid many unnecessary troubles.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Developing AI-Enabled Database Solutions |
| Exam Number: | DP-800 |
| Exam Duration: | 100 minutes |
| Real Exam Qty: | 40-60 |
| Available Languages: | Japanese, Portuguese (Brazil), French, Chinese (Simplified), German, Korean, English, Spanish |
| Exam Price: | $165 USD |
| Exam Format: | Drag and drop, Case studies, Active screen, Multiple choice, Multiple select |
| Certificate Validity Period: | 1 year (renewable annually via free online assessment) |
| Passing Score: | 700 (on a scale of 1-1000) |
| Recommended Training: | Microsoft Learn DP-800 Learning Path |
| Exam Registration: | Pearson VUE Registration |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE test centers |
| Pre Condition: | No mandatory prerequisites; recommended experience: T-SQL development, SQL Server/Azure SQL, CI/CD practices, basic AI concepts |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/resources/study-guides/dp-800 |
>> Latest DP-800 Dumps Free <<
In this cut-throat competitive world of Microsoft, the Microsoft DP-800 certification is the most desired one. But what creates an obstacle in the way of the aspirants of the Developing AI-Enabled Database Solutions (DP-800) certificate is their failure to find up-to-date, unique, and reliable Developing AI-Enabled Database Solutions (DP-800) practice material to succeed in passing the Microsoft DP-800 certification exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 77
You have an Azure SQL database that contains the following SQL graph tables:
- A NODE table named dbo.Person
- An EDGE table named dbo.Knows
Each row in dbo.Person contains the following columns:
- PersonID (int)
- DisplayName (nvarchar(100))
You need to use a MATCH operator and exactly two directed Knows relationships to return the PersonID and DisplayName of people that are reachable from the person identified by an input parameter named @StartPersonId.
Which Transact-SQL query should you use?
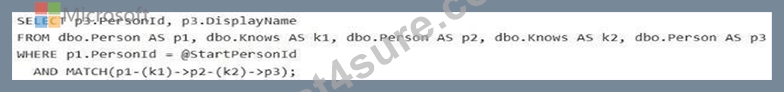
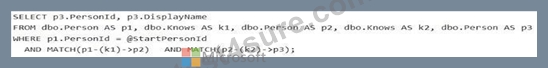
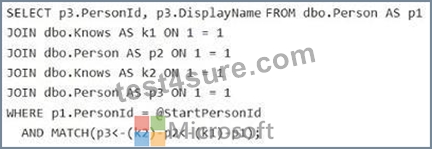
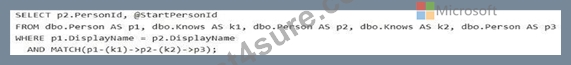
Answer: A
Explanation:
To achieve this using SQL Graph in Azure SQL, you use the MATCH clause to define the path.
Since you need exactly two directed relationships (A → B → C), you must chain the edge table twice in the same direction.
Transact-SQL Statement
SELECT
Person3.ID,
Person3.NameColumn -- Replace with your actual nvarchar(100) column name FROM PersonNodeTable AS Person1, KnowsEdgeTable AS Knows1, PersonNodeTable AS Person2, KnowsEdgeTable AS Knows2, PersonNodeTable AS Person3 WHERE MATCH(Person1-(Knows1)->Person2-(Knows2)->Person3) AND Person1.ID = @InputID; Use code with caution.
Key Components
MATCH Clause: Defines the traversal pattern. The syntax (Node)-(Edge)->(Node) ensures the relationship is directed.
Chaining: To get "exactly two" steps, you define three node aliases and two edge aliases.
Aliases: Each instance of the table must have a unique alias (e.g., Person1, Person2, Person3) so the engine can distinguish between the different points in the path.
Filtering: The WHERE clause uses your input parameter (@InputID) to set the starting point of the graph traversal Incorrect:
[Not A]
Need three persons, not two.
[Not B]
Do not use JOIN.
[Not C]
Incorrect MATCH statement.
Reference:
https://learn.microsoft.com/en-us/sql/relational-databases/graphs/sql-graph-sample
NEW QUESTION # 78
You are developing an Azure SQL solution by using Microsoft Visual Studio 2026. The solution uses a GitHub repository.
You plan to use GitHub Copilot Chat to access the GitHub repository tools by connecting to the GitHub MCP Server.
You need to configure Visual Studio to support the planned configuration. The solution must rely on OAuth to access the MCP server.
What should you create?
Answer: D
Explanation:
In this scenario, you need to create an mcp.json file. This file acts as the configuration bridge that tells Visual Studio 2026 and GitHub Copilot Chat how to connect to and communicate with the GitHub MCP Server.
Key Configuration Details
The mcp.json file is typically placed in your solution's root directory or a specific .mcp folder to enable project-specific tools Configuration Steps
1. Create the MCP Configuration File
You must define the connection to the GitHub MCP server so Copilot Chat can interact with your repository tools.
File Name: mcp.json
Location: Usually placed in %AppData%\Microsoft\VisualStudio\2026\mcp.json (or the project root depending on your specific extension settings).
Content:
{
"mcpServers": {
"github": {
"url": "https://api.githubcopilot.com/mcp/",
"auth": "OAuth"
}
}
}
2. Authenticate via OAuth
3. Connect Azure SQL in VS 2026
Reference:
https://www.workato.com/the-connector/mcp-server-tutorial/
NEW QUESTION # 79
Drag and Drop Question
You have a SQL database in Microsoft Fabric that contains a table named WebSite.Logs.
WebSite.Logs stores application telemetry data. WebSite.Logs contains a nvarchar (max) column named log that stores JSON documents.
You have a daily report that filters by the $.severity JSON property and returns LogId, LogDateTime, and log. The report frequently causes full table scans.
You need to modify WebSite.Logs to support efficient filtering by $.severity and avoid key lookups for the columns returned by the report.
How should you complete the Transact-SQL code to avoid full table scans? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.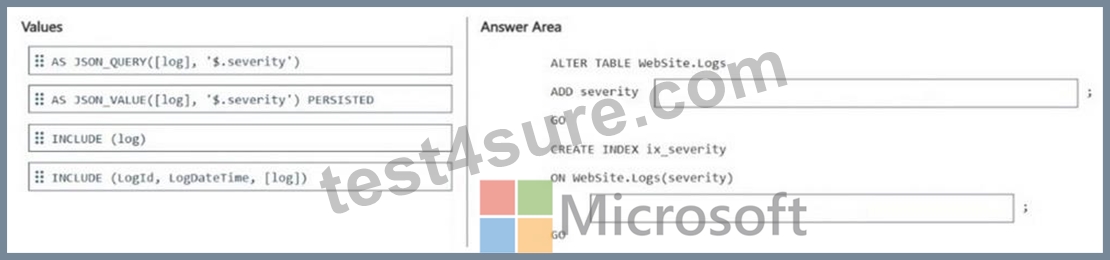
Answer:
Explanation: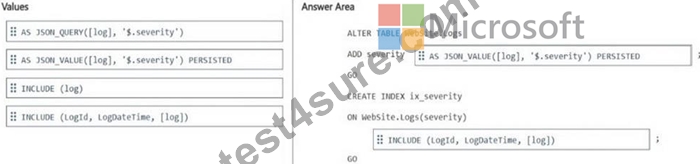
NEW QUESTION # 80
You have an Azure SQL database that contains the following tables and columns.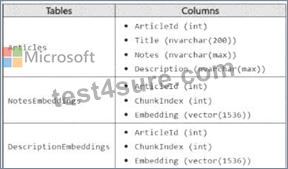
Embeddings in the NotesEnbeddings and DescriptionEabeddings tables have been generated from values in the Description and notes columns of the Articles table by using different chunk sizes.
You need to perform approximate nearest neighbor (ANN) queries across both embedding tables. The solution must minimize the impact of using different chunk sizes.
What should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.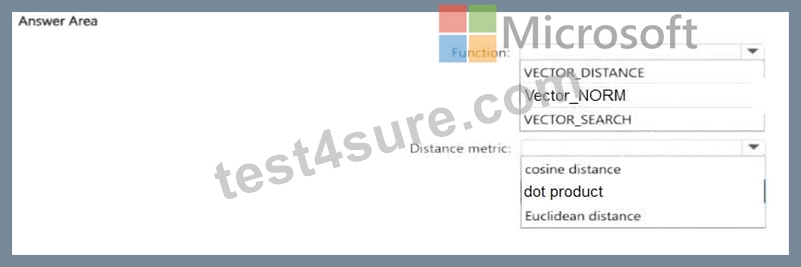
Answer:
Explanation: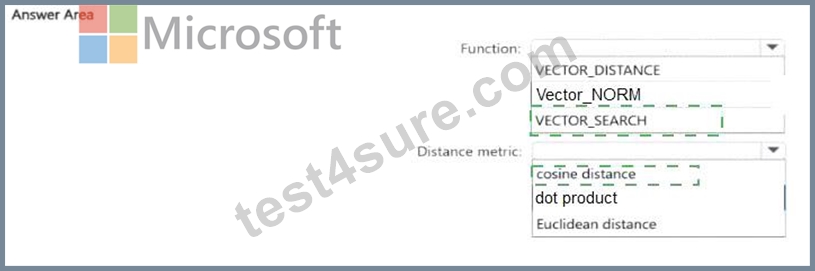
Explanation: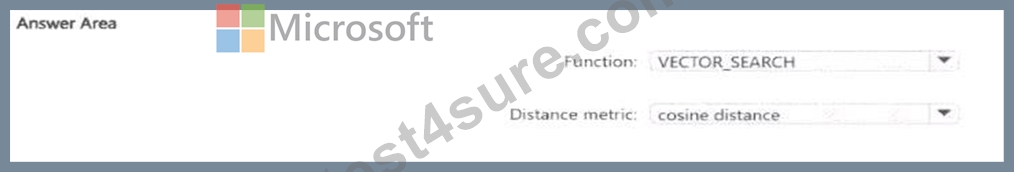
The correct function is VECTOR_SEARCH because the requirement is to perform approximate nearest neighbor (ANN) queries. Microsoft's SQL documentation states that VECTOR_SEARCH is the function used for vector similarity search, and that an ANN index is used only with VECTOR_SEARCH when a compatible vector index exists on the target column. By contrast, VECTOR_DISTANCE calculates an exact distance and does not use a vector index for ANN retrieval.
The correct distance metric is cosine distance. Microsoft documents that VECTOR_SEARCH supports cosine, dot, and euclidean metrics, and Microsoft guidance specifically notes that cosine similarity is commonly used for text embeddings. It also states that retrieval of the most similar texts to a given text typically functions better with cosine similarity, and that Azure OpenAI embeddings rely on cosine similarity to compute similarity between a query and documents. Since both NotesEmbeddings and DescriptionEmbeddings are text-derived embeddings and the goal is to minimize the impact of different chunk sizes, cosine is the best choice because it compares direction/angle rather than being as sensitive to vector magnitude as Euclidean distance.
NEW QUESTION # 81
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.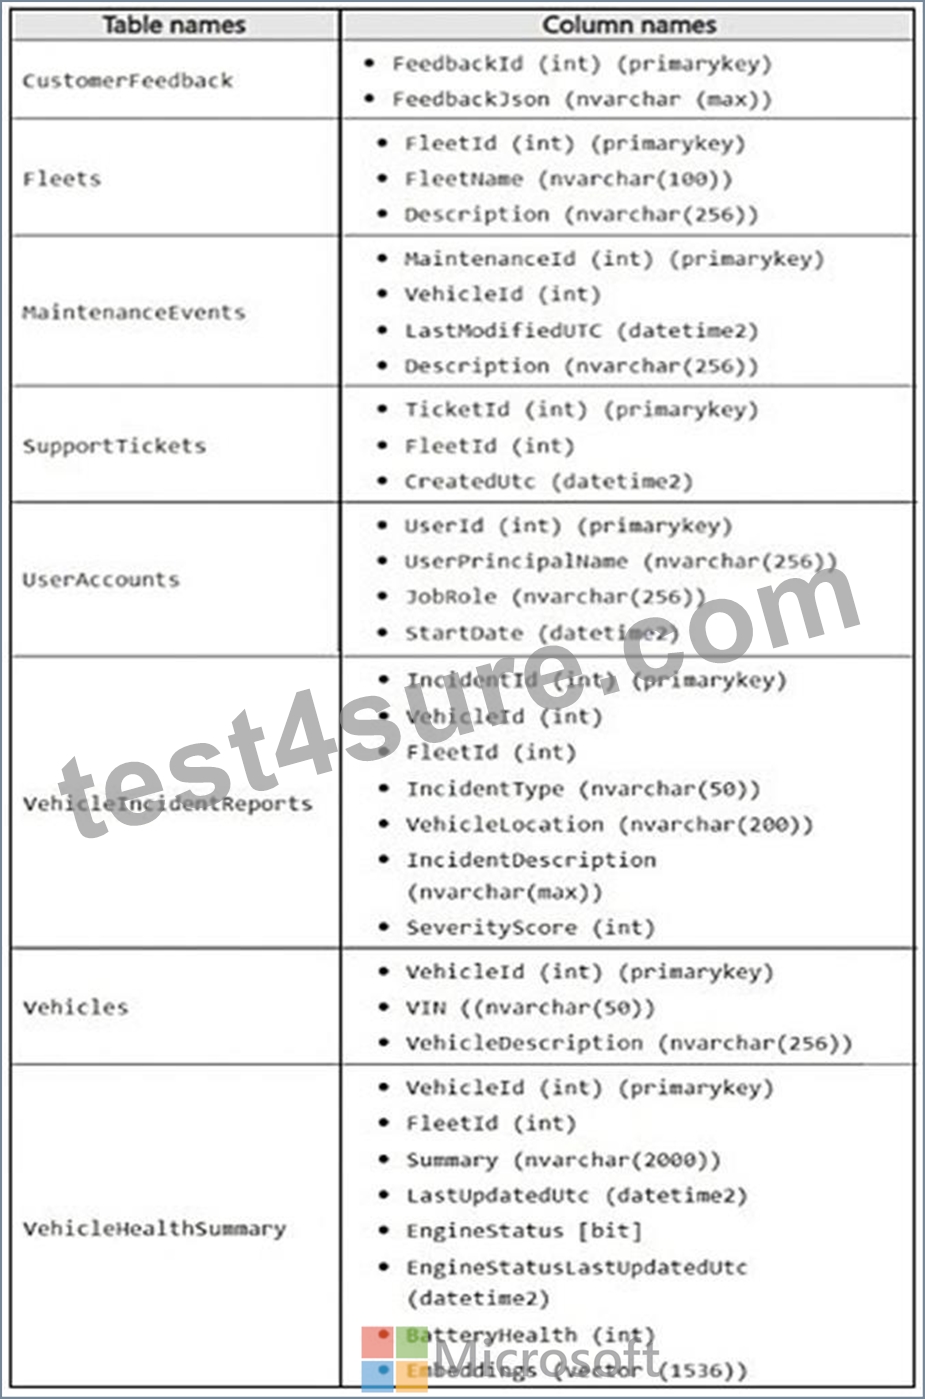
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.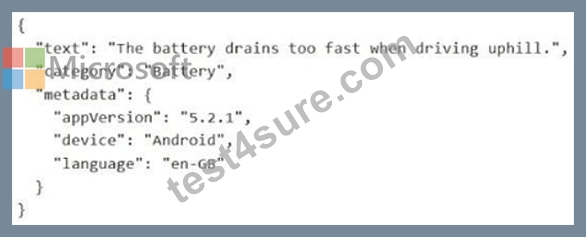
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.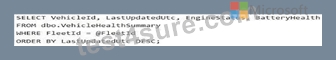
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
Drag and Drop Question
You need to meet the database performance requirements for maintenance data.
How should you complete the Transact-SQL code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.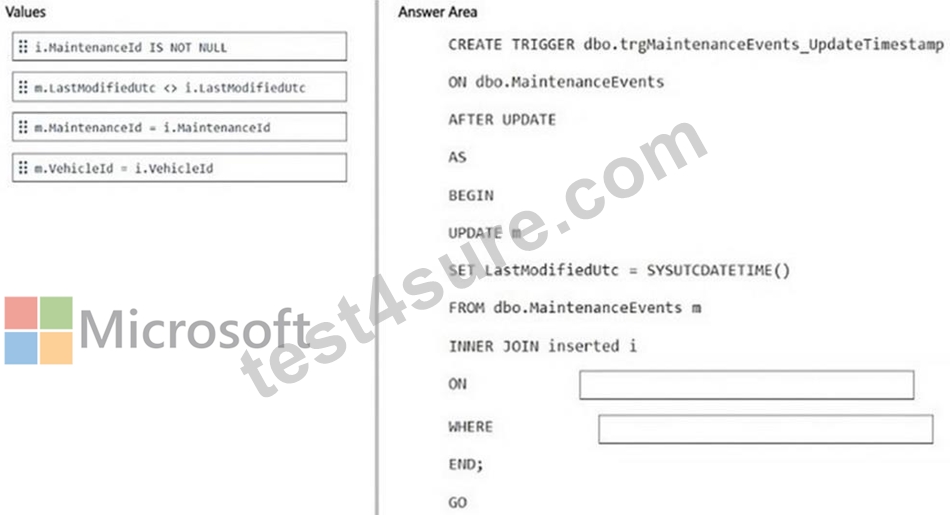
Answer:
Explanation: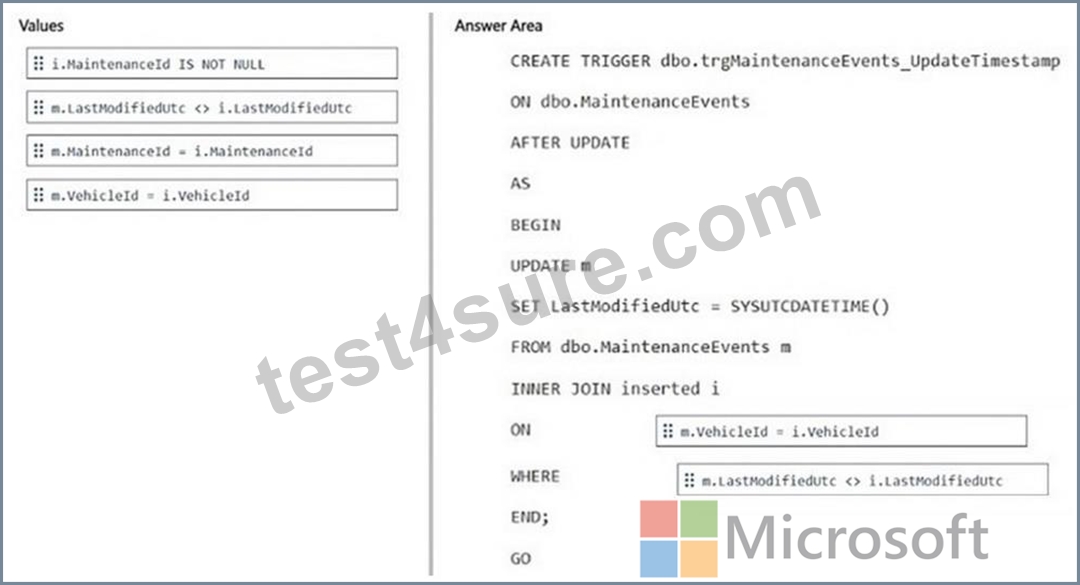
NEW QUESTION # 82
......
Latest DP-800 Exam Preparation: https://www.test4sure.com/DP-800-pass4sure-vce.html