Demo Certified-Data-Engineer-Professional Test - Certified-Data-Engineer-Professional Latest Test Simulator

We all know that Certified-Data-Engineer-Professional study materials can help us solve learning problems. But if it is too complex, not only can’t we get good results, but also the burden of students' learning process will increase largely. Unlike those complex and esoteric materials, our Certified-Data-Engineer-Professional Study Materials are not only of high quality, but also easy to learn. Our study materials do not have the trouble that users can't read or learn because we try our best to present those complex and difficult test sites in a simple way.
| Section | Objectives |
|---|
| Topic 1: Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 4. Use Query Profile and Spark UI to monitor workloads
|
| Topic 2: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 3: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
|
| Topic 4: Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Topic 5: Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Topic 6: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
|
| Topic 7: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 2. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 3. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 4. Apply Change Data Feed to address streaming table limitations and improve latency
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Topic 8: Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Identify the benefits of liquid clustering over partitioning and Z-Ordering
|
| Topic 9: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 2. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 3. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 4. Create pipeline components using control flow operators such as if/else and foreach
- 5. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 6. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 7. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 8. Explain the advantages and disadvantages of streaming tables compared to materialized views
|
| Topic 10: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
>> Demo Certified-Data-Engineer-Professional Test <<
Certified-Data-Engineer-Professional Latest Test Simulator & Certified-Data-Engineer-Professional Regualer Update
Hundreds of candidates want to get the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) certification exam because it helps them in accelerating their Databricks careers. Cracking the Certified-Data-Engineer-Professional exam of this credential is vital when it comes to the up gradation of their resume. The Certified-Data-Engineer-Professional Certification Exam helps students earn from online work and it also benefits them in order to get a job in any good tech company.
Databricks Certified Data Engineer Professional Sample Questions (Q179-Q184):
NEW QUESTION # 179
A data engineering team is implementing an append-only data pipeline using Delta Lake, and wants to ensure that data is never modified or deleted once written. Which Delta Lake feature should the data engineer enable to prevent modifications to existing data?
- A. Delta VACUUM
- B. Delta Time Travel
- C. Delta OPTIMIZE
- D. Delta APPEND_ONLY
Answer: D
Explanation:
Enabling the append-only table property enforces that data can only be inserted into the Delta table. Updates and deletes are blocked, ensuring that once data is written it is never modified or removed, which is essential for strict append-only pipeline guarantees.
NEW QUESTION # 180
A Delta Lake table was created with the below query:
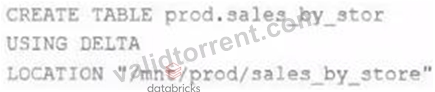
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
- A. The table reference in the metastore is updated and all data files are moved.
- B. The table name change is recorded in the Delta transaction log.
- C. All related files and metadata are dropped and recreated in a single ACID transaction.
- D. The table reference in the metastore is updated and no data is changed.
- E. A new Delta transaction log Is created for the renamed table.
Answer: D
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly.
NEW QUESTION # 181
A data engineer is working on a Databricks notebook that requires several third-party Python libraries. Some of these are available on PyPI, while others are custom-developed and stored as local.wheel (.whl) and source (.tar.gz) files in an S3 bucket. The goal is to ensure all dependencies are installed and correctly available across multiple jobs running on any automated cluster in a Unity Catalog-enabled workspace. The engineer needs to install the required dependencies in a way that ensures a consistent environment setup across interactive notebooks and jobs and complies with workspace security policies (no internet access). Which approach should the engineer use to install and manage these dependencies while also ensuring reproducibility and compliance?
- A. Use %pip install in every notebook and job to install packages directly from PyPl and custom S3 paths.
- B. Install all dependencies manually in the driver node of an interactive cluster, then export the environment and reimport on job clusters using %conda.
- C. Create a Python wheel file for the entire project, upload it to the Databricks Workspace Files or Volumes, and install it using a Cluster Library or pip install in a requirements.txt declared within a Databricks Asset Bundle.
- D. Use an init script on the cluster to install all dependencies using pip, referencing the local file system.
Answer: C
Explanation:
Packaging dependencies as wheel files and managing them through Databricks-supported artifacts ensures consistent, reproducible environments across interactive and job clusters.
Storing the wheels in Workspace Files or Unity Catalog Volumes complies with no-internet security constraints, while installing them via cluster libraries or Asset Bundles standardizes dependency management across all jobs and pipelines.
NEW QUESTION # 182
The Databricks CLI is use to trigger a run of an existing job by passing the job_id parameter. The response that the job run request has been submitted successfully includes a filed run_id.
Which statement describes what the number alongside this field represents?
- A. The job_id is returned in this field.
- B. The globally unique ID of the newly triggered run.
- C. The total number of jobs that have been run in the workspace.
- D. The job_id and number of times the job has been are concatenated and returned.
- E. The number of times the job definition has been run in the workspace.
Answer: B
Explanation:
When triggering a job run using the Databricks CLI, the run_id field in the response represents a globally unique identifier for that particular run of the job. This run_id is distinct from the job_id.
While the job_id identifies the job definition and is constant across all runs of that job, the run_id is unique to each execution and is used to track and query the status of that specific job run within the Databricks environment. This distinction allows users to manage and reference individual executions of a job directly.
NEW QUESTION # 183
The data engineering team is migrating an enterprise system with thousands of tables and views into the Lakehouse. They plan to implement the target architecture using a series of bronze, silver, and gold tables. Bronze tables will almost exclusively be used by production data engineering workloads, while silver tables will be used to support both data engineering and machine learning workloads. Gold tables will largely serve business intelligence and reporting purposes. While personal identifying information (PII) exists in all tiers of data, pseudonymization and anonymization rules are in place for all data at the silver and gold levels.
The organization is interested in reducing security concerns while maximizing the ability to collaborate across diverse teams.
Which statement exemplifies best practices for implementing this system?
- A. Working in the default Databricks database provides the greatest security when working with managed tables, as these will be created in the DBFS root.
- B. Storinq all production tables in a single database provides a unified view of all data assets available throughout the Lakehouse, simplifying discoverability by granting all users view privileges on this database.
- C. Because all tables must live in the same storage containers used for the database they're created in, organizations should be prepared to create between dozens and thousands of databases depending on their data isolation requirements.
- D. Isolating tables in separate databases based on data quality tiers allows for easy permissions management through database ACLs and allows physical separation of default storage locations for managed tables.
- E. Because databases on Databricks are merely a logical construct, choices around database organization do not impact security or discoverability in the Lakehouse.
Answer: D
Explanation:
This is the correct answer because it exemplifies best practices for implementing this system. By isolating tables in separate databases based on data quality tiers, such as bronze, silver, and gold, the data engineering team can achieve several benefits. First, they can easily manage permissions for different users and groups through database ACLs, which allow granting or revoking access to databases, tables, or views. Second, they can physically separate the default storage locations for managed tables in each database, which can improve performance and reduce costs. Third, they can provide a clear and consistent naming convention for the tables in each database, which can improve discoverability and usability.
NEW QUESTION # 184
......
Our company keeps pace with contemporary talent development and makes every learners fit in the needs of the society. Based on advanced technological capabilities, our Certified-Data-Engineer-Professional study materials are beneficial for the masses of customers. Our experts have plenty of experience in meeting the requirement of our customers and try to deliver satisfied Certified-Data-Engineer-Professional Exam guides to them. Our Certified-Data-Engineer-Professional exam prepare is definitely better choice to help you go through the Certified-Data-Engineer-Professional test. Buy our Certified-Data-Engineer-Professional exam questions, the success is just ahead of you.
Certified-Data-Engineer-Professional Latest Test Simulator: https://www.validtorrent.com/Certified-Data-Engineer-Professional-valid-exam-torrent.html
- Pass Guaranteed Quiz Databricks - Perfect Certified-Data-Engineer-Professional - Demo Databricks Certified Data Engineer Professional Test 👠 ✔ www.exam4labs.com ️✔️ is best website to obtain ✔ Certified-Data-Engineer-Professional ️✔️ for free download 🦆Certified-Data-Engineer-Professional 100% Accuracy
- Exam Discount Certified-Data-Engineer-Professional Voucher 🍾 Exam Discount Certified-Data-Engineer-Professional Voucher 🚜 Certified-Data-Engineer-Professional Real Torrent 🧔 Search for 《 Certified-Data-Engineer-Professional 》 and download exam materials for free through ▷ www.pdfvce.com ◁ 🐪Exam Sample Certified-Data-Engineer-Professional Questions
- Pass Guaranteed Quiz Pass-Sure Databricks - Demo Certified-Data-Engineer-Professional Test 🔝 Go to website ▶ www.vce4dumps.com ◀ open and search for 「 Certified-Data-Engineer-Professional 」 to download for free 🧽Certified-Data-Engineer-Professional Exam Braindumps
- 100% Pass Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Accurate Demo Test 🚌 Search for 「 Certified-Data-Engineer-Professional 」 and obtain a free download on ☀ www.pdfvce.com ️☀️ 🏬Certified-Data-Engineer-Professional 100% Accuracy
- Correct Demo Certified-Data-Engineer-Professional Test - Leader in Qualification Exams - Pass-Sure Certified-Data-Engineer-Professional Latest Test Simulator 🎌 《 www.exam4labs.com 》 is best website to obtain ⇛ Certified-Data-Engineer-Professional ⇚ for free download 🎴Latest Certified-Data-Engineer-Professional Braindumps
- Databricks Certified-Data-Engineer-Professional Exam Practice Questions are Real and Verified By Experts 👆 Download [ Certified-Data-Engineer-Professional ] for free by simply entering ⏩ www.pdfvce.com ⏪ website 😃Valid Certified-Data-Engineer-Professional Exam Sample
- Exam Discount Certified-Data-Engineer-Professional Voucher 💙 New Certified-Data-Engineer-Professional Cram Materials 🤴 New Certified-Data-Engineer-Professional Cram Materials 🔂 Open ▷ www.troytecdumps.com ◁ and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download exam materials for free 💉Certified-Data-Engineer-Professional Real Torrent
- New Certified-Data-Engineer-Professional Cram Materials 🧐 Exam Discount Certified-Data-Engineer-Professional Voucher 🔏 New Certified-Data-Engineer-Professional Cram Materials 💽 Open 《 www.pdfvce.com 》 and search for ▛ Certified-Data-Engineer-Professional ▟ to download exam materials for free 🔕Certified-Data-Engineer-Professional Best Practice
- Certified-Data-Engineer-Professional Real Dumps Free 🌗 Certified-Data-Engineer-Professional Exam Braindumps 🛬 Valid Certified-Data-Engineer-Professional Exam Sample 🚂 Open website ➤ www.prepawayexam.com ⮘ and search for ➡ Certified-Data-Engineer-Professional ️⬅️ for free download 🧫Certified-Data-Engineer-Professional Learning Engine
- Databricks Trustable Demo Certified-Data-Engineer-Professional Test – Pass Certified-Data-Engineer-Professional First Attempt 🕘 Immediately open { www.pdfvce.com } and search for ⮆ Certified-Data-Engineer-Professional ⮄ to obtain a free download 🧂Reliable Certified-Data-Engineer-Professional Test Camp
- Exam Sample Certified-Data-Engineer-Professional Questions 🔲 Certified-Data-Engineer-Professional Test Voucher 🗾 Certified-Data-Engineer-Professional Learning Engine 🎹 Search for 「 Certified-Data-Engineer-Professional 」 and obtain a free download on ➡ www.torrentvce.com ️⬅️ 📊Exam Sample Certified-Data-Engineer-Professional Questions
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes