DOWNLOAD the newest ValidVCE Professional-Machine-Learning-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1EH2KgPeKc3maS4wBVUeiZH_uw6MI2TcN
Passing the Professional-Machine-Learning-Engineer exam has never been so efficient or easy when getting help from our Professional-Machine-Learning-Engineer training materials. This way is not only financially accessible, but time-saving and comprehensive to deal with the important questions emerging in the real exam. All exams from different suppliers will be easy to handle. Actually, this Professional-Machine-Learning-Engineer Exam is not only practical for working or studying conditions, but a manifest and prestigious show of your personal ability.
The Professional Machine Learning Engineer exam is a performance-based assessment that evaluates the candidate's ability to solve real-world problems using machine learning techniques. Professional-Machine-Learning-Engineer Exam consists of a series of hands-on tasks that require the candidate to demonstrate their understanding of various machine learning concepts and their ability to apply them in practical scenarios. Professional-Machine-Learning-Engineer exam is conducted online and can be taken from anywhere in the world.
To be eligible for the exam, candidates must have experience in developing and deploying machine learning models using Google Cloud Platform. They should also have experience with programming languages such as Python and SQL, and knowledge of machine learning concepts such as supervised and unsupervised learning, reinforcement learning, and deep learning.
>> Professional-Machine-Learning-Engineer Mock Exams <<
If someone who can pass the exam, they can earn a high salary in a short time. If you decide to beat the exam, you must try our Professional-Machine-Learning-Engineer exam torrent, then, you will find that it is so easy to pass the exam. You only need little time and energy to review and prepare for the exam if you use our Google Professional Machine Learning Engineer prep torrent as the studying materials. So it is worthy for them to buy our product. We provide the introduction of the features and advantages of our Professional-Machine-Learning-Engineer Test Prep as follow so as to let you have a good understanding of our product before your purchase.
The Google Professional Machine Learning Engineer certification proves that the successful candidates possess sufficient knowledge and skills to design and create scalable solutions for optimal performance. Some of the job roles that these individuals can consider include a Data Engineer, a Senior Data Engineer, a Machine Learning Engineer, a Technical Solutions Engineer, a Software Engineer, and a Cloud Infrastructure Engineer, among others. The median salary that the certificate holders can count on is around $140,000 per annum.
NEW QUESTION # 333
You are an ML engineer in the contact center of a large enterprise. You need to build a sentiment analysis tool that predicts customer sentiment from recorded phone conversations. You need to identify the best approach to building a model while ensuring that the gender, age, and cultural differences of the customers who called the contact center do not impact any stage of the model development pipeline and results. What should you do?
Answer: C
Explanation:
Sentiment analysis is the process of identifying and extracting the emotions, opinions, and attitudes expressed in a text or speech. Sentiment analysis can help businesses understand their customers' feedback, satisfaction, and preferences. There are different approaches to building a sentiment analysis tool, depending on the input data and the output format. Some of the common approaches are:
* Extracting sentiment directly from the voice recordings: This approach involves using acoustic features, such as pitch, intensity, and prosody, to infer the sentiment of the speaker. This approach can capture the nuances and subtleties of the vocal expression, but it also requires a large and diverse dataset of labeled voice recordings, which may not be easily available or accessible. Moreover, this approach may not account for the semantic and contextual information of the speech, which can also affect the sentiment.
* Converting the speech to text and building a model based on the words: This approach involves using automatic speech recognition (ASR) to transcribe the voice recordings into text, and then using lexical features, such as word frequency, polarity, and valence, to infer the sentiment of the text. This approach can leverage the existing text-based sentiment analysis models and tools, but it also introduces some challenges, such as the accuracy and reliability of the ASR system, the ambiguity and variability of the natural language, and the loss of the acoustic information of the speech.
* Converting the speech to text and extracting sentiments based on the sentences: This approach involves using ASR to transcribe the voice recordings into text, and then using syntactic and semantic features, such as sentence structure, word order, and meaning, to infer the sentiment of the text. This approach can capture the higher-level and complex aspects of the natural language, such as negation, sarcasm, and irony, which can affect the sentiment. However, this approach also requires more sophisticated and
* advanced natural language processing techniques, such as parsing, dependency analysis, and semantic role labeling, which may not be readily available or easy to implement.
* Converting the speech to text and extracting sentiment using syntactical analysis: This approach involves using ASR to transcribe the voice recordings into text, and then using syntactical analysis, such as part-of-speech tagging, phrase chunking, and constituency parsing, to infer the sentiment of the text.
This approach can identify the grammatical and structural elements of the natural language, such as nouns, verbs, adjectives, and clauses, which can indicate the sentiment. However, this approach may not account for the pragmatic and contextual information of the speech, such as the speaker's intention, tone, and situation, which can also influence the sentiment.
For the use case of building a sentiment analysis tool that predicts customer sentiment from recorded phone conversations, the best approach is to convert the speech to text and extract sentiments based on the sentences.
This approach can balance the trade-offs between the accuracy, complexity, and feasibility of the sentiment analysis tool, while ensuring that the gender, age, and cultural differences of the customers who called the contact center do not impact any stage of the model development pipeline and results. This approach can also handle different types and levels of sentiment, such as polarity (positive, negative, or neutral), intensity (strong or weak), and emotion (anger, joy, sadness, etc.). Therefore, converting the speech to text and extracting sentiments based on the sentences is the best approach for this use case.
NEW QUESTION # 334
You have developed a fraud detection model for a large financial institution using Vertex AI. The model achieves high accuracy, but the stakeholders are concerned about the model's potential for bias based on customer demographics. You have been asked to provide insights into the model's decision-making process and identify any fairness issues. What should you do?
Answer: B
Explanation:
Feature attribution in Vertex AI (using tools like SHAP or integrated gradients) provides transparency into which features most influence the model's predictions. This helps identify whether demographic features are contributing disproportionately, which is essential for detecting and addressing fairness concerns. It aligns with stakeholder needs for explainability and bias detection.
NEW QUESTION # 335
You trained a text classification model. You have the following SignatureDefs: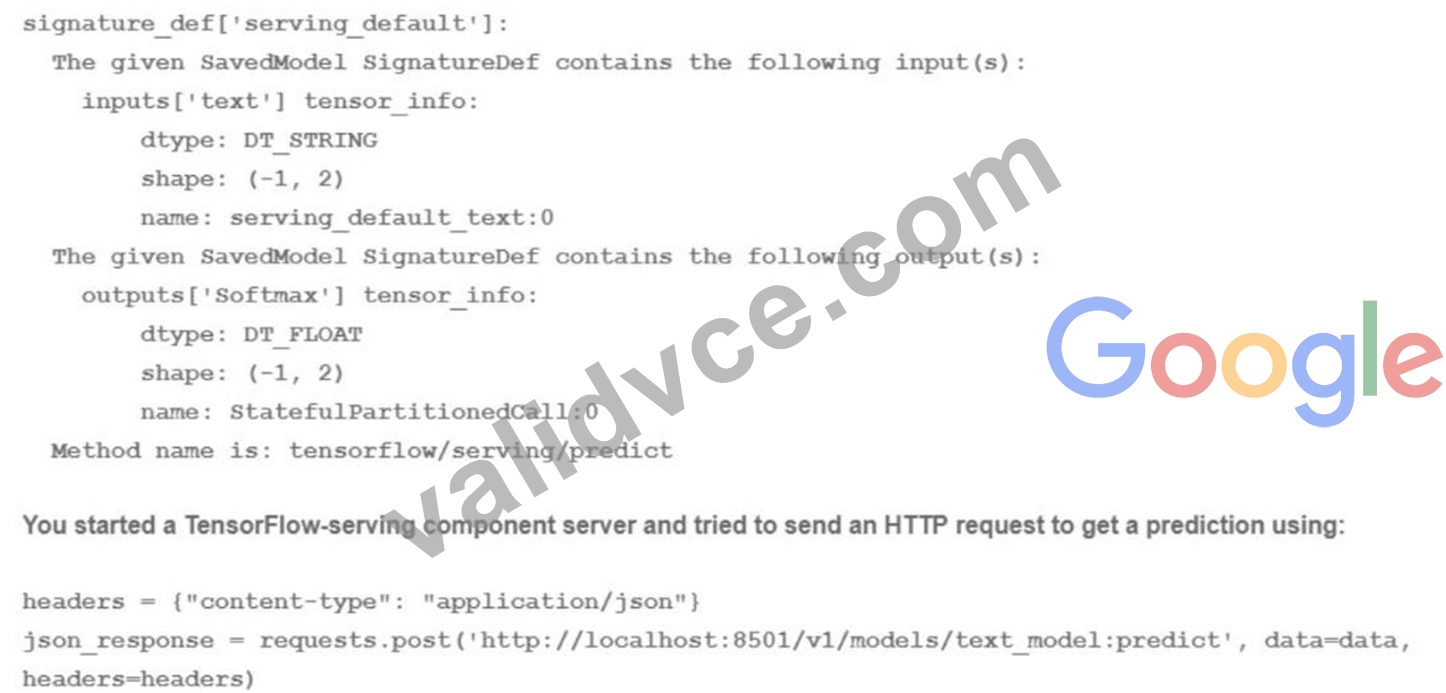
What is the correct way to write the predict request?
Answer: B
Explanation:
A predict request is a way to send data to a trained model and get predictions in return. A predict request can be written in different formats, such as JSON, protobuf, or gRPC, depending on the service and the platform that are used to host and serve the model. A predict request usually contains the following information:
The signature name: This is the name of the signature that defines the inputs and outputs of the model. A signature is a way to specify the expected format, type, and shape of the data that the model can accept and produce. A signature can be specified when exporting or saving the model, or it can be automatically inferred by the service or the platform. A model can have multiple signatures, but only one can be used for each predict request.
The instances: This is the data that is sent to the model for prediction. The instances can be a single instance or a batch of instances, depending on the size and shape of the data. The instances should match the input specification of the signature, such as the number, name, and type of the input tensors.
For the use case of training a text classification model, the correct way to write the predict request is D. data json.dumps({"signature_name": "serving_default", "instances": [['a', 'b'], ['c', 'd'], ['e', 'f']]}) This option involves writing the predict request in JSON format, which is a common and convenient format for sending and receiving data over the web. JSON stands for JavaScript Object Notation, and it is a way to represent data as a collection of name-value pairs or an ordered list of values. JSON can be easily converted to and from Python objects using the json module.
This option also involves using the signature name "serving_default", which is the default signature name that is assigned to the model when it is saved or exported without specifying a custom signature name. The serving_default signature defines the input and output tensors of the model based on the SignatureDef that is shown in the image. According to the SignatureDef, the model expects an input tensor called "text" that has a shape of (-1, 2) and a type of DT_STRING, and produces an output tensor called "softmax" that has a shape of (-1, 2) and a type of DT_FLOAT. The -1 in the shape indicates that the dimension can vary depending on the number of instances, and the 2 indicates that the dimension is fixed at 2. The DT_STRING and DT_FLOAT indicate that the data type is string and float, respectively.
This option also involves sending a batch of three instances to the model for prediction. Each instance is a list of two strings, such as ['a', 'b'], ['c', 'd'], or ['e', 'f']. These instances match the input specification of the signature, as they have a shape of (3, 2) and a type of string. The model will process these instances and produce a batch of three predictions, each with a softmax output that has a shape of (1, 2) and a type of float. The softmax output is a probability distribution over the two possible classes that the model can predict, such as positive or negative sentiment.
Therefore, writing the predict request as data json.dumps({"signature_name": "serving_default", "instances": [['a', 'b'], ['c', 'd'], ['e', 'f']]}) is the correct and valid way to send data to the text classification model and get predictions in return.
Reference:
[json - JSON encoder and decoder]
NEW QUESTION # 336
You are developing ML models with Al Platform for image segmentation on CT scans. You frequently update your model architectures based on the newest available research papers, and have to rerun training on the same dataset to benchmark their performance. You want to minimize computation costs and manual intervention while having version control for your code. What should you do?
Answer: D
Explanation:
Developing ML models with AI Platform for image segmentation on CT scans requires a lot of computation and experimentation, as image segmentation is a complex and challenging task that involves assigning a label to each pixel in an image. Image segmentation can be used for various medical applications, such as tumor detection, organ segmentation, or lesion localization1 To minimize the computation costs and manual intervention while having version control for the code, one should use Cloud Build linked with Cloud Source Repositories to trigger retraining when new code is pushed to the repository. Cloud Build is a service that executes your builds on Google Cloud Platform infrastructure. Cloud Build can import source code from Cloud Source Repositories, Cloud Storage, GitHub, or Bitbucket, execute a build to your specifications, and produce artifacts such as Docker containers or Java archives2 Cloud Build allows you to set up automated triggers that start a build when changes are pushed to a source code repository. You can configure triggers to filter the changes based on the branch, tag, or file path3 Cloud Source Repositories is a service that provides fully managed private Git repositories on Google Cloud Platform. Cloud Source Repositories allows you to store, manage, and track your code using the Git version control system. You can also use Cloud Source Repositories to connect to other Google Cloud services, such as Cloud Build, Cloud Functions, or Cloud Run4 To use Cloud Build linked with Cloud Source Repositories to trigger retraining when new code is pushed to the repository, you need to do the following steps:
Create a Cloud Source Repository for your code, and push your code to the repository. You can use the Cloud SDK, Cloud Console, or Cloud Source Repositories API to create and manage your repository5 Create a Cloud Build trigger for your repository, and specify the build configuration and the trigger settings. You can use the Cloud SDK, Cloud Console, or Cloud Build API to create and manage your trigger.
Specify the steps of the build in a YAML or JSON file, such as installing the dependencies, running the tests, building the container image, and submitting the training job to AI Platform. You can also use the Cloud Build predefined or custom build steps to simplify your build configuration.
Push your new code to the repository, and the trigger will start the build automatically. You can monitor the status and logs of the build using the Cloud SDK, Cloud Console, or Cloud Build API.
The other options are not as easy or feasible. Using Cloud Functions to identify changes to your code in Cloud Storage and trigger a retraining job is not ideal, as Cloud Functions has limitations on the memory, CPU, and execution time, and does not provide a user interface for managing and tracking your builds. Using the gcloud command-line tool to submit training jobs on AI Platform when you update your code is not optimal, as it requires manual intervention and does not leverage the benefits of Cloud Build and its integration with Cloud Source Repositories. Creating an automated workflow in Cloud Composer that runs daily and looks for changes in code in Cloud Storage using a sensor is not relevant, as Cloud Composer is mainly designed for orchestrating complex workflows across multiple systems, and does not provide a version control system for your code.
NEW QUESTION # 337
You are creating a deep neural network classification model using a dataset with categorical input values. Certain columns have a cardinality greater than 10,000 unique values. How should you encode these categorical values as input into the model?
Answer: C
Explanation:
https://cloud.google.com/ai-platform/training/docs/algorithms/wide-and-deep If the column is categorical with high cardinality, then the column is treated with hashing, where the number of hash buckets equals to the square root of the number of unique values in the column.
NEW QUESTION # 338
......
Exam Professional-Machine-Learning-Engineer Preview: https://www.validvce.com/Professional-Machine-Learning-Engineer-exam-collection.html
2026 Latest ValidVCE Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1EH2KgPeKc3maS4wBVUeiZH_uw6MI2TcN