2026 Latest Prep4sures DP-800 PDF Dumps and DP-800 Exam Engine Free Share: https://drive.google.com/open?id=1cn2dTWM6IBky1VopfTpyeup6Sy4lEtVp
Constant improvements are the inner requirement for one person. As one person you can’t be satisfied with your present situation and must keep the pace of the times. You should constantly update your stocks of knowledge and practical skills. So you should attend the certificate exams such as the test DP-800 Certification to improve yourself and buying our DP-800 study materials is your optimal choice. Our DP-800 study materials combine the real exam’s needs and the practicability of the knowledge.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Microsoft Developing AI-Enabled Database Solutions (DP-800) |
| Exam Number: | DP-800 |
| Certificate Validity Period: | 1 year (Microsoft role-based certifications require annual renewal) |
| Available Languages: | English |
| Exam Format: | Multiple choice, Case studies |
| Passing Score: | 700/1000 (typical Microsoft passing score; subject to confirmation) |
| Recommended Training: | Microsoft Learn - Azure Data & AI Learning Paths |
| Exam Registration: | Microsoft Certification Dashboard |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or onsite testing center |
| Pre Condition: | No formal prerequisites required, but familiarity with Azure data services and database concepts is recommended |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/ |
Prep4sures addresses this issue by offering real Microsoft DP-800 Questions. Prep4sures's team of professionals worked tirelessly to create the DP-800 questions, ensuring that applicants have access to the most recent and genuine DP-800 Exam Questions. With Prep4sures's help, you can pass the DP-800 exam on your first attempt or claim a refund according to certain terms and conditions.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 83
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.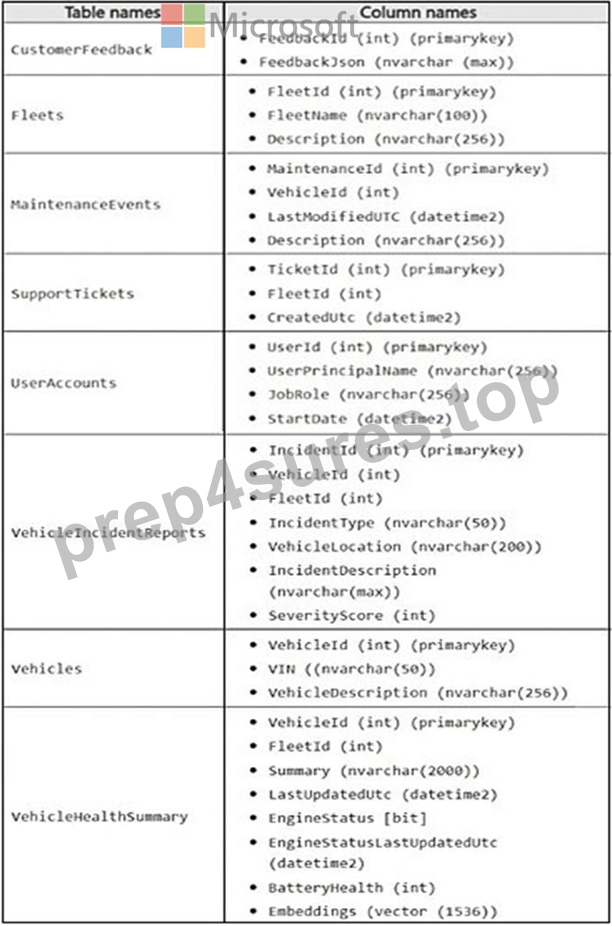
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.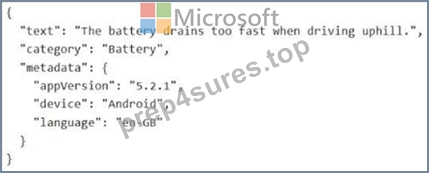
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.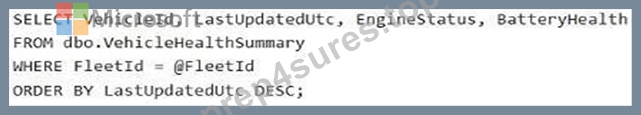
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to recommend a solution to resolve the slow dashboard query issue. What should you recommend?
Answer: A
Explanation:
Scenario:
The engineers at Contoso report that the following dashboard query runs slowly.
You review the execution plan and discover that the plan shows a clustered index scan.
To optimize this query, you should create a covering nonclustered index that handles both the filtering (WHERE) and the sorting (ORDER BY) requirements while including the remaining columns to avoid expensive lookups.
Recommended Index Strategy
Creating an index with FleetID as the first key column and LastUpdateUtc as the second key column will allow SQL Server to perform an Index Seek to find the specific fleet and then retrieve those rows in the pre-sorted order required by your ORDER BY clause.
T-SQL Implementation:
CREATE NONCLUSTERED INDEX IX_VehicleHealth_Fleet_Update
ON dbo.VehicleHealthSummary (FleetID, LastUpdateUtc DESC)
INCLUDE (EngineStatus, BatteryHealth);
Use code with caution.
Why this works
Eliminates Clustered Index Scan: The current plan scans the entire table because no index exists that starts with FleetID. This new index allows the engine to jump directly to the relevant rows.
Avoids a Sort Operator: By including LastUpdateUtc DESC in the index key, the data is already physically ordered. SQL Server can read the index and return the results immediately without needing a costly in-memory sort.
Fully Covers the Query: Using the INCLUDE clause for EngineStatus and BatteryHealth ensures all data required by the SELECT statement is present in the index. This prevents "Key Lookups," where the engine would otherwise have to go back to the original table for those specific values.
Reference:
https://www.mssqltips.com/sqlservertip/8192/sql-server-uses-non-clustered-index-rather-than- clustered-index
NEW QUESTION # 84
You have an Azure SQL database that contains a table named Customer. Customer contains the following columns:
NationalIDNumber is unique per customer.
InvestigationNotes contains free-form text.
You have a stored procedure that performs point lookups by NationalIDNumber and returns InvestigationNotes in the query results without filtering on InvestigationNotes.
You need to encrypt both columns by using Always Encrypted and the highest security possible.
Which type of Always Encrypted encryption should you use for each column?
Answer: A
NEW QUESTION # 85
Your company has an ecommerce catalog in a Microsoft SQL Server 202b database named SalesDB SalesDB contains a table named products, products contains the following columns:
* product.id (int)
* product_name (nvarchar(200))
* description (nvarchar(max))
* category (nvarchar(50))
* brand (nvarchar(W))
* price (decimal)
* sku (nvarchar(40))
The description fields ate updated dairy by a content pipeline, and price can change multiple times per day.
You want customers to be able to submit natural language queries and apply structured filters for brand and price. You plan to store embeddings in a new VECTOR(1536) column and use VECTOR_SEARCH(...
METRIC=' cosine ' ...).
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.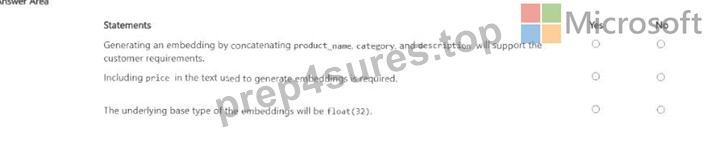
Answer:
Explanation: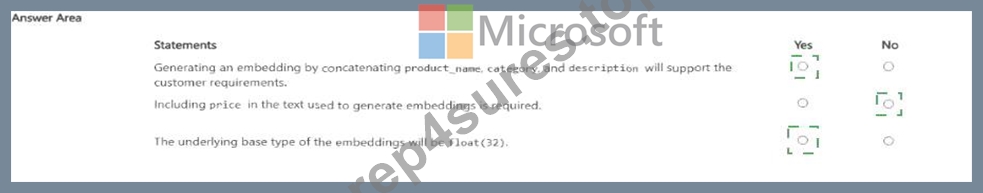
Explanation: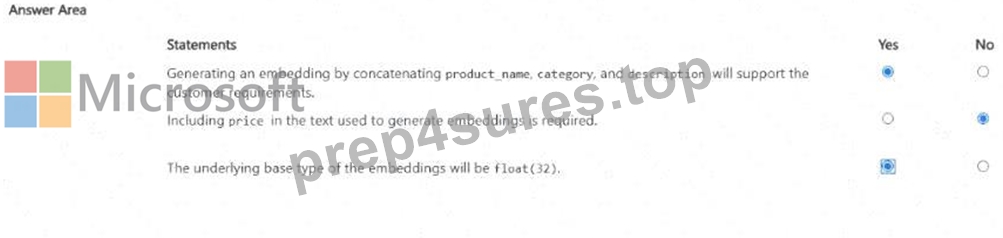
The first statement is Yes . Embeddings are used to represent the semantic meaning of content, and vector search is for conceptually similar matches over that content. Here, the semantically meaningful fields are product_name, category, and description. Using those together supports natural-language search, while brand and price can be handled as structured filters outside the embedding itself. This is an inference from Microsoft's guidance that vector search works over embeddings representing content meaning, while filters remain part of the nonvector query pipeline.
The second statement is No . price changes multiple times per day and is a structured numeric attribute, not stable semantic content. Since the requirement already says customers can apply structured filters for brand and price , price does not need to be embedded into the text. Embedding volatile numeric values would also make embeddings stale faster without improving the semantic-search objective. This is again an inference grounded in Microsoft's distinction between vector similarity over content and filtering/sorting over nonvector fields.
The third statement is Yes . In SQL Server's vector type, the default underlying base type is float32 unless float16 is specified explicitly.
NEW QUESTION # 86
You have an Azure SQL database that contains a table named dbo.ManualChunks. dbo.HonualChunks contains product manuals A retrieval query already returns the top five matching chunks as nvarchar(max) text.
You need to call an Azure OpenAI REST endpomt for chat completions. The request body must include both the user question and theretiieved chunks.
You write the following Transact-SQL code.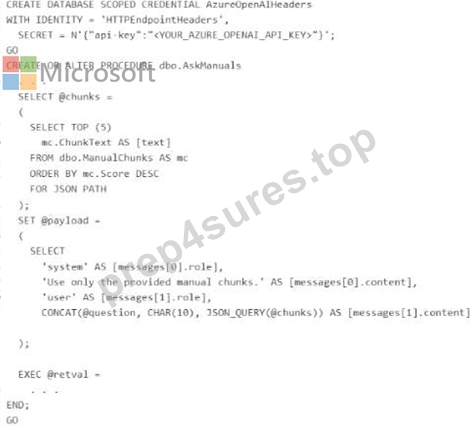
What should you insert at line 22?
Answer: D
Explanation:
The correct insertion at line 22 is FOR JSON PATH, WITHOUT_ARRAY_WRAPPER .
The request body for the Azure OpenAI chat completions call must be a single JSON object containing the messages array with both the system/user content and the retrieved chunks. Microsoft documents that FOR JSON PATH is the preferred way to shape JSON output, especially when you want precise control over nested property names like messages[0].role and messages[1] .content.
The key detail is WITHOUT_ARRAY_WRAPPER . By default, FOR JSON returns results enclosed in square brackets as a JSON array. Microsoft documents that WITHOUT_ARRAY_WRAPPER removes those brackets so a single JSON object is produced instead. That is exactly what is needed here for @payload, because the stored procedure is building one request body, not an array of request bodies.
NEW QUESTION # 87
You have a database named db1. The schema is stored in a Git repository as an SDK-style SQL database project The repository Contains the following GitHub Action workflow.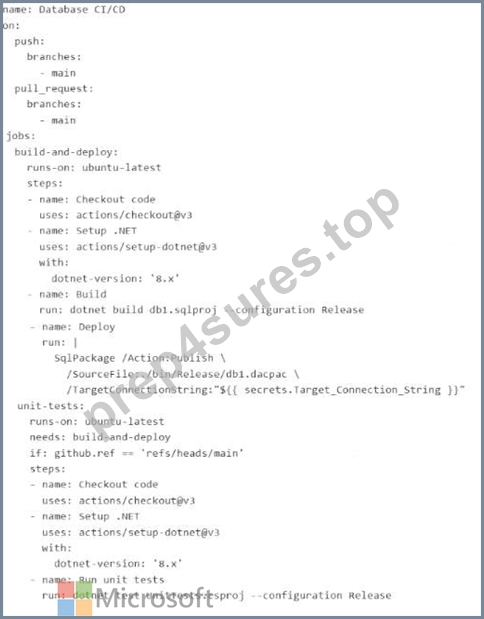
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.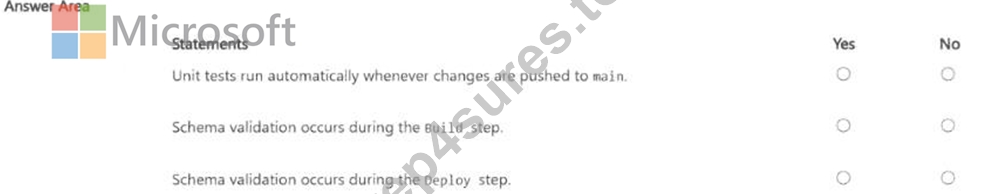
Answer:
Explanation: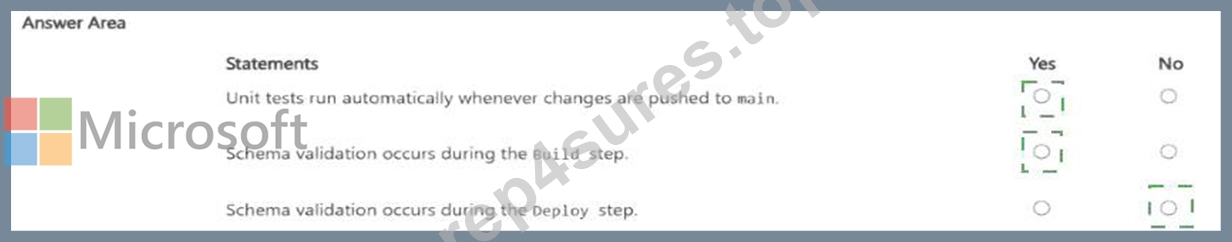
Explanation:
* Unit tests run automatically whenever changes are pushed to main. # Yes
* Schema validation occurs during the Build step. # Yes
* Schema validation occurs during the Deploy step. # No
The first statement is Yes . The workflow is configured to trigger on both push to main and pull_request targeting main. The unit-tests job has this condition:
if: github.ref == ' refs/heads/main '
On a push to main , GitHub sets github.ref to refs/heads/main, so the condition is true and the unit-tests job runs. GitHub's workflow syntax documentation confirms that push.branches: [main] triggers on pushes to main, and the github.ref value for branch pushes is the fully qualified ref such as refs/heads/main.
The second statement is Yes . The Build step runs:
dotnet build db1.sqlproj --configuration Release
For an SDK-style SQL database project, the build process produces a .dacpac and validates the database project model as part of compilation/build. Microsoft's SQL database project documentation describes SDK- style SQL projects as the project format used for SQL Database Projects, and Microsoft's command-line build documentation is specifically about building a .dacpac from that SQL project. That means schema-level project validation happens during build.
The third statement is No . The Deploy step uses:
SqlPackage /Action:Publish ...
Microsoft documents that SqlPackage Publish incrementally updates the target database schema to match the source .dacpac. That is a deployment operation, not the primary schema-validation stage of the SQL project source itself. In this workflow, the schema is validated when the SQL project is built into the .dacpac; the deploy step applies that built artifact to the target database.
NEW QUESTION # 88
......
Reliable DP-800 Braindumps Free: https://www.prep4sures.top/DP-800-exam-dumps-torrent.html
P.S. Free & New DP-800 dumps are available on Google Drive shared by Prep4sures: https://drive.google.com/open?id=1cn2dTWM6IBky1VopfTpyeup6Sy4lEtVp