時にはためらうことは多くの機会を逃すことにつながります。 弊社のNCP-BC-7.5試験の多くがPDFをダンプすると思われる場合は、Ifしないでください。 あまりにもheすると、多くの時間を無駄にします。 弊社のNCP-BC-7.5試験ダンプPDFは、気軽に準備して試験に簡単に合格するのに役立ちます。 時間を最大限に活用し、有用な認定を取得すると、他の人よりも先に上級職に就くことができます。 チャンスは準備された心を支持します。 Fast2testは、この分野の最高のNCP-BC-7.5試験ダンプPDF資料を提供します。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Troubleshoot BCDR Failures | 20% | - Resolve storage and snapshot errors - Diagnose network-related replication failures - Troubleshoot replication and protection policy issues - Resolve misconfigurations in DR environments - Fix third-party backup integration problems |
| Topic 2: Interpret and Configure BCDR Requirements | 30% | - Select replication types: Async, NearSync, Synchronous, Metro - Create and configure recovery plans - Configure network and storage for BCDR - Determine prerequisites for BCDR configuration - Configure snapshot policies and retention - Design secure BCDR environments: segmentation, RBAC, approval policies - Translate business requirements into RPO/RTO objectives |
| Topic 3: Test BCDR Solutions | 25% | - Validate recovery plan execution and outcomes - Perform disaster recovery validation procedures - Verify site connectivity and replication throughput - Execute planned, unplanned, and test failovers |
| Topic 4: Perform BCDR Operational Tasks | 25% | - Post-failover cleanup and re-protection - Execute failover and failback workflows - Snapshot-based VM and volume recovery - Migrate legacy protection domains to modern policies - Self-service restore operations |
NutanixのNCP-BC-7.5試験に関する権威のある学習教材を見つけないで、悩んでいますか?世界中での各地の人々はほとんどNutanixのNCP-BC-7.5試験を受験しています。NutanixのNCP-BC-7.5の認証試験の高品質の資料を提供しているユニークなサイトはFast2testです。もし君はまだ心配することがあったら、私たちのNutanixのNCP-BC-7.5問題集を購入する前に、一部分のフリーな試験問題と解答をダンロードして、試用してみることができます。
質問 # 30
Exhibit: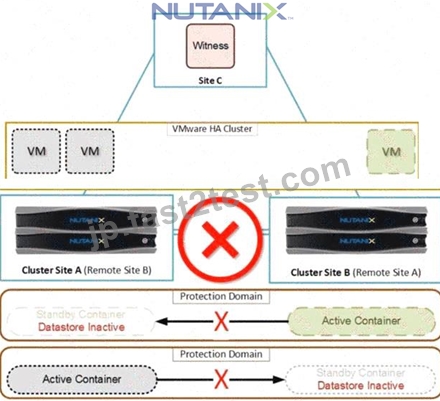
An administrator wants to protect the snapshots created on the cluster. Only authorized users should be allowed to modify or delete the snapshots on the cluster. How can the administrator harden the security of the snapshots?
正解:D
解説:
Security hardening for BCDR is focused on protecting the integrity of recovery points against accidental deletion, administrative errors, or malicious intent such as ransomware. While infrastructure-level hardening like SSH keys (Option C) or host-level security (Option A) is important, they do not prevent a user with valid administrative credentials in Prism from deleting a snapshot. To address the specific requirement of ensuring only " authorized " and verified actions can modify or delete snapshots, the administrator should implement an " Approval Policy " .
An Approval Policy introduces a " four-eyes " principle for critical management tasks. When this policy is active, any attempt to delete or modify a recovery point does not execute immediately. Instead, it triggers a request in the Prism Central " Task " console and enters a " Pending Approval " state. A separate authorized user-an " Approver " -must then review the request and explicitly grant permission before the deletion can occur. This creates a vital procedural safeguard, ensuring that no single individual has the unilateral power to destroy the organization ' s backup data. By configuring this policy, the administrator hardens the DR environment against both internal threats and external actors who might gain access to a single set of admin credentials, providing a robust layer of defense for critical data assets.
質問 # 31
An administrator at a retail company is preparing to apply a critical OS security patch to a production SQL Server VM. Before starting, the administrator ensures the VM is part of a Protection Domain and manually creates a local snapshot (Recovery Point). Ten minutes after the patch is applied, the SQL service fails to start, and the database logs indicate corruption in the system registry. The administrator needs to return the VM to its functional state from ten minutes ago as quickly as possible. The administrator decides to perform a Restore from the local snapshot. Under which condition would an In-place Restore (Revert) fail, forcing the administrator to use the Clone (Out-of-place) option instead?
正解:A
質問 # 32
A financial institution is designing a disaster recovery solution for a business-critical application that requires a zero recovery point objective (RPO). The infrastructure team decides to implement Nutanix Metro Availability between two physical data centers (DC-Alpha and DC-Beta) interconnected by a dedicated dark fiber. What is the maximum possible network latency on this link for this configuration to function correctly?
正解:A
解説:
Nutanix Metro Availability is a continuous availability solution designed to survive a site failure with zero data loss (Zero RPO). Because it operates on a synchronous replication model, every write performed by a virtual machine must be acknowledged by both the local and the remote clusters before the write is confirmed to the application. This process introduces a " latency penalty " equal to the network Round Trip Time (RTT) between the sites.
To maintain acceptable application performance and ensure cluster stability, Nutanix enforces a strict latency limit of 5 ms RTT between the primary and secondary clusters. If the latency exceeds this 5 ms threshold, the time spent waiting for remote acknowledgments would cause severe performance degradation for high-I/O workloads, such as the SQL or Oracle databases common in financial institutions. Furthermore, high latency increases the risk of the synchronous link being " broken " during periods of high data churn. While the Witness VM (used for tie-breaking) can tolerate much higher latency (up to 200 ms), the data-path link must remain under 5 ms to satisfy the technical requirements of the Metro Availability feature and the performance expectations of Tier-1 business-critical applications.
質問 # 33
Which ports must remain open to support replication between two Prism Element clusters?
正解:D
解説:
Replication between Nutanix clusters involves the transfer of both actual data blocks and the metadata required to manage the consistency and scheduling of those snapshots. Two specific services running on the Controller VMs (CVMs) are responsible for these tasks: Stargate and Cerebro.
Port TCP 2009 is used by the Stargate service. Stargate is the primary I/O manager for the Nutanix cluster, and in a BCDR context, it handles the " Snapshot-on-wire " data transfer. This is the port where the actual bits of the virtual disks are sent from the source cluster to the destination cluster. Port TCP 2020 is used by the Cerebro service. Cerebro is the replication engine that handles protection domain orchestration, snapshot scheduling, and cross-site handshake operations. Without port 2020, the clusters cannot synchronize their schedules or confirm that a recovery point has been successfully stored at the remote site. While other ports like 9440 (Prism management) and 22 (SSH) are used for administrative tasks, ports 2009 and 2020 are the mandatory " data path " and " control path " ports required for the continuous and successful replication of workloads between availability zones.
質問 # 34
A security team has detected a ransomware attack that began encrypting files on the primary site at 2:00 AM.
By 2:45 AM, the primary site is still accessible but workloads are compromised. The administrator needs to recover to a known-good state from before the attack.
Which statement shows the action and reasoning that the administrator should consider?
正解:C
解説:
In a Nutanix Disaster Recovery context, choosing the right failover type is critical during a ransomware event.
A " Planned Failover " is designed for maintenance scenarios. Its first step is to synchronize the current data state to the recovery site to ensure zero data loss. In a ransomware attack, the " current state " is encrypted or corrupted data. If an administrator performs a Planned Failover at 2:45 AM, the system will capture and replicate the encrypted files, effectively " backing up " the ransomware to the recovery site.
To successfully recover from ransomware, the administrator must perform an " Unplanned Failover. " Despite the name, this failover type is the correct choice for this scenario because it allows the administrator to manually select a historical recovery point from the destination cluster ' s storage. By choosing a recovery point from 1:00 AM (before the attack began), the administrator can restore the virtual machines to a known- good, unencrypted state. This is a primary use case for maintaining a multi-day or multi-week snapshot retention policy. While a " Test Failover " (Option A) could be used to verify the 1:00 AM snapshot in an isolated network first, the ultimate production recovery is achieved via an Unplanned Failover that specifically targets a point-in-time snapshot that predates the infection.
質問 # 35
......
あなたはNutanixのNCP-BC-7.5試験への努力を通して満足的な結果を得られているのは我々Fast2testの希望です。信じられないなら、弊社のデモをやってみて、NutanixのNCP-BC-7.5試験問題集を体験することができます。試して我々専門家たちの真面目さを感じられています。NutanixのNCP-BC-7.5試験のほかの試験に参加するつもりでしたら、あなたも弊社のFast2testでふさわしいソフトを探すことができます。あなたは満足できると信じています。
NCP-BC-7.5無料ダウンロード: https://jp.fast2test.com/NCP-BC-7.5-premium-file.html