Databricks - High Pass-Rate Certified-Data-Engineer-Professional - Practice Test Databricks Certified Data Engineer Professional Pdf

If you are still hesitate to choose our TestPassKing, you can try to free download part of Databricks Certified-Data-Engineer-Professional exam certification exam questions and answers provided in our TestPassKing. So that you can know the high reliability of our TestPassKing. Our TestPassKing will be your best selection and guarantee to pass Databricks Certified-Data-Engineer-Professional Exam Certification. Your choose of our TestPassKing is equal to choose success.
| Section | Objectives |
|---|
| Topic 1: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Topic 2: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 2. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 3. Create pipeline components using control flow operators such as if/else and foreach
- 4. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 5. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 6. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 7. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 8. Explain the advantages and disadvantages of streaming tables compared to materialized views
|
| Topic 3: Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Topic 4: Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Topic 5: Monitoring and Alerting | - Monitoring
- 1. Use Query Profile and Spark UI to monitor workloads
- 2. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 3. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 4. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
| Topic 6: Debugging and Deploying | - Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
|
| Topic 7: Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
|
| Topic 8: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 9: Data Modeling | - Design and optimize data models
- 1. Design dimensional models for analytical workloads with efficient querying and aggregation
- 2. Design and implement scalable data models using Delta Lake to manage large datasets
- 3. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Topic 10: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 2. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 3. Apply Change Data Feed to address streaming table limitations and improve latency
- 4. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 5. Understand Delta optimization techniques such as deletion vectors and liquid clustering
|
>> Practice Test Certified-Data-Engineer-Professional Pdf <<
New Exam Certified-Data-Engineer-Professional Materials, Exam Certified-Data-Engineer-Professional Torrent
The Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) Exam Questions offered by TestPassKing provide you with a good idea of what you can expect in the Certified-Data-Engineer-Professional exam from Databricks. All the Certified-Data-Engineer-Professional exam topics and objectives are well covered by our product. Thus, TestPassKing Databricks Certified-Data-Engineer-Professional Practice Questions are considered a very good resource that will help you in your practicing by focusing on your weak points and strengthening them to easily pass the Certified-Data-Engineer-Professional exam.
Databricks Certified Data Engineer Professional Sample Questions (Q77-Q82):
NEW QUESTION # 77
A user new to Databricks is trying to troubleshoot long execution times for some pipeline logic they are working on. Presently, the user is executing code cell-by-cell, using display() calls to confirm code is producing the logically correct results as new transformations are added to an operation. To get a measure of average time to execute, the user is running each cell multiple times interactively.
Which of the following adjustments will get a more accurate measure of how code is likely to perform in production?
- A. The Jobs Ul should be leveraged to occasionally run the notebook as a job and track execution time during incremental code development because Photon can only be enabled on clusters launched for scheduled jobs.
- B. Calling display () forces a job to trigger, while many transformations will only add to the logical query plan; because of caching, repeated execution of the same logic does not provide meaningful results.
- C. Production code development should only be done using an IDE; executing code against a local build of open source Spark and Delta Lake will provide the most accurate benchmarks for how code will perform in production.
- D. The only way to meaningfully troubleshoot code execution times in development notebooks Is to use production-sized data and production-sized clusters with Run All execution.
- E. Scala is the only language that can be accurately tested using interactive notebooks; because the best performance is achieved by using Scala code compiled to JARs. all PySpark and Spark SQL logic should be refactored.
Answer: D
NEW QUESTION # 78
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).
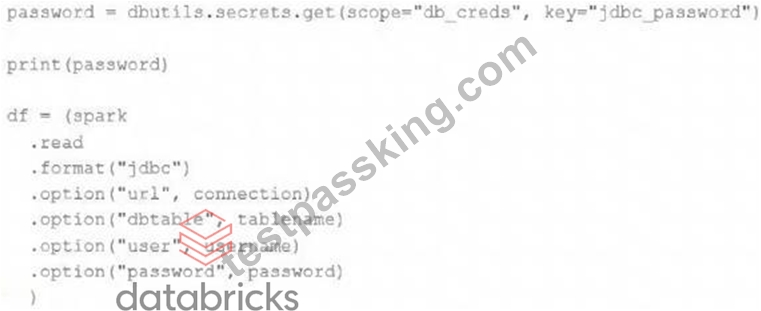
Which statement describes what will happen when the above code is executed?
- A. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the encoded password will be saved to DBFS.
- B. The connection to the external table will succeed; the string "redacted" will be printed.
- C. The connection to the external table will succeed; the string value of password will be printed in plain text.
- D. The connection to the external table will fail; the string "redacted" will be printed.
- E. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the password will be printed in plain text.
Answer: B
Explanation:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks.
NEW QUESTION # 79
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream to power several production monitoring dashboards and a production model. At present, 45 of the 100 fields are being used in at least one of these applications.
The data engineer is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields.
Which of the following accurately presents information about Delta Lake and Databricks that may impact their decision-making process?
- A. The Tungsten encoding used by Databricks is optimized for storing string data; newly-added native support for querying JSON strings means that string types are always most efficient.
- B. Human labor in writing code is the largest cost associated with data engineering workloads; as such, automating table declaration logic should be a priority in all migration workloads.
- C. Because Databricks will infer schema using types that allow all observed data to be processed, setting types manually provides greater assurance of data quality enforcement.
- D. Because Delta Lake uses Parquet for data storage, data types can be easily evolved by just modifying file footer information in place.
- E. Schema inference and evolution on .Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
Answer: C
Explanation:
This is the correct answer because it accurately presents information about Delta Lake and Databricks that may impact the decision-making process of a junior data engineer who is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields. Delta Lake and Databricks support schema inference and evolution, which means that they can automatically infer the schema of a table from the source data and allow adding new columns or changing column types without affecting existing queries or pipelines. However, schema inference and evolution may not always be desirable or reliable, especially when dealing with complex or nested data structures or when enforcing data quality and consistency across different systems. Therefore, setting types manually can provide greater assurance of data quality enforcement and avoid potential errors or conflicts due to incompatible or unexpected data types.
NEW QUESTION # 80
A data engineering team has a time-consuming data ingestion job with three data sources. Each notebook takes about one hour to load new data. One day, the job fails because a notebook update introduced a new required configuration parameter. The team must quickly fix the issue and load the latest data from the failing source. Which action should the team take?
- A. Repair the run with the new parameter.
- B. Repair the run with the new parameter, and update the task by adding the missing task parameter.
- C. Update the task by adding the missing task parameter, and manually run the job.
- D. Share the analysis with the failing notebook owner so that they can fix it quickly.
Answer: B
Explanation:
The repair run capability in Databricks Jobs allows re-execution of failed tasks without re-running successful ones. When a parameterized job fails due to missing or incorrect task configuration, engineers can perform a repair run to fix inputs or parameters and resume from the failed state.
This approach saves time, reduces cost, and ensures workflow continuity by avoiding unnecessary recomputation. Additionally, updating the task definition with the missing parameter prevents future runs from failing.
Running the job manually (B) loses run context; (C) alone does not prevent recurrence; (D) delays resolution. Thus, A follows the correct operational and recovery practice.
NEW QUESTION # 81
The data governance team has instituted a requirement that all tables containing Personal Identifiable Information (PH) must be clearly annotated. This includes adding column comments, table comments, and setting the custom table property "contains_pii" = true.
The following SQL DDL statement is executed to create a new table:
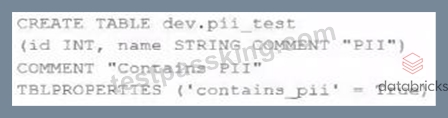
Which command allows manual confirmation that these three requirements have been met?
- A. DESCRIBE EXTENDED dev.pii test
- B. SHOW TBLPROPERTIES dev.pii test
- C. DESCRIBE HISTORY dev.pii test
- D. SHOW TABLES dev
- E. DESCRIBE DETAIL dev.pii test
Answer: A
Explanation:
This is the correct answer because it allows manual confirmation that these three requirements have been met. The requirements are that all tables containing Personal Identifiable Information (PII) must be clearly annotated, which includes adding column comments, table comments, and setting the custom table property "contains_pii" = true. The DESCRIBE EXTENDED command is used to display detailed information about a table, such as its schema, location, properties, and comments. By using this command on the dev.pii_test table, one can verify that the table has been created with the correct column comments, table comment, and custom table property as specified in the SQL DDL statement.
NEW QUESTION # 82
......
On the basis of the current social background and development prospect, the Certified-Data-Engineer-Professional certifications have gradually become accepted prerequisites to stand out the most in the workplace. But it is not easy for every one to achieve their Certified-Data-Engineer-Professional certification since the Certified-Data-Engineer-Professional Exam is quite difficult and takes time to prepare for it. Our Certified-Data-Engineer-Professional exam materials are pleased to serve you as such an exam tool to win the exam at your first attempt. If you don't believe it, just come and try!
New Exam Certified-Data-Engineer-Professional Materials: https://www.testpassking.com/Certified-Data-Engineer-Professional-exam-testking-pass.html
- Professional Practice Test Certified-Data-Engineer-Professional Pdf | Newest New Exam Certified-Data-Engineer-Professional Materials and Correct Exam Databricks Certified Data Engineer Professional Torrent 📤 Copy URL [ www.prepawayete.com ] open and search for ( Certified-Data-Engineer-Professional ) to download for free 🦃Certified-Data-Engineer-Professional Valid Test Test
- Certified-Data-Engineer-Professional exam training material - Certified-Data-Engineer-Professional test practice pdf - Certified-Data-Engineer-Professional valid free demo 💔 Simply search for ⇛ Certified-Data-Engineer-Professional ⇚ for free download on ⮆ www.pdfvce.com ⮄ 📗Certified-Data-Engineer-Professional Valid Vce
- Pass Guaranteed Quiz 2026 Databricks Marvelous Practice Test Certified-Data-Engineer-Professional Pdf 👰 Search for “ Certified-Data-Engineer-Professional ” and download it for free on ▷ www.examcollectionpass.com ◁ website 💘Certified-Data-Engineer-Professional Valid Test Test
- Exam Certified-Data-Engineer-Professional Online 🪐 Certified-Data-Engineer-Professional Mock Exams 🎧 Certified-Data-Engineer-Professional Cost Effective Dumps 🕔 Search for ( Certified-Data-Engineer-Professional ) and download it for free immediately on ✔ www.pdfvce.com ️✔️ 🙏Certified-Data-Engineer-Professional Cost Effective Dumps
- Certified-Data-Engineer-Professional Reliable Dumps Sheet 🧺 Exam Certified-Data-Engineer-Professional Blueprint 🕛 Certified-Data-Engineer-Professional Free Practice Exams 🎲 Go to website ▷ www.pdfdumps.com ◁ open and search for ( Certified-Data-Engineer-Professional ) to download for free 🏩Certified-Data-Engineer-Professional Reliable Study Notes
- Practice Test Certified-Data-Engineer-Professional Pdf | High-quality Databricks New Exam Certified-Data-Engineer-Professional Materials: Databricks Certified Data Engineer Professional 💝 Search for ➤ Certified-Data-Engineer-Professional ⮘ and easily obtain a free download on ☀ www.pdfvce.com ️☀️ 🏊Certified-Data-Engineer-Professional Latest Exam Price
- Professional Practice Test Certified-Data-Engineer-Professional Pdf | Newest New Exam Certified-Data-Engineer-Professional Materials and Correct Exam Databricks Certified Data Engineer Professional Torrent 🅱 Search for “ Certified-Data-Engineer-Professional ” and download exam materials for free through ▷ www.troytecdumps.com ◁ 🐇Certified-Data-Engineer-Professional Reliable Study Notes
- Vce Certified-Data-Engineer-Professional Files 🧗 Certified-Data-Engineer-Professional Mock Exams ✒ Valid Certified-Data-Engineer-Professional Test Answers 🔝 Simply search for [ Certified-Data-Engineer-Professional ] for free download on 「 www.pdfvce.com 」 💆Certified-Data-Engineer-Professional Reliable Study Notes
- Certified-Data-Engineer-Professional Pdf Torrent 😰 Certified-Data-Engineer-Professional Test Practice 🃏 Certified-Data-Engineer-Professional Latest Exam Price 🌕 Search for 《 Certified-Data-Engineer-Professional 》 on 《 www.troytecdumps.com 》 immediately to obtain a free download 🦜Exam Certified-Data-Engineer-Professional Online
- Vce Certified-Data-Engineer-Professional Files 🚾 Exam Certified-Data-Engineer-Professional Blueprint 😘 Valid Certified-Data-Engineer-Professional Test Answers 👞 { www.pdfvce.com } is best website to obtain ▛ Certified-Data-Engineer-Professional ▟ for free download 🌁Latest Certified-Data-Engineer-Professional Dumps Files
- Pass Guaranteed Quiz 2026 Databricks Marvelous Practice Test Certified-Data-Engineer-Professional Pdf 🦺 Download ⮆ Certified-Data-Engineer-Professional ⮄ for free by simply entering ➡ www.practicevce.com ️⬅️ website 📞Exam Certified-Data-Engineer-Professional Blueprint
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes