As far as the prices of DP-750 exam dumps are concerned, we ensure you that our Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam questions prices are entirely affordable for everyone. The real and updated DP-750 exam dumps are being offered at discounted prices. You can grab this opportunity and download the top-notch and real Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam questions at discounted prices. Best wishes for the final Microsoft DP-750 certification exam!!!
| Section | Weight | Objectives |
|---|---|---|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Prepare and process data | 30-35% | - Data quality and validation
|
| Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
>> Trustworthy DP-750 Source <<
As far as the top features of BraindumpsPrep DP-750 exam questions formats are concerned, the Microsoft DP-750 desktop practice test software and web-based practice test software both are customizable and track your performance. These DP-750 practice tests are specifically designed to give you a real-time DP-750 Exam environment for preparation. You can trust both DP-750 practice test software and start preparing today. The desktop software runs on Windows computers. The web-based DP-750 practice exam is supported by all browsers and operating systems.
NEW QUESTION # 74
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount != None)
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
NEW QUESTION # 75
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
dbl sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the dbl.sales.ordets table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.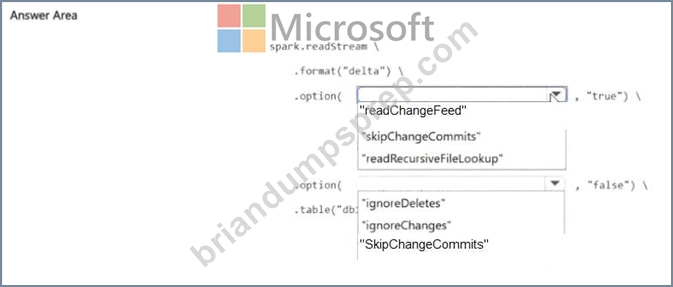
Answer:
Explanation: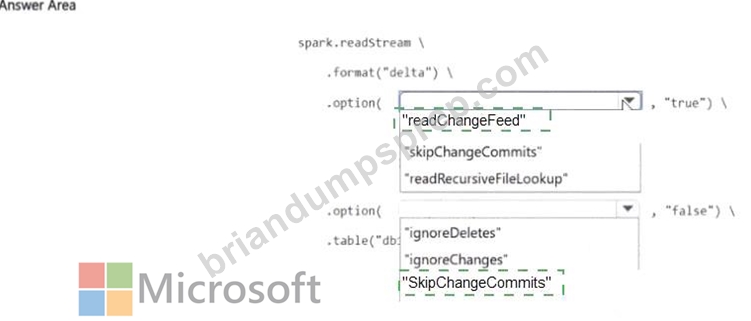
Explanation:
When Change Data Feed (CDF) is enabled on a Delta table, reading the full change stream - inserts, updates, and deletes - requires this pattern:
spark.readStream.format('delta').option('readChangeFeed', 'true').table('db1.sales_orders') The readChangeFeed option switches the reader from the default 'new rows only' mode to a mode that returns all change events. Each row in the resulting DataFrame includes a _change_type column (insert, update_preimage, update_postimage, delete) so downstream processing can distinguish what happened to each record.
Without readChangeFeed = true, streaming a Delta table only surfaces newly appended rows. Deletes and updates are invisible, making it unsuitable for true CDC pipelines. The stream also supports startingVersion or startingTimestamp options to begin from a specific point in table history rather than the current moment.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-change-data-feed
NEW QUESTION # 76
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1.
You need to meet the following requirements:
- Records that violate rule1 must NOT be written to Table1, but the
pipeline must continue processing valid records.
- Data engineers must be able to review expectation metrics by using
minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.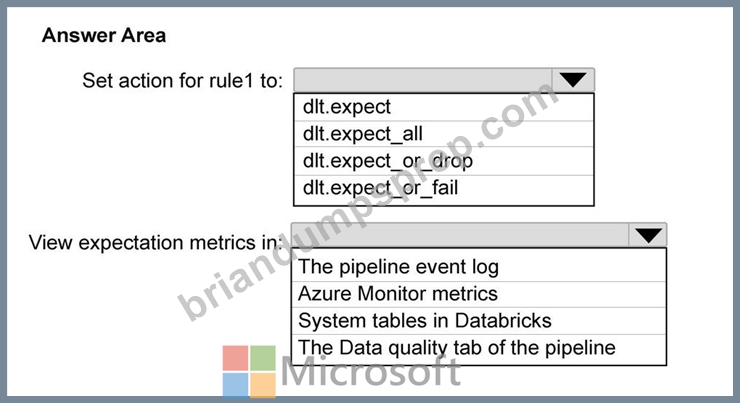
Answer:
Explanation: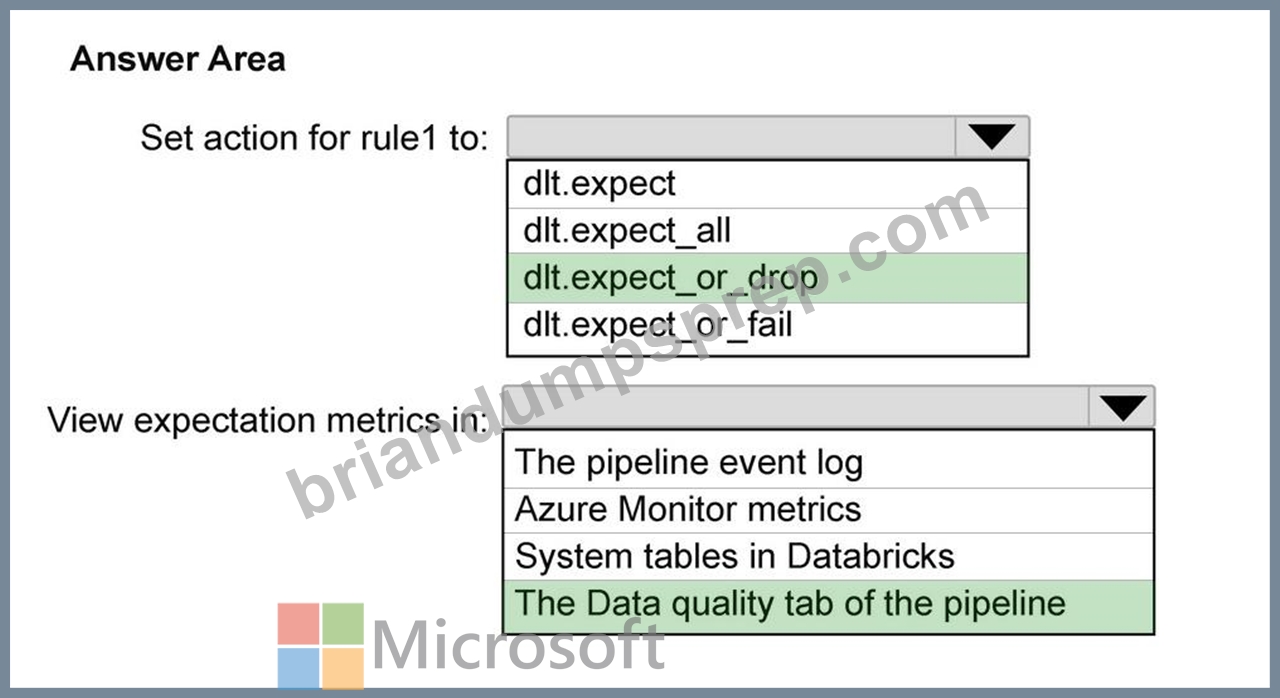
NEW QUESTION # 77
You have a Lakeflow Spark Declarative Pipelines {SDP) pipeline in Azure Databricks. The pipeline ingests transaction data into a table named Table1.
You need to ensure that in the event of an invalid record, the pipeline continues to run. The solution must meet the following requirements:
* Invalid records must NOT be written to Table 1.
* Invalid records must be preserved for review.
* Minimize development effort
What should you do?
Answer: B
Explanation:
The correct answer is B - define a pipeline expectation.
SDP expectations with @dlt.expect_or_drop are built precisely for this scenario: the pipeline keeps running, bad records are excluded from Table1, and those records are automatically captured in the pipeline's event log as expectation violations - available for review without any extra code.
Option A (custom quarantine logic) would work but requires writing and maintaining additional pipeline tables and routing logic. The whole point of SDP expectations is to handle this pattern declaratively, with far less code.
Option C (WHERE clauses in downstream queries) is a read-time filter, not a write-time guard. Invalid records would still land in Table1 and would simply be hidden from downstream views - they're not preserved for review in any structured way. Option D (check constraint on Table1) would throw an exception on write and halt the pipeline, violating the 'pipeline continues to run' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 78
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two catalogs named Catalog1 and Catalog2.
An external application uses a service principal named SP1 to connect to a SQL warehouse.
You need to ensure that SP1 can query the data in Catalog1 and Catalog2. The solution must follow the principle of least privilege.
Which permissions should you grant to SP1 for the catalogs?
Answer: D
NEW QUESTION # 79
......
Based on the credibility in this industry, our DP-750 study braindumps have occupied a relatively larger market share and stable sources of customers. Such a startling figure --99% pass rate is not common in this field, but we have made it with our endless efforts. The system of DP-750 test guide will keep track of your learning progress in the whole course. Therefore, you can have 100% confidence in our DP-750 exam guide. According to our overall evaluation and research, seldom do we have cases that customers fail the DP-750 Exam after using our study materials. But to relieve your doubts about failure in the test, we guarantee you a full refund from our company by virtue of the related proof of your report card. Of course you can freely change another DP-750 exam guide to prepare for the next exam. Generally speaking, our company takes account of every client’ difficulties with fitting solutions.
Real DP-750 Exam: https://www.briandumpsprep.com/DP-750-prep-exam-braindumps.html