Übrigens, Sie können die vollständige Version der ZertPruefung Data-Engineer-Associate Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=1o4zNDCQhNwkbnUr8g0CULsr-VHOCnXCY
Wenn Sie Dumps zur Amazon Data-Engineer-Associate Zertifizierungsprüfung von ZertPruefung kaufen, versprechen wir Ihnen, dass Sie 100% die Amazon Data-Engineer-Associate Zertifizierungsprüfung bestehen können. Sonst zahlen wir Ihnen die gesammte Summe zurück.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion and Transformation | 34% | - Ingest data from various sources
- Transform and enrich data
|
| Data Security and Governance | 18% | - Implement access control and authentication
- Encrypt data at rest and in transit - Enforce compliance and data governance
|
| Data Store Management | 26% | - Optimize storage performance and cost - Manage data lifecycle and storage tiers - Design and implement data storage solutions
|
| Data Operations and Support | 22% | - Monitor and troubleshoot data pipelines
- Automate operational tasks - Backup, restore, and disaster recovery |
>> Data-Engineer-Associate Fragenpool <<
Vielleicht mit zahlreichen Übungen fehlt Ihnen noch die Sicherheit für Amazon Data-Engineer-Associate Prüfung. Falls Sie nach dem Kauf unserer Prüfungsunterlagen leider nicht Amazon Data-Engineer-Associate bestehen, bieten wir Ihnen eine volle Rückerstattung. Aber wir glauben, dass unsere Prüfungssoftware, die unseren Kunden eine Bestehensrate von fast 100% angeboten hat, wird Ihre Erwartungen nicht enttäuschen!
198. Frage
A data engineering team is using an Amazon Redshift data warehouse for operational reporting. The team wants to prevent performance issues that might result from long- running queries. A data engineer must choose a system table in Amazon Redshift to record anomalies when a query optimizer identifies conditions that might indicate performance issues.
Which table views should the data engineer use to meet this requirement?
Antwort: B
Begründung:
The STL ALERT EVENT LOG table view records anomalies when the query optimizer identifies conditions that might indicate performance issues. These conditions include skewed data distribution, missing statistics, nested loop joins, and broadcasted data. The STL ALERT EVENT LOG table view can help the data engineer to identify and troubleshoot the root causes of performance issues and optimize the query execution plan. The other table views are not relevant for this requirement. STL USAGE CONTROL records the usage limits and quotas for Amazon Redshift resources. STL QUERY METRICS records the execution time and resource consumption of queries. STL PLAN INFO records the query execution plan and the steps involved in each query. References:
STL ALERT EVENT LOG
System Tables and Views
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide
199. Frage
A retail company uses Amazon Aurora PostgreSQL to process and store live transactional data. The company uses an Amazon Redshift cluster for a data warehouse.
An extract, transform, and load (ETL) job runs every morning to update the Redshift cluster with new data from the PostgreSQL database. The company has grown rapidly and needs to cost optimize the Redshift cluster.
A data engineer needs to create a solution to archive historical data. The data engineer must be able to run analytics queries that effectively combine data from live transactional data in PostgreSQL, current data in Redshift, and archived historical data. The solution must keep only the most recent 15 months of data in Amazon Redshift to reduce costs.
Which combination of steps will meet these requirements? (Select TWO.)
Antwort: C,D
Begründung:
The goal is to archive historical data from an Amazon Redshift data warehouse while combining live transactional data from Amazon Aurora PostgreSQL with current and historical data in a cost-efficient manner. The company wants to keep only the last 15 months of data in Redshift to reduce costs.
* Option A: "Configure the Amazon Redshift Federated Query feature to query live transactional data that is in the PostgreSQL database."Redshift Federated Query allows querying live transactional data directly from Aurora PostgreSQL without having to move it into Redshift, thereby enabling seamless integration of the current data in Redshift and live data in PostgreSQL. This is a cost- effective approach, as it avoids unnecessary data duplication.
* Option C: "Schedule a monthly job to copy data that is older than 15 months to Amazon S3 by using the UNLOAD command. Delete the old data from the Redshift cluster. Configure Amazon Redshift Spectrum to access historical data in Amazon S3."This option uses Amazon Redshift Spectrum, which enables Redshift to query data directly in S3 without moving it into Redshift. By unloading older data (older than 15 months) to S3, and then using Spectrum to access it, this approach reduces storage costs significantly while still allowing the data to be queried when necessary.
* Option B (Redshift Spectrum for live PostgreSQL data) is not applicable, as Redshift Spectrum is intended for querying data in Amazon S3, not live transactional data in Aurora.
* Option D (S3 Glacier Flexible Retrieval) is not suitable because Glacier is designed for long-term archival storage with infrequent access, and querying data in Glacier for analytics purposes would incur higher retrieval times and costs.
* Option E (materialized views) would not meet the need to archive data or combine it from multiple sources; it is best suited for combining frequently accessed data already in Redshift.
References:
* Amazon Redshift Federated Query
* Amazon Redshift Spectrum Documentation
* Amazon Redshift UNLOAD Command
200. Frage
A company's data processing pipeline uses AWS Glue jobs and AWS Glue Data Catalog. All AWS Glue jobs must run in a custom VPC inside a private subnet. The company uses a NAT gateway to support outbound connections.
A data engineer needs to use AWS Glue to migrate data from an on-premises PostgreSQL database to Amazon S3. There is no current network connection between AWS and the on-premises environment.
However, the data engineer has updated the on-premises database to allow traffic from the custom VPC.
Which solution will meet these requirements?
Antwort: A
Begründung:
When AWS Glue jobs run inside a private subnet, they must use secure and supported methods to access external databases. AWS Glue supports JDBC connections to on-premises databases, but best practices require secure credential management and explicit driver configuration.
Using a JDBC driver stored in Amazon S3 allows Glue to connect to PostgreSQL without relying on default drivers. Storing credentials in AWS Secrets Manager eliminates hard-coded credentials and enables secure rotation, aligning with AWS security best practices.
Simply specifying credentials inline is less secure and not recommended. SASL connections are not supported for PostgreSQL JDBC connections. Security groups alone do not establish connectivity or authentication.
Therefore, Option D is the correct and production-grade solution.
201. Frage
A data engineer needs to create an Amazon Athena table based on a subset of data from an existing Athena table named cities_world. The cities_world table contains cities that are located around the world. The data engineer must create a new table named cities_us to contain only the cities from cities_world that are located in the US.
Which SQL statement should the data engineer use to meet this requirement?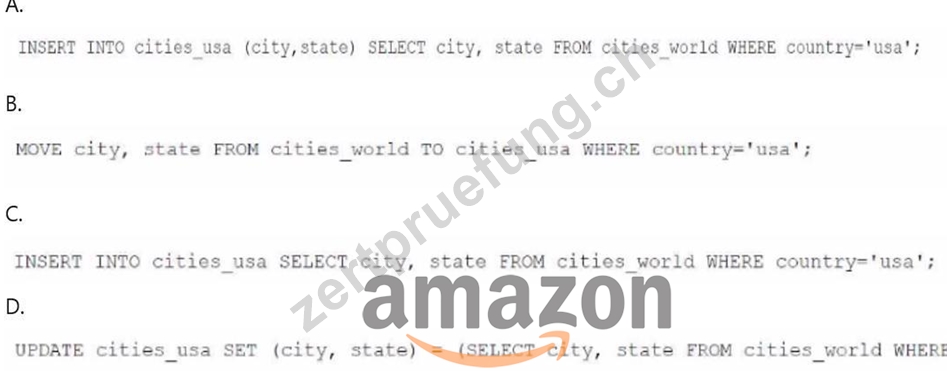
Antwort: C
Begründung:
To create a new table named cities_usa in Amazon Athena based on a subset of data from the existing cities_world table, you should use an INSERT INTO statement combined with a SELECT statement to filter only the records where the country is 'usa'. The correct SQL syntax would be:
* Option A: INSERT INTO cities_usa (city, state) SELECT city, state FROM cities_world WHERE country='usa';This statement inserts only the cities and states where the country column has a value of
'usa' from the cities_world table into the cities_usa table. This is a correct approach to create a new table with data filtered from an existing table in Athena.
Options B, C, and D are incorrect due to syntax errors or incorrect SQL usage (e.g., the MOVE command or the use of UPDATE in a non-relevant context).
References:
* Amazon Athena SQL Reference
* Creating Tables in Athena
202. Frage
A company has five offices in different AWS Regions. Each office has its own human resources (HR) department that uses a unique IAM role. The company stores employee records in a data lake that is based on Amazon S3 storage.
A data engineering team needs to limit access to the records. Each HR department should be able to access records for only employees who are within the HR department's Region.
Which combination of steps should the data engineering team take to meet this requirement with the LEAST operational overhead? (Choose two.)
Antwort: B,C
Begründung:
AWS Lake Formation is a service that helps you build, secure, and manage data lakes on Amazon S3. You can use AWS Lake Formation to register the S3 path as a data lake location, and enable fine-grained access control to limit access to the records based on the HR department's Region. You can use data filters to specify which S3 prefixes or partitions each HR department can access, and grant permissions to the IAM roles of the HR departments accordingly. This solution will meet the requirement with the least operational overhead, as it simplifies the data lake management and security, and leverages the existing IAM roles of the HR departments12.
The other options are not optimal for the following reasons:
A: Use data filters for each Region to register the S3 paths as data locations. This option is not possible, as data filters are not used to register S3 paths as data locations, but to grant permissions to access specific S3 prefixes or partitions within a data location. Moreover, this option does not specify how to limit access to the records based on the HR department's Region.
C: Modify the IAM roles of the HR departments to add a data filter for each department's Region. This option is not possible, as data filters are not added to IAM roles, but to permissions granted by AWS Lake Formation. Moreover, this option does not specify how to register the S3 path as a data lake location, or how to enable fine-grained access control in AWS Lake Formation.
E: Create a separate S3 bucket for each Region. Configure an IAM policy to allow S3 access. Restrict access based on Region. This option is not recommended, as it would require more operational overhead to create and manage multiple S3 buckets, and to configure and maintain IAM policies for each HR department. Moreover, this option does not leverage the benefits of AWS Lake Formation, such as data cataloging, data transformation, and data governance.
References:
1: AWS Lake Formation
2: AWS Lake Formation Permissions
3: AWS Identity and Access Management
4: Amazon S3
203. Frage
......
Wenn Sie sich noch Sorgen um die Amazon Data-Engineer-Associate Prüfung machen, wählen Sie doch ZertPruefung. Die Fragenkataloge zur Amazon Data-Engineer-AssociatePrüfung von ZertPruefung sind zweifellos die besten. ZertPruefung ist Ihre beste Wahl und garantiert Ihnen den 100% Erfolg in der Data-Engineer-Associate Zertifizierungsprüfung. Komm doch, Sie werden der zukünftige beste IT-Expert.
Data-Engineer-Associate Zertifizierungsantworten: https://www.zertpruefung.ch/Data-Engineer-Associate_exam.html
P.S. Kostenlose und neue Data-Engineer-Associate Prüfungsfragen sind auf Google Drive freigegeben von ZertPruefung verfügbar: https://drive.google.com/open?id=1o4zNDCQhNwkbnUr8g0CULsr-VHOCnXCY