MicrosoftのDP-750試験に合格することは容易なことではなくて、良い訓練ツールは成功の保証でXhs1991は君の試験の問題を準備してしまいました。君の初めての合格を目標にします。
| Section | Weight | Objectives |
|---|---|---|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
当社のソフトウェアをダウンロードして30時間以内に練習する場合のみ、自信を持ってテストに参加できます。 DP-750試験トレントは期間限定の試験とオンラインエラー修正をシミュレートできるため、DP-750試験の準備にかかる時間と労力は他の学習教材よりも少なくて済みます。 20時間または30時間を費やすだけでDP-750証明書を手に入れることは非常に経済的です。これは通常、将来のキャリアにとって有益です。したがって、テストを準備するには、DP-750ガイドトレントを購入するのが最善かつ賢明な選択です。
質問 # 71
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes curated Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
正解:D
解説:
The best choice is a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
Low Development Effort: Lakeflow SDP (formerly known as Delta Live Tables or DLT) is a completely declarative ETL framework. You simply define the target schemas and data transformations using standard SQL or Python. Databricks automatically manages the underlying operational complexities, state maintenance, task orchestration, and DAG dependencies for you.
Built-in Quality & Monitoring: It offers out-of-the-box data monitoring capabilities via Expectations, which allow you to specify data cleansing policies (like drop, retain, or fail on bad rows) with zero custom validation code. It also captures complete, automatic end-to-end data lineage and operational stats straight into Unity Catalog.
Built-in Resilience: Infrastructure failure handling and automatic retries are natively managed by the Lakeflow runtime.
Native Storage Ingestion: Using read_files() (Auto Loader) within SDP allows effortless, incremental ingestion of files from cloud object storage directly into curated Delta tables.
Reference:
https://docs.databricks.com/aws/en/ldp/
質問 # 72
What improves join performance for small lookup tables?
正解:D
解説:
Broadcast joins send the small table to all worker nodes, avoiding expensive shuffling. This significantly improves performance. Shuffle and sort merge joins are heavier. Cartesian joins are inefficient and generally avoided.
質問 # 73
You have an Azure Databricks workspace that is attached to a Unity Catalog metastore named metastore1.
Metastore1 contains a catalog named catalog 1.
You need to create a new schema named schema2 that meets the following requirements:
* Is contained in catalog1
* Uses abfss://containergstorageaccount.dfs.core.windows.net/data as the Managed location Which SQL statement should you execute?
正解:C
解説:
The correct answer is A. The Unity Catalog DDL for creating a schema inside a specific catalog and setting a custom managed storage path uses the three-part name (catalog.schema) and the MANAGED LOCATION clause:
CREATE SCHEMA catalog1.schema2 MANAGED LOCATION ' abfss://... ' ;
The three-part name explicitly places the schema inside catalog1. MANAGED LOCATION tells Unity Catalog where to store managed tables and volumes created under this schema - any managed table without its own explicit location will inherit this path.
Option B uses CREATE CATALOG, which creates an entirely new catalog rather than a schema. Option C uses the LOCATION keyword without MANAGED - that syntax is for external locations, not for overriding the managed storage path of a schema. Option D uses WITH DBPROPERTIES, which stores arbitrary key- value metadata but has no effect on where Unity Catalog physically stores data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-ddl-create- schema
質問 # 74
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have 500 GB of sales data stored as multiple CSV files in cloud storage.
You plan to load the data into a Delta table.
You need to ingest the bulk data by using a solution that meets the following requirements:
* Minimize how long it takes to implement the solution.
* Minimize the amount of custom code required.
What should you use?
正解:A
解説:
COPY INTO provides a concise SQL-based mechanism for loading files from cloud storage directly into a Delta table. It requires substantially less custom code than constructing a Spark ingestion application and is suitable for a straightforward bulk load of multiple CSV files. COPY INTO is also retryable and idempotent:
it tracks files already loaded into the target table and skips them during later executions, helping prevent accidental duplication. Auto Loader is optimized primarily for incremental and continuously arriving files and normally requires a streaming or triggered pipeline. Apache Spark read APIs require additional code for reading, transforming, tracking, and writing the files. Manually uploading 500 GB would be inefficient and operationally unsuitable. Therefore, COPY INTO best satisfies both implementation-speed and minimal-code requirements. Microsoft Learn
質問 # 75
You have an Azure Databricks account that contains a single workspace named Workspace1. Workspace1 is enabled for Unity Catalog.
You discover that data access events for Unity Catalog tables fail to appear in the logs.
You need to ensure that all the data access events are captured centrally for auditing purposes. The log data must be available for analysis as quickly as possible.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.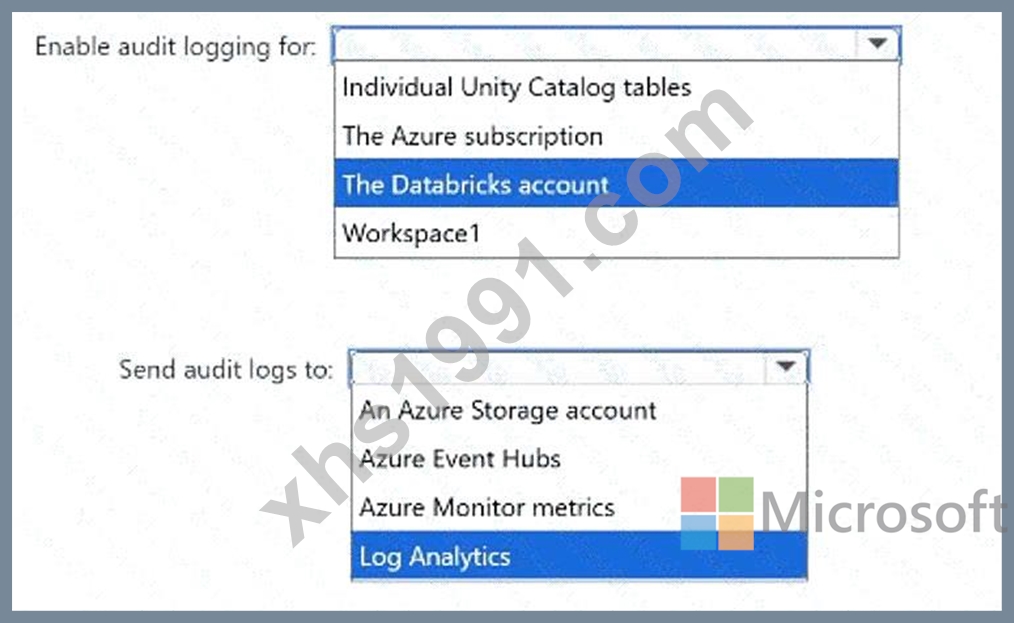
正解:
解説: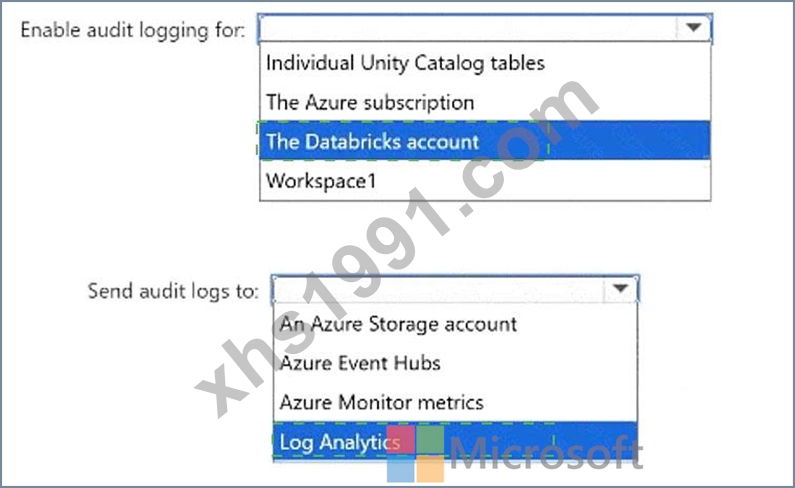
Explanation:
Enable audit logging for: The Databricks account
Send audit logs to: Log Analytics
Enabling audit logging at the Databricks account level provides centralized coverage of account and workspace activities, including Unity Catalog data-access events. Enabling logging only for Workspace1 would provide a narrower configuration and would not offer the same centralized account-level auditing model. Individual Unity Catalog tables and the Azure subscription are not the appropriate Databricks audit- log scope selections. Log Analytics is the suitable destination because it supports rapid ingestion and immediate querying of log records through Azure Monitor Logs. Auditors can search, filter, correlate, and analyze the captured events without first developing a separate data-processing solution. An Azure Storage account is more suitable for inexpensive archival, while Event Hubs is primarily a streaming transport that normally requires an additional consumer before investigators can analyze the records.
質問 # 76
......
弊社Xhs1991のDP-750試験準備では、学習習慣を身に付けるのに役立ちます。 DP-750学習教材を購入して使用すると、学習の良い習慣を身に付けることができます。さらに重要なことは、良い習慣は科学的な小道具の学習方法を見つけ、学習効率を高めるのに役立ちます。そして、短時間でDP-750試験に合格するのに役立ちます。弊社からDP-750テストガイドを急いで購入すると、多くのメリットが得られます。
DP-750試験合格攻略: https://www.xhs1991.com/DP-750.html