P.S. Free & New AIF-C01 dumps are available on Google Drive shared by DumpsValid: https://drive.google.com/open?id=1LGd-AEuqcXsvseiQMKC1FCb5_eQNH3co
We should formulate a set of high efficient study plan to make the AIF-C01 exam dumps easier to operate. Here our products strive for providing you a comfortable study platform and continuously upgrade AIF-C01 test prep to meet every customer’s requirements. Under the guidance of our AIF-C01 Test Braindumps, 20-30 hours’ preparation is enough to help you obtain the Amazon certification, which means you can have more time to do your own business as well as keep a balance between a rest and taking exams.
| Certification Vendor: | Amazon AWS |
|---|---|
| Exam Name: | AWS Certified AI Practitioner |
| Exam Number: | AIF-C01 |
| Related Certifications: | AWS Certified Machine Learning – Specialty AWS Certified Cloud Practitioner |
| Exam Duration: | 90 minutes |
| Real Exam Qty: | 65 (50 scored, 15 unscored) |
| Exam Format: | Multiple response, Multiple choice, Ordering |
| Certificate Validity Period: | 3 years |
| Available Languages: | Korean, English, Japanese, Simplified Chinese, Traditional Chinese |
| Passing Score: | 700 (scaled score 100–1000) |
| Exam Price: | 100 USD |
| Recommended Training: | AWS Skill Builder - AI Practitioner Learning Path AWS Certified AI Practitioner Official Training |
| Exam Registration: | Pearson VUE Scheduling AWS Certification Registration |
| Sample Questions: | Amazon AIF-C01 Sample Questions |
| Exam Way: | Online proctored or testing center delivery |
| Pre Condition: | No required prerequisites; recommended basic understanding of cloud computing and general IT concepts |
| Official Syllabus URL: | https://docs.aws.amazon.com/aws-certification/latest/ai-practitioner-01/ai-practitioner-01.html |
We give customers the privileges to check the content of our AIF-C01 real dumps before placing orders. Such high quality and low price traits of our AIF-C01 guide materials make exam candidates reassured. The free demos of AIF-C01 study quiz include a small part of the real questions and they exemplify the basic arrangement of our AIF-C01 real test. They also convey an atmosphere of high quality and prudent attitude we make.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 171
A company has deployed an AI application in production on AWS. The application's responses have become less accurate over time. The company needs a solution to send alerts when the application performance drifts.
Which AWS service or feature will meet this requirement?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact AWS AI documents:
Amazon SageMaker Model Monitor detects:
* Data drift
* Concept drift
* Model quality degradation
AWS MLOps guidance recommends Model Monitor to:
* Continuously evaluate production models
* Trigger alerts when performance deviates from baselines
* Maintain long-term model reliability
Why the other options are incorrect:
* Amazon A2I (A) adds human review workflows.
* Rekognition (C) is an image analysis service.
* Trusted Advisor (D) provides cost and security recommendations.
AWS AI document references:
* Amazon SageMaker Model Monitor Overview
* Detecting Model Drift on AWS
* Production ML Monitoring Best Practices
NEW QUESTION # 172
A company wants to develop ML applications to improve business operations and efficiency.
Select the correct ML paradigm from the following list for each use case. Each ML paradigm should be selected one or more times. (Select FOUR.)
* Supervised learning
* Unsupervised learning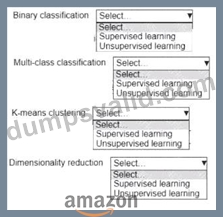
Answer:
Explanation: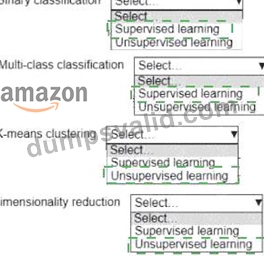
Explanation: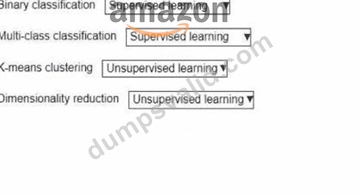
The company is developing ML applications for various use cases, and the task is to select the correct ML paradigm (supervised or unsupervised learning) for each. Supervised learning involves training a model on labeled data to make predictions, while unsupervised learning identifies patterns or structures in unlabeled data. Each use case aligns with one of these paradigms based on its requirements.
Exact Extract from AWS AI Documents:
From the AWS AI Practitioner Learning Path:
"Supervised learning uses labeled data to train models for tasks like classification (e.g., binary or multi-class classification), where the model predicts a category. Unsupervised learning works with unlabeled data for tasks like clustering (e.g., K-means clustering) or dimensionality reduction, identifying patternsor reducing data complexity without predefined labels." (Source: AWS AI Practitioner Learning Path, Module on Machine Learning Strategies) Detailed Explanation:
Binary classification: Supervised learningBinary classification involves predicting one of two classes (e.g., yes
/no, spam/not spam) using labeled data, making it a supervised learning task. The model learns from examples where the correct class is provided.
Multi-class classification: Supervised learningMulti-class classification extends binary classification to predict one of multiple classes (e.g., categorizing items into several groups). Like binary classification, it requires labeled data, so it falls under supervised learning.
K-means clustering: Unsupervised learningK-means clustering groups data into clusters based on similarity, without requiring labeled data. This is a classic unsupervised learning task, as the algorithm identifies patterns in the data on its own.
Dimensionality reduction: Unsupervised learningDimensionality reduction (e.g., using techniques like PCA) reduces the number of features in a dataset while preserving important information. It does not require labeled data, making it an unsupervised learning task.
Hotspot Selection Analysis:
The hotspot lists four use cases, each with a dropdown containing "Select...," "Supervised learning," and
"Unsupervised learning." The correct selections are:
Binary classification: Supervised learning
Multi-class classification: Supervised learning
K-means clustering: Unsupervised learning
Dimensionality reduction: Unsupervised learning
Each paradigm (supervised and unsupervised learning) is used twice, as the question allows for paradigms to be selected one or more times.
References:
AWS AI Practitioner Learning Path: Module on Machine Learning Strategies Amazon SageMaker Developer Guide: Supervised and Unsupervised Learning (https://docs.aws.amazon.com
/sagemaker/latest/dg/algos.html)
AWS Documentation: Introduction to Machine Learning Paradigms (https://aws.amazon.com/machine- learning/)
NEW QUESTION # 173
A company is implementing intelligent agents to provide conversational search experiences for its customers. The company needs a database service that will support storage and queries of embeddings from a generative AI model as vectors in the database.
Which AWS service will meet these requirements?
Answer: B
Explanation:
A: Amazon Athena: Amazon Athena is a serverless query service for analyzing data in Amazon S3 using SQL. It is designed for ad-hoc querying of structured data but does not natively support vector storage or vector similarity searches, making it unsuitable for this use case.
B: Amazon Aurora PostgreSQL: Amazon Aurora PostgreSQL is a fully managed relational database compatible with PostgreSQL. With the pgvector extension (available in PostgreSQL and supported by Aurora PostgreSQL), it can store and query vector embeddings efficiently. The pgvector extension enables vector similarity searches (e.g., using cosine similarity or Euclidean distance), which is critical for conversational search applications using embeddings from generative AI models.
C: Amazon Redshift: Amazon Redshift is a data warehousing service optimized for analytical queries on large datasets. While it supports machine learning features and can store numerical data, it does not have native support for vector embeddings or vector similarity searches as of May 17, 2025, making it less suitable for this use case.
D: Amazon EMR: Amazon EMR is a managed big data platform for processing large-scale data using frameworks like Apache Hadoop and Spark. It is not a database service and is not designed for storing or querying vector embeddings in the context of a conversational search application.
Exact Extract Reference: According to the AWS documentation, "Amazon Aurora PostgreSQL-Compatible Edition supports the pgvector extension, which enables efficient storage and similarity searches for vector embeddings. This makes it suitable for AI/ML workloads such as natural language processing and recommendation systems that rely on vector data." (Source: AWS Aurora Documentation - Using pgvector with Aurora PostgreSQL, https://docs.aws.amazon.com/AmazonRDS/latest/AuroraUserGuide/PostgreSQLpgvector.html). Additionally, the pgvector extension supports operations like nearest-neighbor searches, which are essential for querying embeddings in a conversational search system.
Amazon Aurora PostgreSQL with the pgvector extension directly meets the requirement for storing and querying embeddings as vectors, making B the correct answer.
Explanation:
The requirement is to identify an AWS database service that supports the storage and querying of embeddings (from a generative AI model) as vectors. Embeddings are typically high-dimensional numerical representations of data (e.g., text, images) used in AI applications like conversational search. The database must support vector storage and efficient vector similarity searches. Let's evaluate each option:
Reference:
AWS Aurora Documentation: Using pgvector with Aurora PostgreSQL (https://docs.aws.amazon.com/AmazonRDS/latest/AuroraUserGuide/PostgreSQLpgvector.html) AWS AI Practitioner Study Guide (focus on data engineering for AI, including vector databases) AWS Blog on Vector Search with Aurora (https://aws.amazon.com/blogs/database/using-vector-search-with-amazon-aurora-postgresql/)
NEW QUESTION # 174
A company wants to develop an Al application to help its employees check open customer claims, identify details for a specific claim, and access documents for a claim. Which solution meets these requirements?
Answer: D
Explanation:
The company wants an AI application to help employees check open customer claims, identify claim details, and access related documents. Agents for Amazon Bedrock can automate tasks by interacting with external systems, while Amazon Bedrock knowledge bases provide a repository of information (e.g., claim details and documents) that the agent can query to respond to employee requests, making this the best solution.
Exact Extract from AWS AI Documents:
From the AWS Bedrock User Guide:
"Agents for Amazon Bedrock enable developers to build applications that can perform tasks by interacting with external systems and data sources. When paired with Amazon Bedrock knowledge bases, agents can access structured and unstructured data, such as documents or databases, to provide detailed responses for use cases like customer service or claims management." (Source: AWS Bedrock User Guide, Agents and Knowledge Bases) Detailed Option A: Use Agents for Amazon Bedrock with Amazon Fraud Detector to build the application.Amazon Fraud Detector is for detecting fraudulent activities, not for managing customer claims or accessing documents. This option is irrelevant.
Option B: Use Agents for Amazon Bedrock with Amazon Bedrock knowledge bases to build the application.This is the correct answer. Agents for Amazon Bedrock can interact with knowledge bases to retrieve claim details and documents, enabling employees to check open claims and access relevant information.
Option C: Use Amazon Personalize with Amazon Bedrock knowledge bases to build the application.Amazon Personalize is for building recommendation systems, not for retrieving claim details or documents. This option does not meet the requirements.
Option D: Use Amazon SageMaker AI to build the application by training a new ML model.Training a new ML model on SageMaker is unnecessary and complex for this use case, as the task can be efficiently handled by Agents and knowledge bases on Amazon Bedrock.
Reference:
AWS Bedrock User Guide: Agents and Knowledge Bases (https://docs.aws.amazon.com/bedrock/latest/userguide/agents.html) AWS AI Practitioner Learning Path: Module on Generative AI and Knowledge Bases Amazon Bedrock Developer Guide: Building AI Applications (https://aws.amazon.com/bedrock/)
NEW QUESTION # 175
How can companies use large language models (LLMs) securely on Amazon Bedrock?
Answer: A
Explanation:
To securely use large language models (LLMs) on Amazon Bedrock, companies should design clear and specific prompts to avoid unintended outputs and ensure proper configuration of AWS Identity and Access Management (IAM) roles and policies with the principle of least privilege. This approach limits access to sensitive resources and minimizes the potential impact of security incidents.
* Option A (Correct): "Design clear and specific prompts. Configure AWS Identity and Access Management (IAM) roles and policies by using least privilege access": This is the correct answer as it directly addresses both security practices in prompt design and access management.
* Option B: "Enable AWS Audit Manager for automatic model evaluation jobs" is incorrect because Audit Manager is for compliance and auditing, not directly related to secure LLM usage.
* Option C: "Enable Amazon Bedrock automatic model evaluation jobs" is incorrect because Bedrock does not provide automatic model evaluation jobs specifically for security purposes.
* Option D: "Use Amazon CloudWatch Logs to make models explainable and to monitor for bias" is incorrect because CloudWatch Logs are used for monitoring and not directly for making models explainable or secure.
AWS AI Practitioner References:
* Secure AI Practices on AWS: AWS recommends configuring IAM roles and using least privilege access to ensure secure usage of AI models.
NEW QUESTION # 176
......
AIF-C01 Top Exam Dumps: https://www.dumpsvalid.com/AIF-C01-still-valid-exam.html
P.S. Free & New AIF-C01 dumps are available on Google Drive shared by DumpsValid: https://drive.google.com/open?id=1LGd-AEuqcXsvseiQMKC1FCb5_eQNH3co