As we all know, a good Databricks-Certified-Professional-Data-Engineer Exam Torrent can win the support and fond of the customers, Databricks-Certified-Professional-Data-Engineer exam dumps of are just the product like this. With high pass rate and high quality, we have received good reputation in different countries in the world. We are a professional enterprise in this field, with rich experience and professional spirits, we have help many candidates pass the exam. What’s more, the free update is also provided.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion & Acquisition | 7% | - Schema inference and evolution - Auto Loader and streaming ingestion - Connecting to diverse data sources |
| Ensuring Data Security and Compliance | 10% | - Access control and permissions - Data encryption and masking - Compliance standards implementation |
| Data Governance | 7% | - Data lineage and metadata tracking - Policy enforcement - Unity Catalog management |
| Data Transformation, Cleansing, and Quality | 10% | - Standardization and normalization - Handling missing or inconsistent data - Data validation and quality checks |
| Debugging and Deploying | 10% | - CI/CD and DevOps practices - Troubleshooting pipelines and errors - Deployment using bundles, CLI, and APIs |
| Developing Code for Data Processing using Python and SQL | 22% | - Integration with Databricks APIs and tools - Batch and incremental processing logic - Data transformation and aggregation |
| Data Modelling | 6% | - Medallion Architecture implementation - Schema design and management - Delta Lake table design |
| Monitoring and Alerting | 10% | - Setting up alerts and notifications - Performance and health monitoring - Pipeline observability and logging |
| Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling - Query optimization and caching |
>> Reliable Databricks-Certified-Professional-Data-Engineer Exam Price <<
In our software version of the Databricks-Certified-Professional-Data-Engineer exam dumps, the unique point is that you can take part in the practice test before the real Databricks-Certified-Professional-Data-Engineer exam. You never know what you can get till you try. It is universally acknowledged that mock examination is of great significance for those who are preparing for the exam since candidates can find deficiencies of their knowledge as well as their shortcomings in the practice test, so that they can enrich their knowledge before the Real Databricks-Certified-Professional-Data-Engineer Exam.
NEW QUESTION # 211
The data governance team has instituted a requirement that all tables containing Personal Identifiable Information (PH) must be clearly annotated. This includes adding column comments, table comments, and setting the custom table property " contains_pii " = true .
The following SQL DDL statement is executed to create a new table: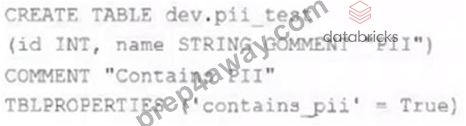
Which command allows manual confirmation that these three requirements have been met?
Answer: D
Explanation:
This is the correct answer because it allows manual confirmation that these three requirements have been met.
The requirements are that all tables containing Personal Identifiable Information (PII) must be clearly annotated, which includes adding column comments, table comments, and setting the custom table property
"contains_pii" = true. The DESCRIBE EXTENDED command is used to display detailed information about a table, such as its schema, location, properties, and comments. By using this command on the dev.pii_test table, one can verify that the table has been created with the correct column comments, table comment, and custom table property as specified in the SQL DDL statement. Verified References: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "DESCRIBE EXTENDED" section.
NEW QUESTION # 212
How are the operational aspects of Lakeflow Declarative Pipelines different from Spark Structured Streaming ?
Answer: B
Explanation:
Databricks documentation explains that Lakeflow Declarative Pipelines build upon Structured Streaming but add higher-level orchestration and automation capabilities. They automatically manage dependencies, materialization, and recovery across multi-stage data flows without requiring external orchestration tools such as Airflow or Azure Data Factory. In contrast, Structured Streaming operates at a lower level, where developers must manually handle orchestration, retries, and dependencies between streaming jobs. Both support Delta Lake outputs and schema evolution; however, Lakeflow Declarative Pipelines simplify management by declaratively defining transformations and data quality expectations. Hence, the correct distinction is A - automated orchestration and management in Lakeflow Declarative Pipelines.
NEW QUESTION # 213
When evaluating the Ganglia Metrics for a given cluster with 3 executor nodes, which indicator would signal proper utilization of the VM's resources?
Answer: D
Explanation:
In the context of cluster performance and resource utilization, a CPU utilization rate of around 75% is generally considered a good indicator of efficient resource usage. This level of CPU utilization suggests that the cluster is being effectively used without being overburdened or underutilized.
* A consistent 75% CPU utilization indicates that the cluster's processing power is being effectively employed while leaving some headroom to handle spikes in workload or additional tasks without maxing out the CPU, which could lead to performance degradation.
* A five Minute Load Average that remains consistent/flat (Option A) might indicate underutilization or a bottleneck elsewhere.
* Monitoring network I/O (Options B and C) is important, but these metrics alone don't provide a complete picture of resource utilization efficiency.
* Total Disk Space (Option D) remaining constant is not necessarily an indicator of proper resource utilization, as it's more related to storage rather than computational efficiency.
References:
* Ganglia Monitoring System: Ganglia Documentation
* Databricks Documentation on Monitoring: Databricks Cluster Monitoring
NEW QUESTION # 214
The data governance team is reviewing user for deleting records for compliance with GDPR. The following logic has been implemented to propagate deleted requests from the user_lookup table to the user aggregate table.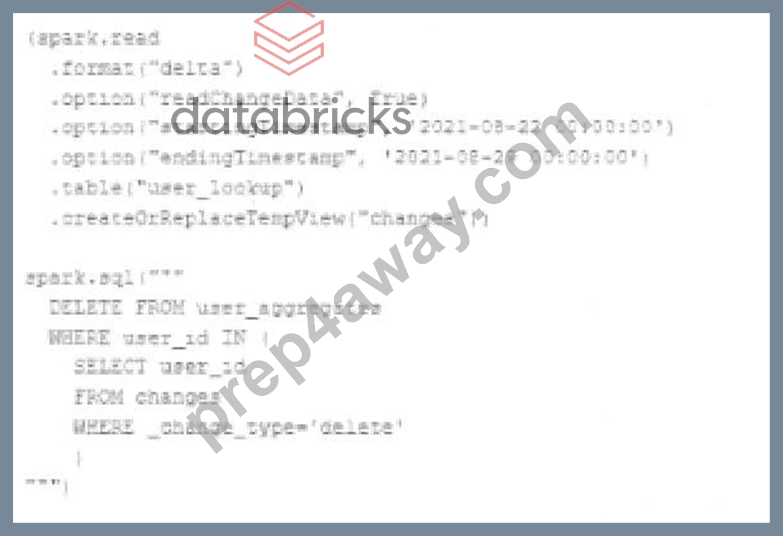
Assuming that user_id is a unique identifying key and that all users have requested deletion have been removed from the user_lookup table, which statement describes whether successfully executing the above logic guarantees that the records to be deleted from the user_aggregates table are no longer accessible and why?
Answer: D
Explanation:
The DELETE operation in Delta Lake is ACID compliant, which means that once the operation is successful, the records are logically removed from the table. However, the underlying files that contained these records may still exist and be accessible via time travel to older versions of the table. To ensure that these records are physically removed and compliance with GDPR is maintained, a VACUUM command should be used to clean up these data files after a certain retention period. The VACUUM command will remove the files from the storage layer, and after this, the records will no longer be accessible.
NEW QUESTION # 215
What type of table is created when you create delta table with below command?
CREATE TABLE transactions USING DELTA LOCATION "DBFS:/mnt/bronze/transactions"
Answer: E
Explanation:
Explanation
Anytime a table is created using the LOCATION keyword it is considered an external table, below is the current syntax.
Syntax
CREATE TABLE table_name ( column column_data_type...) USING format LOCATION "dbfs:/" format -> DELTA, JSON, CSV, PARQUET, TEXT I created the table command based on the above question, you can see it created an external table,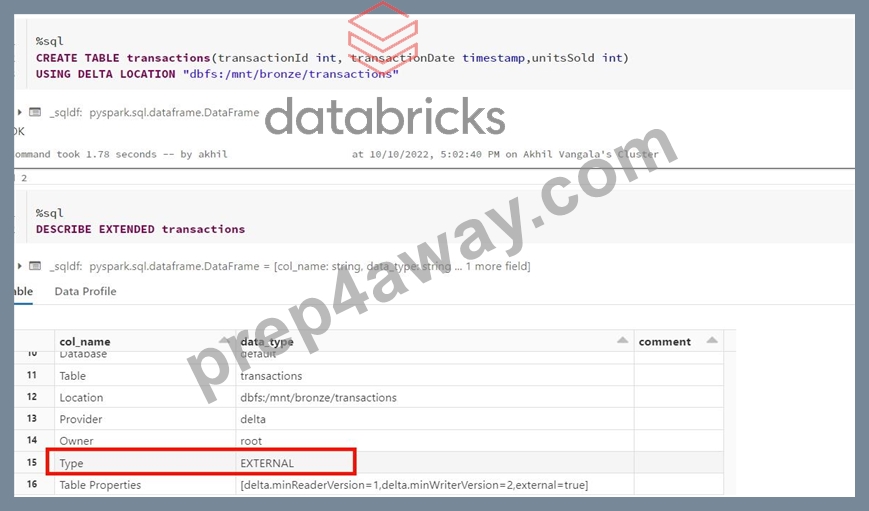
NEW QUESTION # 216
......
Databricks-Certified-Professional-Data-Engineer also offers free demos, allowing users to test the quality and suitability of the Databricks-Certified-Professional-Data-Engineer exam dumps before purchasing. The demo provides access to a limited portion of the material, providing users with a better understanding of the content. Additionally, Databricks-Certified-Professional-Data-Engineer provides three months of free updates to ensure that candidates have access to the latest questions.
Databricks-Certified-Professional-Data-Engineer Reliable Braindumps Book: https://www.prep4away.com/Databricks-certification/braindumps.Databricks-Certified-Professional-Data-Engineer.ete.file.html