P.S. Free & New DP-750 dumps are available on Google Drive shared by Itbraindumps: https://drive.google.com/open?id=1EpxF-fXJ2TmbBYzixcuBjyYP5-SiXc2v
In rare cases, if you fail to pass the Implementing Data Engineering Solutions Using Azure Databricks DP-750 exam despite using Implementing Data Engineering Solutions Using Azure Databricks exam dumps we will return your whole payment without any deduction. Take the best decision of your professional career and start exam preparation with Implementing Data Engineering Solutions Using Azure Databricks exam practice questions and become a certified Implementing Data Engineering Solutions Using Azure Databricks DP-750 expert.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Prepare and process data | 30-35% | - Data transformation and modeling
|
| Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
In contemporary society, information is very important to the development of the individual and of society (DP-750 practice test), and information technology gives considerable power to those able to access and use it. Therefore, we should dare to explore, and be happy to accept new things. In terms of preparing for exams, we really should not be restricted to paper material, there are so many advantages of our electronic DP-750 Study Guide, such as High pass rate, Fast delivery and free renewal for a year to name but a few. I can assure you that you will pass the exam as well as getting the related certification as easy as rolling off a log.
NEW QUESTION # 65
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount.isNotNull())
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
NEW QUESTION # 66
You have a Lakeflow Spark Declarative Pipelines {SDP) pipeline in Azure Databricks. The pipeline ingests transaction data into a table named Table1.
You need to ensure that in the event of an invalid record, the pipeline continues to run. The solution must meet the following requirements:
* Invalid records must NOT be written to Table 1.
* Invalid records must be preserved for review.
* Minimize development effort
What should you do?
Answer: A
Explanation:
The correct answer is B - define a pipeline expectation.
SDP expectations with @dlt.expect_or_drop are built precisely for this scenario: the pipeline keeps running, bad records are excluded from Table1, and those records are automatically captured in the pipeline's event log as expectation violations - available for review without any extra code.
Option A (custom quarantine logic) would work but requires writing and maintaining additional pipeline tables and routing logic. The whole point of SDP expectations is to handle this pattern declaratively, with far less code.
Option C (WHERE clauses in downstream queries) is a read-time filter, not a write-time guard. Invalid records would still land in Table1 and would simply be hidden from downstream views - they're not preserved for review in any structured way. Option D (check constraint on Table1) would throw an exception on write and halt the pipeline, violating the 'pipeline continues to run' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 67
You need to configure resiliency for a job in Lakeflow Jobs named Job1 to meet the pipeline deployment and operation requirements.
What should you do?
Answer: B
Explanation:
Task-level retries allow the ingestion task to recover automatically from transient failures without rerunning unrelated tasks or restarting the complete workflow. Downstream tasks remain governed by their dependencies and start only after ingestion succeeds. This provides focused failure recovery and reduces unnecessary compute consumption. Disabling retries and relying on manual execution directly contradicts the requirement for resilient, automated pipeline operation. Setting the retry count to zero also prevents automatic retry behavior. Restarting the workflow from the first task whenever any task fails would repeat completed processing, increase costs, and potentially reingest data unnecessarily. Lakeflow Jobs supports individual retry policies for tasks, including the number of retries and delay between attempts, making option D the most controlled and operationally efficient configuration. Microsoft Learn
NEW QUESTION # 68
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.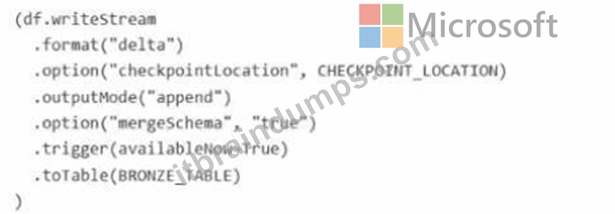
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.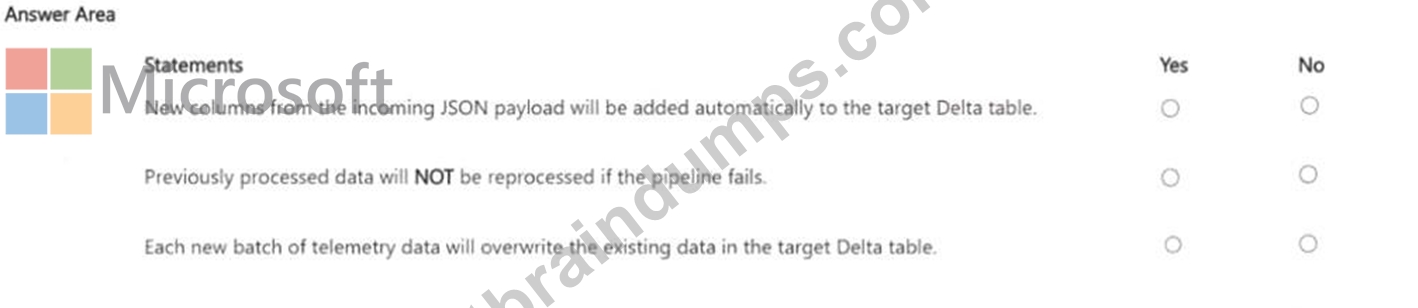
Answer:
Explanation: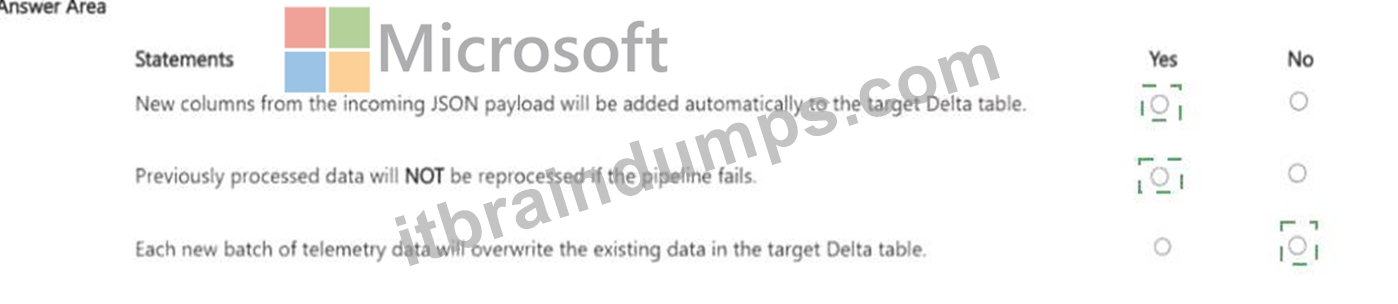
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: 'overwrite' replaces existing data; 'append' adds to it.
Always check whether the code uses the correct Delta format (.format('delta')), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 69
Drag and Drop Question
You have an Azure Databricks workspace that contains an all-purpose compute cluster named Cluster1. Cluser1 is used for interactive development.
You need to configure Cluster1 to meet the following requirements:
- Automatically add and remove worker nodes based on workload demand.
- Automatically shut down when the cluster has been idle for a specific period.
What should you configure for each requirement? To answer, drag the appropriate options to the correct requirements. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.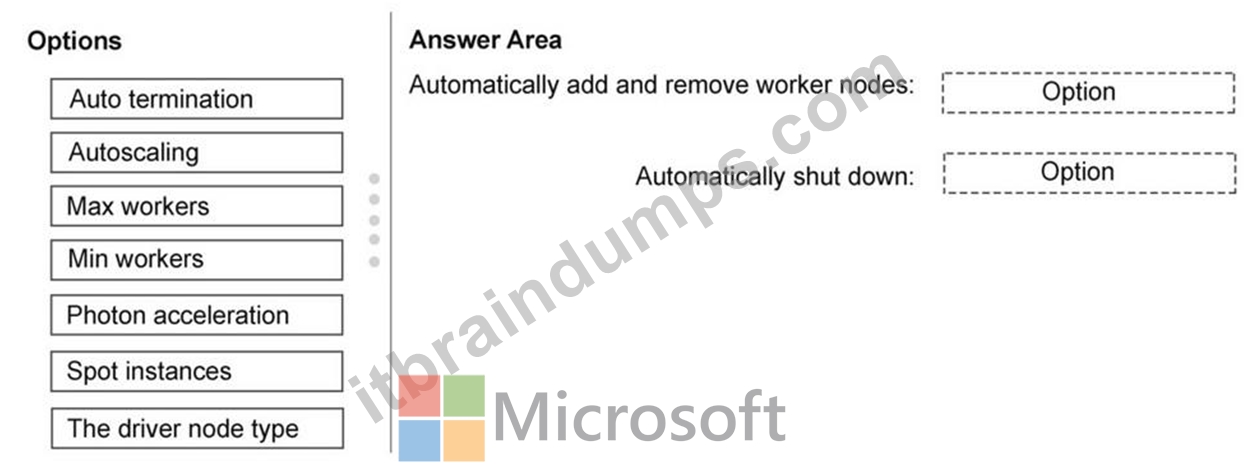
Answer:
Explanation: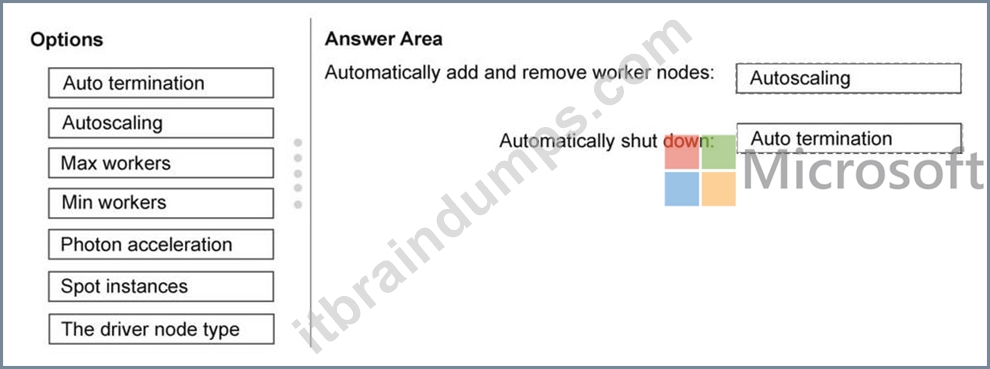
NEW QUESTION # 70
......
The Microsoft DP-750 desktop-based practice exam is compatible with Windows-based computers and only requires an internet connection for the first-time license validation. The web-based Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice test is accessible on any browser without needing to install any separate software. Finally, the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) dumps pdf is easily portable and can be used on smart devices or printed out.
DP-750 Prepaway Dumps: https://www.itbraindumps.com/DP-750_exam.html
What's more, part of that Itbraindumps DP-750 dumps now are free: https://drive.google.com/open?id=1EpxF-fXJ2TmbBYzixcuBjyYP5-SiXc2v