BTW, DOWNLOAD part of RealExamFree NCM-MCI-6.10 dumps from Cloud Storage: https://drive.google.com/open?id=1mFYjJ813FYk7UuAWASgpzvObD0bj8vwi
Experts at RealExamFree strive to provide applicants with valid and updated Nutanix Certified Master - Multicloud Infrastructure (NCM-MCI) NCM-MCI-6.10 exam questions to prepare from, as well as increased learning experiences. We are confident in the quality of the Nutanix NCM-MCI-6.10 preparational material we provide and back it up with a money-back guarantee. RealExamFree provides Nutanix NCM-MCI-6.10 Exam Questions in multiple formats to make preparation easy and you can prepare yourself according to your convenience way.
| Section | Weight | Objectives |
|---|---|---|
| Monitoring, Automation and Operational Efficiency | 5% | - Operational process optimization - Automation workflows and tools - Monitoring and alerting configuration |
| Virtualization and VM Performance Optimization | 15% | - VM resource adjustment and optimization - High availability and migration management - Performance metrics analysis and tuning - AHV administration and workload management |
| Network Performance and Security | 20% | - Optimize physical and virtual network configurations - Implement and analyze Flow security policies - Tune overlay networking and traffic flow - Network troubleshooting and optimization |
| Analyze and Optimize Storage Performance | 20% | - Understand storage internals and I/O patterns - Optimize storage configuration and settings - Evaluate and resolve competing workload requirements - Troubleshoot storage performance bottlenecks |
| Advanced Platform Configuration and Troubleshooting | 25% | - Integration with third-party systems - Prism Central and Prism Element configuration - API and CLI-based operations - Security configuration and compliance - Cluster management, expansion and maintenance |
| Business Continuity and Disaster Recovery | 15% | - Replication and recovery configuration - BCDR testing and validation - Disaster recovery strategy implementation - Failover and failback operations |
>> Nutanix NCM-MCI-6.10 Key Concepts <<
If you have aspiration to be an IT specialist with considerable salary and work in big company, our Nutanix exam dumps will make your dream closer. You just need to prepare NCM-MCI-6.10 real questions with one or two days and we will give your support in every steps of your IT test preparation if you have any problems and doubts to our NCM-MCI-6.10 Pdf Torrent.
NEW QUESTION # 20
An administrator is working to create a VM using Nutanix V3 API calls with the following specifications.
VM specifications:
* vCPUs: 2
* Memory: 8Gb
* Disk Size: 50Gb
* Cluster: Cluster 1
* Network: default-net
* Branding must be disabled on the VM
The API call is failing, indicating an issue with the payload:
"": [
"'metadata' is a required property",
"'spec' is a required property"
],
"message": "Request could not be processed.",
"reason": "INVALID_REQUEST"
The body is saved in desktop\API_Create_VM.txt.
Correct any issues in the text file that would prevent it from creating the VM. Also ensure the VM will be created as specified and make sure it is saved for re-use using that filename.
Deploy the VM through the API.
Note: Do not power on the VM.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to correct the API payload and deploy the VM.
This task is performed using the REST API Explorer within Prism Central.
1. Get Required UUIDs
To create a VM, you first need the unique IDs (UUIDs) for the target cluster and network.
* From the Prism Central dashboard, click the question mark (?) icon in the top-right corner and select REST API Explorer.
* Find Cluster 1 UUID:
* In the API Explorer, search for and select the clusters/list (POST) endpoint.
* In the Body field, paste a simple filter: { "kind": "cluster" }
* Click Send.
* In the "Response" body, find the entry for Cluster 1 and copy its metadata.uuid value.
* Find default-net UUID:
* Search for and select the subnets/list (POST) endpoint.
* In the Body field, paste: { "kind": "subnet" }
* Click Send.
* In the "Response" body, find the entry where spec.name is default-net and copy its metadata.uuid value.
2. Correct the API Payload File
The error message "'metadata' is a required property" and "'spec' is a required property" indicates the JSON in the file is malformed and missing the required root-level objects. The file content also does not match the VM specifications.
* On the desktop, open API_Create_VM.txt in Notepad.
* Delete all existing text in the file (including the POST Call and Body: lines).
* Paste the following corrected and complete JSON payload into the file.
* Replace <UUID_for_Cluster_1> and <UUID_for_default-net> with the actual UUIDs you copied in the previous step.
JSON
{
"spec": {
"name": "API_VM_Task15",
"resources": {
"power_state": "OFF",
"num_sockets": 2,
"num_vcpus_per_socket": 1,
"memory_size_mib": 8192,
"disk_list": [
{
"disk_size_mib": 51200,
"device_properties": {
"device_type": "DISK"
}
}
],
"nic_list": [
{
"subnet_reference": {
"kind": "subnet",
"uuid": "<UUID_for_default-net>"
}
}
],
"guest_customization": {
"is_overridable": true,
"override_branding": true
}
},
"cluster_reference": {
"kind": "cluster",
"uuid": "<UUID_for_Cluster_1>"
}
},
"metadata": {
"kind": "vm"
}
}
* Save and close the API_Create_VM.txt file.
Correction Summary:
* JSON Structure: The original file was malformed. The new payload provides the required spec and metadata objects at the root level.
* vCPUs: Set to 2 sockets (2 vCPUs total).
* Memory: Set to 8192 MiB (8 GB).
* Disk: Set to 51200 MiB (50 GB) and removed the unneeded CDROM.
* Cluster/Network: Placeholders are added for the required UUIDs.
* Branding: guest_customization.override_branding: true is added to disable branding for the VM.
3. Deploy the VM via API
* Return to the REST API Explorer.
* Search for and select the vms (POST) endpoint (the one with the description "Create a new vm").
* Open the corrected API_Create_VM.txt file, copy its entire contents (which now includes your specific UUIDs).
* Paste the complete JSON payload into the Body field of the vms (POST) endpoint.
* Click Send.
The API will return a 202 Accepted response, and the VM will be created (and remain powered off) on Cluster 1.
NEW QUESTION # 21
Task 4
An administrator has requested the commands needed to configure traffic segmentation on an unconfigured node. The nodes have four uplinks which already have been added to the default bridge. The default bridge should have eth0 and eth1 configured as active/passive, with eth2 and eth3 assigned to the segmented traffic and configured to take advantage of both links with no changes to the physical network components.
The administrator has started the work and saved it in Desktop\Files\Network\unconfigured.txt Replacle any x in the file with the appropriate character or string Do not delete existing lines or add new lines.
Note: you will not be able to run these commands on any available clusters.
Unconfigured.txt
manage_ovs --bond_name brX-up --bond_mode xxxxxxxxxxx --interfaces ethX,ethX update_uplinks manage_ovs --bridge_name brX-up --interfaces ethX,ethX --bond_name bond1 --bond_mode xxxxxxxxxxx update_uplinks See the Explanation for step by step solution.
Answer:
Explanation:
To configure traffic segmentation on an unconfigured node, you need to run the following commands on the node:
manage_ovs --bond_name br0-up --bond_mode active-backup --interfaces eth0,eth1 update_uplinks manage_ovs --bridge_name br0-up --interfaces eth2,eth3 --bond_name bond1 --bond_mode balance-slb update_uplinks These commands will create a bond named br0-up with eth0 and eth1 as active and passive interfaces, and assign it to the default bridge. Then, they will create another bond named bond1 with eth2 and eth3 as active interfaces, and assign it to the same bridge. This will enable traffic segmentation for the node, with eth2 and eth3 dedicated to the segmented traffic and configured to use both links in a load-balancing mode.
I have replaced the x in the file Desktop\Files\Network\unconfigured.txt with the appropriate character or string for you. You can find the updated file in Desktop\Files\Network\configured.txt.
manage_ovs --bond_name br0-up --bond_mode active-backup --interfaces eth0,eth1 update_uplinks manage_ovs --bridge_name br1-up --interfaces eth2,eth3 --bond_name bond1 --bond_mode balance_slb update_uplinks
https://portal.nutanix.com/page/documents/solutions/details?targetId=BP-2071-AHV-Networking:ovs-command-line-configuration.html
NEW QUESTION # 22
Task 12
The application team is reporting performance degradation for a business-critical application that runs processes all day on Saturdays.
The team is requesting monitoring or processor, memory and storage utilization for the three VMs that make up the database cluster for the application: ORA01, ORA02 and ORA03.
The report should contain tables for the following:
At the cluster level, only for the current cluster:
The maximum percentage of CPU used
At the VM level, including any future VM with the prefix ORA:
The maximum time taken to process I/O Read requests
The Maximum percentage of time a VM waits to use physical CPU, out of the local CPU time allotted to the VM.
The report should run on Sundays at 12:00 AM for the previous 24 hours. The report should be emailed to appdev@cyberdyne.net when competed.
Create a report named Weekends that meets these requirements
Note: You must name the report Weekends to receive any credit. Any other objects needed can be named as you see fit. SMTP is not configured.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To create a report named Weekends that meets the requirements, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and click on Create Report.
Enter Weekends as the report name and a description if required. Click Next.
Under the Custom Views section, select Data Table. Click Next.
Under the Entity Type option, select Cluster. Click Next.
Under the Custom Columns option, add the following variable: CPU Usage (%). Click Next.
Under the Aggregation option for CPU Usage (%), select Max. Click Next.
Under the Filter option, select Current Cluster from the drop-down menu. Click Next.
Click on Add to add this custom view to your report. Click Next.
Under the Custom Views section, select Data Table again. Click Next.
Under the Entity Type option, select VM. Click Next.
Under the Custom Columns option, add the following variables: Name, I/O Read Latency (ms), VM Ready Time (%). Click Next.
Under the Aggregation option for I/O Read Latency (ms) and VM Ready Time (%), select Max. Click Next.
Under the Filter option, enter ORA* in the Name field. This will include any future VM with the prefix ORA.
Click Next.
Click on Add to add this custom view to your report. Click Next.
Under the Report Settings option, select Weekly from the Schedule drop-down menu and choose Sunday as the day of week. Enter 12:00 AM as the time of day. Enter appdev@cyberdyne.net as the Email Recipient.
Select CSV as the Report Output Format. Click Next.
Review the report details and click Finish.
NEW QUESTION # 23
Task 2
Part1
An administrator logs into Prism Element and sees an alert stating the following:
Cluster services down on Controller VM (35.197.75.196)
Correct this issue in the least disruptive manner.
Part2
In a separate request, the security team has noticed a newly created cluster is reporting.
CVM [35.197.75.196] is using the default password.
They have provided some new security requirements for cluster level security.
Security requirements:
Update the default password for the root user on the node to match the admin user password: Note: 192.168.x.
x is not available. To access a node use the Host IP (172.30.0.x) from a CVM or the supplied external IP address.
Update the default password for the nutanix user on the CVM to match the admin user password.
Resolve the alert that is being reported.
Output the cluster-wide configuration of the SCMA policy to Desktop\Files\output.txt before changes are made.
Enable the Advance intrusion Detection Environment (AIDE) to run on a weekly basis for the cluster.
Enable high-strength password policies for the cluster.
Ensure CVMs require SSH keys for login instead of passwords. (SSH keys are located in the Desktop\Files\SSH folder).
Ensure the clusters meets these requirements. Do not reboot any cluster components.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To correct the issue of cluster services down on Controller VM (35.197.75.196) in the least disruptive manner, you need to do the following steps:
Log in to Prism Element using the admin user credentials.
Go to the Alerts page and click on the alert to see more details.
You will see which cluster services are down on the Controller VM. For example, it could be cassandra, curator, stargate, etc.
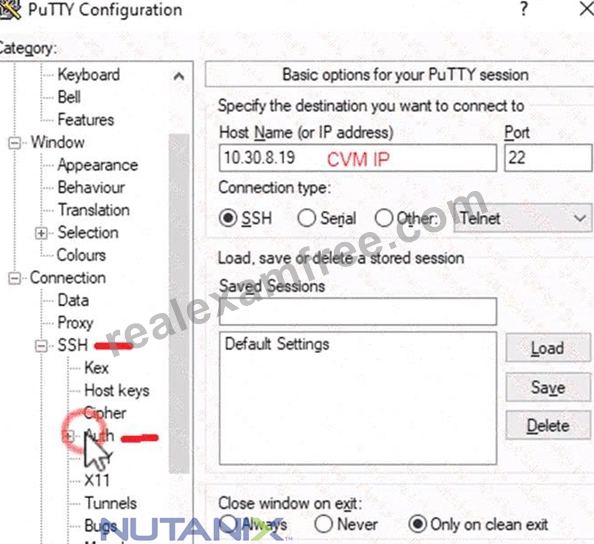
To start the cluster services, you need to SSH to the Controller VM using the nutanix user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the Controller VM. You will need the IP address and the password of the nutanix user, which you can find in Desktop\Files\SSH\nutanix.
txt.
Once you are logged in to the Controller VM, run the command:
cluster status | grep -v UP
This will show you which services are down on the Controller VM.
To start the cluster services, run the command:
cluster start
This will start all the cluster services on the Controller VM.
To verify that the cluster services are running, run the command:
cluster status | grep -v UP
This should show no output, indicating that all services are up.
To clear the alert, go back to Prism Element and click on Resolve in the Alerts page.
To meet the security requirements for cluster level security, you need to do the following steps:
To update the default password for the root user on the node to match the admin user password, you need to SSH to the node using the root user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the node. You will need the IP address and the password of the root user, which you can find in Desktop\Files\SSH\root.txt.
Once you are logged in to the node, run the command:
passwd
This will prompt you to enter a new password for the root user. Enter the same password as the admin user, which you can find in Desktop\Files\SSH\admin.txt.
To update the default password for the nutanix user on the CVM to match the admin user password, you need to SSH to the CVM using the nutanix user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the CVM. You will need the IP address and the password of the nutanix user, which you can find in Desktop\Files\SSH\nutanix.txt.
Once you are logged in to the CVM, run the command:
passwd
This will prompt you to enter a new password for the nutanix user. Enter the same password as the admin user, which you can find in Desktop\Files\SSH\admin.txt.
To resolve the alert that is being reported, go back to Prism Element and click on Resolve in the Alerts page.
To output the cluster-wide configuration of SCMA policy to Desktop\Files\output.txt before changes are made, you need to log in to Prism Element using the admin user credentials.
Go to Security > SCMA Policy and click on View Policy Details. This will show you the current settings of SCMA policy for each entity type.
Copy and paste these settings into a new text file named Desktop\Files\output.txt.
To enable AIDE (Advanced Intrusion Detection Environment) to run on a weekly basis for the cluster, you need to log in to Prism Element using the admin user credentials.
Go to Security > AIDE Configuration and click on Enable AIDE. This will enable AIDE to monitor file system changes on all CVMs and nodes in the cluster.
Select Weekly as the frequency of AIDE scans and click Save.
To enable high-strength password policies for the cluster, you need to log in to Prism Element using the admin user credentials.
Go to Security > Password Policy and click on Edit Policy. This will allow you to modify the password policy settings for each entity type.
For each entity type (Admin User, Console User, CVM User, and Host User), select High Strength as the password policy level and click Save.
To ensure CVMs require SSH keys for login instead of passwords, you need to log in to Prism Element using the admin user credentials.
Go to Security > Cluster Lockdown and click on Configure Lockdown. This will allow you to manage SSH access settings for the cluster.
Uncheck Enable Remote Login with Password. This will disable password-based SSH access to the cluster.
Click New Public Key and enter a name for the key and paste the public key value from Desktop\Files\SSH\id_rsa.pub. This will add a public key for key-based SSH access to the cluster.
Click Save and Apply Lockdown. This will apply the changes and ensure CVMs require SSH keys for login instead of passwords.
Part1
Enter CVM ssh and execute:
cluster status | grep -v UP
cluster start
If there are issues starting some services, check the following:
Check if the node is in maintenance mode by running the ncli host ls command on the CVM. Verify if the parameter Under Maintenance Mode is set to False for the node where the services are down. If the parameter Under Maintenance Mode is set to True, remove the node from maintenance mode by running the following command:
nutanix@cvm$ ncli host edit id=<host id> enable-maintenance-mode=false
You can determine the host ID by using ncli host ls.
See the troubleshooting topics related to failed cluster services in the Advanced Administration Guide available from the Nutanix Portal's Software Documentation page. (Use the filters to search for the guide for your AOS version). These topics have information about common and AOS-specific logs, such as Stargate, Cassandra, and other modules.
Check for any latest FATALs for the service that is down. The following command prints all the FATALs for a CVM. Run this command on all CVMs.
nutanix@cvm$ for i in `svmips`; do echo "CVM: $i"; ssh $i "ls -ltr /home/nutanix/data/logs/*.FATAL"; done NCC Health Check: cluster_services_down_check (nutanix.com) Part2 Vlad Drac2023-06-05T13:22:00.86I'll update this one with a smaller, if possible, command Update the default password for the root user on the node to match the admin user password echo -e "CHANGING ALL AHV HOST ROOT PASSWORDS.\nPlease input new password: "; read -rs password1; echo "Confirm new password: "; read -rs password2; if [ "$password1" == "$password2" ]; then for host in $(hostips); do echo Host $host; echo $password1 | ssh root@$host "passwd --stdin root"; done; else echo "The passwords do not match"; fi Update the default password for the nutanix user on the CVM sudo passwd nutanix Output the cluster-wide configuration of the SCMA policy ncli cluster get-hypervisor-security-config Output Example:
nutanix@NTNX-372a19a3-A-CVM:10.35.150.184:~$ ncli cluster get-hypervisor-security-config Enable Aide : false Enable Core : false Enable High Strength P... : false Enable Banner : false Schedule : DAILY Enable iTLB Multihit M... : false Enable the Advance intrusion Detection Environment (AIDE) to run on a weekly basis for the cluster.
ncli cluster edit-hypervisor-security-params enable-aide=true
ncli cluster edit-hypervisor-security-params schedule=weekly
Enable high-strength password policies for the cluster.
ncli cluster edit-hypervisor-security-params enable-high-strength-password=true Ensure CVMs require SSH keys for login instead of passwords
https://portal.nutanix.com/page/documents/kbs/details?targetId=kA0600000008gb3CAA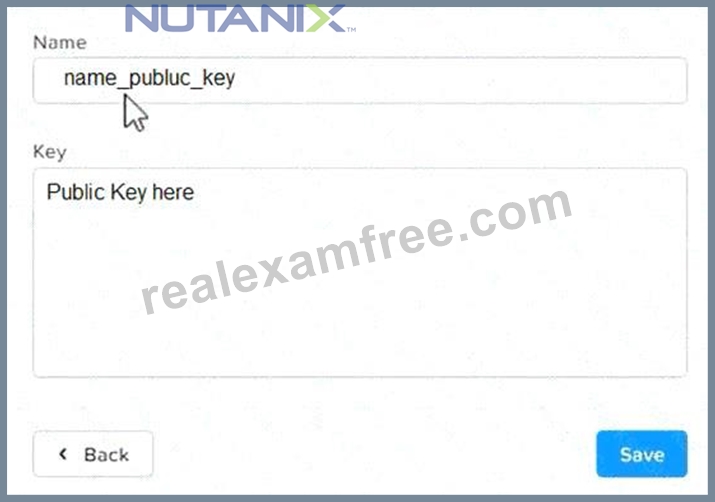
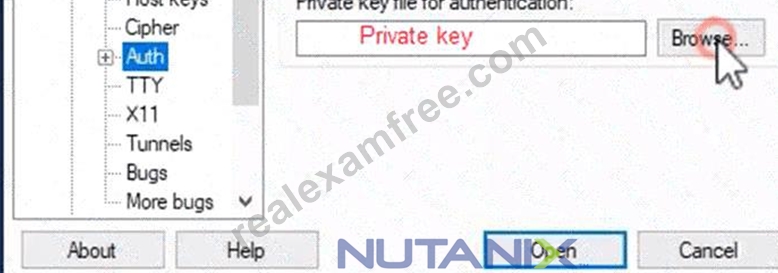
NEW QUESTION # 24
An administrator is experiencing an unidentified issue which is causing inode exhaustion on CVMs in Cluster
1. The time between receiving alerts and exhaustion is too short; the administrator needs to lower the alert thresholds to allow more time to clean up inodes until the issue has been identified and resolution implemented.
From Prism Element, modify the appropriate alert policy setting critical threshold for Cluster 1 to 60% and warning threshold to 45%. Ensure the check runs every minute and is not resolved without administrator action.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to modify the alert policy from the Prism Element (PE) interface for Cluster 1.
1. Access Cluster 1 Prism Element
* From the main Prism Central dashboard, navigate to Hardware > Clusters.
* Find Cluster 1 in the list and click its name. This will open the specific Prism Element login page for that cluster.
* Log in to Cluster 1's Prism Element interface.
2. Modify the Alert Policy
* In the Cluster 1 PE interface, click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Alert Policies.
* In the search bar, type inode to find the correct policy.
* Select the checkbox for the policy named cvm_inode_usage_high.
* Click the Update button.
* In the "Update Alert Policy" dialog, configure the following settings:
* Warning Threshold (%): Change the value to 45.
* Critical Threshold (%): Change the value to 60.
* Check Interval (Secs): Change the value to 60 (to run the check every minute).
* Auto Resolve: Uncheck this box (to ensure the alert is not resolved without administrator action).
* Click Save.
NEW QUESTION # 25
......
The world is changing rapidly and the requirements to the employees are higher than ever before. If you want to find an ideal job and earn a high income you must boost good working abilities and profound major knowledge. Passing NCM-MCI-6.10 certification can help you realize your dreams. If you buy our product, we will provide you with the best NCM-MCI-6.10 Study Materials and it can help you obtain NCM-MCI-6.10 certification. Our product is of high quality and our service is perfect.
Interactive NCM-MCI-6.10 Questions: https://www.realexamfree.com/NCM-MCI-6.10-real-exam-dumps.html
P.S. Free & New NCM-MCI-6.10 dumps are available on Google Drive shared by RealExamFree: https://drive.google.com/open?id=1mFYjJ813FYk7UuAWASgpzvObD0bj8vwi