DAA-C01専門知識訓練 & DAA-C01受験対策

無料でクラウドストレージから最新のXhs1991 DAA-C01 PDFダンプをダウンロードする:https://drive.google.com/open?id=12L7ojmGEFqafmh_VavYomBfug8oT1DKf
SnowflakeのDAA-C01試験トレントの指示に従って、準備期間を非常に短い時間で完了し、試験に合格することもできます。これにより、多くの時間とエネルギーを節約し、SnowPro Advanced: Data Analyst Certification Exam準備トレントで生産性を高めることができます。 実際、あなたが進歩するための高効率な準備時間を保証する理由は、主に、当社Xhs1991のDAA-C01テストで学習プロセス中に顧客を集中させ、ターゲットを絞ることができるコンテンツとレイアウトの素晴らしい組織に起因します ブレインダンプ。 DAA-C01のSnowPro Advanced: Data Analyst Certification Exam試験準備の高い合格率は99%〜100%です。
Snowflake DAA-C01 Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Security, Governance, and Data Sharing | - Access control and security
- 1. Authentication and encryption concepts
- 2. Role-based access control (RBAC)
- Data sharing and governance
- 1. Data masking and policies
- 2. Secure data sharing
|
| Topic 2: Data Loading and Unloading | - Data ingestion methods
- 1. Continuous ingestion and Snowpipe concepts
- 2. COPY INTO and bulk loading
- Data export
- 1. UNLOAD and external stages
|
| Topic 3: Data Modeling and Performance Optimization | - Performance tuning
- 1. Clustering and pruning techniques
- 2. Warehouse sizing and auto-suspend/auto-resume
- Modeling approaches in Snowflake
- 1. Data normalization vs denormalization
- 2. Star and snowflake schemas
|
| Topic 4: Snowflake Architecture and Data Platform Fundamentals | - Snowflake architecture concepts
- 1. Cloud services layer, compute layer, storage layer
- 2. Virtual warehouses and scaling
- Data platform fundamentals
- 1. Data lifecycle in Snowflake
- 2. Separation of storage and compute
|
| Topic 5: Data Transformation and Analysis | - SQL-based transformations
- 1. Semi-structured data (VARIANT, JSON, XML)
- 2. Joins, aggregations, window functions
- Analytical workloads
- 1. Materialized views and caching
- 2. Query optimization for analytics
|
>> DAA-C01専門知識訓練 <<
最高のSnowflake DAA-C01専門知識訓練 & 合格スムーズDAA-C01受験対策 | 真実的なDAA-C01学習体験談
DAA-C01勉強のトレントを購入すると、24時間オンラインの効率的なサービスを提供します。 DAA-C01学習資料に関するご質問はいつでもお問い合わせいただけます。また、いつでもご連絡いただけます。もちろん、忙しくてオンラインで連絡する時間がない場合は、心配しないで、いつでもDAA-C01ガイド資料に関する問題をメールでお知らせください。カスタマーサービスからすぐにメールが届きます。一言で言えば、24時間オンラインの効率的なサービスは、すべての問題を解決して試験に合格するのに役立つと考えています。
Snowflake SnowPro Advanced: Data Analyst Certification Exam 認定 DAA-C01 試験問題 (Q10-Q15):
質問 # 10
You are tasked with loading JSON files into Snowflake using Snowsight. The JSON files are semi-structured and contain nested arrays and objects. You want to flatten the JSON structure during the load process to facilitate easier querying. Which of the following Snowsight-integrated features or approaches are suitable for flattening the JSON data during the load process? Select all that apply.
- A. Use Snowsight's 'Load Data' wizard along with Snowflake's built-in functions like 'GET_PATH' and operator within the computed column expressions during the load process to extract and load specific elements from the JSON data into individual columns.
- B. Load the JSON data into a staging table as raw JSON strings. Then, write a custom Python User-Defined Function (UDF) that parses the JSON strings and returns a flattened representation of the data. Use this UDF in a 'CREATE TABLE AS SELECT statement to load the flattened data into a new table.
- C. Use Snowsight's 'Load Data' wizard to load the JSON files directly into relational tables by defining mappings between JSON elements and table columns. Snowsight automatically flattens the JSON structure based on the defined mappings.
- D. Load the JSON data into a VARIANT column in Snowflake. Then, use SQL with 'LATERAL FLATTEN' to query and extract data from the nested structures, creating a view to represent the flattened data.
- E. Create a Snowpipe that automatically loads new JSON files from a stage into a Snowflake table. Within the Snowpipe definition, define a transformation that uses 'LATERAL FLATTEN' to flatten the JSON data before loading it into the target table.
正解:A、D、E
解説:
Options A, C, and E are all suitable approaches for flattening JSON data. Option A leverages 'LATERAL FLATTEN' in SQL, which is a common and efficient way to flatten JSON structures after loading into a VARIANT column. Option C utilizes Snowpipe with a transformation including 'LATERAL FLATTEN' , enabling automatic flattening during ingestion. Option E uses computed columns in Snowsight to extract JSON elements during loading using 'GET_PATH' or the operator. Option B is incorrect; Snowsight's 'Load Data' wizard doesn't automatically flatten JSON during the initial load. It mainly handles the basic load of the JSON file into a VARIANT column, not automatic flattening. Option D is a valid but less performant alternative; UDFs can be slower than native Snowflake SQL functions for large datasets.
質問 # 11
You are analyzing sales data in Snowflake to identify seasonal trends and patterns. You have a table 'SALES DATA with columns 'SALE DATE (DATE) and 'SALE_AMOUNT (NUMBER). Which of the following SQL queries and visualization techniques would be MOST effective in identifying and visualizing these seasonal trends? Assume the data spans several years.
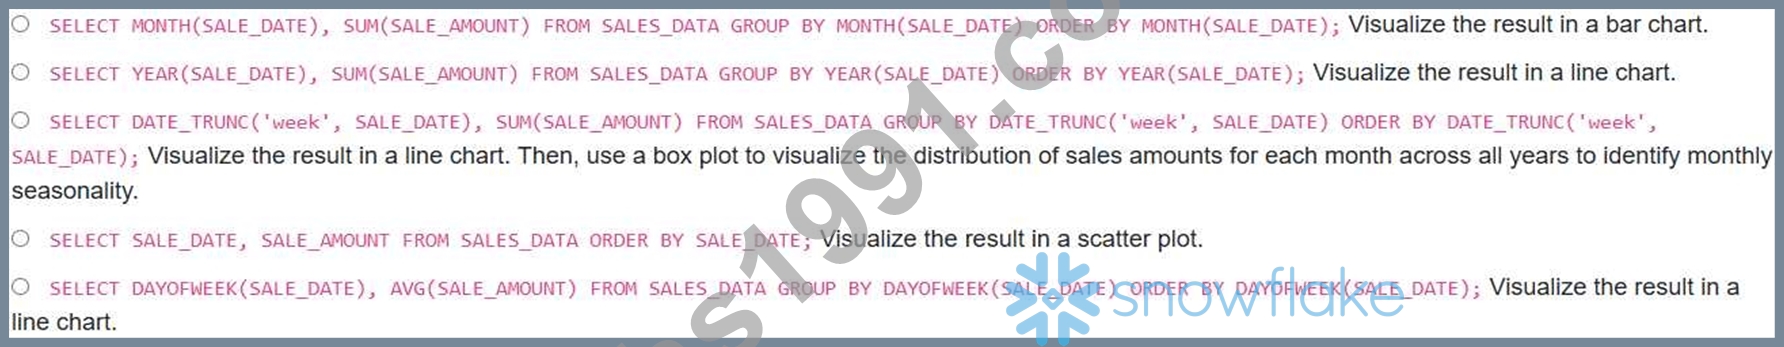
- A. Option B
- B. Option A
- C. Option E
- D. Option C
- E. Option D
正解:D
解説:
Option C is the most effective because it combines weekly sales aggregation with a box plot analysis of monthly sales across multiple years. The weekly aggregation provides a granular view of sales trends, while the box plot effectively visualizes the distribution of sales for each month, allowing for easy identification of monthly seasonal patterns and outliers. Option A only shows monthly sales volume, not the distribution of sales within each month across years. Option B shows the yearly trend, not seasonal variations. Option D doesn't aggregate the data and hence can't show you the seasonality. Option E only shows the daily variance across weeks.
質問 # 12
How do constraints, such as primary keys, impact table joins between parent/child tables in Snowflake?
- A. Constraints restrict data access to authorized user roles
- B. Primary keys allow only one-to-one table joins
- C. Primary keys ensure data uniqueness for table relationships
- D. Constraints limit table join operations to specific data types
正解:C
解説:
Primary keys enforce data uniqueness, ensuring integrity and maintaining relationships between parent and child tables in Snowflake.
質問 # 13
A marketing team wants to visualize customer engagement across different channels (email, website, social media). They have engagement data stored in a Snowflake table 'CUSTOMER ENGAGEMENT' with columns 'CUSTOMER ID, 'CHANNEL', 'EVENT TYPE', 'EVENT TIMESTAMP', and 'EVENT VALUE' (representing engagement score). They need a dashboard that efficiently displays the total engagement score per channel for the last 7 days, allowing for quick drill-down into individual customer behavior. Which approach provides the MOST optimized query and view structure for this requirement, prioritizing performance for a large dataset?
- A. Use a stored procedure to calculate the engagement score and update a temporary table daily. The dashboard queries this temporary table.
- B. Create a view that directly aggregates data from 'CUSTOMER_ENGAGEMENT for the last 7 days in the dashboard query itself. Use 'GROUP BY CHANNEL' and ' SUM(EVENT_BALUE)'.
- C. Load the entire 'CUSTOMER ENGAGEMENT table into the dashboard tool's internal memory and perform the aggregation and filtering there.
- D. Create a materialized view 'MV CUSTOMER ENGAGEMENT that pre-aggregates the total engagement score per channel for the last 7 days, refreshed daily using a Snowflake task. The dashboard query then selects directly from this materialized view.
- E. Create a standard view that aggregates data from 'CUSTOMER ENGAGEMENT using 'GROUP BY CHANNEL' , but without filtering for the last 7 days. Filter for the last 7 days within the dashboard query.
正解:D
解説:
Materialized views (B) are the most performant option because they pre-compute and store the aggregated data. A daily refresh using a Snowflake task ensures the data is up-to-date. Option A requires the aggregation to be performed every time the dashboard is loaded. Option C is less efficient than B because it filters after aggregation. Option D is not scalable for large datasets. Option E adds unnecessary complexity and potential performance bottlenecks with the stored procedure and temporary table.
質問 # 14
You are working with a dataset containing customer orders and their associated products. The data is stored in two tables: 'ORDERS' (order_id, customer_id, order_date) and 'ORDER ITEMS' (order_id, product_id, quantity, price). The Bl team needs to analyze the top- selling products and the average order value per customer. However, due to data quality issues, some 'order _ id' values in the 'ORDER ITEMS table do not exist in the 'ORDERS' table, leading to data inconsistencies. What is the most robust and efficient way to handle this data inconsistency issue while ensuring accurate reporting?
- A. Use a LEFT JOIN from 'ORDERS' to 'ORDER ITEMS to include all orders, even if they don't have corresponding items. Filter out rows with NULL 'product_id' in the final result.
- B. Use a RIGHT JOIN from 'ORDERS' to 'ORDER ITEMS' and filter out rows where order details are missing.
- C. Use a UNION ALL statement to combine the two tables, creating a single table with all order and item information. Handle inconsistencies during data extraction and loading (ETL) processes.
- D. Use an INNER JOIN between 'ORDERS' and 'ORDER ITEMS'. Before joining, use a subquery or CTE to filter 'ORDER ITEMS' to include only 'order_id' values that exist in 'ORDERS'. After joining apply a filter for valid prices(Price > 0). This ensures correct analysis and avoids invalid orders. Select all the rows with valid prices (Price > 0).
- E. Create a flattened view that combines 'ORDERS' and 'ORDER_ITEMS' using a FULL OUTER JOIN. Handle missing values in the reporting layer.
正解:D
解説:
Option B provides the most robust and efficient solution. By using an INNER JOIN after filtering the 'ORDER_ITEMS' table to include only valid 'order_id' values (those present in the 'ORDERS' table), you ensure that the analysis is based on consistent and reliable data. The subquery/CTE effectively cleans the data before joining, preventing inaccurate calculations. Filtering for valid prices ensures data quality. Option A would include orders without item details, which is not desired for this analysis. Options C and D might result in inaccurate results due to the incomplete relationship between orders and products. Option E is not suitable since it mixes the distinct column sets, resulting in inaccurate analyses. Always ensure referential integrity where business logic dictates.
質問 # 15
......
当社のWebサイトにある優れたDAA-C01学習教材の助けを借りてDAA-C01試験を受ける準備ができている場合、選択は素晴らしいものになります。 DAA-C01トレーニング資料は優れた選択肢であり、特にDAA-C01試験に時間をかけずに合格し、成功することに熱心な方に役立ちます。 それに加えて、DAA-C01の調査問題には3つのバージョンがあります。PDFバージョン、ソフトバージョン、およびAPPバージョンです。これらは興味深く、選択するのに役立ちます。
DAA-C01受験対策: https://www.xhs1991.com/DAA-C01.html
- 高品質なDAA-C01専門知識訓練 - 合格スムーズDAA-C01受験対策 | 100%合格率のDAA-C01学習体験談 🌳 ▶ DAA-C01 ◀を無料でダウンロード▛ www.passtest.jp ▟ウェブサイトを入力するだけDAA-C01無料ダウンロード
- DAA-C01日本語版問題集 🎹 DAA-C01認定資格 ☣ DAA-C01日本語版 🏖 ☀ www.goshiken.com ️☀️には無料の( DAA-C01 )問題集がありますDAA-C01日本語参考
- DAA-C01必殺問題集 🔌 DAA-C01対応内容 🕔 DAA-C01対応内容 🐱 [ www.passtest.jp ]に移動し、《 DAA-C01 》を検索して、無料でダウンロード可能な試験資料を探しますDAA-C01再テスト
- DAA-C01日本語版問題集 📙 DAA-C01日本語版問題集 💟 DAA-C01日本語参考 🕟 今すぐ➤ www.goshiken.com ⮘を開き、“ DAA-C01 ”を検索して無料でダウンロードしてくださいDAA-C01関連資格試験対応
- DAA-C01模擬対策 🔦 DAA-C01テスト内容 🚍 DAA-C01日本語参考 🧐 URL ☀ www.mogiexam.com ️☀️をコピーして開き、▶ DAA-C01 ◀を検索して無料でダウンロードしてくださいDAA-C01復習対策書
- 高品質なDAA-C01専門知識訓練一回合格-素敵なDAA-C01受験対策 💿 ⮆ www.goshiken.com ⮄に移動し、➤ DAA-C01 ⮘を検索して無料でダウンロードしてくださいDAA-C01復習対策書
- 高品質なDAA-C01専門知識訓練 - 合格スムーズDAA-C01受験対策 | 100%合格率のDAA-C01学習体験談 🗣 ➥ www.passtest.jp 🡄に移動し、➠ DAA-C01 🠰を検索して、無料でダウンロード可能な試験資料を探しますDAA-C01対応内容
- 高品質なDAA-C01専門知識訓練 - 合格スムーズDAA-C01受験対策 | 100%合格率のDAA-C01学習体験談 🍾 ウェブサイト⏩ www.goshiken.com ⏪から➤ DAA-C01 ⮘を開いて検索し、無料でダウンロードしてくださいDAA-C01模擬対策
- 高品質なDAA-C01専門知識訓練 - 合格スムーズDAA-C01受験対策 | 100%合格率のDAA-C01学習体験談 🛵 最新「 DAA-C01 」問題集ファイルは【 www.xhs1991.com 】にて検索DAA-C01無料試験
- DAA-C01必殺問題集 👤 DAA-C01日本語参考 🥒 DAA-C01日本語版問題集 🏁 サイト【 www.goshiken.com 】で➡ DAA-C01 ️⬅️問題集をダウンロードDAA-C01必殺問題集
- DAA-C01資格問題対応 🕜 DAA-C01無料ダウンロード 🍋 DAA-C01日本語参考 🥫 ➤ www.xhs1991.com ⮘で[ DAA-C01 ]を検索して、無料で簡単にダウンロードできますDAA-C01関連資格試験対応
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
さらに、Xhs1991 DAA-C01ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=12L7ojmGEFqafmh_VavYomBfug8oT1DKf