有難いDatabricks-Certified-Professional-Data-Engineer受験記と便利なDatabricks-Certified-Professional-Data-Engineerサンプル問題集

さらに、GoShiken Databricks-Certified-Professional-Data-Engineerダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1cmFGcg2exZInBMzqpfAFoq7kmb1gU2fA
GoShikenのDatabricks-Certified-Professional-Data-Engineer問題集を入手してから、非常に短い時間で試験に準備しても、あなたは順調に試験に合格することができます。GoShikenの問題集には、実際の試験に出る可能性がある問題が全部含まれていますから、問題集における問題を覚える限り、簡単に試験に合格することができます。これは試験に合格する最速のショートカットです。仕事に忙しいから試験の準備をする時間はあまりないとしたら、絶対GoShikenのDatabricks-Certified-Professional-Data-Engineer問題集を見逃すことはできないです。これはあなたがDatabricks-Certified-Professional-Data-Engineer試験に合格できる最善で、しかも唯一の方法ですから。
Databricks Databricks-Certified-Professional-Data-Engineer Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Data Ingestion | 15-20% | - Batch ingestion methods
- 1. Spark APIs for ingestion
- 2. Integration with external systems
- 3. DBR autoloader
- Streaming ingestion
- 1. Kafka integration
- 2. Structured streaming fundamentals
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Data governance fundamentals
- 2. Bronze, silver, gold data layers
- 3. Differences between data lake, data warehouse, and lakehouse
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Task dependencies and orchestration
- 2. Monitoring and alerting
- 3. Jobs and job scheduling
|
| Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
- 1. Spark SQL queries and functions
- 2. DataFrame operations and transformations
- 3. Window functions
- Python and SQL for data engineering
- 1. Spark APIs in Python
- 2. Built-in and user-defined functions
- 3. Performance optimization techniques
|
| Delta Lake | 20-25% | - Delta Lake fundamentals
- 1. ACID transactions
- 2. Time travel and data versioning
- 3. Optimize and Z-order
- Delta Lake operations
- 1. Schema evolution and enforcement
- 2. Delta Live Tables
- 3. Merge, update, delete operations
|
>> Databricks-Certified-Professional-Data-Engineer受験記 <<
Databricks-Certified-Professional-Data-Engineerサンプル問題集 & Databricks-Certified-Professional-Data-Engineer試験
何よりもまず、国際市場のさまざまな国の人々のさまざまなニーズに応えるために、このWebサイトでDatabricks-Certified-Professional-Data-Engineer学習質問の3種類のバージョンを用意しました。第二に、Databricks-Certified-Professional-Data-Engineer実践教材の支払い後、年間を通じて当社から最新のトレーニング教材を無料で入手できることを保証できます。最後になりましたが、私たちは週7日、1日24時間でお客様に最も思いやりのあるアフターサービスを提供します。
Databricks Certified Professional Data Engineer Exam 認定 Databricks-Certified-Professional-Data-Engineer 試験問題 (Q39-Q44):
質問 # 39
A nightly job ingests data into a Delta Lake table using the following code:
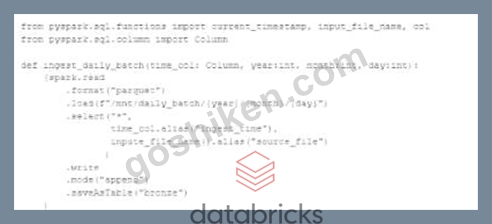
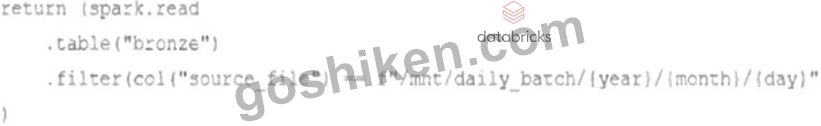
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
- A. return spark.read.option("readChangeFeed", "true").table ("bronze")
- B. return spark.readStream.load("bronze")
- C.
- D. return spark.readStream.table("bronze")
正解:C
解説:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
質問 # 40
A data engineer is testing a collection of mathematical functions, one of which calculates the area under a curve as described by another function.
Which kind of the test does the above line exemplify?
- A. Integration
- B. Unit
- C. Manual
- D. functional
正解:B
解説:
A unit test is designed to verify the correctness of a small, isolated piece of code, typically a single function. Testing a mathematical function that calculates the area under a curve is an example of a unit test because it is testing a specific, individual function to ensure it operates as expected.
Reference:
Software Testing Fundamentals: Unit Testing
質問 # 41
A Delta Lake table representing metadata about content from user has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE Based on the above schema, which column is a good candidate for partitioning the Delta Table?
- A. Post_time
- B. Date
- C. Post_id
- D. User_id
正解:B
解説:
Partitioning a Delta Lake table improves query performance by organizing data into partitions based on the values of a column. In the given schema, the date column is a good candidate for partitioning for several reasons:
* Time-Based Queries: If queries frequently filter or group by date, partitioning by the date column can significantly improve performance by limiting the amount of data scanned.
* Granularity: The date column likely has a granularity that leads to a reasonable number of partitions (not too many and not too few). This balance is important for optimizing both read and write performance.
* Data Skew: Other columns like post_id or user_id might lead to uneven partition sizes (data skew), which can negatively impact performance.
Partitioning by post_time could also be considered, but typically date is preferred due to its more manageable granularity.
:
Delta Lake Documentation on Table Partitioning: Optimizing Layout with Partitioning
質問 # 42
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFramedf. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFramedfhas the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block:
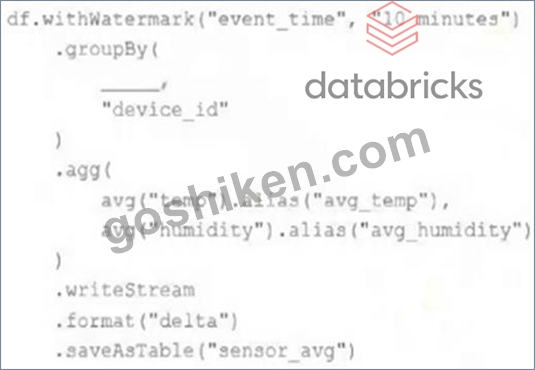
Choose the response that correctly fills in the blank within the code block to complete this task.
- A. to_interval("event_time", "5 minutes").alias("time")
- B. lag("event_time", "10 minutes").alias("time")
- C. window("event_time", "10 minutes").alias("time")
- D. "event_time"
- E. window("event_time", "5 minutes").alias("time")
正解:E
解説:
Explanation
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1second. In this case, the window duration is "5 minutes", which means each window will cover a non-overlapping five-minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window.
The alias function is used to rename the struct column as "time". Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under
"WINDOW" section.
質問 # 43
A user new to Databricks is trying to troubleshoot long execution times for some pipeline logic they are working on. Presently, the user is executing code cell-by-cell, usingdisplay()calls to confirm code is producing the logically correct results as new transformations are added to an operation. To get a measure of average time to execute, the user is running each cell multiple times interactively.
Which of the following adjustments will get a more accurate measure of how code is likely to perform in production?
- A. Calling display () forces a job to trigger, while many transformations will only add to the logical query plan; because of caching, repeated execution of the same logic does not provide meaningful results.
- B. Scala is the only language that can be accurately tested using interactive notebooks; because the best performance is achieved by using Scala code compiled to JARs. all PySpark and Spark SQL logic should be refactored.
- C. Production code development should only be done using an IDE; executing code against a local build of open source Spark and Delta Lake will provide the most accurate benchmarks for how code will perform in production.
- D. The Jobs Ul should be leveraged to occasionally run the notebook as a job and track execution time during incremental code development because Photon can only be enabled on clusters launched for scheduled jobs.
- E. The only way to meaningfully troubleshoot code execution times in development notebooks Is to use production-sized data and production-sized clusters with Run All execution.
正解:A
解説:
This is the correct answer because it explains which of the following adjustments will get a more accurate measure of how code is likely to perform in production. The adjustment is that calling display() forces a job to trigger, while many transformations will only add to the logical query plan; because of caching, repeated execution of the same logic does not provide meaningful results. When developing code in Databricks notebooks, one should be aware of how Spark handles transformations and actions. Transformations are operations that create a new DataFrame or Dataset from an existing one, such as filter, select, or join. Actions are operations that trigger a computation on a DataFrame or Dataset and return a result to the driver program or write it to storage, such as count, show, or save. Calling display() on a DataFrame or Dataset is also an action that triggers a computation and displays the result in a notebook cell. Spark uses lazy evaluation for transformations, which means that they are not executed until an action is called. Spark also uses caching to store intermediate results in memory or disk for faster access in subsequent actions. Therefore, calling display() forces a job to trigger, while many transformations will only add to the logical query plan; because of caching, repeated execution of the same logic does not provide meaningful results. To get a more accurate measure of how code is likely to perform in production, one should avoid calling display() too often or clear the cache before running each cell. Verified References: [Databricks Certified Data Engineer Professional], under "Spark Core" section; Databricks Documentation, under "Lazy evaluation" section; Databricks Documentation, under "Caching" section.
質問 # 44
......
DatabricksのDatabricks-Certified-Professional-Data-Engineer認定試験は業界で広く認証されたIT認定です。世界各地の人々はDatabricksのDatabricks-Certified-Professional-Data-Engineer認定試験が好きです。この認証は自分のキャリアを強化することができ、自分が成功に近づかせますから。DatabricksのDatabricks-Certified-Professional-Data-Engineer試験と言ったら、GoShiken のDatabricksのDatabricks-Certified-Professional-Data-Engineer試験トレーニング資料はずっとほかのサイトを先んじているのは、GoShiken にはIT領域のエリートが組み立てられた強い団体がありますから。その団体はいつでも最新のDatabricks Databricks-Certified-Professional-Data-Engineer試験トレーニング資料を追跡していて、彼らのプロな心を持って、ずっと試験トレーニング資料の研究に力を尽くしています。
Databricks-Certified-Professional-Data-Engineerサンプル問題集: https://www.goshiken.com/Databricks/Databricks-Certified-Professional-Data-Engineer-mondaishu.html
- Databricks-Certified-Professional-Data-Engineer試験問題 🏋 Databricks-Certified-Professional-Data-Engineer真実試験 🌿 Databricks-Certified-Professional-Data-Engineer問題集 🏋 サイト▶ www.xhs1991.com ◀で{ Databricks-Certified-Professional-Data-Engineer }問題集をダウンロードDatabricks-Certified-Professional-Data-Engineer専門試験
- 素敵なDatabricks Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam受験記 - 100% パスレートGoShiken Databricks-Certified-Professional-Data-Engineerサンプル問題集 🆖 ウェブサイト《 www.goshiken.com 》を開き、「 Databricks-Certified-Professional-Data-Engineer 」を検索して無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer日本語版復習指南
- 試験の準備方法-検証するDatabricks-Certified-Professional-Data-Engineer受験記試験-100%合格率のDatabricks-Certified-Professional-Data-Engineerサンプル問題集 👒 ☀ www.passtest.jp ️☀️を入力して{ Databricks-Certified-Professional-Data-Engineer }を検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer専門試験
- Databricks-Certified-Professional-Data-Engineer復習攻略問題 🍀 Databricks-Certified-Professional-Data-Engineer日本語版復習指南 🍥 Databricks-Certified-Professional-Data-Engineer専門試験 📩 最新“ Databricks-Certified-Professional-Data-Engineer ”問題集ファイルは▛ www.goshiken.com ▟にて検索Databricks-Certified-Professional-Data-Engineer問題集
- Databricks-Certified-Professional-Data-Engineer復習攻略問題 ⛹ Databricks-Certified-Professional-Data-Engineer資格模擬 🧷 Databricks-Certified-Professional-Data-Engineer真実試験 🟤 今すぐ➥ www.xhs1991.com 🡄を開き、☀ Databricks-Certified-Professional-Data-Engineer ️☀️を検索して無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer問題集
- Databricks-Certified-Professional-Data-Engineer資格認証攻略 🧒 Databricks-Certified-Professional-Data-Engineer認証資格 ⛲ Databricks-Certified-Professional-Data-Engineer真実試験 🔐 《 www.goshiken.com 》で➠ Databricks-Certified-Professional-Data-Engineer 🠰を検索して、無料で簡単にダウンロードできますDatabricks-Certified-Professional-Data-Engineer資格認証攻略
- 検証するDatabricks-Certified-Professional-Data-Engineer受験記試験-試験の準備方法-一番優秀なDatabricks-Certified-Professional-Data-Engineerサンプル問題集 😟 ➡ www.goshiken.com ️⬅️サイトにて➽ Databricks-Certified-Professional-Data-Engineer 🢪問題集を無料で使おうDatabricks-Certified-Professional-Data-Engineer模擬試験最新版
- Databricks-Certified-Professional-Data-Engineer試験解説 💼 Databricks-Certified-Professional-Data-Engineer問題集 🤖 Databricks-Certified-Professional-Data-Engineer無料模擬試験 🖱 今すぐ⮆ www.goshiken.com ⮄で✔ Databricks-Certified-Professional-Data-Engineer ️✔️を検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer専門試験
- Databricks-Certified-Professional-Data-Engineer試験解説 🧺 Databricks-Certified-Professional-Data-Engineer無料模擬試験 ⏹ Databricks-Certified-Professional-Data-Engineer無料模擬試験 🚪 ➠ www.mogiexam.com 🠰には無料の➡ Databricks-Certified-Professional-Data-Engineer ️⬅️問題集がありますDatabricks-Certified-Professional-Data-Engineer真実試験
- Databricks-Certified-Professional-Data-Engineer試験の準備方法|更新するDatabricks-Certified-Professional-Data-Engineer受験記試験|素敵なDatabricks Certified Professional Data Engineer Examサンプル問題集 ✳ ウェブサイト☀ www.goshiken.com ️☀️から▛ Databricks-Certified-Professional-Data-Engineer ▟を開いて検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer試験対策書
- 試験の準備方法-更新するDatabricks-Certified-Professional-Data-Engineer受験記試験-信頼的なDatabricks-Certified-Professional-Data-Engineerサンプル問題集 🧓 サイト☀ www.passtest.jp ️☀️で⮆ Databricks-Certified-Professional-Data-Engineer ⮄問題集をダウンロードDatabricks-Certified-Professional-Data-Engineer試験問題
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S. GoShikenがGoogle Driveで共有している無料かつ新しいDatabricks-Certified-Professional-Data-Engineerダンプ:https://drive.google.com/open?id=1cmFGcg2exZInBMzqpfAFoq7kmb1gU2fA