Improving your efficiency and saving your time has always been the goal of our Certified-Data-Engineer-Professional preparation exam. If you are willing to try our Certified-Data-Engineer-Professional study materials, we believe you will not regret your choice. With our Certified-Data-Engineer-Professional Practice Engine for 20 to 30 hours, we can claim that you will be quite confident to attend you exam and pass it for sure for we have high pass rate as 98% to 100% which is unmatched in the market.
| Section | Weight | Objectives |
|---|---|---|
| Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures - Use Spark UI, Query Profiler, and system tables |
| Developing Code for Data Processing using Python and SQL | ~22% | - Implement scalable Python/SQL code and project structures - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Manage dependencies, libraries, and UDFs |
| Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics - Implement reliable streaming pipelines |
| Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Data Modeling | ~10% | - Apply dimensional modeling techniques - Design scalable Delta Lake schemas and clustering |
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API - Implement testing and deployment pipelines |
| Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
| Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data - Apply advanced Spark transformations |
>> Latest Certified-Data-Engineer-Professional Exam Price <<
Before you buy our Certified-Data-Engineer-Professional study questions you can have a free download and tryout and you can have an understanding of our product by visiting our pages of our product on the website. The content of our Certified-Data-Engineer-Professional guide torrent is easy to be mastered and has simplified the important information. Our Certified-Data-Engineer-Professional study questions convey more important information with less amount of questions and answers and thus make the learning relaxing and efficient.
NEW QUESTION # 200
A data engineer has created a new cluster using shared access mode with default configurations.
The data engineer needs to allow the development team access to view the driver logs if needed.
What are the minimal cluster permissions that allow the development team to accomplish this?
Answer: C
Explanation:
The CAN VIEW permission on a cluster allows users to see cluster details, including driver and executor logs. This is the minimal permission required for the development team to access logs without granting them the ability to modify, restart, or attach notebooks to the cluster.
NEW QUESTION # 201
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below: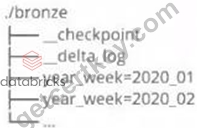
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
Answer: D
Explanation:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss.
NEW QUESTION # 202
A data engineer is attempting to execute the following PySpark code:
df = spark.read.table("sales")
result = df.groupBy("region").agg(sum("revenue"))
However, upon inspecting the execution plan and profiling the Spark job, they observe excessive data shuffling during the aggregation phase.
Which technique should be applied to reduce shuffling during the groupBy aggregation operation?
Answer: C
Explanation:
Repartitioning the DataFrame by the grouping key ensures that records with the same region are colocated in the same partitions before the aggregation runs. This significantly reduces the amount of data shuffled during the groupBy operation, leading to more efficient execution.
NEW QUESTION # 203
A data engineer is building a customer data pipeline in Lakeflow Spark Declarative Pipelines. The source is a cloud-based event stream with limited retention containing inserts, updates, and deletes for customer records. These changes are being applied using the AUTO CDC INTO syntax to maintain an SCD Type 1 table as the target table, customer_dim. How should the data engineer build a downstream job that streams from the customer_dim table to only act on updates and delete events, processing data incrementally?
Answer: D
Explanation:
Reading the change data feed from the customer_dim table enables downstream processing to react specifically to update and delete events while operating incrementally. Change data feed exposes row-level change types and versions, making it the correct mechanism for streaming only the relevant changes from an SCD Type 1 table maintained with AUTO CDC INTO.
NEW QUESTION # 204
Incorporating unit tests into a PySpark application requires upfront attention to the design of your jobs, or a potentially significant refactoring of existing code.
Which statement describes a main benefit that offset this additional effort?
Answer: D
NEW QUESTION # 205
......
Getcertkey provide you with the comprehensive Databricks Certified-Data-Engineer-Professional Exam information to help you to succeed. Our training materials are the latest study materials which bring by experts. We help you achieve your success. You can get the most detailed and accurate exam questions and answers from us. Our Training Tools are updated in a timely manner in accordance with the changing of Exam Objectives. In fact, the success is not far away, go down along with Getcertkey, then you will come to the road to success.
Certified-Data-Engineer-Professional Reliable Test Cost: https://www.getcertkey.com/Certified-Data-Engineer-Professional_braindumps.html