P.S. Free 2026 Microsoft AI-300 dumps are available on Google Drive shared by Pass4cram: https://drive.google.com/open?id=1XEaK7ZqF6kCFTXP2Sxd_gK5UxEaKwDyP
We provide you with free update for 365 days for AI-300 study guide after purchasing, and the update version will be sent to your email automatically, you just need to check your email for the update version. In addition, we have a professional team to compile and review AI-300 exam materials, therefore the quality can be guaranteed, and you can use them at ease. AI-300 Exam Materials cover most of the knowledge points for the exam, and you can master the major knowledge points for the exam as well as improve your professional ability in the process of learning.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
| Topic 2: Implement machine learning model lifecycle and operations | 25–30% | - Monitor and maintain models in production
|
| Topic 3: Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Topic 4: Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Topic 5: Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
>> AI-300 Latest Dumps Questions <<
Pass4cram gives a guarantee to our customers that they can pass the Microsoft AI-300 Certification Exam on the first try by preparing from the Pass4cram and if they fail to pass it despite their efforts they can claim their payment back as per terms and conditions. Pass4cram facilitates customers with a 24/7 support system which means whenever they get stuck somewhere they don't struggle and contact the support system which will assist them in the right way. A lot of students have prepared from practice material and rated it positively.
NEW QUESTION # 157
-
You have an Azure Machine Learning workspace and a collection of image files stored in two Azure Blob Storage accounts.
You need to configure data asset properties.
Which values should you use in your configuration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.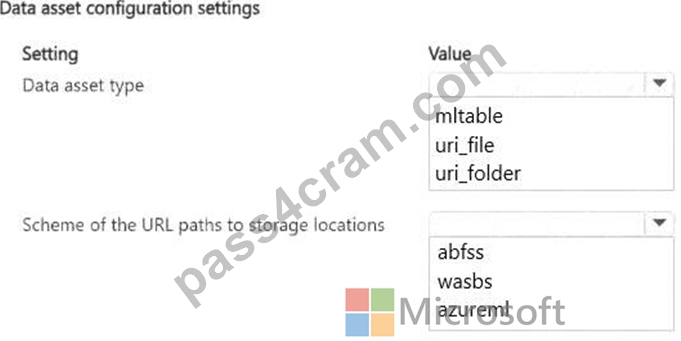
Answer:
Explanation: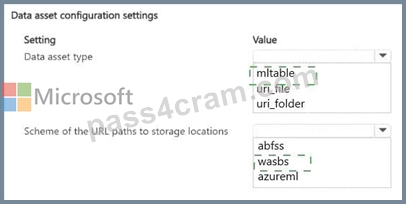
Explanation:
Data asset type: mltable
Scheme of the URL paths to storage locations: wasbs
The correct data asset type is mltable because the image collection is distributed across multiple storage locations . Microsoft identifies MLTable as the appropriate Azure Machine Learning data asset type when unstructured data such as images, text, or audio is spread across multiple storage locations. An MLTable definition can contain multiple file, folder, or pattern entries, allowing one logical data asset to reference image data residing in different storage accounts.
A uri_folder data asset is appropriate when the required unstructured files reside within a single folder path .
It represents one folder location and therefore does not provide the same multi-path abstraction required by this scenario. uri_file represents only an individual file and is clearly unsuitable for a collection of images.
For the path scheme, Azure Machine Learning uses wasbs:// for Azure Blob Storage. Microsoft documents the canonical format as:
wasbs:// < container > @ < account > .blob.core.windows.net/ < path >
By comparison, abfss:// is used for Azure Data Lake Storage Gen2, while azureml:// identifies Azure Machine Learning datastore paths rather than direct Azure Blob Storage URLs.
Therefore, an MLTable containing multiple wasbs:// paths correctly represents image files distributed across the two Azure Blob Storage accounts.
Study Guide Reference: Design and implement an MLOps infrastructure - Azure Machine Learning data assets, MLTable, multi-location datasets, storage URI schemes, and Blob Storage integration.
NEW QUESTION # 158
A team deploys a generative AI application that uses a model deployed in Microsoft Foundry.
The application must support latency monitoring under production load.
You need to enable performance observability.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.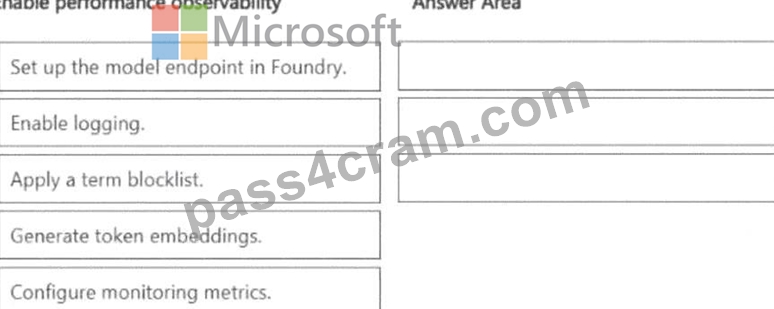
Answer:
Explanation: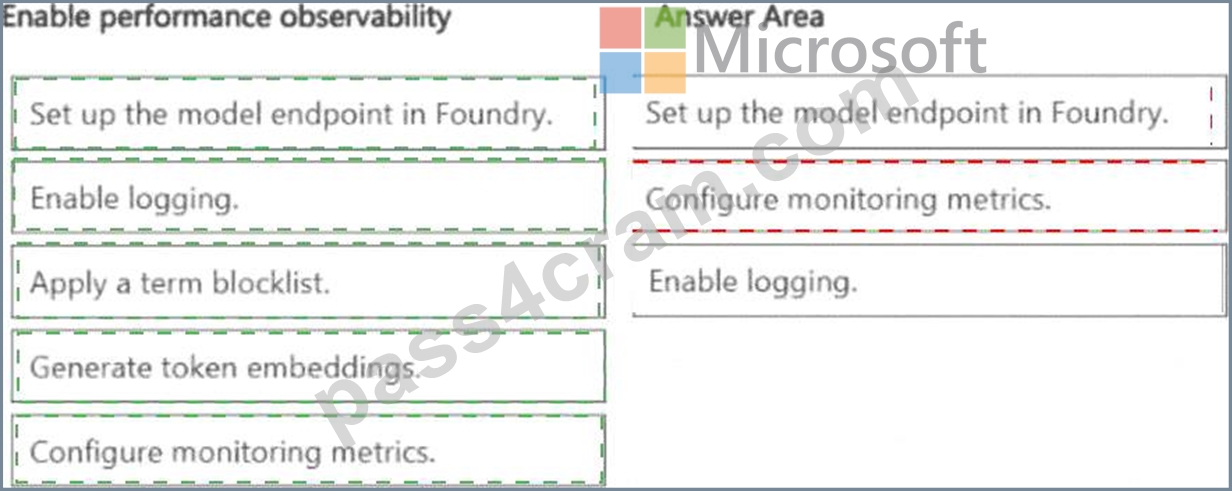
Explanation:
Microsoft ' s observability guidance for Azure AI Foundry applications describes a three-stage activation sequence. First, enable Tracing in the Microsoft Foundry project settings before deployment - Tracing instruments the application ' s LLM calls with OpenTelemetry-compatible spans that capture timing data for each step in the flow. Second, deploy the application to a production endpoint so that real traffic flows through the instrumented code path - without actual production traffic, there is no latency data to observe.
Third, configure Azure Monitor and Application Insights to receive, aggregate, and visualize the telemetry emitted by Tracing. Azure Monitor ' s metrics explorer and Application Insights ' performance views display p50, p95, and p99 latency distributions over time, enabling the team to identify latency regressions and set alert thresholds. This sequence - instrument, deploy, visualize - is the canonical Microsoft path to production AI performance observability.
Microsoft Learn Reference Topic: Monitor generative AI applications with Azure Monitor and Microsoft Foundry Tracing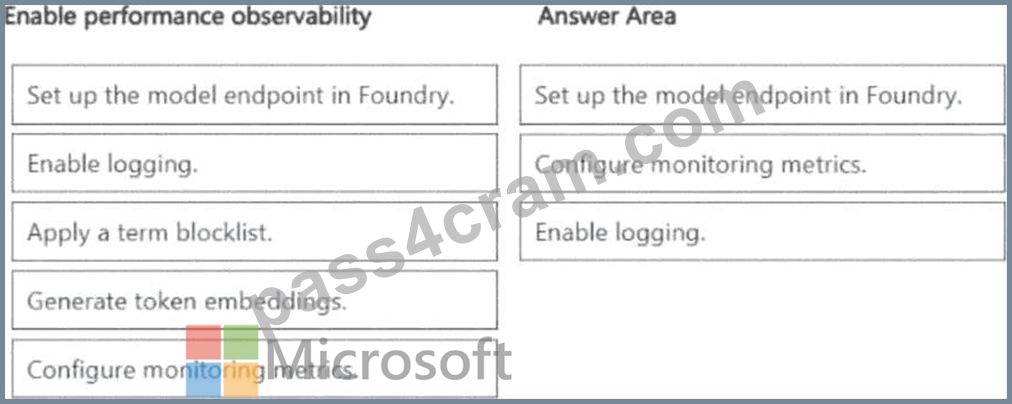
NEW QUESTION # 159
A team is building a Retrieval-Augmented Generation (RAG) system.
The team observes that the retrieved documents are often irrelevant or incomplete.
You need to improve retrieval accuracy.
What should you adjust?
Answer: B
Explanation:
Chunk size and overlap directly affect the precision and completeness of information retrieved in a RAG architecture. Microsoft identifies effective chunking as a critical part of successful RAG implementation. If chunks are too large, they can contain excessive unrelated information, reducing retrieval precision because the vector representation covers multiple concepts. Conversely, chunks that are too small can omit necessary surrounding context or separate related information across chunk boundaries, resulting in incomplete retrieval.
Overlap helps preserve semantic continuity between adjacent chunks. Microsoft recommends using overlap particularly with fixed-size chunking because relevant facts or concepts can span chunk boundaries. The optimal chunk size and overlap should therefore be evaluated against representative documents and queries rather than treated as fixed constants. Microsoft specifically notes that larger chunks can preserve contextual richness, while appropriately configured overlap prevents contextual information from being lost at segmentation boundaries.
Temperature controls generation variability , not document retrieval. Token limits constrain how much content a model processes but do not inherently make retrieval more relevant. Embedding strategy can also influence retrieval quality, but given the stated symptom of irrelevant or incomplete retrieved passages , tuning chunk size and overlap is the directly targeted remediation.
Study Guide Reference: Optimize generative AI systems and model performance - RAG optimization, document chunking, retrieval precision, contextual completeness, and grounding.
NEW QUESTION # 160
Hotspot Question
You use Azure Machine Learning to implement hyperparameter tuning with a Bandit early termination policy for an Azure ML Python SDK v2-based model training.
The policy uses a slack_factor set to 0.1, an evaluation interval set to 1, and an evaluation delay set to 5.
You need to evaluate the outcome of the early termination policy.
What should you evaluate? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.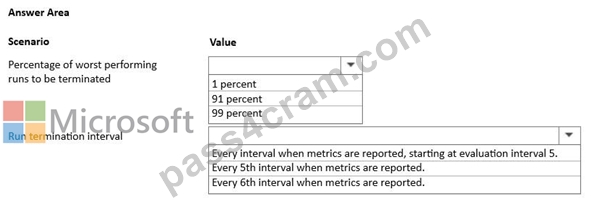
Answer:
Explanation: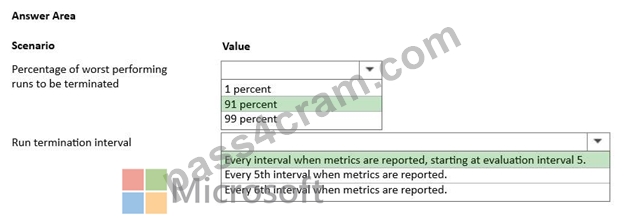
Explanation:
Box 1: 91%
Box 2: Every interval when metrics are reported, starting at evaluation interval 5 Every interval when metrics are reported, starting at evaluation interval 5 is the best description for the run termination schedule in this scenario.
evaluation_interval = 1: The policy checks for potential termination every time the training script logs the primary metric.
evaluation_delay = 5: Policy evaluation is suspended for the first 5 intervals to prevent the premature termination of training runs before they have time to stabilize.
Combined Behavior: Once the evaluation_delay threshold of 5 is met, the policy applies at every subsequent multiple of the evaluation_interval (Intervals 5, 6, 7, etc.).
Reference:
https://azure.github.io/azureml-sdk-for-r/reference/bandit_policy.html
NEW QUESTION # 161
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You work in Microsoft Foundry with a prompt flow.
You must manually evaluate prompts and compare results across prompt variants.
You need to capture the inputs, outputs, token usage, and latencies for each flow run for the evaluation.
Solution: Use the prompt flow SDK to enable tracing for the flow before executing runs. Then run the flow to generate traceable results.
Does the solution meet the goal?
Answer: A
Explanation:
Correct:
* In Microsoft Foundry, turn on Tracing for the prompt flow of the project and execute test runs to produce trace data.
Incorrect:
* Create prompt variants and compare their outputs in the Evaluation experience.
* Use the prompt flow SDK to enable tracing for the flow before executing runs. Then run the flow to generate traceable results.
Note:
In Azure AI Foundry, you can capture and compare these metrics by enabling Tracing and using the Bulk Test feature. This allows you to systematically evaluate different prompt variants against a common dataset.
Steps to Evaluate and Compare Prompt Variants
*-> 1. Enable Tracing
Navigate to your Prompt Flow project.
Locate the Tracing toggle at the top of the flow authoring page.
Switch it to On.
This ensures every execution captures latency, token counts, and node-level inputs/outputs.
2. Create Prompt Variants
Within your flow, identify the LLM node you want to test.
Click Variants to create multiple versions of your prompt (e.g., Variant_0, Variant_1).
This allows you to test different instructions or few-shot examples side-by-side.
3. Run a Bulk Test (Evaluation)
4. Analyze the Results
Reference:
https://www.linkedin.com/pulse/streamlining-generative-ai-development-azure-foundry-tracing- taneja-mbwze
NEW QUESTION # 162
......
The AI-300 certification exam is one of the top-rated career advancement certifications in the market. This AI-300 exam dumps have been inspiring beginners and experienced professionals since its beginning. There are several personal and professional benefits that you can gain after passing the Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam.
AI-300 Intereactive Testing Engine: https://www.pass4cram.com/AI-300_free-download.html
BTW, DOWNLOAD part of Pass4cram AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1XEaK7ZqF6kCFTXP2Sxd_gK5UxEaKwDyP