P.S. It-PassportsがGoogle Driveで共有している無料かつ新しいData-Engineer-Associateダンプ:https://drive.google.com/open?id=1WNiBszUh2CQnoVnr-NshIMd0D4RBsH9j
IT技術の急速な発展につれて、IT認証試験の問題は常に変更されています。したがって、It-PassportsのData-Engineer-Associate問題集も絶えずに更新されています。それに、It-Passportsの教材を購入すれば、It-Passportsは一年間の無料アップデート・サービスを提供してあげます。問題が更新される限り、It-Passportsは直ちに最新版のData-Engineer-Associate資料を送ってあげます。そうすると、あなたがいつでも最新バージョンの資料を持っていることが保証されます。It-Passportsはあなたが試験に合格するのを助けることができるだけでなく、あなたは最新の知識を学ぶのを助けることもできます。このような素晴らしい資料をぜひ見逃さないでください。
| Section | Weight | Objectives |
|---|---|---|
| Data Operations and Support | 22% | - Backup, restore, and disaster recovery - Monitor and troubleshoot data pipelines
- Automate operational tasks |
| Data Store Management | 26% | - Optimize storage performance and cost - Manage data lifecycle and storage tiers - Design and implement data storage solutions
|
| Data Ingestion and Transformation | 34% | - Ingest data from various sources
|
| Data Security and Governance | 18% | - Protect sensitive data - Enforce compliance and data governance
|
>> Data-Engineer-Associate認定資格試験問題集 <<
クライアントの時間を節約するために、Data-Engineer-Associate実践ガイドを購入してから5〜10分後にクライアントに製品をメール形式で送信し、情報を簡素化して学習と学習に数十時間しか必要としないようにします。テストの準備をします。 Data-Engineer-Associateガイド資料の使用過程で発生する問題をクライアントが解決できるように、クライアントはいつでも学習資料に関する問題について相談できます。したがって、当社のData-Engineer-Associateトレーニング資料は人を対象としたものであり、クライアントの経験を重要な地位に置いていると言えます。
質問 # 171
A company receives .csv files that contain physical address data. The data is in columns that have the following names: Door_No, Street_Name, City, and Zip_Code. The company wants to create a single column to store these values in the following format: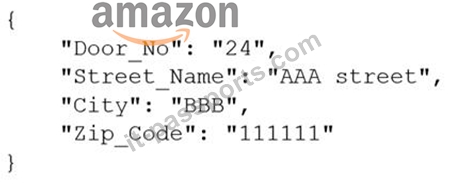
Which solution will meet this requirement with the LEAST coding effort?
正解:C
解説:
The NEST TO MAP transformation allows you to combine multiple columns into a single column that contains a JSON object with key-value pairs. This is the easiest way to achieve the desired format for the physical address data, as you can simply select the columns to nest and specify the keys for each column. The NEST TO ARRAY transformation creates a single column that contains an array of values, which is not the same as the JSON object format. The PIVOT transformation reshapes the data by creating new columns from unique values in a selected column, which is not applicable for this use case. Writing a Lambda function in Python requires more coding effort than using AWS Glue DataBrew, which provides a visual and interactive interface for data transformations. References:
7 most common data preparation transformations in AWS Glue DataBrew (Section: Nesting and unnesting columns) NEST TO MAP - AWS Glue DataBrew (Section: Syntax)
質問 # 172
A company is building a data lake for a new analytics team. The company is using Amazon S3 for storage and Amazon Athena for query analysis. All data that is in Amazon S3 is in Apache Parquet format.
The company is running a new Oracle database as a source system in the company's data center. The company has 70 tables in the Oracle database. All the tables have primary keys. Data can occasionally change in the source system. The company wants to ingest the tables every day into the data lake.
Which solution will meet this requirement with the LEAST effort?
正解:C
解説:
The company needs to ingest tables from an on-premises Oracle database into a data lake on Amazon S3 in Apache Parquet format. The most efficient solution, requiring the least manual effort, would be to use AWS Database Migration Service (DMS) for continuous data replication.
Option C: Create an AWS Database Migration Service (AWS DMS) task for ongoing replication. Set the Oracle database as the source. Set Amazon S3 as the target. Configure the task to write the data in Parquet format.
AWS DMS can continuously replicate data from the Oracle database into Amazon S3, transforming it into Parquet format as it ingests the data. DMS simplifies the process by providing ongoing replication with minimal setup, and it automatically handles the conversion to Parquet format without requiring manual transformations or separate jobs. This option is the least effort solution since it automates both the ingestion and transformation processes.
Other options:
Option A (Apache Sqoop on EMR) involves more manual configuration and management, including setting up EMR clusters and writing Sqoop jobs.
Option B (AWS Glue bookmark job) involves configuring Glue jobs, which adds complexity. While Glue supports data transformations, DMS offers a more seamless solution for database replication.
Option D (RDS and Lambda triggers) introduces unnecessary complexity by involving RDS and Lambda for a task that DMS can handle more efficiently.
Reference:
AWS Database Migration Service (DMS)
DMS S3 Target Documentation
質問 # 173
A company receives a daily file that contains customer data in .xls format. The company stores the file in Amazon S3. The daily file is approximately 2 GB in size.
A data engineer concatenates the column in the file that contains customer first names and the column that contains customer last names. The data engineer needs to determine the number of distinct customers in the file.
Which solution will meet this requirement with the LEAST operational effort?
正解:D
解説:
AWS Glue DataBrew is a visual data preparation tool that allows you to clean, normalize, and transform data without writing code. You can use DataBrew to create recipes that define the steps to apply to your data, such as filtering, renaming, splitting, or aggregating columns. You can also use DataBrew to run jobs that execute the recipes on your data sources, such as Amazon S3, Amazon Redshift, or Amazon Aurora. DataBrew integrates with AWS Glue Data Catalog, which is a centralized metadata repository for your data assets1.
The solution that meets the requirement with the least operational effort is to use AWS Glue DataBrew to create a recipe that uses the COUNT_DISTINCT aggregate function to calculate the number of distinct customers. This solution has the following advantages:
It does not require you to write any code, as DataBrew provides a graphical user interface that lets you explore, transform, and visualize your data. You can use DataBrew to concatenate the columns that contain customer first names and last names, and then use the COUNT_DISTINCT aggregate function to count the number of unique values in the resulting column2.
It does not require you to provision, manage, or scale any servers, clusters, or notebooks, as DataBrew is a fully managed service that handles all the infrastructure for you. DataBrew can automatically scale up or down the compute resources based on the size and complexity of your data and recipes1.
It does not require you to create or update any AWS Glue Data Catalog entries, as DataBrew can automatically create and register the data sources and targets in the Data Catalog. DataBrew can also use the existing Data Catalog entries to access the data in S3 or other sources3.
Option A is incorrect because it suggests creating and running an Apache Spark job in an AWS Glue notebook. This solution has the following disadvantages:
It requires you to write code, as AWS Glue notebooks are interactive development environments that allow you to write, test, and debug Apache Spark code using Python or Scala. You need to use the Spark SQL or the Spark DataFrame API to read the S3 file and calculate the number of distinct customers.
It requires you to provision and manage a development endpoint, which is a serverless Apache Spark environment that you can connect to your notebook. You need to specify the type and number of workers for your development endpoint, and monitor its status and metrics.
It requires you to create or update the AWS Glue Data Catalog entries for the S3 file, either manually or using a crawler. You need to use the Data Catalog as a metadata store for your Spark job, and specify the database and table names in your code.
Option B is incorrect because it suggests creating an AWS Glue crawler to create an AWS Glue Data Catalog of the S3 file, and running SQL queries from Amazon Athena to calculate the number of distinct customers. This solution has the following disadvantages:
It requires you to create and run a crawler, which is a program that connects to your data store, progresses through a prioritized list of classifiers to determine the schema for your data, and then creates metadata tables in the Data Catalog. You need to specify the data store, the IAM role, the schedule, and the output database for your crawler.
It requires you to write SQL queries, as Amazon Athena is a serverless interactive query service that allows you to analyze data in S3 using standard SQL. You need to use Athena to concatenate the columns that contain customer first names and last names, and then use the COUNT(DISTINCT) aggregate function to count the number of unique values in the resulting column.
Option C is incorrect because it suggests creating and running an Apache Spark job in Amazon EMR Serverless to calculate the number of distinct customers. This solution has the following disadvantages:
It requires you to write code, as Amazon EMR Serverless is a service that allows you to run Apache Spark jobs on AWS without provisioning or managing any infrastructure. You need to use the Spark SQL or the Spark DataFrame API to read the S3 file and calculate the number of distinct customers.
It requires you to create and manage an Amazon EMR Serverless cluster, which is a fully managed and scalable Spark environment that runs on AWS Fargate. You need to specify the cluster name, the IAM role, the VPC, and the subnet for your cluster, and monitor its status and metrics.
It requires you to create or update the AWS Glue Data Catalog entries for the S3 file, either manually or using a crawler. You need to use the Data Catalog as a metadata store for your Spark job, and specify the database and table names in your code.
Reference:
1: AWS Glue DataBrew - Features
2: Working with recipes - AWS Glue DataBrew
3: Working with data sources and data targets - AWS Glue DataBrew
[4]: AWS Glue notebooks - AWS Glue
[5]: Development endpoints - AWS Glue
[6]: Populating the AWS Glue Data Catalog - AWS Glue
[7]: Crawlers - AWS Glue
[8]: Amazon Athena - Features
[9]: Amazon EMR Serverless - Features
[10]: Creating an Amazon EMR Serverless cluster - Amazon EMR
[11]: Using the AWS Glue Data Catalog with Amazon EMR Serverless - Amazon EMR
質問 # 174
A transportation company wants to track vehicle movements by capturing geolocation records. The records are 10 bytes in size. The company receives up to 10,000 records every second. Data transmission delays of a few minutes are acceptable because of unreliable network conditions.
The transportation company wants to use Amazon Kinesis Data Streams to ingest the geolocation data. The company needs a reliable mechanism to send data to Kinesis Data Streams. The company needs to maximize the throughput efficiency of the Kinesis shards.
Which solution will meet these requirements in the MOST operationally efficient way?
正解:B
解説:
* Problem Analysis:
* The company ingests geolocation records (10 bytes each) at 10,000 records per second into Kinesis Data Streams.
* Data transmission delays are acceptable, but the solution must maximize throughput efficiency.
* Key Considerations:
* TheKinesis Producer Library (KPL)batches records and uses aggregation to optimize shard throughput.
* Efficiently handles high-throughput scenarios with minimal operational overhead.
* Solution Analysis:
* Option A: Kinesis Agent
* Designed for file-based ingestion; not optimized for geolocation records.
* Option B: KPL
* Aggregates records into larger payloads, significantly improving shard throughput.
* Suitable for applications generating small, high-frequency records.
* Option C: Kinesis Firehose
* Firehose is for delivery to destinations like S3 or Redshift and is not optimized for direct ingestion to Kinesis Data Streams.
* Option D: Kinesis SDK
* The SDK lacks advanced features like aggregation, resulting in lower throughput efficiency.
* Final Recommendation:
* UseKinesis Producer Library (KPL)for its built-in aggregation and batching capabilities.
:
Kinesis Producer Library (KPL) Overview
Best Practices for Amazon Kinesis
質問 # 175
A company processes 500 GB of audience and advertising data daily, storing CSV files in Amazon S3 with schemas registered in AWS Glue Data Catalog. They need to convert these files to Apache Parquet format and store them in an S3 bucket.
The solution requires a long-running workflow with 15 GiB memory capacity to process the data concurrently, followed by a correlation process that begins only after the first two processes complete.
Which solution will meet these requirements with the LEAST operational overhead?
正解:D
解説:
Option C is correct because AWS Glue workflows are designed to orchestrate multiple ETL jobs, crawlers, and triggers with dependency management and a visual workflow graph. AWS documentation states that Glue workflows can create and visualize complex ETL activities involving multiple jobs and triggers, and that triggers can be configured so that a job starts only when multiple watched jobs satisfy specified completion conditions. AWS also states that a conditional trigger can fire when any or all watched jobs complete with the desired status. That directly matches the requirement to run the first two processes concurrently and begin the third process only after both finish.
This is also the least operational overhead option because the whole workflow stays inside AWS Glue, which already fits the ETL conversion use case from CSV to Parquet on S3 with catalog integration. Option A would work but adds MWAA operational complexity. Option B is more custom and infrastructure-heavy.
Option D using Lambda is not ideal for long-running, memory-intensive ETL steps. Therefore, AWS Glue workflows is the most direct and exam-aligned answer.
質問 # 176
......
実際に、多くの受験者はData-Engineer-Associate試験に合格したいです。難しいですが、自分自身はより良いものになりたいので、やはりチャレンジしたいです。そのような場合、Data-Engineer-Associate学習教材のようないい資料が必要です。Data-Engineer-Associate学習教材を利用すれば、あなたはData-Engineer-Associate試験を簡単にパスできます。
Data-Engineer-Associate受験料: https://www.it-passports.com/Data-Engineer-Associate.html
P.S. It-PassportsがGoogle Driveで共有している無料かつ新しいData-Engineer-Associateダンプ:https://drive.google.com/open?id=1WNiBszUh2CQnoVnr-NshIMd0D4RBsH9j