P.S. Free & New DP-750 dumps are available on Google Drive shared by ITdumpsfree: https://drive.google.com/open?id=1KG6psciF5TRtALcKKdCpBrxRLAdYd1pV
We know deeply that a reliable DP-750 exam material is our company's foothold in this competitive market. High accuracy and high quality are the most important things we always looking for. We understand our candidates have no time to waste, everyone wants an efficient learning. So we take this factor into consideration, develop the most efficient way for you to prepare for the DP-750 exam, that is the real questions and answers practice mode, firstly, it simulates the real Implementing Data Engineering Solutions Using Azure Databricks test environment perfectly, which offers greatly help to our customers. Secondly, it includes printable PDF Format, also the instant access to download make sure you can study anywhere and anytime. All in all, high efficiency of DP-750 Exam Material is the reason for your selection.
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
>> Reliable DP-750 Test Testking <<
We will try our best to solve your problems for you. I believe that you will be more inclined to choose a good service product, such as DP-750 learning question. After all, everyone wants to be treated warmly and kindly, and hope to learn in a more pleasant mood. The authoritative, efficient, and thoughtful service of DP-750 learning question will give you the best user experience, and you can also get what you want with our study materials. I hope our study materials can accompany you to pursue your dreams. If you can choose DP-750 test guide, we will be very happy. We look forward to meeting you.
NEW QUESTION # 51
You have an Azure Databricks workspace named Workspace! that uses a Git repository. The repository contains a Databricks notebook named Notebook1.
From the main branch, you create a feature branch named Branch! and commit changes to Notebooks Another user commits changes to Notebook1 in main.
When you attempt to merge Branch! into main, the merge fails due to conflicts.
You need to merge Branch! into the main branch. The solution must ensure that Notebook1 includes all the changes from both the branches.
What should you do?
Answer: D
Explanation:
The correct answer is D - apply the main branch changes to Branch1 and resolve the conflicts.
When a merge fails due to conflicts, the right workflow is to bring main's changes into the feature branch, resolve conflicts there, and then merge the clean feature branch into main. This is the standard Git conflict resolution pattern - resolve in the feature branch, not in main - because it protects the main branch from partial or broken states during resolution.
Option A (clone Branch1 as a new repository) creates a disconnected copy; it doesn't resolve the conflict and breaks the relationship with the remote. Option B (apply changes directly to main) bypasses the feature branch entirely and risks overwriting the other developer's work. Option C (clone main as a new repository) again creates a disconnected copy - none of Branch1's changes would be incorporated, and history would be lost.
Reference: https://learn.microsoft.com/en-us/azure/databricks/repos/git-operations-with-repos
NEW QUESTION # 52
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements.
What should you do?
Answer: A
Explanation:
The correct answer is A. Photon is Azure Databricks ' native vectorized query engine, written in C++, designed to accelerate data ingestion and SQL-heavy workloads significantly over the standard Spark JVM path. Enabling it on a job compute cluster directly addresses Contoso ' s requirement for ' fast and consistent performance for BI workloads ' and ' production ingestion workloads that can scale automatically during telemetry spikes. ' Photon integrates transparently - no code changes are needed - and pairs well with autoscaling job clusters to handle the bursty 40,000-sensor telemetry load.
Option B contradicts the isolation requirement: Contoso explicitly needs production and development separated, not merged onto shared compute. Option C with a fixed large node gives peak capacity at all times, driving up costs even during quiet periods. Option D disabling autoscaling is the opposite of what ' s needed
- telemetry spikes require elastic scaling, not a locked node count.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/photon
NEW QUESTION # 53
You have an Azure Databricks workspace and a remote Git repository named Repo1. Repo1 contains two branches named main and Branch1.
You are on a development team that works in Repo1.
You commit changes to Branch1 and must merge the changes into main.
Before completing the merge, you need to meet the following requirements:
* Ensure that Branch1 includes the changes committed to main since Branch1 was created.
* Ensure that merge conflicts are detected and resolved.
What should you do first?
Answer: D
Explanation:
The latest remote changes from main must first be retrieved so that the development environment has the current main-branch state. After pulling those updates, main can be merged into Branch1, and any conflicts can be detected and resolved before Branch1 is proposed for integration into main. Immediately merging a stale local copy of main into Branch1 could omit commits added remotely after Branch1 was created. Pulling Branch1 only synchronizes the feature branch and does not retrieve the required main-branch changes.
Creating a pull request before updating and testing Branch1 would defer conflict discovery until later in the integration process. Pulling the latest main changes is therefore the correct first operation in the sequence.
Microsoft Learn
NEW QUESTION # 54
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1.
You need to meet the following requirements:
- Records that violate rule1 must NOT be written to Table1, but the
pipeline must continue processing valid records.
- Data engineers must be able to review expectation metrics by using
minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.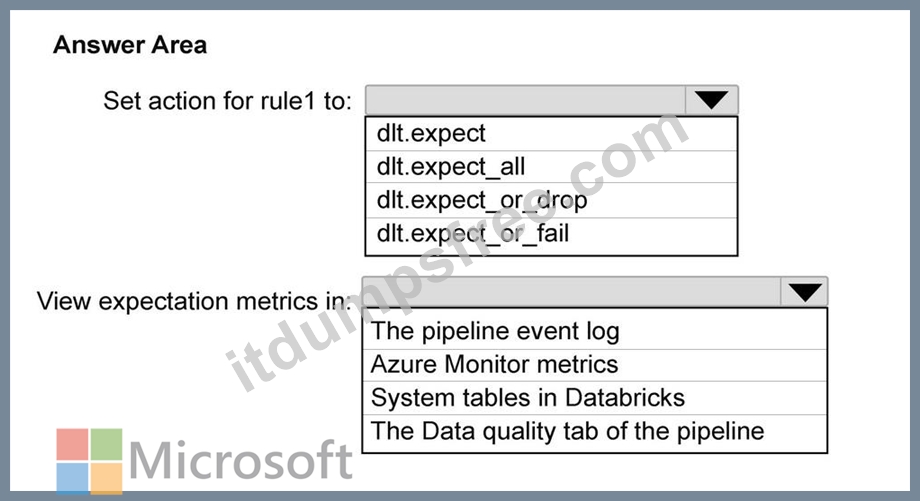
Answer:
Explanation: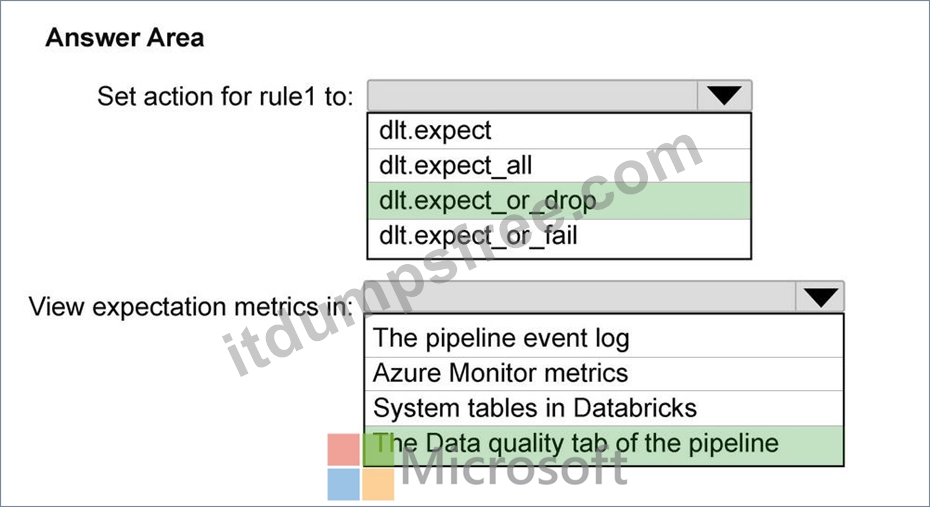
NEW QUESTION # 55
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a Databricks access connector.
Does this meet the goal?
Answer: A
Explanation:
The correct answer is B - No.
A Databricks Access Connector is an Azure resource that provides a managed identity for Databricks to authenticate to Azure Storage services. It is an authentication bridge - nothing more. Creating one doesn't register any external database, doesn't create any Unity Catalog objects representing DB1, and doesn't enable querying of SQL Server data from Databricks.
An Access Connector is a prerequisite for setting up storage credentials and external locations in Unity Catalog (to access ADLS Gen2, for example), but it has no role in Lakehouse Federation or foreign catalog creation. It cannot expose an external database's schemas and tables in Unity Catalog alongside native objects.
The correct solution for this scenario is a foreign catalog (Q47), which requires a connection object pointing to DB1 - not an Access Connector.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/storage-credentials
NEW QUESTION # 56
......
We all know that the importance of the DP-750 certification exam has increased. Many people remain unsuccessful in its DP-750 exam because of using invalid DP-750 practice test material. If you want to avoid failure and loss of money and time, download actual Implementing Data Engineering Solutions Using Azure Databricks (DP-750) Questions of ITdumpsfree. This Microsoft DP-750 exam preparation material is important because it will help you cover each topic and understand it well.
DP-750 Exam Dumps: https://www.itdumpsfree.com/DP-750-exam-passed.html
P.S. Free & New DP-750 dumps are available on Google Drive shared by ITdumpsfree: https://drive.google.com/open?id=1KG6psciF5TRtALcKKdCpBrxRLAdYd1pV