BONUS!!! Download part of Prep4sureExam Databricks-Certified-Data-Analyst-Associate dumps for free: https://drive.google.com/open?id=1cQpT-PRDO_873v8mz4VAT9EiA8VPLk8X
Managing time during the Databricks Databricks-Certified-Data-Analyst-Associate exam is a challenging task. Most candidates cannot manage their time during the Databricks Databricks-Certified-Data-Analyst-Associate exam, leave the questions, and fail. Time management skills can help students gain excellent marks in the Databricks-Certified-Data-Analyst-Associate Exam. Databricks Databricks-Certified-Data-Analyst-Associate practice exam on the software help you identify which kind of Databricks-Certified-Data-Analyst-Associate questions are more time-consuming, and they would be able to assess their efficiency in answering questions.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Data Analyst Associate Exam |
| Exam Number: | Databricks-Certified-Data-Analyst-Associate |
| Exam Duration: | 90 minutes |
| Exam Price: | $200 USD |
| Exam Format: | Multiple Choice |
| Available Languages: | English |
| Related Certifications: | Databricks Certified Machine Learning Associate Databricks Certified Data Engineer Associate |
| Real Exam Qty: | 45 |
| Certificate Validity Period: | 2 years |
| Passing Score: | 70% |
| Sample Questions: | Databricks Databricks-Certified-Data-Analyst-Associate Sample Questions |
| Exam Way: | Online proctored or test center proctored |
| Pre Condition: | No formal prerequisites. Databricks recommends 6+ months of hands-on experience with data analysis and Databricks SQL. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-analyst-associate |
>> Exam Databricks-Certified-Data-Analyst-Associate Collection <<
Databricks-Certified-Data-Analyst-Associate test questions have a mock examination system with a timing function, which provides you with the same examination environment as the real exam. Although some of the hard copy materials contain mock examination papers, they do not have the automatic timekeeping system. Therefore, it is difficult for them to bring the students into a real test state. With Databricks-Certified-Data-Analyst-Associate Exam Guide, you can perform the same computer operations as the real exam, completely taking you into the state of the actual exam, which will help you to predict the problems that may occur during the exam, and let you familiarize yourself with the exam operation in advance and avoid rushing during exams.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 40
A data analyst has a managed table table_name in database database_name. They would now like to remove the table from the database and all of the data files associated with the table. The rest of the tables in the database must continue to exist.
Which of the following commands can the analyst use to complete the task without producing an error?
Answer: B
Explanation:
The DROP TABLE command removes a table from the metastore and deletes the associated data files. The syntax for this command is DROP TABLE [IF EXISTS] [database_name.]table_name;. The optional IF EXISTS clause prevents an error if the table does not exist. The optional database_name. prefix specifies the database where the table resides. If not specified, the current database is used. Therefore, the correct command to remove the table table_name from the database database_name and all of the data files associated with it is DROP TABLE database_name.table_name;. The other commands are either invalid syntax or would produce undesired results. Reference: Databricks - DROP TABLE
NEW QUESTION # 41
Which of the following describes how Databricks SQL should be used in relation to other business intelligence (BI) tools like Tableau, Power BI, and looker?
Answer: A
Explanation:
Databricks SQL is not meant to replace or substitute other BI tools, but rather to complement them by providing a fast and easy way to query, explore, and visualize data on the lakehouse using the built-in SQL editor, visualizations, and dashboards. Databricks SQL also integrates seamlessly with popular BI tools like Tableau, Power BI, and Looker, allowing analysts to use their preferred tools to access data through Databricks clusters and SQL warehouses. Databricks SQL offers low-code and no-code experiences, as well as optimized connectors and serverless compute, to enhance the productivity and performance of BI workloads on the lakehouse. References: Databricks SQL, Connecting Applications and BI Tools to Databricks SQL, Databricks integrations overview, Databricks SQL: Delivering a Production SQL Development Experience on the Lakehouse
NEW QUESTION # 42
A data analysis team is working with the table_bronze SQL table as a source for one of its most complex projects. A stakeholder of the project notices that some of the downstream data is duplicative. The analysis team identifies table_bronze as the source of the duplication.
Which of the following queries can be used to deduplicate the data from table_bronze and write it to a new table table_silver?
A)
CREATE TABLE table_silver AS
SELECT DISTINCT *
FROM table_bronze;
B)
CREATE TABLE table_silver AS
INSERT *
FROM table_bronze;
C)
CREATE TABLE table_silver AS
MERGE DEDUPLICATE *
FROM table_bronze;
D)
INSERT INTO TABLE table_silver
SELECT * FROM table_bronze;
E)
INSERT OVERWRITE TABLE table_silver
SELECT * FROM table_bronze;
Answer: E
Explanation:
Option A uses the SELECT DISTINCT statement to remove duplicate rows from the table_bronze and create a new table table_silver with the deduplicated data. This is the correct way to deduplicate data using Spark SQL12. Option B simply inserts all the rows from table_bronze into table_silver, without removing any duplicates. Option C is not a valid syntax for Spark SQL, as there is no MERGE DEDUPLICATE statement. Option D appends all the rows from table_bronze into table_silver, without removing any duplicates. Option E overwrites the existing data in table_silver with the data from table_bronze, without removing any duplicates. Reference: Delete Duplicate using SPARK SQL, Spark SQL - How to Remove Duplicate Rows
NEW QUESTION # 43
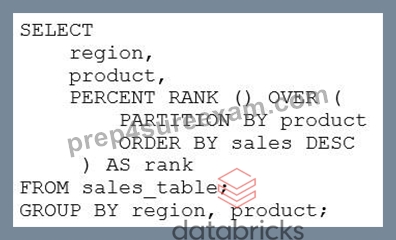
A data analyst has been asked to use the below table sales_table to get the percentage rank of products within region by the sales: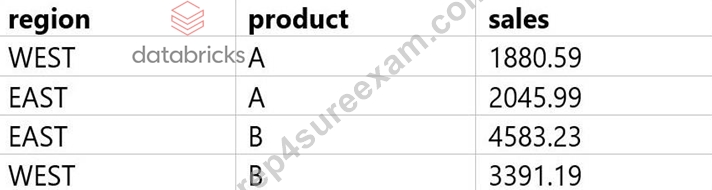
The result of the query should look like this: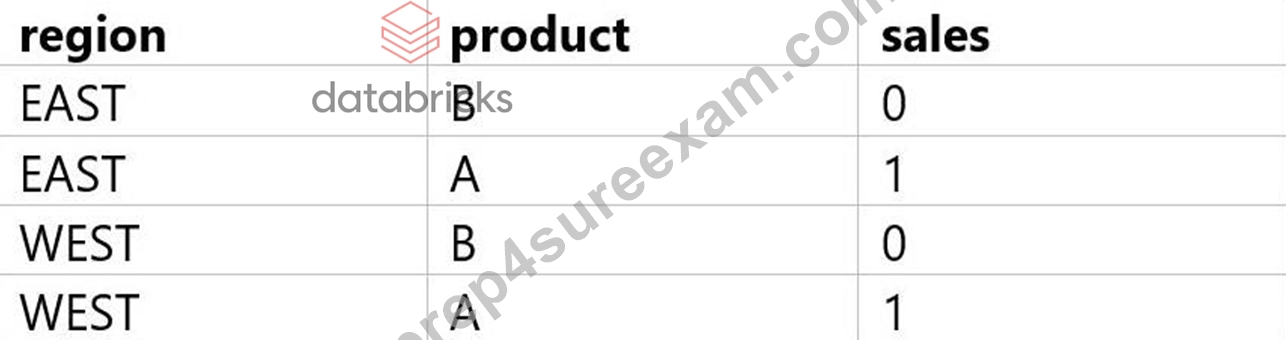
Which of the following queries will accomplish this task?
A)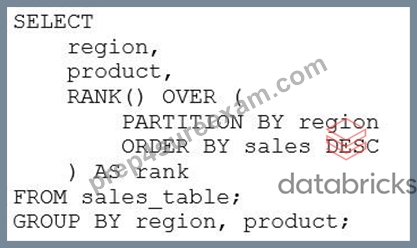
B)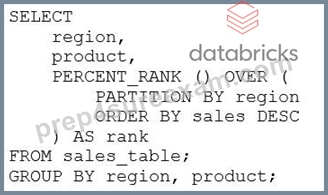
C)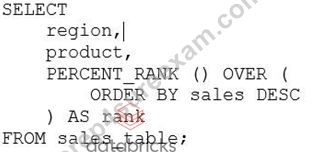
Answer: B
Explanation:
The correct query to get the percentage rank of products within region by the sales is option B. This query uses the PERCENT_RANK() window function to calculate the relative rank of each product within each region based on the sales amount. The window function is partitioned by region and ordered by sales in descending order. The result is aliased as rank and displayed along with the region and product columns. The other options are incorrect because:
A) Option A uses the RANK() window function instead of the PERCENT_RANK() function. The RANK() function returns the rank of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM().
C) Option C uses the DENSE_RANK() window function instead of the PERCENT_RANK() function. The DENSE_RANK() function returns the rank of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM().
D) Option D uses the ROW_NUMBER() window function instead of the PERCENT_RANK() function. The ROW_NUMBER() function returns the sequential number of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM(). Reference:
1: PERCENT_RANK (Transact-SQL)
2: Window functions in Databricks SQL
3: Databricks Certified Data Analyst Associate Exam Guide
NEW QUESTION # 44
A data analyst wants to generate insights from large, complex datasets. The analyst needs to quickly understand the meaning of various data columns, ask questions in natural language, and receive AI-driven recommendations for optimizing data queries and workflows.
Which Databricks component is primarily responsible for enabling these capabilities?
Answer: D
Explanation:
Option A is correct. The Data Intelligence Engine is the platform-level intelligence layer that understands the semantics and uniqueness of an organization's data and enables AI-assisted experiences across Databricks.
Unity Catalog provides governance and metadata management, Genie Spaces provide a natural-language interface for curated business data, and Databricks Assistant is a user-facing assistant for code/query help.
However, the question asks which component is primarily responsible for enabling these capabilities across the platform; that is the Data Intelligence Engine. Databricks describes the platform as powered by a Data Intelligence Engine that understands the uniqueness and semantics of data and helps optimize performance.
References: Databricks Data Intelligence Platform documentation and Data Analyst Associate Exam Guide.
NEW QUESTION # 45
......
Popular Databricks-Certified-Data-Analyst-Associate Exams: https://www.prep4sureexam.com/Databricks-Certified-Data-Analyst-Associate-dumps-torrent.html
DOWNLOAD the newest Prep4sureExam Databricks-Certified-Data-Analyst-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1cQpT-PRDO_873v8mz4VAT9EiA8VPLk8X