DOWNLOAD the newest ActualTorrent DP-800 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1LqcumzPTMiFiCwgbodft231RtREI20W0
If you haplessly fail the DP-800 exam, we treat it as our responsibility then give you full refund and get other version of DP-800 practice material for free. That is why we win a great deal of customers around the world. Especially for those time-sensitive and busy candidates, all three versions of DP-800 Exam Questions can be chosen based on your preference. Such as app version of our DP-800 learning guide, you can learn it using your phone without the limitation of place or time.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Developing AI-Enabled Database Solutions |
| Exam Number: | DP-800 |
| Passing Score: | 700 |
| Exam Format: | Drag and drop, Case studies, Multiple select, Build list, Multiple choice |
| Certificate Validity Period: | 1 year |
| Real Exam Qty: | 40-60 |
| Related Certifications: | Microsoft Certified: SQL AI Developer Associate |
| Available Languages: | Italian, Indonesian (Indonesia), Arabic (Saudi Arabia), Korean, Portuguese (Brazil), Japanese, Chinese (Simplified), Chinese (Traditional), German, Spanish, French, English |
| Exam Price: | $165 USD |
| Exam Duration: | 100 minutes |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or in-person at a testing center |
| Pre Condition: | No specific prerequisites, but candidates should have experience with SQL and a basic understanding of Azure services. Familiarity with AI or machine learning concepts is recommended. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/exams/dp-800/ |
>> Latest DP-800 Dumps Book <<
Many candidates who take the qualifying exams are not aware of our products and are not guided by our systematic guidance, and our users are much superior to them. In similar educational products, the DP-800 quiz guide is absolutely the most practical. Also, from an economic point of view, our Developing AI-Enabled Database Solutions exam dumps is priced reasonable, so the DP-800 test material is very responsive to users, user satisfaction is also leading the same products. So economical and practical learning platform, I believe that will be able to meet the needs of users. Users can deeply depend on our Developing AI-Enabled Database Solutions exam dumps when you want to get a qualification. There may be many problems and difficulties you will face, but believe in our Developing AI-Enabled Database Solutions exam dumps if you want to be the next beneficiary, our DP-800 Quiz guide is not only superior in price than any other makers in the educational field , but also are distinctly superior in the quality of our products.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 20
You have an Azure SQL database named SalesDB that contains a table named dbo. Articles, dbo.Articles contains two million articles with embeddmgs. The articles are updated frequently throughout the day.
You query the embeddings by using VECTOR_SEARQi
Users report that semantic search results do NOT reflect the updates until the following day.
Vou need to ensure that the embeddings are updated whenever the articles change. The solution must minimize CPU usage on SalesDB Which embedding maintenance method should you implement?
Answer: A
Explanation:
The correct answer is B because the problem is not the vector search operator itself. The problem is that embeddings are becoming stale when article content changes . Microsoft documents that change data capture (CDC) tracks insert, update, and delete operations on source tables, which makes it the right mechanism to identify only the rows that changed.
This also best satisfies the requirement to minimize CPU usage on SalesDB . With CDC, the database only records the row changes, and the embedding regeneration work can be moved to an external process such as an Azure Functions app. That avoids running embedding generation inline inside the database for every update and avoids repeatedly recalculating embeddings for unchanged rows. In contrast, an hourly full-table regeneration would be extremely wasteful on a table with two million frequently updated articles, and a trigger that calls embedding generation per row would push expensive AI work into the transactional path of the database.
Option A is incorrect because changing from VECTOR_SEARCH to VECTOR_DISTANCE does not regenerate embeddings; it only changes the retrieval method. Microsoft states that VECTOR_SEARCH is the ANN search function, while VECTOR_DISTANCE performs exact distance calculation, so neither option addresses stale embedding data.
So the right design is:
* use CDC to detect only changed articles,
* process those changes outside the database,
* regenerate embeddings only for changed rows,
* write back the refreshed embeddings for current semantic search results.
NEW QUESTION # 21
Your company has an ecommerce catalog in a Microsoft SQL Server 202b database named SalesDB SalesDB contains a table named products, products contains the following columns:
* product.id (int)
* product_name (nvarchar(200))
* description (nvarchar(max))
* category (nvarchar(50))
* brand (nvarchar(W))
* price (decimal)
* sku (nvarchar(40))
The description fields ate updated dairy by a content pipeline, and price can change multiple times per day.
You want customers to be able to submit natural language queries and apply structured filters for brand and price. You plan to store embeddings in a new VECTOR(1536) column and use VECTOR_SEARCH(...
METRIC=' cosine ' ...).
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.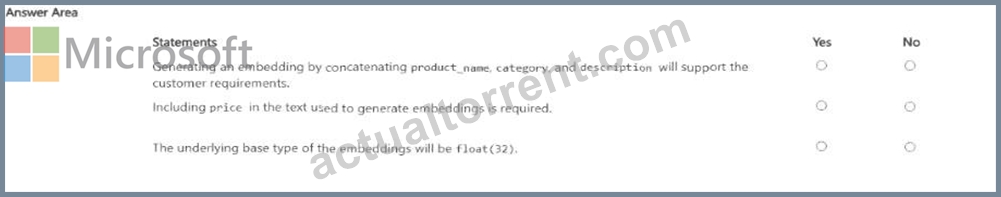
Answer:
Explanation: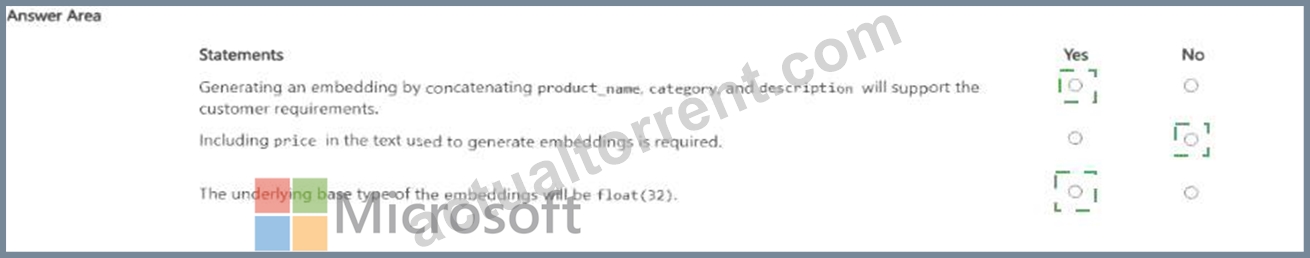
Explanation: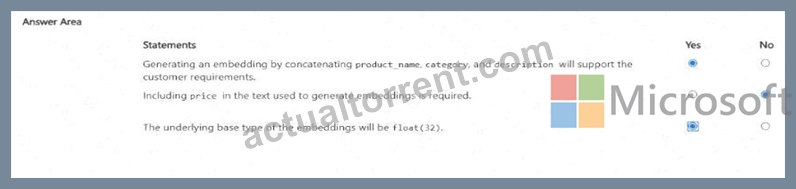
The first statement is Yes . Embeddings are used to represent the semantic meaning of content, and vector search is for conceptually similar matches over that content. Here, the semantically meaningful fields are product_name, category, and description. Using those together supports natural-language search, while brand and price can be handled as structured filters outside the embedding itself. This is an inference from Microsoft's guidance that vector search works over embeddings representing content meaning, while filters remain part of the nonvector query pipeline.
The second statement is No . price changes multiple times per day and is a structured numeric attribute, not stable semantic content. Since the requirement already says customers can apply structured filters for brand and price , price does not need to be embedded into the text. Embedding volatile numeric values would also make embeddings stale faster without improving the semantic-search objective. This is again an inference grounded in Microsoft's distinction between vector similarity over content and filtering/sorting over nonvector fields.
The third statement is Yes . In SQL Server's vector type, the default underlying base type is float32 unless float16 is specified explicitly.
NEW QUESTION # 22
You have a database named DB1. The schema is stored in a Git repository as an SDK-style SQL database project.
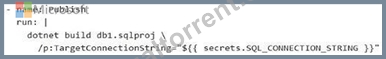
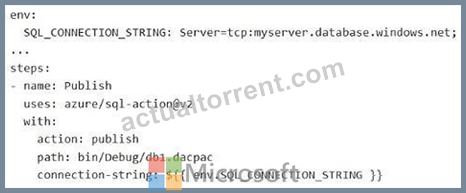
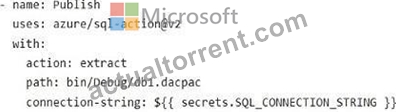
You have a GitHub Actions workflow that already runs dotnet build and produces a database artifact.
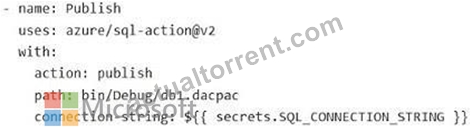
You need to add a deployment step that publishes the .dacpac file to an Azure SQL database by using the secrets stored in GitHub repository secrets.
What should you include in the workflow?
Answer: A
Explanation:
To deploy your .dacpac to Azure SQL using GitHub Actions, you should use the official azure/sql- action@v2. This action is designed specifically to take the output of your dotnet build and publish it.
Assuming your build step is already working, here is how you structure the deployment job.
GitHub Actions Workflow Snippet
Add this job to your .yml file. It depends on your build job (usually named build) and runs on a runner with the Azure CLI installed (like ubuntu-latest).
- name: Deploy SQL Schema
uses: azure/sql-action@v2
with:
connection-string: ${{ secrets.AZURE_SQL_CONNECTION_STRING }}
path: './bin/Release/netstandard2.1/YourDatabase.dacpac' # Path to your .dacpac action: 'publish' Incorrect:
[Not A]
Use connection-string: ${{ secrets.AZURE_SQL_CONNECTION_STRING }}
[Not B]
Action set to publish, not to extract.
[Not D]
Use azure/sql-action@v2.
Reference:
https://stackoverflow.com/questions/75490960/github-actions-dotnet-publish-specify-a-project- with-a-dot-in-the-name
NEW QUESTION # 23
You need to enable similarity search to provide the analysts with the ability to retrieve the most relevant health summary reports. The solution must minimize latency.
What should you include in the solution?
Answer: D
Explanation:
The correct answer is D because the requirement is to enable similarity search over embedding vectors and to minimize latency . Microsoft documents that CREATE VECTOR INDEX is specifically used to create an index on vector data for approximate nearest neighbor (ANN) search , which is designed to accelerate vector similarity queries compared to exact k-nearest-neighbor scans.
This matches the scenario exactly. The VehicleHealthSummary table already includes an Embeddings (vector (1536)) column. In Microsoft SQL platforms, embeddings are stored in vector columns and queried for semantic similarity. To improve performance and reduce response time, Microsoft recommends a vector index , not a regular B-tree nonclustered index and not a full-text index. A vector index is purpose-built for finding the most similar vectors efficiently.
The other options are not appropriate:
* A would require manual comparison logic and would increase latency rather than minimize it.
* B is incorrect because a standard nonclustered index is not the index type used for vector similarity operations.
* C is incorrect because full-text indexes are for textual token-based search, not numeric vector embeddings.
Microsoft's current documentation is explicit that vector indexes support approximate nearest neighbor search , and that the optimizer can use the ANN index automatically for vector queries. That is the exam- aligned design choice when the goal is fast retrieval of the most relevant health summary reports from an embeddings column.
NEW QUESTION # 24
You have an Azure SQL database that contains a table named Customer. Customer contains the following columns:
- NationalIDNumber is unique per customer.
- InvestigationNotes contains free-form text.
You have a stored procedure that performs point lookups by NationalIDNumber and returns InvestigationNotes in the query results without filtering on InvestigationNotes.
You need to encrypt both columns by using Always Encrypted and the highest security possible.
Which type of Always Encrypted encryption should you use for each column?
Answer: A
Explanation:
To achieve the highest security for an Azure SQL Database using Always Encrypted, you must use Randomized Encryption for the InvestigationNotes and Deterministic Encryption for the NationalIDNumber.
While "Randomized" is more secure, it does not support point lookups (equality searches).
Therefore, a hybrid approach is required to maintain functionality while maximizing protection.
Recommended Encryption Settings
* NationalIDNumber
Deterministic is required to allow the Stored Procedure to perform point lookups (WHERE NationalIDNumber = @id).
* InvestigationNotes
Use randomized as it provides the highest security. It prevents pattern matching and "leakage" for sensitive text.
Reference:
https://medium.com/@ih_hira/implementing-always-encrypted-with-azure-key-vault-and-entity- framework-core-in-azure-sql-part-1-3a0e5fd7ed9b
NEW QUESTION # 25
......
DP-800 Exam Questions Pdf: https://www.actualtorrent.com/DP-800-questions-answers.html
BTW, DOWNLOAD part of ActualTorrent DP-800 dumps from Cloud Storage: https://drive.google.com/open?id=1LqcumzPTMiFiCwgbodft231RtREI20W0