Constantly updated multiple mock exams with a great number of questions that will help you in better self-assessment. Memorize all your previous Designing and Implementing Multi-Agent AI Solutions (AI-500) exam questions attempts and display all the changes in your results at the end of each Microsoft AI-500 Practice Exam attempt. Users will be able to customize the AI-500 practice test software by time or question types. Supported on all Windows-based PCs.
| Section | Weight | Objectives |
|---|---|---|
| Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Develop multi-agent solutions in Azure | 30-35% | - Implement agent memory, context management, and knowledge integration
|
| Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Implement observability and monitoring
|
| Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement guardrails
|
We never boost on the achievements of our AI-500 exam questions. There is no single version of level that is suitable for all exam candidates. Because we are all individual creature has unique requirement. But our AI-500 training materials are considerate for your preference and convenience. After many years of review, experts boiled their knowledge and experience of the exam down to three versions of AI-500 Training Materials. They are all booming AI-500 guide dump in today's market.
NEW QUESTION # 46
You have a Microsoft Foundry multi-agent customer support solution that retrieves grounding data from a shared vector index. The indexed corpus contains product runbooks in Markdown and support articles in HTML Both document types use a consistent hierarchical markup.
You discover that current fixed-size token chunking creates chunks that cross section boundaries.
You need to recommend a chunking approach for the ingestion pipeline. The solution must preserve existing document structure boundaries and minimize custom chunking code.
What should you recommend?
Answer: D
Explanation:
The corpus already contains reliable document hierarchy in Markdown and HTML, so the ingestion pipeline should preserve those author-defined boundaries rather than infer new ones from token counts or topic shifts.
Format-specific header splitters can divide Markdown by heading levels and HTML by structural headers, producing chunks that align with meaningful sections. This directly solves the current problem of fixed-size token chunks crossing section boundaries and requires less custom logic than building a semantic topic-shift chunker. Recursive character splitting can be configured with structure-aware separators, but it remains a more generic fallback when format-specific structure is already available. Microsoft Azure AI Search guidance recommends exploiting document structure such as headings when chunking. Therefore B is the most direct and maintainable approach. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure AI Search - structure-aware chunking and Markdown indexing
NEW QUESTION # 47
You have a Microsoft Foundry multi-agent solution that includes a orchestrator and agents named Agent1 and Agent2. The solution has the following characteristics:
* The orchestrator routes tasks to both agents.
* The agents invoice Model Context Protocol (MCP)-hosted tools.
* Agent? sends model-generated JSON parameters directly to tool endpoints.
* The agents use a shared managed identity that has contributor access to the resource group that contains the tool-backed Azure resources.
You need to implement a guardrail strategy for tool calls. The solution must meet the following requirements:
* Prevent invalid or out-of-range tool parameters from reaching the tool endpoints.
* Scope each agent ' s permissions to its assigned tools
* Limit Agent? to refund-processing tools only.
* Log tool invocations for audit purposes.
What should you do?
Answer: B
Explanation:
The solution needs deterministic validation before model-generated tool arguments reach MCP endpoints, per- agent authorization boundaries, tool scoping, and audit logging. Validating typed payload schemas at the tool boundary prevents malformed or out-of-range arguments before execution, which is stronger than validating outputs after a tool has already run. Per-agent managed identities and scoped RBAC roles reduce lateral movement and contain the impact of a compromised agent. A per-agent tool-access policy also ensures the refund-focused agent cannot invoke unrelated tools. Finally, Azure Monitor/trace logging provides an auditable record of tool invocations. A2A capability cards describe remote-agent capabilities rather than validate tool arguments. System instructions are not an authorization boundary, and shared Contributor access leaves an excessive blast radius. Option D is therefore the only answer that satisfies all four requirements at enforceable platform boundaries. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: AI-500 Study Guide - tool scopes, permission boundaries, and auditing
NEW QUESTION # 48
You have a Microsoft Foundry agent named Agent1.
You open Agent1 in the playground and update the instructions.
You need to run a full evaluation against the updated instructions. The solution must meet the following requirements:
* Test the changes by using a synthetic dataset.
* Ensure that the changes are available only for the development team that has access to Agent1.
What should you do first?
Answer: B
Explanation:
The instructions changed in the playground, but a full evaluation needs a stable, versioned agent definition.
Saving the changes as a new version creates an immutable snapshot that can be evaluated against a synthetic dataset while remaining inside the project for the development team. Publishing is a later lifecycle action that makes a version available to broader consumers or production endpoints and is not required for a private development evaluation. Previewing exercises the current playground configuration interactively but does not establish the versioned target needed for repeatable evaluation. Creating an evaluation before saving the new version risks evaluating the previous configuration instead of the intended update. Microsoft Foundry ' s development lifecycle separates edit, save/version, evaluate, and publish stages, so A is the correct first action. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry agents - development lifecycle
NEW QUESTION # 49
You need to implement the business rule for claim Approval. Which workflow node should you use?
Answer: B
Explanation:
The business rule requires human review for refunds above the stated threshold before payment can continue.
A workflow therefore needs a user or operator interaction point that pauses progress and obtains an explicit response. In the workflow options provided, Ask a question is the node that introduces that human interaction.
Invoke agent simply delegates work to another agent; it does not itself guarantee human approval. Deliver a message sends information without collecting a decision, and Go to changes control flow without obtaining authorization. Microsoft Agent Framework and Foundry workflow guidance treat human-in-the-loop approval as a first-class orchestration requirement for consequential actions. The decisive requirement is not just to notify a reviewer, but to stop automated progression until the reviewer supplies a decision. Therefore the workflow must include an interactive question/approval step before the refund-processing action can proceed for amounts over the threshold. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Microsoft Agent Framework - Human-in-the-loop workflows
NEW QUESTION # 50
You are validating the outcome of the consultant proposal for the Patient Intake agent.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.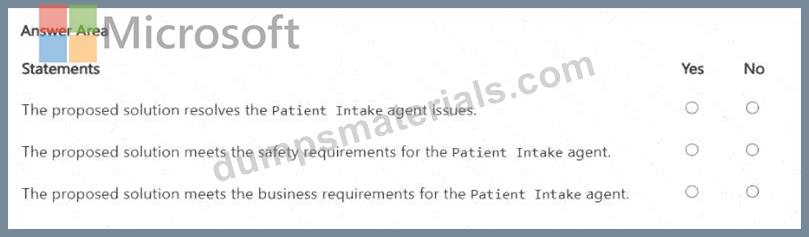
Answer:
Explanation: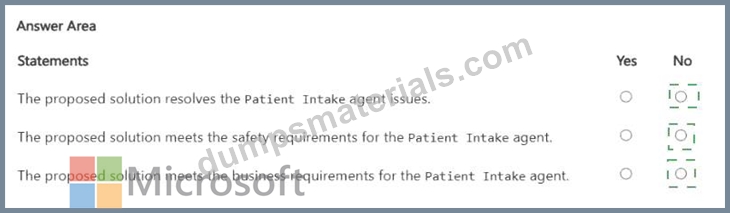
Explanation:
No / No / No
All three consultant-proposal statements should be rejected. Applying the highest sensitivity to every guardrail control is not automatically safer because it can increase false positives and unnecessarily block legitimate clinical interactions; controls should be tuned to the actual risk and tested. Telling the model in a system prompt to ignore hate speech is not equivalent to enabling the platform content-safety controls required for public-facing agents. Finally, repeatedly prompting patients to verify symptoms does not address long-context growth and can worsen token usage and latency. Microsoft guidance separates deterministic safety controls, evaluation, and context-management mechanisms from ordinary prompt instructions. The proposal also hardcodes medical behavior in prompts, contrary to the requirement to avoid embedding new clinical logic in the core prompt. A robust design would use appropriate content-safety/guardrail controls, validated intervention points, and a deliberate memory/compaction strategy rather than relying on increasingly restrictive or repetitive prompt text. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: AI-500 Study Guide - guardrails, context management, and evaluation
NEW QUESTION # 51
......
Our study materials are choosing the key from past materials to finish our AI-500 torrent prep. It only takes you 20 hours to 30 hours to do the practice. After your effective practice, you can master the examination point from the AI-500 Exam Torrent. Then, you will have enough confidence to pass it. So start with our AI-500 torrent prep from now on. We can succeed so long as we make efforts for one thing.
Dump AI-500 Torrent: https://www.dumpsmaterials.com/AI-500-real-torrent.html