我々社のMicrosoft AI-200問題集を使用して試験に合格しないで全額での返金を承諾するのは弊社の商品に不自信ではなく、行為でもって我々の誠意を示します。Microsoft AI-200問題集の専業化であれば、アフタサービスの細心であれば、我々MogiExamはお客様を安心に購買して利用させます。お客様の満足は我々の進む力です。
| Section | Weight | Objectives |
|---|---|---|
| Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
| Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
| Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
| Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
MogiExamソフトウェア教材を練習するのに20〜30時間しかかからず、試験に参加できます。 時間と労力はほとんどかかりません。 AI-200試験問題は習得しやすく、重要な情報の内容を簡素化します。 AI-200テストガイドは、より重要な情報と回答と質問の量を伝えるため、受験者の学習は簡単で非常に効率的です。 そのため、学習者がAI-200ガイドトレントを習得して、短時間でAI-200試験に合格すると便利です。
質問 # 16
You need to ensure that responses from your Azure OpenAI application include citations back to the specific source documents used, to support user trust and verification.
What should you implement?
正解:B
解説:
A retrieval-augmented generation (RAG) architecture is the correct mechanism when generated answers must be traceable to specific source documents. RAG first retrieves relevant document chunks from a search index or other knowledge source, supplies those chunks to the language model as grounding context, and then generates an answer based on that retrieved information. Microsoft specifically documents that RAG enables responses containing citations back to source content .
For reliable citation generation, each retrieved chunk should carry identifying metadata such as a source identifier, document title, section, page, or URL . Microsoft's Azure RAG guidance recommends labeling retrieved chunks and including source metadata with them, then explicitly instructing the model to cite the corresponding sources in its response. This allows users to verify individual claims against the underlying documents.
Modern Azure AI Search agentic retrieval can also return structured references and grounding metadata , specifically designed for citation linking.
Increasing top_p only alters token sampling. Content filtering addresses safety, not provenance. Using a base model without retrieval provides no authoritative document linkage.
Study Guide references: RAG architecture; grounding data; retrieval metadata; Azure AI Search references; prompt engineering for citations.
質問 # 17
A container in an AKS cluster repeatedly restarts.
Pod events show probe failures, although node-level CPU and memory metrics are normal.
You need to diagnose the cause of the repeating restarts.
What should you do first?
正解:B
解説:
The first troubleshooting action should be to inspect the pod events and container logs . Microsoft's AKS troubleshooting guidance identifies Kubernetes events and application logs as primary diagnostic sources when a pod repeatedly restarts or enters states such as CrashLoopBackOff. kubectl describe pod < pod-name
> exposes events including failed liveness or readiness probes, restart reasons, scheduling problems, and container termination information. kubectl logs < pod-name > provides application-level output, while kubectl logs < pod-name > --previous is particularly useful when the container has already restarted because it retrieves logs from the previous terminated container instance.
The scenario already states that node CPU and memory are normal, making node resource pressure less likely.
Probe failures can instead result from incorrect probe paths, ports, timeouts, dependency checks, slow application initialization, or application errors. Microsoft specifically recommends reviewing health probe configuration and application behavior before modifying infrastructure.
Scaling replicas does not identify the root cause. Decreasing initialDelaySeconds can actually make a slow- starting application fail sooner. Draining or rebooting the node is unjustified without evidence of a node-level fault.
Study Guide references: AKS troubleshooting # Kubernetes events, container logs, liveness/readiness probes, kubectl describe, kubectl logs --previous.
質問 # 18
You deploy multiple instances of a change feed processor to handle a high ingestion rate within Azure Cosmos DB for NoSQL.
Each processor instance must process a different subset of partitions.
You need to ensure the workload is load-balanced across all processor instances.
What should you configure?
正解:B
質問 # 19
You are building o back end pipeline that receives Al inference requests. The pipeline must perform the following actions:
* Publish a message so that multiple independent consumers receive it.
* Process massages in order through a single consumer entity.
* isolate any failed messages
You need to configure the appropriate Service Bus entities.
How should you configure the service bus entities? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once..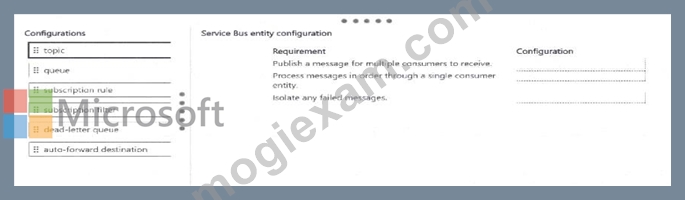
正解:
解説: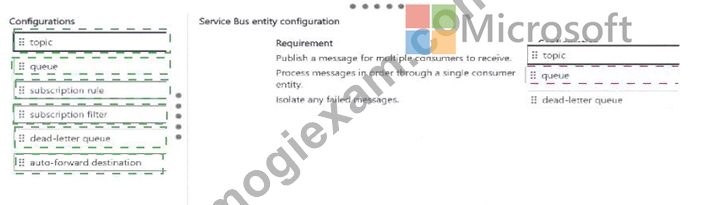
Explanation: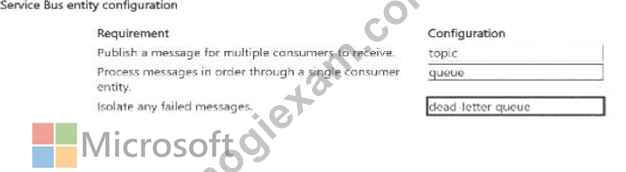
質問 # 20
Drag and Drop Question
You are deploying an Azure Function app that retrieves secrets from Key Vault by using a managed identity.
The deployment must ensure that identity and secret configuration are in place before the function code is deployed.
You need to deploy the function app securely.
In which order should you perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.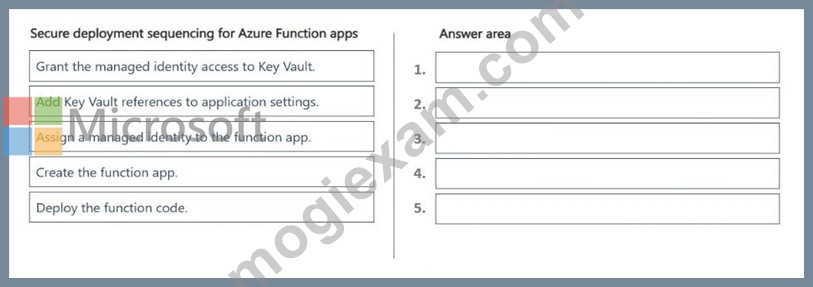
正解:
解説: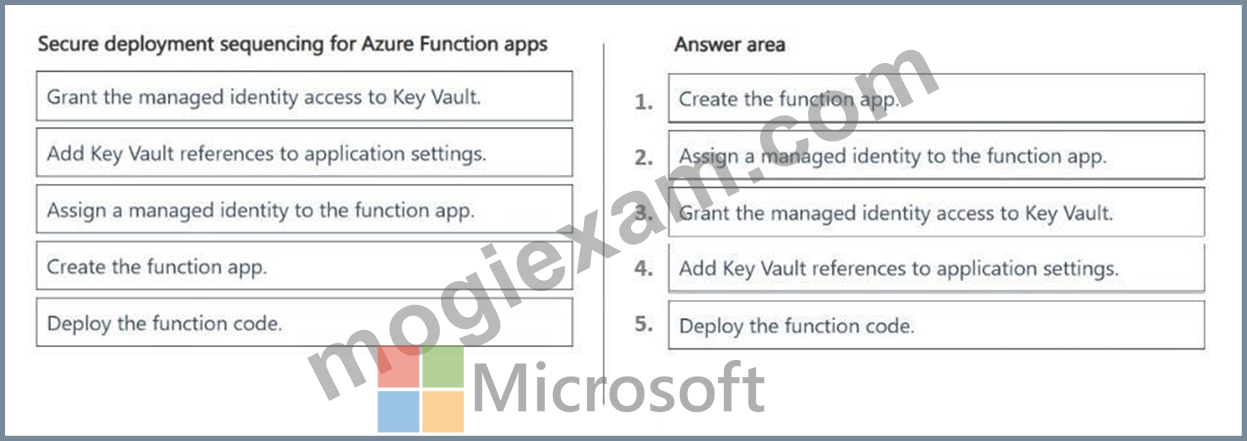
Explanation:
Step 1: Create the function app
You must first provision the underlying Azure Functions infrastructure before you can bind an identity or configuration settings to it.
Step 2: Assign a managed identity to the function app
Turning on the managed identity (such as a system-assigned identity) creates a distinct security principal in Microsoft Entra ID for the resource.
Step 3: Grant access to Key Vault
Use the managed identity's principal ID to create an access policy or RBAC role assignment in Key Vault, allowing the app to read secrets.
Step 4: Add Key Vault references to application settings.
Configure the Function App's application settings to point to the Key Vault secret URIs (@Microsoft.KeyVault(...)), which can now be securely resolved by the identity.
Step 5: Deploy the function code
Finally, deploy the application code. This ensures that when the code initializes and executes, all environment variables and secrets are already active and accessible, preventing application startup failures.
Reference:
https://learn.microsoft.com/en-us/azure/app-service/app-service-key-vault-references
質問 # 21
......
MogiExamの経験豊富な専門家チームはMicrosoftのAI-200認定試験に向かって専門性の問題集を作って、とても受験生に合っています。MogiExamの商品はIT業界中で高品質で低価格で君の試験のために専門に研究したものでございます。
AI-200入門知識: https://www.mogiexam.com/AI-200-exam.html