2026 Latest ITdumpsfree Data-Engineer-Associate PDF Dumps and Data-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1E9aP8kdwfYNWpbkGM3F_dmbBGlmjxX35
Do you want to choose a lifetime of mediocrity or become better and pursue your dreams? I believe you will have your own pursuit. Perhaps you do not know how to go better our Data-Engineer-Associate learning engine will give you some help. The choice is like if a person is at a fork, and which way to go depends on his own decision. Our Data-Engineer-Associate Study Materials have successfully helped a lot of candidates achieve their certifications and become better. Our Data-Engineer-Associate learning guide will be your best choice.
| Section | Weight | Objectives |
|---|---|---|
| Data Security and Governance | 18% | - Ensure data encryption
|
| Data Ingestion and Transformation | 34% | - Apply programming concepts
|
| Data Operations and Support | 22% | - Monitor data pipelines
|
| Data Store Management | 26% | - Understand data cataloging
|
>> Latest Data-Engineer-Associate Dumps Ppt <<
Every Amazon aspirant wants to pass the Amazon Data-Engineer-Associate exam to achieve high-paying jobs and promotions. The biggest issue AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) exam applicants face is that they don't find credible platforms to buy Real Data-Engineer-Associate Exam Dumps. When candidates don't locate actual AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) exam questions they prepare from outdated material and ultimately lose resources.
NEW QUESTION # 196
A company that operates globally must follow regulations that require data from an AWS Region to be accessible only within that Region.
A data engineer is creating a data pipeline that will create resources in the Region where the data engineer works. The data pipeline should have access to data only from the Region where the data engineer works. The pipeline uses Active Directory as an identity and authentication system. The pipeline uses a custom identity broker application to verify that employees are signed in to Active Directory and to obtain temporary credentials by using the AssumeRole API operation.
Which solution will meet the locality requirements with the LEAST administrative effort?
Answer: A
Explanation:
Option A minimizes administration because it keeps one base IAM role for the pipeline and enforces regional locality at session time by attaching a session policy when the broker calls AssumeRole. This aligns with the security best practice of applying only what is necessary, because permissions should be limited to the exact scope required for the session. The material explicitly emphasizes the principle of least privilege, stating that permissions "should apply only to what is necessary," and the most appropriate approach is to grant only the minimum actions needed for the job.
With session policies, the organization avoids creating and maintaining separate per-Region roles (Option B), avoids managing users and group memberships for federated sessions (Option C), and avoids individually attaching policies per engineer (Option D). Instead, the broker can dynamically apply a Region-specific restriction for each login, ensuring the temporary credentials are valid only for the engineer's working Region. This design reduces ongoing operational burden while still enforcing strict locality controls through temporary, scoped credentials and least-privilege boundaries.
NEW QUESTION # 197
A financial company recently added more features to its mobile app. The new features required the company to create a new topic in an existing Amazon Managed Streaming for Apache Kafka (Amazon MSK) cluster.
A few days after the company added the new topic, Amazon CloudWatch raised an alarm on the RootDiskUsed metric for the MSK cluster.
How should the company address the CloudWatch alarm?
Answer: D
Explanation:
TheRootDiskUsedmetric for the MSK cluster indicates that the storage on the broker is reaching its capacity.
The best solution is to expand the storage of the MSK broker and enable automatic storage expansion to prevent future alarms.
* Expand MSK Broker Storage:
* AWS Managed Streaming for Apache Kafka (MSK) allows you toexpand the broker storageto accommodate growing data volumes. Additionally,auto-expansionof storage can be configured to ensure that storage grows automatically as the data increases.
Reference:Amazon MSK Cluster Storage Expansion
Alternatives Considered:
B (Expand Zookeeper storage): Zookeeper is responsible for managing Kafka metadata and not for storing data, so increasing Zookeeper storage won't resolve the root disk issue.
C (Update instance type): Changing the instance type would increase computational resources but not directly address the storage problem.
D (Target-Volume-in-GiB): This parameter is irrelevant for the existing topic and will not solve the storage issue.
References:
Amazon MSK Storage Auto Scaling
NEW QUESTION # 198
A data engineer needs to create an Amazon Athena table based on a subset of data from an existing Athena table named cities_world. The cities_world table contains cities that are located around the world. The data engineer must create a new table named cities_us to contain only the cities from cities_world that are located in the US.
Which SQL statement should the data engineer use to meet this requirement?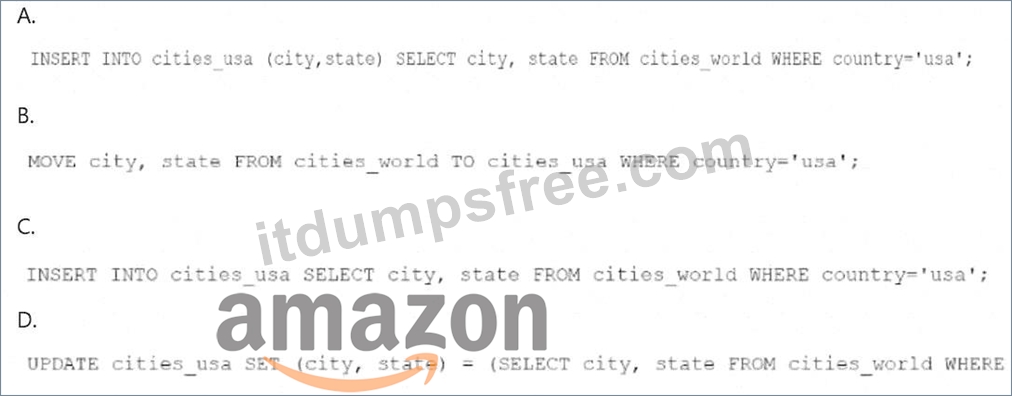
Answer: C
Explanation:
To create a new table named cities_usa in Amazon Athena based on a subset of data from the existing cities_world table, you should use an INSERT INTO statement combined with a SELECT statement to filter only the records where the country is 'usa'. The correct SQL syntax would be:
Option A: INSERT INTO cities_usa (city, state) SELECT city, state FROM cities_world WHERE country='usa';This statement inserts only the cities and states where the country column has a value of 'usa' from the cities_world table into the cities_usa table. This is a correct approach to create a new table with data filtered from an existing table in Athena.
Options B, C, and D are incorrect due to syntax errors or incorrect SQL usage (e.g., the MOVE command or the use of UPDATE in a non-relevant context).
References:
Amazon Athena SQL Reference
Creating Tables in Athena
NEW QUESTION # 199
A company has used an Amazon Redshift table that is named Orders for 6 months. The company performs weekly updates and deletes on the table. The table has an interleaved sort key on a column that contains AWS Regions.
The company wants to reclaim disk space so that the company will not run out of storage space. The company also wants to analyze the sort key column.
Which Amazon Redshift command will meet these requirements?
Answer: A
Explanation:
Amazon Redshift is a fully managed, petabyte-scale data warehouse service that enables fast and cost-effective analysis of large volumes of data. Amazon Redshift uses columnar storage, compression, and zone maps to optimize the storage and performance of data. However, over time, as data is inserted, updated, or deleted, the physical storage of data can become fragmented, resulting in wasted disk space and degraded query performance. To address this issue, Amazon Redshift provides the VACUUM command, which reclaims disk space and resorts rows in either a specified table or all tables in the current schema1.
The VACUUM command has four options: FULL, DELETE ONLY, SORT ONLY, and REINDEX. The option that best meets the requirements of the question is VACUUM REINDEX, which re-sorts the rows in a table that has an interleaved sort key and rewritesthe table to a new location on disk. An interleaved sort key is a type of sort key that gives equal weight to each column in the sort key, and stores the rows in a way that optimizes the performance of queries that filter by multiple columns in the sort key. However, as data is added or changed, the interleaved sort order can become skewed, resulting in suboptimal query performance. The VACUUM REINDEX option restores the optimal interleaved sort order and reclaims disk space by removing deleted rows. This option also analyzes the sort key column and updates the table statistics, which are used by the query optimizer to generate the most efficient query execution plan23.
The other options are not optimal for the following reasons:
A: VACUUM FULL Orders. This option reclaims disk space by removing deleted rows and resorts the entire table. However, this option is not suitable for tables that have an interleaved sort key, as it does not restore the optimal interleaved sort order. Moreover, this option is the most resource-intensive and time-consuming, as it rewrites the entire table to a new location on disk.
B: VACUUM DELETE ONLY Orders. This option reclaims disk space by removing deleted rows, but does not resort the table. This option is not suitable for tables that have any sort key, as it does not improve the query performance by restoring the sort order. Moreover, this option does not analyze the sort key column and update the table statistics.
D: VACUUM SORT ONLY Orders. This option resorts the entire table, but does not reclaim disk space by removing deleted rows. This option is not suitable for tables that have an interleaved sort key, as it does not restore the optimal interleaved sort order. Moreover, this option does not analyze the sort key column and update the table statistics.
References:
1: Amazon Redshift VACUUM
2: Amazon Redshift Interleaved Sorting
3: Amazon Redshift ANALYZE
NEW QUESTION # 200
A company stores datasets in JSON format and .csv format in an Amazon S3 bucket. The company has Amazon RDS for Microsoft SQL Server databases, Amazon DynamoDB tables that are in provisioned capacity mode, and an Amazon Redshift cluster. A data engineering team must develop a solution that will give data scientists the ability to query all data sources by using syntax similar to SQL.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: D
Explanation:
The best solution to meet the requirements of giving data scientists the ability to query all data sources by using syntax similar to SQL with the least operational overhead is to use AWS Glue to crawl the data sources, store metadata in the AWS Glue Data Catalog, use Amazon Athena to query the data, use SQL for structured data sources, and use PartiQL for data that is stored in JSON format.
AWS Glue is a serverless data integration service that makes it easy to prepare, clean, enrich, and move data between data stores1. AWS Glue crawlers are processes that connect to a data store, progress through a prioritized list of classifiers to determine the schema for your data, and then create metadata tables in the Data Catalog2. The Data Catalog is a persistent metadata store that contains table definitions, job definitions, and other control information to help you manage your AWS Glue components3. You can use AWS Glue to crawl the data sources, such as Amazon S3, Amazon RDS for Microsoft SQL Server, and Amazon DynamoDB, and store the metadata in the Data Catalog.
Amazon Athena is a serverless, interactive query service that makes it easy to analyze data directly in Amazon S3 using standard SQL or Python4. Amazon Athena also supports PartiQL, a SQL-compatible query language that lets you query, insert, update, and delete data from semi-structured and nested data, such as JSON. You can use Amazon Athena to query the data from the Data Catalog using SQL for structured data sources, such as .csv files and relational databases, and PartiQL for data that is stored in JSON format. You can also use Athena to query data from other data sources, such as Amazon Redshift, using federated queries.
Using AWS Glue and Amazon Athena to query all data sources by using syntax similar to SQL is the least operational overhead solution, as you do not need to provision, manage, or scale any infrastructure, and you pay only for the resources you use. AWS Glue charges you based on the compute time and the data processed by your crawlers and ETL jobs1. Amazon Athena charges you based on the amount of data scanned by your queries. You can also reduce the cost and improve the performance of your queries by using compression, partitioning, and columnar formats for your data in Amazon S3.
Option B is not the best solution, as using AWS Glue to crawl the data sources, store metadata in the AWS Glue Data Catalog, and use Redshift Spectrum to query the data, would incur more costs and complexity than using Amazon Athena. Redshift Spectrum is a feature of Amazon Redshift, a fully managed data warehouse service, that allows you to query and join data across your data warehouse and your data lake using standard SQL. While Redshift Spectrum is powerful and useful for many data warehousing scenarios, it is not necessary or cost-effective for querying all data sources by using syntax similar to SQL. Redshift Spectrum charges you based on the amount of data scanned by your queries, which is similar to Amazon Athena, but it also requires you to have an Amazon Redshift cluster, which charges you based on the node type, the number of nodes, and the duration of the cluster5. These costs can add up quickly, especially if you have large volumes of data and complex queries. Moreover, using Redshift Spectrum would introduce additional latency and complexity, as you would have to provision and manage the cluster, and create an external schema and database for the data in the Data Catalog, instead of querying it directly from Amazon Athena.
Option C is not the best solution, as using AWS Glue to crawl the data sources, store metadata in the AWS Glue Data Catalog, use AWS Glue jobs to transform data that is in JSON format to Apache Parquet or .csv format, store the transformed data in an S3 bucket, and use Amazon Athena to query the original and transformed data from the S3 bucket, would incur more costs and complexity than using Amazon Athena with PartiQL. AWS Glue jobs are ETL scripts that you can write in Python or Scala to transform your data and load it to your target data store. Apache Parquet is a columnar storage format that can improve the performance of analytical queries by reducing the amount of data that needs to be scanned and providing efficient compression and encoding schemes6. While using AWS Glue jobs and Parquet can improve the performance and reduce the cost of your queries, they would also increase the complexity and the operational overhead of the data pipeline, as you would have to write, run, and monitor the ETL jobs, and store the transformed data in a separate location in Amazon S3. Moreover, using AWS Glue jobs and Parquet would introduce additional latency, as you would have to wait for the ETL jobs to finish before querying the transformed data.
Option D is not the best solution, as using AWS Lake Formation to create a data lake, use Lake Formation jobs to transform the data from all data sources to Apache Parquet format, store the transformed data in an S3 bucket, and use Amazon Athena or Redshift Spectrum to query the data, would incur more costs and complexity than using Amazon Athena with PartiQL. AWS Lake Formation is a service that helps you centrally govern, secure, and globally share data for analytics and machine learning7. Lake Formation jobs are ETL jobs that you can create and run using the Lake Formation console or API. While using Lake Formation and Parquet can improve the performance and reduce the cost of your queries, they would also increase the complexity and the operational overhead of the data pipeline, as you would have to create, run, and monitor the Lake Formation jobs, and store the transformed data in a separate location in Amazon S3. Moreover, using Lake Formation and Parquet would introduce additional latency, as you would have to wait for the Lake Formation jobs to finish before querying the transformed data. Furthermore, using Redshift Spectrum to query the data would also incur the same costs and complexity as mentioned in option B. Reference:
What is Amazon Athena?
Data Catalog and crawlers in AWS Glue
AWS Glue Data Catalog
Columnar Storage Formats
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide
AWS Glue Schema Registry
What is AWS Glue?
Amazon Redshift Serverless
Amazon Redshift provisioned clusters
[Querying external data using Amazon Redshift Spectrum]
[Using stored procedures in Amazon Redshift]
[What is AWS Lambda?]
[PartiQL for Amazon Athena]
[Federated queries in Amazon Athena]
[Amazon Athena pricing]
[Top 10 performance tuning tips for Amazon Athena]
[AWS Glue ETL jobs]
[AWS Lake Formation jobs]
NEW QUESTION # 201
......
Improvement in Data-Engineer-Associate science and technology creates unassailable power in the future construction and progress of society. As we can see, the rapid progression of the whole world is pushing people forward and the competitiveness among people who are fighting on the first line is growing intensely. Numerous advantages of Data-Engineer-Associate training materials are well-recognized, such as 99% pass rate in the exam, free trial before purchasing, secure privacy protection and so forth. From the customers’ point of view, our Data-Engineer-Associate Test Question put all candidates’ demands as the top priority. We treasure every customer’ reliance and feedback to the optimal Data-Engineer-Associate practice test.
Braindumps Data-Engineer-Associate Torrent: https://www.itdumpsfree.com/Data-Engineer-Associate-exam-passed.html
P.S. Free & New Data-Engineer-Associate dumps are available on Google Drive shared by ITdumpsfree: https://drive.google.com/open?id=1E9aP8kdwfYNWpbkGM3F_dmbBGlmjxX35