P.S. ShikenPASSがGoogle Driveで共有している無料かつ新しいdbt-Analytics-Engineeringダンプ:https://drive.google.com/open?id=1u77nnQz5u3BaGRNxCqGfDYlkS4QnrwHX
ShikenPASSは多種なdbt Labs認証試験を受ける方を正確な資料を提供者でございます。弊社の無料なdbt-Analytics-Engineeringサンプルを遠慮なくダウンロードしてください。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Developing dbt Models | 20% | - Model design and structure
|
| Topic 2: Implementing dbt Tests | 10% | - Custom tests - Built-in tests - Test configuration and execution |
| Topic 3: Creating and Maintaining Documentation | 10% | - Documentation standards - Descriptions and metadata - Generating documentation |
| Topic 4: Debugging and Error Resolution | 15% | - Resolving data quality issues - Debugging techniques - Identifying modeling errors |
| Topic 5: Leveraging dbt State | 5% | - State management - State-aware operations |
| Topic 6: dbt Models Governance | 15% | - Naming conventions and standards - Version control integration - Project organization and structure |
| Topic 7: External Dependencies | 10% | - Managing snapshots - Using packages - External sources integration |
| Topic 8: Managing Data Pipelines | 15% | - Pipeline orchestration - CI/CD integration - Deployment strategies |
>> dbt-Analytics-Engineering的中問題集 <<
ShikenPASSは当面最新のdbt Labsのdbt-Analytics-Engineeringの認証試験の準備問題を提供している認証された候補者のリーダーです。弊社の資源はずっと改訂され、アップデートされていますから、緊密な相関関係があります。dbt Labsのdbt-Analytics-Engineeringの認証試験を準備しているあなたは、自分がトレーニングを選んで、しかも次の問題を受かったほうがいいです。弊社の試験問題はほとんど毎月で一回アップデートしますから、あなたは市場で一番新鮮な、しかも依頼できる良い資源を得ることができることを保証いたします。
質問 # 173
You suspect discrepancies in a critical model. To troubleshoot, you need to understand the order of model execution, but the DAG is complex. What would be the BEST strategy to get this information?
正解:C
解説:
While other options provide some information, dbt docs generate creates comprehensive documentation including a visual DAG to show execution flow clearly.
質問 # 174
You accidentally pushed a large file containing sensitive data to a public remote repository. What immediate actions should you take?
正解:C、D
解説:
B: You must ensure the sensitive data is completely removed from the history of the repository. C: The hosting service might have additional security measures or be able to assist in preventing the sensitive data from being accessed
質問 # 175
(Multiple Select)
正解:A、D
解説:
seeds are ideal for static reference data and environment-specific configurations. Large data backfills are usually handled outside of 'seeds'. Generic tests would be defined in the tests section.
質問 # 176 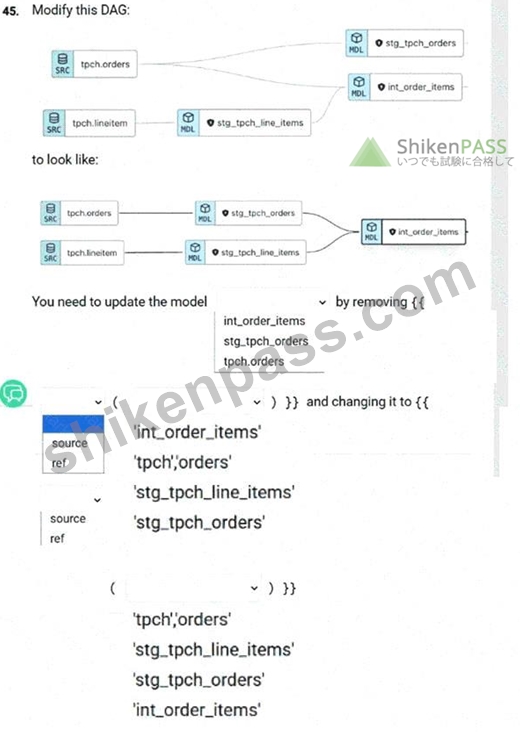
正解:
解説: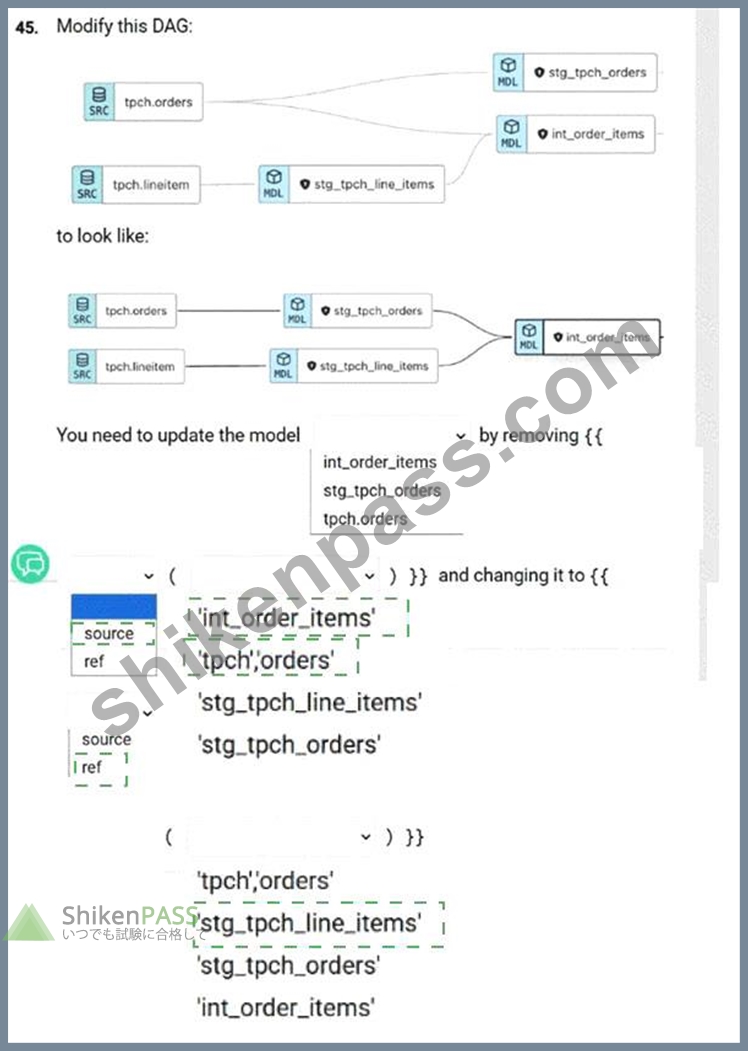
Explanation:
Update int_order_items by replacing:
* {{ source('tpch', 'orders') }} # {{ ref('stg_tpch_orders') }}
* {{ source('tpch', 'lineitem') }} # {{ ref('stg_tpch_line_items') }}
In dbt's recommended modeling pattern, sources should be referenced only in the staging layer. Downstream models (intermediate and mart/fact models) should reference staging models via ref(), not the raw source() directly. This keeps all raw-to-clean logic centralized in the staging layer and makes refactoring and documentation easier.
In the original DAG, int_order_items depends directly on tpch.orders and tpch.lineitem via source(), and staging models also depend on those same sources. That creates parallel paths from the sources and breaks the clean layered architecture.
By updating the int_order_items SQL to use:
from {{ ref('stg_tpch_orders') }}
join {{ ref('stg_tpch_line_items') }} ...
instead of:
from {{ source('tpch', 'orders') }}
join {{ source('tpch', 'lineitem') }} ...
you ensure that int_order_items sits entirely downstream of the staging layer. The new DAG becomes linear: sources # staging # intermediate (int_order_items) # any further marts. This improves modularity, reusability of cleaned logic, and makes the DAG easier to reason about and maintain.
質問 # 177
Which of the following is NOT a direct benefit of thorough source, table, and column descriptions in dbt?
正解:D
解説:
Explanation: While good descriptions have numerous benefits, they don't inherently speed up model compilation and execution within dbt-
質問 # 178
......
dbt-Analytics-Engineering試験はIT業界でのあなたにとって重要です。あなたはdbt-Analytics-Engineering試験に悩んでいますか?試験に合格できないことを心配していますか?我々の提供した一番新しくて全面的なdbt Labsのdbt-Analytics-Engineering問題集はあなたのすべての需要を満たすことができます。資格をもらうのはあなたの発展の第一歩で、我々のdbt-Analytics-Engineering日本語対策はあなたを助けて試験に合格して資格をもらうことができます。
dbt-Analytics-Engineering日本語版と英語版: https://www.shikenpass.com/dbt-Analytics-Engineering-shiken.html
さらに、ShikenPASS dbt-Analytics-Engineeringダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1u77nnQz5u3BaGRNxCqGfDYlkS4QnrwHX