当社Microsoftのソフトウェアバージョンには、実際のAI-300試験環境をシミュレートするという利点があります。 多くの受験者は、練習をするときにパフォーマンスが正しくなりすぎて緊張するため、Jpshiken実際のAI-300試験に合格できません。 AI-300練習資料のこのソフトウェアバージョンは、心理的な恐怖を克服するのに役立ちます。 その上、練習を終えると得点が表示されるので、数回後には間違いなくどんどん良くなります。 AI-300試験の受験を完了したため、Operationalizing Machine Learning and Generative AI Solutions試験に合格する必要があります。
| Section | Weight | Objectives |
|---|---|---|
| Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
| Implement machine learning model lifecycle and operations | 25–30% | - Register, version, and package models
|
短時間で試験に合格して認定資格を取得する場合は、適切なAI-300試験問題を選択することが非常に重要です。 AI-300学習資料にもっと注意を払う必要があります。 。すべてのお客様に適切な学習教材を提供するために、当社の多くの専門家がAI-300トレーニング教材を設計しました。 AI-300試験の質問を購入すると、AI-300試験に合格して認定資格を取得するのが非常に簡単になると約束できます。
質問 # 142
Drag and Drop Question
You build and manage a model by using Azure Machine Learning workspace.
Before you deploy the model, you must create a Responsible AI dashboard in Azure Machine Learning studio. The dashboard must provide observation of the following:
- metrics that show real-world impact on an outcome of interest due to
taking a treatment policy
- examples with minimal changes to a particular data point such that
the model's prediction changes
You need to implement the components for the Responsible AI dashboard.
Which components should you implement? To answer, move the appropriate components to the correct observations. You may use each component once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.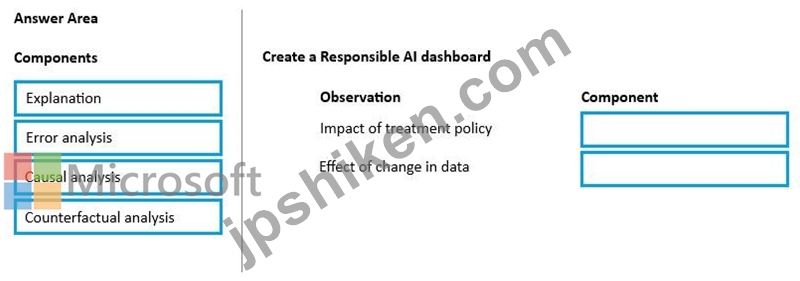
正解:
解説: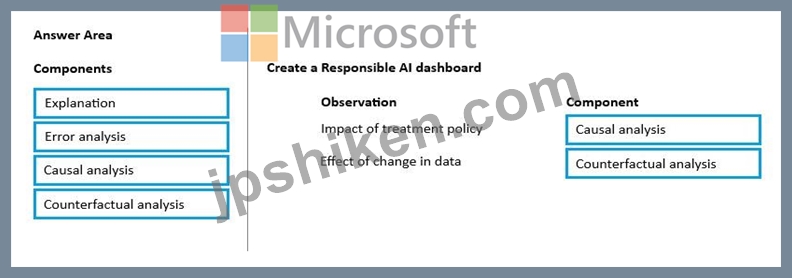
Explanation:
Box 1: Causal analysis
To observe metrics that show the real-world impact on an outcome of interest due to taking a treatment policy, you must implement the Causal analysis component.
Real-World Intervention: Causal analysis specifically uses historical data to evaluate how changing a particular feature (the treatment) directly impacts a real-world outcome.
Policy Making: It generates policy insights by showing which treatment policy is most effective for a specific cohort to optimize your outcome of interest.
Box 2: Counterfactual analysis
You must implement Counterfactual analysis.
The Counterfactual what-if component of the Azure Machine Learning Responsible AI dashboard is designed specifically to "interrogate" a model. It calculates the exact feature tweaks necessary to reverse or modify a specific forecast:
Minimizing Changes: It generates a set of examples demonstrating the smallest possible adjustments to a data point that cause the model's prediction to flip.
Actionable Scenarios: It surfaces the closest data points with opposing or alternative predictions, allowing you to easily test "what-if" scenarios.Why Other Components Do Not Match Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/concept-responsible-ai-dashboard
質問 # 143
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to recommend a solution to address Fabrikam Inc.'s limited rollback capability. Which deployment approach should you recommend?
正解:D
解説:
Scenario:
Current Environment: Deployment is performed manually by data scientists, with limited rollback capability.
The correct deployment type to address this problem is Managed online endpoints with traffic splitting.
Native traffic control: Managed online endpoints naturally support native blue-green deployments under a single HTTP endpoint.
Granular traffic splitting: You can deploy a new model version (e.g., green) with 0% live traffic, safely test it, and then incrementally shift traffic from the old version (e.g., blue).Instant rollbacks:
If the new model shows bugs or degrades performance, you can immediately change the traffic percentage configuration back to 100% for the old deployment. This eliminates the risks of limited rollback capabilities.
No infrastructure overhead: Unlike setting up manual routing, Azure handles the underlying infrastructure and routing mechanisms in a turnkey fashion.
Incorrect:
[Not A]
VM-hosted REST APIs: This forces you to build, maintain, and configure your own custom load balancers and deployment scripts to handle routing and rollbacks, which increases operational risk and complexity.
[Not B]
Azure Kubernetes Service with blue-green switching: While it supports blue-green deployments, it requires you to manage complex Kubernetes infrastructure, service meshes, or ingress controllers manually to handle the traffic switching.
[Not D]
Batch endpoints: These are designed for long-running, asynchronous processing of large data batches rather than real-time requests where instant live-traffic rollback is required.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-safely-rollout-online-endpoints
質問 # 144
You use Azure Machine Learning to train models across multiple experiments by using the same workspace.
You must record training runs in a centralized location to compare results from different jobs.
During training, performance values must be captured so they appear in the experiment run history.
You need to configure experiment tracking.
What should you configure for each requirement? To answer, select the appropriate options in the answer area
. NOTE: Each correct selection is worth one point.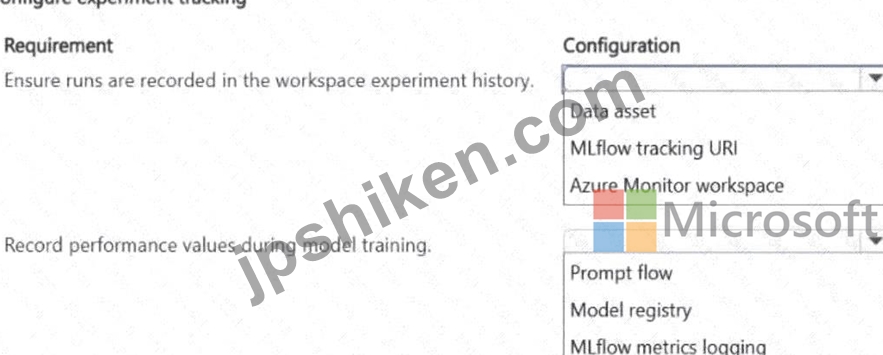
正解:
解説: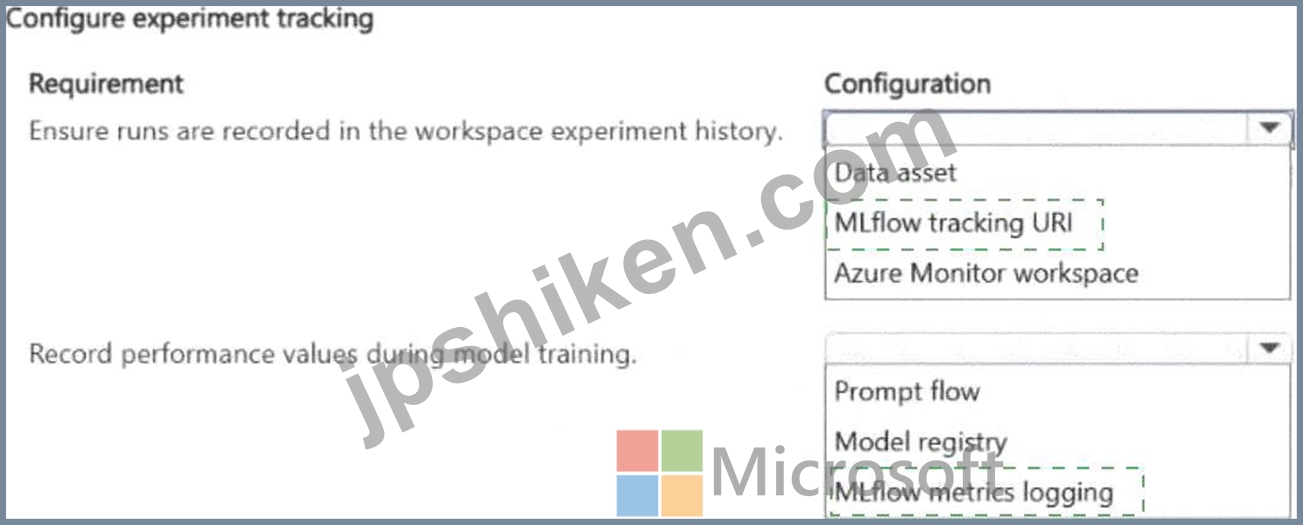
Explanation:
Azure Machine Learning ' s experiment tracking is built around two complementary concepts. First, experiments are named containers that group related runs. By calling mlflow.set_experiment with an experiment name at the start of your training code, all subsequent runs are grouped under that experiment name in the AML workspace, creating the centralized record required. Second, metrics are scalar values such as accuracy, loss, or AUC that represent model performance. Calling mlflow.log_metric with a metric name and value during training persists these values to the run ' s record in the experiment history. These values appear on the Azure ML Studio run detail page and can be compared across runs using the experiment comparison view. Without set_experiment, runs fall into a default experiment. Without log_metric, the run history has no performance data to display or compare.
Microsoft Learn Reference Topic: Track machine learning experiments with MLflow in Azure Machine Learning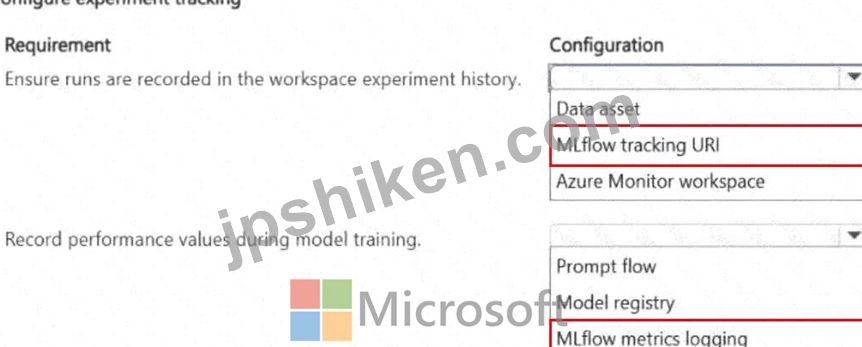
質問 # 145
You manage an Azure Machine Learning workspace. You have a folder that contains a CSV file.
The folder is registered as a folder data asset.
You plan to use the folder data asset for data wrangling during interactive development.
You need to access and load the folder data asset into a Pandas data frame.
Which method should you use to achieve this goal?
正解:A
解説:
Azure Machine Learning supports a Table type (mltable). This allows for the creation of a blueprint that defines how to load data files into memory as a Pandas or Spark data frame.
Authoring MLTable Files
To directly create the MLTable file, we recommend that you use the mltable Python SDK to author your MLTable files instead of a text editor.
Supported file types
You can create an MLTable using a range of different file types:
* Delimited Text
(for example, CSV files)
from_delimited_files(paths=[path])
Incorrect:
* Parquet
from_parquet_files(paths=[path])
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-mltable
質問 # 146
DRAG DROP
A team deploys a classification model to production and scores incoming customer data daily.
After several weeks, business stakeholders report unexpected changes in prediction behavior, even though the endpoint remains healthy.
You need to determine whether data drift is occurring and if it is, identify the appropriate actions.
Which action should you perform for each observed signal? To answer, move the appropriate actions to the correct observed signals. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.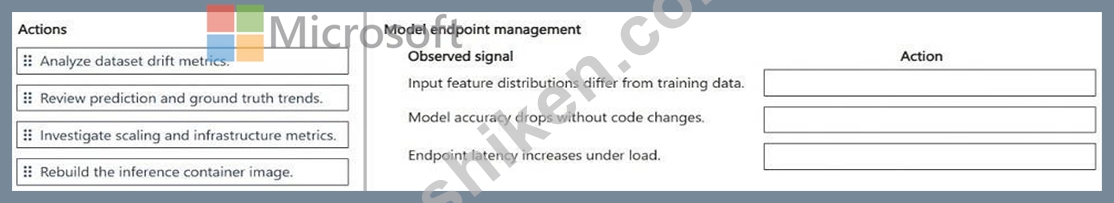
正解:
解説: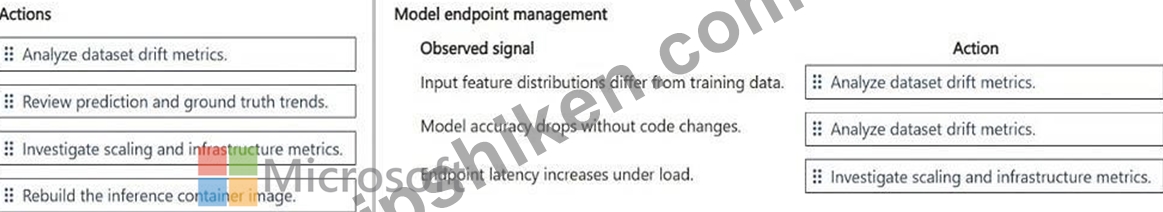
質問 # 147
......
学習資料が時代に遅れないようにしながら、AI-300学習の質問をより専門的にするために多数の専門家を選択しました。もちろん、必要な情報を取得するためにすべてを行っており、より迅速に進めることができます。また、AI-300試験トレーニングプロフェッショナルからいつでもサポートを受けることができます。私たちは、AI-300テストガイドの専門家の助けを借りて、確実に非常に良い経験を得ることを確信できます。優れた材料と方法は、より少ない労力でより多くの成果を上げるのに役立ちます。 AI-300テストガイドを選択して、成功に近づけましょう!
AI-300学習教材: https://www.jpshiken.com/AI-300_shiken.html