P.S. Free & New Databricks-Certified-Data-Engineer-Associate dumps are available on Google Drive shared by Itcertmaster: https://drive.google.com/open?id=1qxsQ9EaKta-ALp89hCUswjt7rDDB0sTM
Our company is committed to the success of our customers. All company tenets are customer-oriented. Our Databricks-Certified-Data-Engineer-Associate practice questions are created with the utmost profession for we are trained for this kind of Databricks-Certified-Data-Engineer-Associate study prep with the experience and knowledge of professionals from leading organizations around the world. Our company Databricks-Certified-Data-Engineer-Associate Exam Quiz is truly original question treasure created by specialist research and amended several times before publication.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Data Engineer Associate Exam |
| Exam Number: | Databricks-Certified-Data-Engineer-Associate |
| Passing Score: | Not publicly disclosed, approximately 70% |
| Real Exam Qty: | 45 |
| Exam Price: | 200 USD |
| Exam Duration: | 90 minutes |
| Available Languages: | Korean, Portuguese (Brazil), English, Japanese |
| Certificate Validity Period: | 2 years |
| Related Certifications: | Databricks Certified Data Engineer Professional Databricks Certified Data Analyst Associate |
| Exam Format: | Multiple choice, Proctored |
| Recommended Training: | Databricks Academy - Data Engineer Associate Learning Path Databricks Documentation |
| Exam Registration: | Official Registration |
| Sample Questions: | Databricks Databricks-Certified-Data-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored or in-person at authorized test centers |
| Pre Condition: | No mandatory prerequisites; 6+ months hands-on experience with Databricks and data engineering tasks recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-engineer-associate |
>> Exam Databricks-Certified-Data-Engineer-Associate Fees <<
Our Databricks Databricks-Certified-Data-Engineer-Associate practice exam also provides users with a feel for what the real Databricks Databricks-Certified-Data-Engineer-Associate exam will be like. Both Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) practice exams are the same as the Actual Databricks-Certified-Data-Engineer-Associate Test and give candidates the experience of taking the real Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam. These Databricks-Certified-Data-Engineer-Associate practice tests can be customized according to your needs.
Databricks Certified Data Engineer Associate certification is ideal for professionals working in data engineering, data warehousing, and data modeling roles. Databricks Certified Data Engineer Associate Exam certification demonstrates the candidate's knowledge of Databricks and their ability to design and implement data engineering solutions using Databricks. It also validates their understanding of data transformation, ETL processes, data warehousing, and data modeling concepts. Databricks Certified Data Engineer Associate Exam certification can enhance the candidate's career opportunities and increase their earning potential.
NEW QUESTION # 278
A data engineer is working with two tables. Each of these tables is displayed below in its entirety.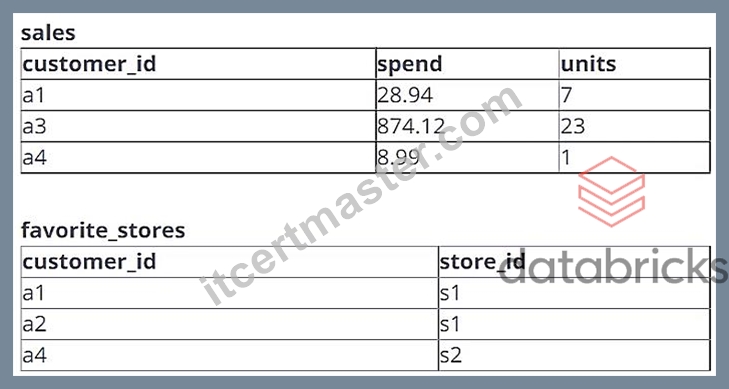
The data engineer runs the following query to join these tables together: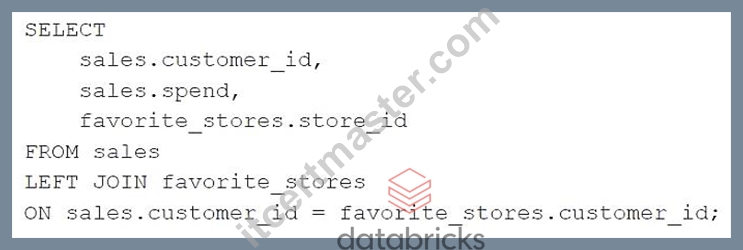
Which of the following will be returned by the above query?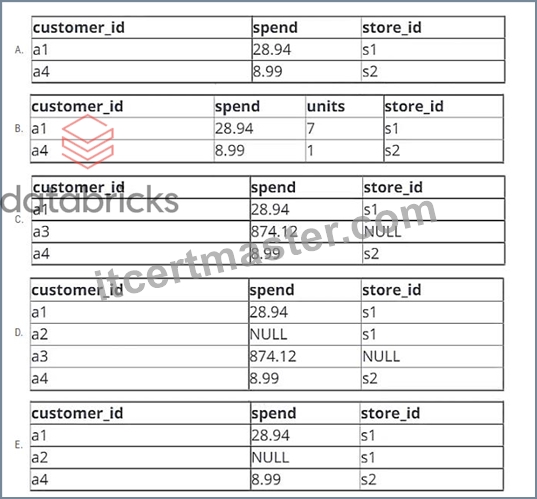
Answer: A
Explanation:
Option A is the correct answer because it shows the result of an INNER JOIN between the two tables. An INNER JOIN returns only the rows that have matching values in both tables based on the join condition. In this case, the join condition is ON a.customer_id = c.customer_id, which means that only the rows that have the same customer ID in both tables will be included in the output. The output will have four columns: customer_id, name, account_id, and overdraft_amt. The output will have four rows, corresponding to the four customers who have accounts in the account table.
The use of INNER JOIN can be referenced from Databricks documentation on SQL JOIN or from other sources like W3Schools or GeeksforGeeks.
NEW QUESTION # 279
An Auto Loader stream fails when a new column appears in incoming JSON files. The team wants the stream to add the new column automatically, restarting as needed, rather than failing permanently.
Which cloudFiles.schemaEvolutionMode setting should be used?
Answer: B
Explanation:
addNewColumns is the default mode when a schema location is provided: the stream fails on encountering an unknown column, updates the stored schema, and on restart processes data with the evolved schema. rescue keeps the schema fixed and places unexpected fields in the rescued data column, while none and failOnNewColumns do not evolve the schema.
NEW QUESTION # 280
A data engineer needs to persist a DataFrame to disk instead of memory because the dataset is too large to fit in memory. Which Spark persistence level supports disk storage?
Answer: B
NEW QUESTION # 281
A data engineer is attempting to drop a Spark SQL table my_table and runs the following command:
DROP TABLE IF EXISTS my_table;
After running this command, the engineer notices that the data files and metadata files have been deleted from the file system.
Which of the following describes why all of these files were deleted?
Answer: B
Explanation:
The reason why all of the data files and metadata files were deleted from the file system after dropping the table is that the table was managed. A managed table is a table that is created and managed by Spark SQL. It stores both the data and the metadata in the default location specified by the spark.sql.warehouse.dir configuration property. When a managed table is dropped, both the data and the metadata are deleted from the file system.
Option B is not correct, as the size of the table's data does not affect the behavior of dropping the table.
Whether the table's data is smaller or larger than 10 GB, the data files and metadata files will be deleted if the table is managed, and will be preserved if the table is external.
Option C is not correct, for the same reason as option B.
Option D is not correct, as an external table is a table that is created and managed by the user. It stores the data in a user-specified location, and only stores the metadata in the Spark SQL catalog. When an external table is dropped, only the metadata is deleted from the catalog, but the data files are preserved in the file system.
Option E is not correct, as a table must have a location to store the data. If the location is not specified by the user, it will use the default location for managed tables. Therefore, a table without a location is a managed table, and dropping it will delete both the data and the metadata.
References:
* Managing Tables
* [Databricks Data Engineer Professional Exam Guide]
NEW QUESTION # 282
The Delta transaction log for the 'students' tables is shown using the 'DESCRIBE HISTORY students' command. A Data Engineer needs to query the table as it existed before the UPDATE operation listed in the log.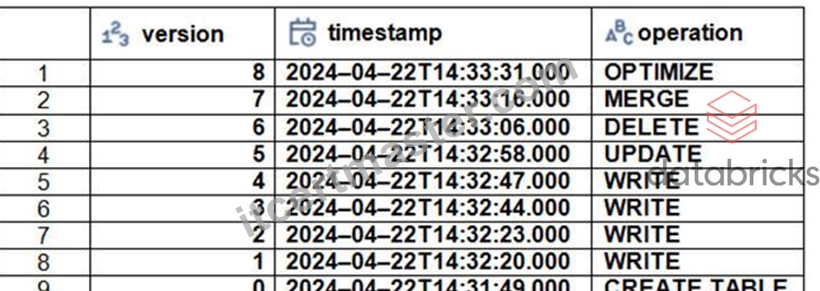
Which command should the Data Engineer use to achieve this? (Choose two.)
Answer: B,C
NEW QUESTION # 283
......
Databricks-Certified-Data-Engineer-Associate Dumps Free Download: https://www.itcertmaster.com/Databricks-Certified-Data-Engineer-Associate.html
BONUS!!! Download part of Itcertmaster Databricks-Certified-Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1qxsQ9EaKta-ALp89hCUswjt7rDDB0sTM