What's more, part of that ExamTorrent Databricks-Generative-AI-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1P0XTjOE7bqKumLN3yP43jUaGJUg0mqPY
Because these Databricks Certified Generative AI Engineer Associate Databricks-Generative-AI-Engineer-Associate exam dumps are designed by experts after in-depth research about the certification exam content. The Databricks Certified Generative AI Engineer Associate exam product is made of 100% real Databricks Databricks-Generative-AI-Engineer-Associate Exam Questions verified by Databricks professionals. The Databricks Certified Generative AI Engineer Associate Databricks-Generative-AI-Engineer-Associate Valid Dumps of ExamTorrent are exceptionally curated and approved by experts. We have hired professionals who after in-depth research add the most important and real test questions in three formats of our Databricks-Generative-AI-Engineer-Associate exam practice material.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate Exam |
| Exam Number: | Databricks-Generative-AI-Engineer-Associate |
| Available Languages: | English, Japanese, Brazilian Portuguese, Korean |
| Real Exam Qty: | 45 |
| Exam Price: | USD 200 |
| Exam Format: | Multiple choice |
| Exam Duration: | 90 minutes |
| Certificate Validity Period: | 2 years |
| Passing Score: | 700/1000 or 70% |
| Recommended Training: | Generative AI Engineering with Databricks |
| Exam Registration: | Databricks Certification Registration |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored or in-person test center |
| Pre Condition: | No formal prerequisites; recommended 6+ months hands-on experience building generative AI solutions |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/genai-engineer-associate |
>> Databricks Databricks-Generative-AI-Engineer-Associate 100% Accuracy <<
By seeing your goofs you can work on your show continually for the Databricks Databricks-Generative-AI-Engineer-Associate approach. You can give vast phony tests to make them ideal for Databricks Databricks-Generative-AI-Engineer-Associate and can check their past given exams. Databricks Databricks-Generative-AI-Engineer-Associate Dumps will give reliable free updates to our clients generally all the Databricks Certified Generative AI Engineer Associate.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 26
A Generative Al Engineer at an automotive company would like to build a question-answering chatbot for customers to inquire about their vehicles. They have a database containing various documents of different vehicle makes, their hardware parts, and common maintenance information.
Which of the following components will NOT be useful in building such a chatbot?
Answer: B
Explanation:
The task involves building a question-answering chatbot for an automotive company using a database of vehicle-related documents. The chatbot must efficiently process customer inquiries and provide accurate responses. Let's evaluate each component to determine which isnotuseful, per Databricks Generative AI Engineer principles.
* Option A: Response-generating LLM
* An LLM is essential for generating natural language responses to customer queries based on retrieved information. This is a core component of any chatbot.
* Databricks Reference:"The response-generating LLM processes retrieved context to produce coherent answers"("Building LLM Applications with Databricks," 2023).
* Option B: Invite users to submit long, rather than concise, questions
* Encouraging long questions is a user interaction design choice, not a technical component of the chatbot's architecture. Moreover, long, verbose questions can complicate intent detection and retrieval, reducing efficiency and accuracy-counter to best practices for chatbot design. Concise questions are typically preferred for clarity and performance.
* Databricks Reference: While not explicitly stated, Databricks' "Generative AI Cookbook" emphasizes efficient query processing, implying that simpler, focused inputs improve LLM performance. Inviting long questions doesn't align with this.
* Option C: Vector database
* A vector database stores embeddings of the vehicle documents, enabling fast retrieval of relevant information via semantic search. This is critical for a question-answering system with a large document corpus.
* Databricks Reference:"Vector databases enable scalable retrieval of context from large datasets"("Databricks Generative AI Engineer Guide").
* Option D: Embedding model
* An embedding model converts text (documents and queries) into vector representations for similarity search. It's a foundational component for retrieval-augmented generation (RAG) in chatbots.
* Databricks Reference:"Embedding models transform text into vectors, facilitating efficient matching of queries to documents"("Building LLM-Powered Applications").
Conclusion: Option B is not a usefulcomponentin building the chatbot. It's a user-facing suggestion rather than a technical building block, and it could even degrade performance by introducing unnecessary complexity. Options A, C, and D are all integral to a Databricks-aligned chatbot architecture.
NEW QUESTION # 27
A Generative AI Engineer is developing a chatbot designed to assist users with insurance-related queries. The chatbot is built on a large language model (LLM) and is conversational. However, to maintain the chatbot's focus and to comply with company policy, it must not provide responses to questions about politics. Instead, when presented with political inquiries, the chatbot should respond with a standard message:
"Sorry, I cannot answer that. I am a chatbot that can only answer questions around insurance." Which framework type should be implemented to solve this?
Answer: D
Explanation:
In this scenario, the chatbot must avoid answering political questions and instead provide a standard message for such inquiries. Implementing aSafety Guardrailis the appropriate solution for this:
* What is a Safety Guardrail?Safety guardrails are mechanisms implemented in Generative AI systems to ensure the model behaves within specific bounds. In this case, it ensures the chatbot does not answer politically sensitive or irrelevant questions, which aligns with the business rules.
* Preventing Responses to Political Questions:The Safety Guardrail is programmed to detect specific types of inquiries (like political questions) and prevent the model from generating responses outside its intended domain. When such queries are detected, the guardrail intervenes and provides a pre-defined response: "Sorry, I cannot answer that. I am a chatbot that can only answer questions around insurance."
* How It Works in Practice:The LLM system can include aclassification layeror trigger rules based on specific keywords related to politics. When such terms are detected, the Safety Guardrail blocks the normal generation flow and responds with the fixed message.
* Why Other Options Are Less Suitable:
* B (Security Guardrail): This is more focused on protecting the system from security vulnerabilities or data breaches, not controlling the conversational focus.
* C (Contextual Guardrail): While context guardrails can limit responses based on context, safety guardrails are specifically about ensuring the chatbot stays within a safe conversational scope.
* D (Compliance Guardrail): Compliance guardrails are often related to legal and regulatory adherence, which is not directly relevant here.
Therefore, aSafety Guardrailis the right framework to ensure the chatbot only answers insurance-related queries and avoids political discussions.
NEW QUESTION # 28
A Generative AI Engineer is designing a RAG application for answering user questions on technical regulations as they learn a new sport.
What are the steps needed to build this RAG application and deploy it?
Answer: C
Explanation:
The Generative AI Engineer needs to follow a methodical pipeline to build and deploy a Retrieval- Augmented Generation (RAG) application. The steps outlined in option B accurately reflect this process:
* Ingest documents from a source : This is the first step, where the engineer collects documents (e.g., technical regulations) that will be used for retrieval when the application answers user questions.
* Index the documents and save to Vector Search : Once the documents are ingested, they need to be embedded using a technique like embeddings (e.g., with a pre-trained model like BERT) and stored in a vector database (such as Pinecone or FAISS). This enables fast retrieval based on user queries.
* User submits queries against an LLM : Users interact with the application by submitting their queries. These queries will be passed to the LLM.
* LLM retrieves relevant documents : The LLM works with the vector store to retrieve the most relevant documents based on their vector representations.
* LLM generates a response : Using the retrieved documents, the LLM generates a response that is tailored to the user ' s question.
* Evaluate model : After generating responses, the system must be evaluated to ensure the retrieved documents are relevant and the generated response is accurate. Metrics such as accuracy, relevance, and user satisfaction can be used for evaluation.
* Deploy it using Model Serving : Once the RAG pipeline is ready and evaluated, it is deployed using a model-serving platform such as Databricks Model Serving. This enables real-time inference and response generation for users.
By following these steps, the Generative AI Engineer ensures that the RAG application is both efficient and effective for the task of answering technical regulation questions.
NEW QUESTION # 29
Which TWO chain components are required for building a basic LLM-enabled chat application that includes conversational capabilities, knowledge retrieval, and contextual memory?
Answer: B,C
Explanation:
Building a basic LLM-enabled chat application with conversational capabilities, knowledge retrieval, and contextual memory requires specific components that work together to process queries, maintain context, and retrieve relevant information. Databricks' Generative AI Engineer documentation outlines key components for such systems, particularly in the context of frameworks like LangChain or Databricks' MosaicML integrations. Let's evaluate the required components:
* Understanding the Requirements :
* Conversational capabilities : The app must generate natural, coherent responses.
* Knowledge retrieval : It must access external or domain-specific knowledge.
* Contextual memory : It must remember prior interactions in the conversation.
* Databricks Reference: " A typical LLM chat application includes a memory component to track conversation history and a retrieval mechanism to incorporate external knowledge " ( " Databricks Generative AI Cookbook, " 2023).
* Evaluating the Options :
* A. (Q) : This appears incomplete or unclear (possibly a typo). Without further context, it's not a valid component.
* B. Vector Stores : These store embeddings of documents or knowledge bases, enabling semantic search and retrieval of relevant information for the LLM. This is critical for knowledge retrieval in a chat application.
* Databricks Reference : " Vector stores, such as those integrated with Databricks' Lakehouse, enable efficient retrieval of contextual data for LLMs " ( " Building LLM Applications with Databricks " ).
* C. Conversation Buffer Memory : This component stores the conversation history, allowing the LLM to maintain context across multiple turns. It's essential for contextual memory.
* Databricks Reference : " Conversation Buffer Memory tracks prior user inputs and LLM outputs, ensuring context-aware responses " ( " Generative AI Engineer Guide " ).
* D. External tools : These (e.g., APIs or calculators) enhance functionality but aren't required for a basic chat app with the specified capabilities.
* E. Chat loaders : These might refer to data loaders for chat logs, but they're not a core chain component for conversational functionality or memory.
* F. React Components : These relate to front-end UI development, not the LLM chain's backend functionality.
* Selecting the Two Required Components :
* For knowledge retrieval , Vector Stores (B) are necessary to fetch relevant external data, a cornerstone of Databricks' RAG-based chat systems.
* For contextual memory , Conversation Buffer Memory (C) is required to maintain conversation history, ensuring coherent and context-aware responses.
* While an LLM itself is implied as the core generator, the question asks for chain components beyond the model, making B and C the minimal yet sufficient pair for a basic application.
Conclusion : The two required chain components are B. Vector Stores and C. Conversation Buffer Memory
, as they directly address knowledge retrieval and contextual memory, respectively, aligning with Databricks' documented best practices for LLM-enabled chat applications.
NEW QUESTION # 30
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.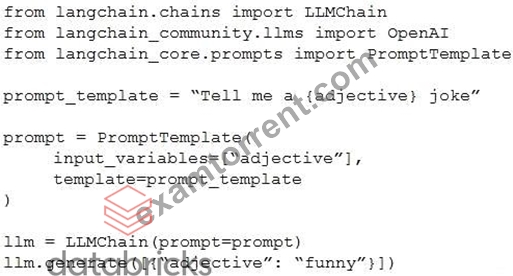
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
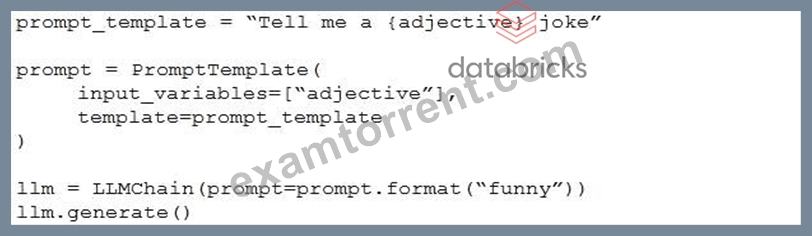
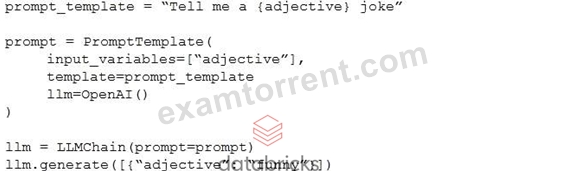
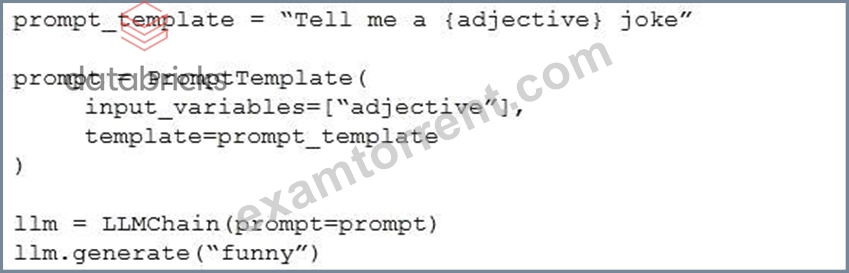
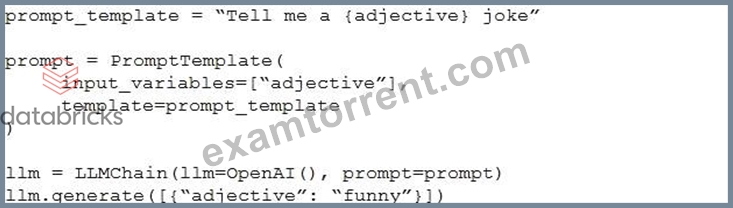
Answer: B
Explanation:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods:
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
* Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
* Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 31
......
Exam Dumps Databricks-Generative-AI-Engineer-Associate Zip: https://www.examtorrent.com/Databricks-Generative-AI-Engineer-Associate-valid-vce-dumps.html
BTW, DOWNLOAD part of ExamTorrent Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1P0XTjOE7bqKumLN3yP43jUaGJUg0mqPY