2026年JPNTestの最新AB-731 PDFダンプおよびAB-731試験エンジンの無料共有:https://drive.google.com/open?id=1knthgcF_khwhDPqu_PMBMjz4UjwtntRl
国際市場のさまざまな国の人々のさまざまな要件に対応するために、このWebサイトで3種類のAB-731準備質問(PDFバージョン、オンラインエンジン、ソフトウェアバージョン)を準備しました。好きなものを選んでください。 3つのバージョンには独自の特性があります。 AB-731トレーニング資料のPDFバージョンは印刷に便利です。ソフトウェアバージョンは模擬テストを提供でき、オンラインバージョンはいつでもどこでも読むことができます。どのバージョンを選択すべきか迷っている場合は、まずAB-731無料デモをダウンロードして、決定する前に直接体験してください。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
MicrosoftのAB-731認証試験のために少ないお金でよい成果を取られるのJPNTestのは最良の選択でございます。JPNTestは例年試験内容を提供したあなたに後悔しないように価値があるサイトだけではなく、無料の一年更新サービスも提供するに最も賢明な選択でございます。
質問 # 74
Your company plans to use generative AI to help project managers and engineers work with construction blueprints stored as PDF files. You need to recommend a generative AI solution that processes both images and text, summarizes building design, answers questions, and extracts information such as locations of electrical, heating, and plumbing systems. What should you recommend?
正解:B
解説:
Construction blueprints in PDFs often contain a mix of text, symbols, linework, and diagrams . The requirements include understanding both visual layout (where systems are located) and textual annotations , producing summaries, and answering Q & A. That combination requires a multimodal generative AI approach-models that can reason over images and text together. Therefore, A is best.
OCR alone (B) can extract printed text, but it won't reliably interpret diagram geometry, symbols, or spatial relationships (e.g., "electrical riser is on the east core near gridline B-4"). Text completion (C) is too generic and doesn't address image understanding. Document summarization (D) is only one requirement (summary) and still depends on first extracting/understanding both visual and textual elements.
A multimodal solution can ingest the PDF pages as images (or rendered page images) plus extracted text, then answer questions grounded in both modalities. In practice, you may combine OCR and layout extraction with a multimodal LLM so the model can reference drawing regions, legends, callouts, and system diagrams to produce accurate explanations and field extractions.
質問 # 75
A marketing team wants to automatically create product descriptions and campaign email drafts.
Which generative AI capability best meets this business need?
正解:A
質問 # 76
Hotspot Question
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.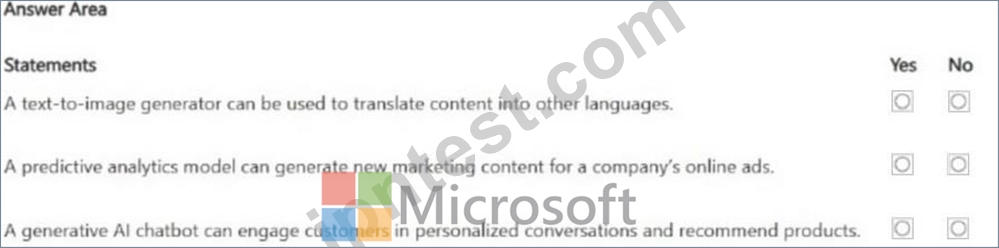
正解:
解説: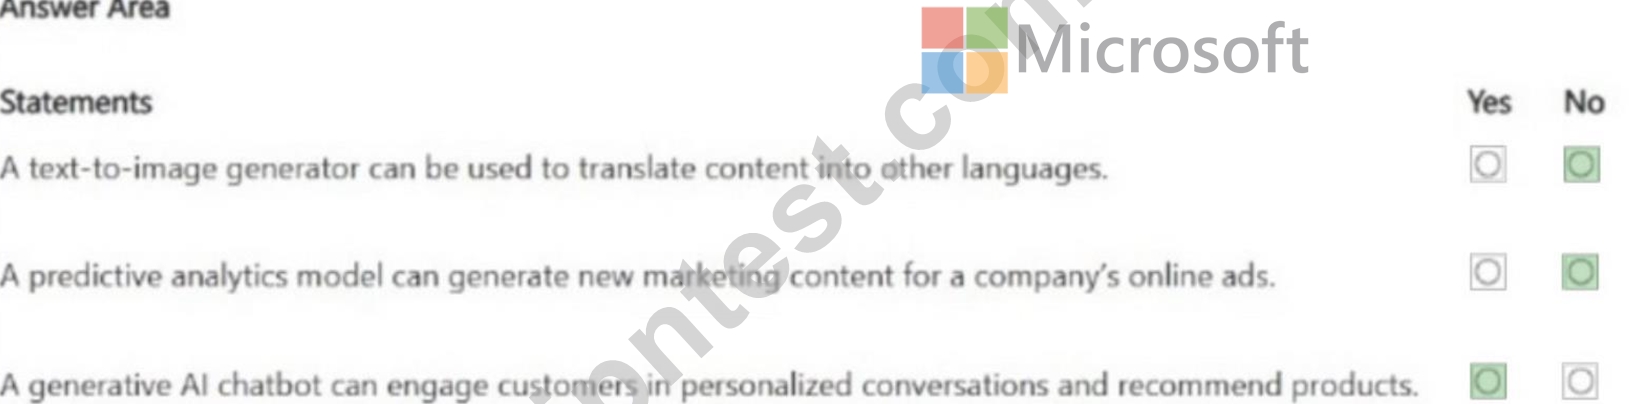
Explanation:
Box 1: No
A text-to-image generator (like DALL-E or Midjourney) takes textual descriptions and synthesizes them into visual imagery. It does not perform language translation workflows; that task requires natural language processing (NLP) or large language models (LLMs).
Box 2: No
Predictive analytics models rely on historical data and machine learning algorithms to forecast future trends, behaviors, or numerical outcomes (such as click-through rates or future sales).
They do not create or synthesize brand-new creative artifacts like marketing text or ad copies; that is the role of Generative AI.
Box 3: Yes
Generative AI chatbots (like those built using custom LLMs or Copilot Studio) excel at maintaining dynamic, human-like context. They can handle highly personalized conversations based on user profile inputs and dynamically synthesize relevant product recommendations.
質問 # 77
You have a large language model (LLM) that was pretrained by using public data.
You want the LLM to generate responses that incorporate frequently updated proprietary content, such as internal documents and knowledge bases.
You need to recommend a solution to ensure that the LLM uses the most current information without retraining the model.
What should you include in the recommendation?
正解:D
解説:
The correct answer is D. Retrieval Augmented Generation (RAG). A pretrained LLM does not automatically know frequently updated proprietary content unless that content is supplied to it during use or the model is retrained. RAG solves this by retrieving relevant, current information from internal documents, knowledge bases, or indexed repositories at runtime and adding that information to the model's prompt context. This keeps responses grounded in the latest approved business content without changing the model weights. Fine- tuning adapts the model but is more expensive and does not automatically keep up with frequently changing knowledge. Content filtering is a safety control, not a freshness mechanism. Prompt engineering improves instructions, but by itself it does not retrieve current proprietary content.
質問 # 78
- Select the answer that correctly completes the sentence.
When you use Microsoft 365 Copilot connectors to connect external content to __________, your users can find, summarize, and learn from line-of-business (LOB) data by using natural language prompts.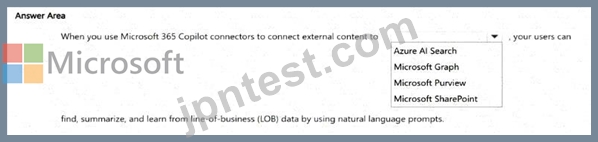
正解:
解説: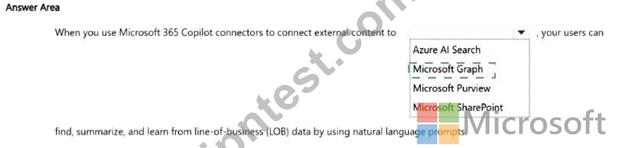
Explanation:
Microsoft Graph
Microsoft 365 Copilot connectors (built on Microsoft Graph connectors) are used to bring external, line-of- business content into the Microsoft 365 ecosystem by ingesting it into Microsoft Graph . Once connected, the content can be indexed and made discoverable through Microsoft Search and available for Copilot experiences, enabling users to use natural language prompts to find and summarize relevant LOB information-subject to permissions and governance controls.
The other choices don't match how Copilot connectors are positioned. Azure AI Search is an Azure indexing
/retrieval service used in custom RAG solutions, but Microsoft 365 Copilot connectors are specifically designed to surface external content through Microsoft 365 experiences via Graph. Microsoft Purview focuses on data governance, compliance, and risk management rather than being the primary ingestion target for Copilot connector content. SharePoint can store content, but the connector model is about indexing external systems into Microsoft Graph so the content becomes searchable and usable across Microsoft 365, not merely placing it into SharePoint as the destination.
So the correct completion is Microsoft Graph because that is the foundational data and indexing fabric Copilot uses to reason over organizational content with appropriate permission trimming.
質問 # 79
......
AB-731練習問題を買いたい場合、自分のメールアドレスを記入してください。そうすれば、支払ったら、すくお客様にAB-731練習問題を送付できます。だから、それは重要な情報です。また、もしAB-731練習問題は更新されましたら、弊社は最新版をお客様のメールボックスに送付致します。
AB-731模擬練習: https://www.jpntest.com/shiken/AB-731-mondaishu
無料でクラウドストレージから最新のJPNTest AB-731 PDFダンプをダウンロードする:https://drive.google.com/open?id=1knthgcF_khwhDPqu_PMBMjz4UjwtntRl