We provide all candidates with DP-750 test torrent that is compiled by experts who have good knowledge of exam, and they are very experience in compile DP-750 study materials. Once we have latest version, we will send it to your mailbox as soon as possible. our DP-750 exam questions just need students to spend 20 to 30 hours practicing can let them have the confidence to pass the DP-750 Exam, so little time great convenience for some workers. It must be your best tool to pass your DP-750 exam and achieve your target.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Prepare and process data | 30-35% | - Data transformation and modeling
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
>> DP-750 Reliable Test Guide <<
Our DP-750 study materials are easy to be mastered and boost varied functions. We compile Our DP-750 preparation questions elaborately and provide the wonderful service to you thus you can get a good learning and preparation for the DP-750 exam. Now there are introduces on the web for you to know the characteristics and functions of our DP-750 Training Materials in detail. And we also have free demo on the web for you to have a try on our DP-750 exam questions. You will be touched by our great quality of DP-750 study guide.
NEW QUESTION # 15
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to implement a daily batch data process that requires complex and highly customized Python transformations. The solution must minimize additional complexity.
What should you include in the solution?
Answer: B
Explanation:
A Databricks notebook provides the flexibility required to implement complex, highly customized Python and PySpark transformations. Scheduling that notebook as a Lakeflow Jobs task supplies native daily orchestration, monitoring, retries, and compute management without introducing another service. Azure Data Factory data flows are oriented toward visually designed transformations and would add external orchestration complexity for logic already implemented most naturally in Python. A continuous job is inappropriate because the workload runs once per day rather than continuously. Spark Declarative Pipelines is effective for declarative batch and streaming ETL, but it is less direct when the core requirement emphasizes highly customized procedural Python transformations. A notebook task therefore provides the necessary programming freedom while keeping scheduling and operation inside Azure Databricks.
NEW QUESTION # 16
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 processes raw data files stored in Azure Storage.
New files arrive at unpredictable intervals.
You need to ensure that Job1 starts automatically when new files arrive and does NOT consume compute resources when no data is available.
Which type of job trigger should you use?
Answer: B
Explanation:
A file arrival trigger starts Job1 when new files are detected in the monitored Azure Storage location. Because the job is launched only after a qualifying arrival, compute does not remain active while the source is idle.
This is well suited to unpredictable file-delivery patterns and avoids the unnecessary executions produced by a fixed schedule. A continuous trigger keeps the workload running and therefore consumes compute even when no files are available. A scheduled trigger starts the job at predetermined times whether or not new data exists. A manual trigger cannot provide automatic processing. File arrival triggers consequently provide the required event-driven behavior while improving resource utilization and controlling cost during inactive periods. Microsoft Learn
NEW QUESTION # 17
You have an Azure Databricks workspace that contains a Delta table named Table1.
Table1 has accumulated obsolete files.
You need to reduce storage costs. The solution must preserve 30 days of time travel history.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
To diminish storage costs while preserving 60 days of time travel history, you must perform the following two actions: Set the delta.deletedFileRetentionDuration table property to 60 days and Run the vacuum command on the table.
Set the delta.deletedFileRetentionDuration table property to 30 days
This property controls how long data files must be deleted before they become eligible for removal by a cleanup process. By default, it is set to 7 days. Increasing it to 60 days ensures that Delta Lake preserves the underlying parquet files required to query any historical snapshot within your 30-day time travel window.
Run the vacuum command on the tableChanging the retention property alone does not delete files or reduce costs. You must explicitly execute the VACUUM command. The command scans the table and permanently deletes uncommitted or deleted data files that are older than the 60- day threshold defined by your retention duration, thereby freeing up storage space.
Incorrect:
[Not C]
Set the delta.logRetentionDuration table property to 30 days
This property controls how long the transaction log (_delta_log) history is kept, which defaults to
30 days. While the transaction log is required for time travel, modifying this property alone does not delete the heavy data files causing high storage costs. Furthermore, it governs the logs rather than the actual deleted data files.
Reference:
https://www.cloudmatter.io/post/data-audit-with-databricks-delta-time-travel
NEW QUESTION # 18
Hotspot Question
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out-of-memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.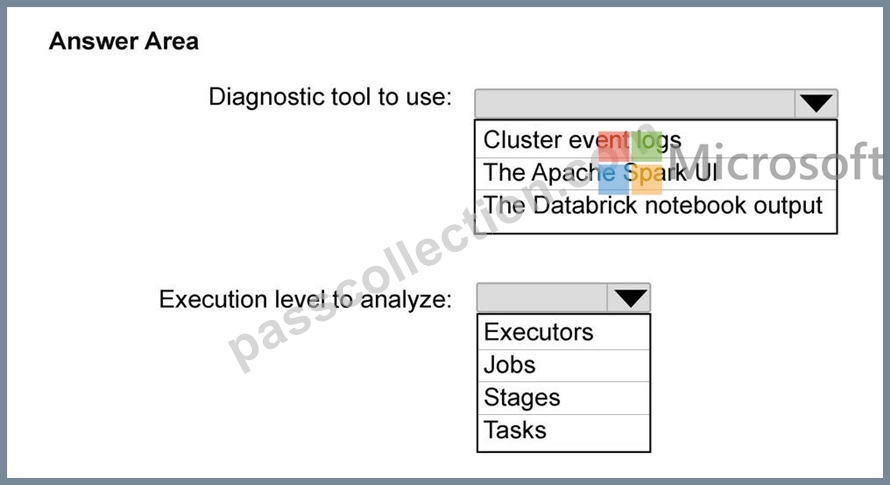
Answer:
Explanation: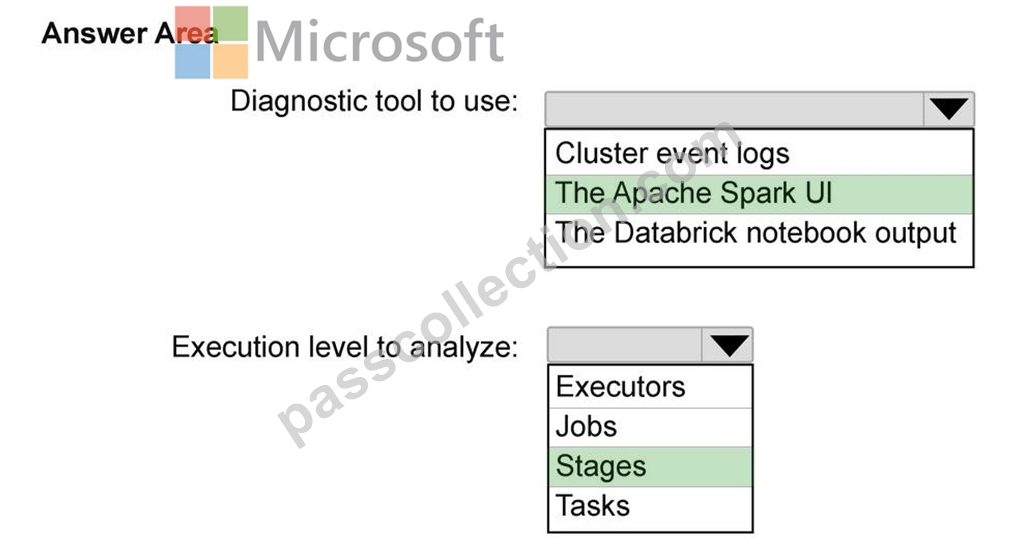
NEW QUESTION # 19
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline in Azure Databricks. The pipeline ingests transaction data into a table named Table1.
You need to ensure that in the event of an invalid record, the pipeline continues to run. The solution must meet the following requirements:
- Invalid records must NOT be written to Table1.
- Invalid records must be preserved for review.
- Minimize development effort.
What should you do?
Answer: C
Explanation:
To meet your pipeline requirements, use the expect_or_drop expectation constraint to ensure invalid records are not written to the table while allowing the pipeline to continue running. To preserve and review invalid records without custom development, capture the failed rows by isolating the inverse rule (expect_or_drop) in a quarantine flow.
Summary of the Behavior Matrix
Pipeline continues to run: Achieved via drop or warn behaviors (the fail policy is excluded because it halts execution).
Invalid records not written to the clean table: Achieved via the drop policy, which discards records from the downstream dataset.
Records preserved for review: Achieved by querying the automated, built-in Lakeflow Event Log Delta table, which automatically captures the details of any rejected or flagged rows without requiring custom code.
Minimized development: Eliminates the need to construct secondary "quarantine" storage tables manually.
Reference:
https://docs.databricks.com/aws/en/ldp/best-practices
NEW QUESTION # 20
......
The system of DP-750 test guide will keep track of your learning progress in the whole course. Therefore, you can have 100% confidence in our DP-750 exam guide. According to our overall evaluation and research, seldom do we have cases that customers fail the DP-750 exam after using our study materials. But to relieve your doubts about failure in the test, we guarantee you a full refund from our company by virtue of the related proof of your report card. Of course you can freely change another DP-750 Exam Guide to prepare for the next exam. Generally speaking, our company takes account of every client’ difficulties with fitting solutions.
DP-750 Reliable Dumps: https://www.passcollection.com/DP-750_real-exams.html