Übrigens, Sie können die vollständige Version der ZertFragen Databricks-Certified-Professional-Data-Engineer Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=15TwMTXVOSI_qD504Vw6cIje8McyiiLKM
Sich für IT-Branche interessierend Sie bereiten sich jetzt auf die wichtige Databricks Databricks-Certified-Professional-Data-Engineer Prüfung? Lassen wir ZertFragen Ihnen helfen! Was wir Ihnen garantieren ist, dass Sie nicht nur die Databricks Databricks-Certified-Professional-Data-Engineer Prüfung bestehen können, sondern auch Sie der leichte Vorbereitungsprozess und guter Kundendienst genießen.
Databricks ist eine cloudbasierte Datenanalyseplattform, die Lösungen für Datenengineering, maschinelles Lernen und Analytik bietet. Die Zertifizierung zum Databricks Certified Professional Data Engineer ist ein Zertifizierungsprogramm, das entwickelt wurde, um die Fähigkeiten und Kenntnisse von Data-Engineers zu validieren, die mit der Databricks-Plattform arbeiten. Das Examen soll die Fähigkeit des Kandidaten bewerten, Datenpipelines mit Databricks zu entwerfen, zu implementieren und zu verwalten.
>> Databricks-Certified-Professional-Data-Engineer Prüfungsaufgaben <<
Aufgrund der großen Übereinstimmung mit den echten Prüfungsfragen-und Antworten können wir Ihnen 100%-Pass-Garantie versprechen. Wir aktualisieren jeden Tag nach den Informationen von Prüfungsabsolventen oder Mitarbeitern von dem Testcenter unsere Prüfungsfragen und Antworten zu Databricks Databricks-Certified-Professional-Data-Engineer (Databricks Certified Professional Data Engineer Exam). Wir extrahieren jeden Tag die Informationen der tatsächlichen Prüfungen und integrieren in unsere Produkte.
Databricks ist eine leistungsstarke Plattform für Datentechnik und maschinelles Lernen, die in verschiedenen Branchen weit verbreitet ist. Um sicherzustellen, dass Fachkräfte über die erforderlichen Fähigkeiten und das Know -how verfügen, um mit Datenbanken zusammenzuarbeiten, bietet das Unternehmen ein Zertifizierungsprogramm an. Eine der angebotenen Zertifizierungen ist die Prüfung für Datenbäume, auch als Databricks Databricks-zertifizierte Professional-Data-Engineer-Prüfung bekannt.
161. Frage
Which of the following technologies can be used to identify key areas of text when parsing Spark Driver log4j output?
Antwort: A
Begründung:
Regex, or regular expressions, are a powerful way of matching patterns in text. They can be used to identify key areas of text when parsing Spark Driver log4j output, such as the log level, the timestamp, the thread name, the class name, the method name, and the message. Regex can be applied in various languages and frameworks, such as Scala, Python, Java, Spark SQL, and Databricks notebooks. Reference:
https://docs.databricks.com/notebooks/notebooks-use.html#use-regular-expressions
https://docs.databricks.com/spark/latest/spark-sql/udf-scala.html#using-regular-expressions-in-udfs
https://docs.databricks.com/spark/latest/sparkr/functions/regexp_extract.html
https://docs.databricks.com/spark/latest/sparkr/functions/regexp_replace.html
162. Frage
A team of data engineer are adding tables to a DLT pipeline that contain repetitive expectations for many of the same data quality checks.
One member of the team suggests reusing these data quality rules across all tables defined for this pipeline.
What approach would allow them to do this?
Antwort: C
Begründung:
Maintaining data quality rules in a centralized Delta table allows for the reuse of these rules across multiple DLT (Delta Live Tables) pipelines. By storing these rules outside the pipeline's target schema and referencing the schema name as a pipeline parameter, the team can apply the same set of data quality checks to different tables within the pipeline. This approach ensures consistency in data quality validations and reduces redundancy in code by not having to replicate the same rules in each DLT notebook or file.
Reference:
Databricks Documentation on Delta Live Tables: Delta Live Tables Guide
163. Frage
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.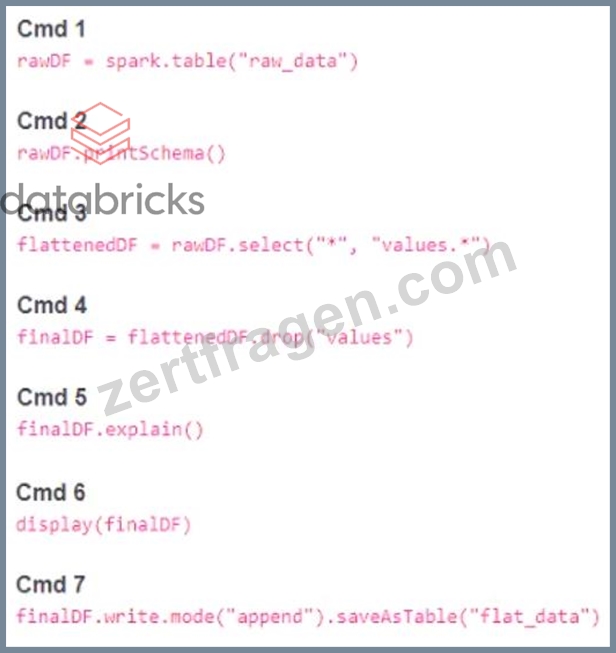
Which command should be removed from the notebook before scheduling it as a job?
Antwort: D
Begründung:
Cmd 6 is the command that should be removed from the notebook before scheduling it as a job. This command is selecting all the columns from the finalDF dataframe and displaying them in the notebook. This is not necessary for the job, as the finalDF dataframe is already written to a table in Cmd 7. Displaying the dataframe in the notebook will only consume resources and time, and it will not affect the output of the job. Therefore, Cmd 6 is redundant and should be removed.
The other commands are essential for the job, as they perform the following tasks:
Cmd 1: Reads the raw_data table into a Spark dataframe called rawDF.
Cmd 2: Prints the schema of the rawDF dataframe, which is useful for debugging and understanding the data structure.
Cmd 3: Selects all the columns from the rawDF dataframe, as well as the nested columns from the values struct column, and creates a new dataframe called flattenedDF.
Cmd 4: Drops the values column from the flattenedDF dataframe, as it is no longer needed after flattening, and creates a new dataframe called finalDF.
Cmd 5: Explains the physical plan of the finalDF dataframe, which is useful for optimizing and tuning the performance of the job.
Cmd 7: Writes the finalDF dataframe to a table called flat_data, using the append mode to add new data to the existing table.
164. Frage
A data engineering team is migrating off its legacy Hadoop platform. As part of the process, they are evaluating storage formats for performance comparison. The legacy platform uses ORC and RCFile formats.
After converting a subset of data to Delta Lake , they noticed significantly better query performance. Upon investigation, they discovered that queries reading from Delta tables leveraged a Shuffle Hash Join , whereas queries on legacy formats used Sort Merge Joins . The queries reading Delta Lake data also scanned less data.
Which reason could be attributed to the difference in query performance?
Antwort: A
Begründung:
Delta Lake outperforms legacy Hadoop formats because it leverages Parquet-based storage , data skipping
, and file pruning . According to Databricks documentation, Delta Lake automatically stores detailed statistics (min/max values and file-level metadata) in the transaction log. During query planning, the engine uses these statistics to skip entire files that do not match query filters , a process called data skipping and file pruning . Additionally, Delta uses a vectorized Parquet reader , which reduces I/O and CPU overhead.
Together, these optimizations allow Delta to scan significantly less data and produce more efficient physical query plans (e.g., Shuffle Hash Join instead of Sort Merge Join). The performance gain is due to efficient data skipping, not the inherent superiority of join type.
165. Frage
A junior developer complains that the code in their notebook isn't producing the correct results in the development environment. A shared screenshot reveals that while they're using a notebook versioned with Databricks Repos, they're using a personal branch that contains old logic. The desired branch named dev-2.3.9 is not available from the branch selection dropdown.
Which approach will allow this developer to review the current logic for this notebook?
Antwort: B
Begründung:
This is the correct answer because it will allow the developer to update their local repository with the latest changes from the remote repository and switch to the desired branch. Pulling changes will not affect the current branch or create any conflicts, as it will only fetch the changes and not merge them. Selecting the dev-2.3.9 branch from the dropdown will checkout that branch and display its contents in the notebook. Verified Reference: [Databricks Certified Data Engineer Professional], under "Databricks Tooling" section; Databricks Documentation, under "Pull changes from a remote repository" section.
166. Frage
......
Databricks-Certified-Professional-Data-Engineer Zertifikatsfragen: https://www.zertfragen.com/Databricks-Certified-Professional-Data-Engineer_prufung.html
P.S. Kostenlose und neue Databricks-Certified-Professional-Data-Engineer Prüfungsfragen sind auf Google Drive freigegeben von ZertFragen verfügbar: https://drive.google.com/open?id=15TwMTXVOSI_qD504Vw6cIje8McyiiLKM