さらに、It-Passports AIF-C01ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1FQbB8m3m7fb7I9Lhe4lh75wRH1DByIfV
試験に合格したい人は、適切なAIF-C01ガイドの質問を選ぶのが困難です。彼らはどの学習教材が自分に適しているかを知りませんし、どの学習教材が最適であるかを知りません。当社は、当社のAIF-C01学習教材が世界市場の中で最高であると約束できます。私たちに知られているように、当社のAIF-C01認定ガイドは、多くの専門家や教授によって設計された当社のAIF-C01学習教材のこのダイナミックな市場における主要な実践教材です。 AIF-C01試験問題に頼ることができます!
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified AI Practitioner |
| Exam Number: | AIF-C01 |
| Exam Price: | USD 100 |
| Related Certifications: | AWS Certified Cloud Practitioner AWS Certified Data Engineer - Associate AWS Certified Machine Learning Engineer - Associate |
| Available Languages: | Simplified Chinese, Portuguese (Brazil), Japanese, English, Korean |
| Certificate Validity Period: | 3 years |
| Passing Score: | 700 / 1000 |
| Exam Duration: | 90 minutes |
| Real Exam Qty: | 80 |
| Exam Format: | Multiple response, Multiple choice |
| Sample Questions: | Amazon AIF-C01 Sample Questions |
| Exam Way: | Online proctored exam (Pearson VUE) or in-person testing center |
| Pre Condition: | None required. Recommended: General IT cloud knowledge and basic understanding of AI/ML concepts. AWS Cloud Practitioner certification is a recommended prerequisite but not mandatory. |
| Official Syllabus URL: | https://aws.amazon.com/certification/certified-ai-practitioner/ |
当社It-Passportsの製品は、実践と記憶に値する専門知識の蓄積です。一緒に参加して、お客様のニーズに合わせてAIF-C01ガイドクイズの成功に貢献する多くの専門家がいます。仕事に取り掛かって顧客とやり取りする前に厳密に訓練された責任ある忍耐強いスタッフ。 AIF-C01試験の準備の質を実践し、経験すると、それらの保守性と有用性を思い出すでしょう。 AIF-C01練習教材が試験受験者の98%以上が夢の証明書を取得するのに役立った理由を説明しています。あなたもそれを手に入れることができると信じてください。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
| トピック 5 |
|
質問 # 293
A company needs to train an ML model to classify images of different types of animals. The company has a large dataset of labeled images and will not label more dat a. Which type of learning should the company use to train the model?
正解:C
解説:
Supervised learning is appropriate when the dataset is labeled. The model uses this data to learn patterns and classify images. Unsupervised learning, reinforcement learning, and active learning are not suitable since they either require unlabeled data or different problem settings. Reference: AWS Machine Learning Best Practices.
質問 # 294
A company wants to develop ML applications to improve business operations and efficiency.
Select the correct ML paradigm from the following list for each use case. Each ML paradigm should be selected one or more times. (Select FOUR.)
* Supervised learning
* Unsupervised learning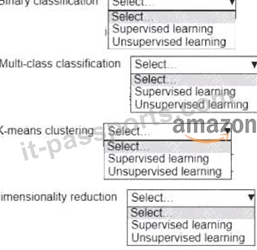
正解:
解説: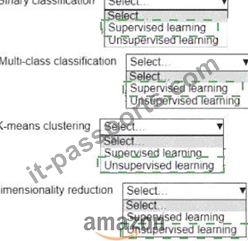
Explanation: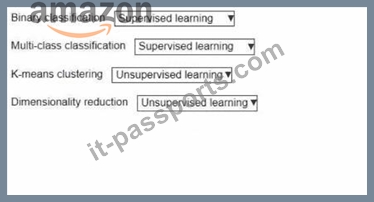
The company is developing ML applications for various use cases, and the task is to select the correct ML paradigm (supervised or unsupervised learning) for each. Supervised learning involves training a model on labeled data to make predictions, while unsupervised learning identifies patterns or structures in unlabeled data. Each use case aligns with one of these paradigms based on its requirements.
Exact Extract from AWS AI Documents:
From the AWS AI Practitioner Learning Path:
"Supervised learning uses labeled data to train models for tasks like classification (e.g., binary or multi-class classification), where the model predicts a category. Unsupervised learning works with unlabeled data for tasks like clustering (e.g., K-means clustering) or dimensionality reduction, identifying patternsor reducing data complexity without predefined labels." (Source: AWS AI Practitioner Learning Path, Module on Machine Learning Strategies) Detailed Explanation:
Binary classification: Supervised learningBinary classification involves predicting one of two classes (e.g., yes
/no, spam/not spam) using labeled data, making it a supervised learning task. The model learns from examples where the correct class is provided.
Multi-class classification: Supervised learningMulti-class classification extends binary classification to predict one of multiple classes (e.g., categorizing items into several groups). Like binary classification, it requires labeled data, so it falls under supervised learning.
K-means clustering: Unsupervised learningK-means clustering groups data into clusters based on similarity, without requiring labeled data. This is a classic unsupervised learning task, as the algorithm identifies patterns in the data on its own.
Dimensionality reduction: Unsupervised learningDimensionality reduction (e.g., using techniques like PCA) reduces the number of features in a dataset while preserving important information. It does not require labeled data, making it an unsupervised learning task.
Hotspot Selection Analysis:
The hotspot lists four use cases, each with a dropdown containing "Select...," "Supervised learning," and
"Unsupervised learning." The correct selections are:
Binary classification: Supervised learning
Multi-class classification: Supervised learning
K-means clustering: Unsupervised learning
Dimensionality reduction: Unsupervised learning
Each paradigm (supervised and unsupervised learning) is used twice, as the question allows for paradigms to be selected one or more times.
References:
AWS AI Practitioner Learning Path: Module on Machine Learning Strategies Amazon SageMaker Developer Guide: Supervised and Unsupervised Learning (https://docs.aws.amazon.com
/sagemaker/latest/dg/algos.html)
AWS Documentation: Introduction to Machine Learning Paradigms (https://aws.amazon.com/machine- learning/)
質問 # 295
A company wants to use AWS services to build an AI assistant for internal company use. The AI assistant's responses must reference internal documentation. The company stores internal documentation as PDF, CSV, and image files.
Which solution will meet these requirements with the LEAST operational overhead?
正解:A
解説:
The best solution is Amazon Bedrock Knowledge Bases, which allows for the seamless integration of structured and unstructured internal documents-such as PDFs, CSVs, and extracted image text-into a retrieval-augmented generation (RAG) pipeline. According to AWS documentation, Bedrock Knowledge Bases offer a no-code or low-code setup to link your enterprise data with foundation models for context-aware responses, without needing to fine-tune or retrain models. The system indexes documents in an Amazon S3 bucket, creates embeddings, and stores them in a vector store. At inference time, the model retrieves relevant context and incorporates it into its response. This approach provides dynamic and up-to-date responses while maintaining data privacy, with minimal operational overhead. Unlike fine-tuning or building a model from scratch in SageMaker, which requires considerable compute resources and model management, Bedrock Knowledge Bases are serverless and easy to configure. It is designed exactly for internal knowledge AI assistants.
Referenced AWS AI/ML Documents and Study Guides:
Amazon Bedrock Developer Guide - Knowledge Bases
AWS Generative AI Best Practices - RAG Patterns for Enterprise Search
質問 # 296
A bank is fine-tuning a large language model (LLM) on Amazon Bedrock to assist customers with questions about their loans. The bank wants to ensure that the model does not reveal any private customer data.
Which solution meets these requirements?
正解:B
解説:
The goal is to prevent a fine-tuned large language model (LLM) on Amazon Bedrock from revealing private customer data. Let's analyze the options:
A . Amazon Bedrock Guardrails: Guardrails in Amazon Bedrock allow users to define policies to filter harmful or sensitive content in model inputs and outputs. While useful for real-time content moderation, they do not address the risk of private data being embedded in the model during fine-tuning, as the model could still memorize sensitive information.
B . Remove personally identifiable information (PII) from the customer data before fine-tuning the LLM: Removing PII (e.g., names, addresses, account numbers) from the training dataset ensures that the model does not learn or memorize sensitive customer data, reducing the risk of data leakage. This is a proactive and effective approach to data privacy during model training.
C . Increase the Top-K parameter of the LLM: The Top-K parameter controls the randomness of the model's output by limiting the number of tokens considered during generation. Adjusting this parameter affects output diversity but does not address the privacy of customer data embedded in the model.
D . Store customer data in Amazon S3. Encrypt the data before fine-tuning the LLM: Encrypting data in Amazon S3 protects data at rest and in transit, but during fine-tuning, the data is decrypted and used to train the model. If PII is present, the model could still learn and potentially expose it, so encryption alone does not solve the problem.
Exact Extract Reference: AWS emphasizes data privacy in AI/ML workflows, stating, "To protect sensitive data, you can preprocess datasets to remove personally identifiable information (PII) before using them for model training. This reduces the risk of models inadvertently learning or exposing sensitive information." (Source: AWS Best Practices for Responsible AI, https://aws.amazon.com/machine-learning/responsible-ai/). Additionally, the Amazon Bedrock documentation notes that users are responsible for ensuring compliance with data privacy regulations during fine-tuning (https://docs.aws.amazon.com/bedrock/latest/userguide/model-customization.html).
Removing PII before fine-tuning is the most direct and effective way to prevent the model from revealing private customer data, making B the correct answer.
Reference:
AWS Bedrock Documentation: Model Customization (https://docs.aws.amazon.com/bedrock/latest/userguide/model-customization.html) AWS Responsible AI Best Practices (https://aws.amazon.com/machine-learning/responsible-ai/) AWS AI Practitioner Study Guide (emphasis on data privacy in LLM fine-tuning)
質問 # 297
An airline company wants to build a conversational AI assistant to answer customer questions about flight schedules, booking, and payments. The company wants to use large language models (LLMs) and a knowledge base to create a text-based chatbot interface.
Which solution will meet these requirements with the LEAST development effort?
正解:D
解説:
The airline company aims to build a conversational AI assistant using large language models (LLMs) and a knowledge base to create a text-based chatbot with minimal development effort. Retrieval Augmented Generation (RAG) on Amazon Bedrock is an ideal solution because it combines LLMs with a knowledge base to provide accurate, contextually relevant responses without requiring extensive model training or custom development. RAG retrieves relevant information from a knowledge base and uses an LLM to generate responses, simplifying the development process.
Exact Extract from AWS AI Documents:
From the AWS Bedrock User Guide:
"Retrieval Augmented Generation (RAG) in Amazon Bedrock enables developers to build conversational AI applications by combining foundation models with external knowledge bases. This approach minimizes development effort by leveraging pre-trained models and integrating them with data sources, such as FAQs or databases, to provide accurate and contextually relevant responses." (Source: AWS Bedrock User Guide, Retrieval Augmented Generation) Detailed Option A: Train models on Amazon SageMaker Autopilot.SageMaker Autopilot is designed for automated machine learning (AutoML) tasks like classification or regression, not for building conversational AI with LLMs and knowledge bases. It requires significant data preparation and is not optimized for chatbot development, making it less suitable.
Option B: Develop a Retrieval Augmented Generation (RAG) agent by using Amazon Bedrock.This is the correct answer. RAG on Amazon Bedrock allows the company to use pre-trained LLMs and integrate them with a knowledge base (e.g., flight schedules or FAQs) to build a chatbot with minimal effort. It avoids the need for extensive training or coding, aligning with the requirement for least development effort.
Option C: Create a Python application by using Amazon Q Developer.While Amazon Q Developer can assist with code generation, building a chatbot from scratch in Python requires significant development effort, including integrating LLMs and a knowledge base manually, which is more complex than using RAG on Bedrock.
Option D: Fine-tune models on Amazon SageMaker Jumpstart.Fine-tuning models on SageMaker Jumpstart requires preparing training data and customizing LLMs, which involves more effort than using a pre-built RAG solution on Bedrock. This option is not the least effort-intensive.
Reference:
AWS Bedrock User Guide: Retrieval Augmented Generation (https://docs.aws.amazon.com/bedrock/latest/userguide/rag.html) AWS AI Practitioner Learning Path: Module on Generative AI and Conversational AI Amazon Bedrock Developer Guide: Building Conversational AI (https://aws.amazon.com/bedrock/)
質問 # 298
......
AIF-C01試験番号: https://www.it-passports.com/AIF-C01.html
P.S.It-PassportsがGoogle Driveで共有している無料の2026 Amazon AIF-C01ダンプ:https://drive.google.com/open?id=1FQbB8m3m7fb7I9Lhe4lh75wRH1DByIfV