BTW, DOWNLOAD part of TestKingIT Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1Ko7HFVzig_z34etg9Q_OkhbRZq8-Qz1u
If you fail Data-Engineer-Associate exam with our Data-Engineer-Associate exam dumps, we will full refund the cost that you purchased our Data-Engineer-Associate exam dumps. However, our promise of "No help, full refund" doesn't shows our no confidence to our products; oppositely, it expresses our most sincere and responsible attitude to reassure our customers. With our professional Data-Engineer-Associate Exam software, you will be at ease about your Data-Engineer-Associate exam, and you will be satisfied with our after-sale service after you have purchased our Data-Engineer-Associate exam software.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion and Transformation | 34% | - Ingest and transform data using AWS services - Build and manage data pipelines |
| Data Store Management | 26% | - Select appropriate data storage solutions - Optimize storage performance and cost |
| Data Security and Governance | 18% | - Implement data security controls - Apply governance and compliance best practices |
| Data Operations and Support | 22% | - Troubleshoot data workflow issues - Monitor and maintain data pipelines |
>> Data-Engineer-Associate Certified Questions <<
These practice exams are customizable and help you counter exam anxiety. You can use Amazon Data-Engineer-Associate desktop practice test software and web-based practice test software to assess your knowledge, test-taking skills, and readiness for the actual Data-Engineer-Associate exam. With both Data-Engineer-Associate exam practice test software you can familiarize yourself with the types of questions, and overall exam environment and improve your exam time management skills. So choose your desired Data-Engineer-Associate Exam Practice test software and start exam preparation today. The desktop software runs on Windows computers and the web-based is supported by all operating systems.
NEW QUESTION # 50
A company has three subsidiaries. Each subsidiary uses a different data warehousing solution. The first subsidiary hosts its data warehouse in Amazon Redshift. The second subsidiary uses Teradata Vantage on AWS. The third subsidiary uses Google BigQuery.
The company wants to aggregate all the data into a central Amazon S3 data lake. The company wants to use Apache Iceberg as the table format.
A data engineer needs to build a new pipeline to connect to all the data sources, run transformations by using each source engine, join the data, and write the data to Iceberg.
Which solution will meet these requirements with the LEAST operational effort?
Answer: A
Explanation:
Amazon Athena provides federated query connectors that allow querying multiple data sources, such as Amazon Redshift, Teradata, and Google BigQuery, without needing to extract the data from the original source. This solution is optimal because it offers the least operational effort by avoiding complex data movement and transformation processes.
* Amazon Athena Federated Queries:
* Athena's federated queries allow direct querying of data stored across multiple sources, including Amazon Redshift, Teradata, and BigQuery. With Athena's support for Apache Iceberg, the company can easily run a Merge operation on the Iceberg table.
* The solution reduces complexity by centralizing the query execution and transformation process in Athena using SQL queries.
NEW QUESTION # 51
A retail company is expanding its operations globally. The company needs to use Amazon QuickSight to accurately calculate currency exchange rates for financial reports. The company has an existing dashboard that includes a visual that is based on an analysis of a dataset that contains global currency values and exchange rates.
A data engineer needs to ensure that exchange rates are calculated with a precision of four decimal places. The calculations must be precomputed. The data engineer must materialize results in QuickSight super-fast, parallel, in-memory calculation engine (SPICE).
Which solution will meet these requirements?
Answer: C
NEW QUESTION # 52
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?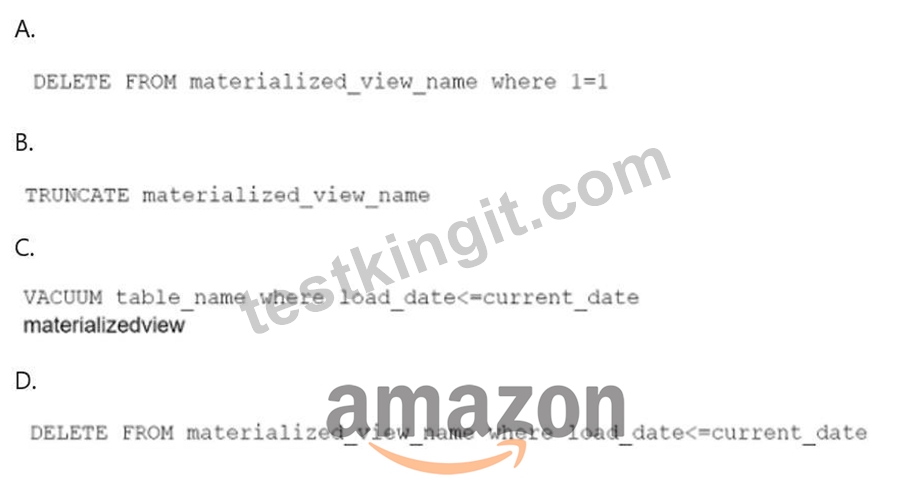
Answer: C
Explanation:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
Option A: DELETE FROM materialized_view_name WHERE 1=1;This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
References:
Amazon Redshift Materialized Views Documentation
Deleting Data from Redshift
NEW QUESTION # 53
A data engineer needs Amazon Athena queries to finish faster. The data engineer notices that all the files the Athena queries use are currently stored in uncompressed .csv format. The data engineer also notices that users perform most queries by selecting a specific column.
Which solution will MOST speed up the Athena query performance?
Answer: C
Explanation:
Amazon Athena is a serverless interactive query service that allows you to analyze data in Amazon S3 using standard SQL. Athena supports various data formats, such as CSV, JSON, ORC, Avro, and Parquet.
However, not all data formats are equally efficient for querying. Some data formats, such as CSV and JSON, are row-oriented, meaning that they store data as a sequence of records, each with the same fields. Row- oriented formats are suitable for loading and exporting data, but they are not optimal for analytical queries that often access only a subset of columns. Row-oriented formats also do not support compression or encoding techniques that can reduce the data size and improve the query performance.
On the other hand, some data formats, such as ORC and Parquet, are column-oriented, meaning that they store data as a collection of columns, each with a specific data type. Column-oriented formats are ideal for analytical queries that often filter, aggregate, or join data by columns. Column-oriented formats also support compression and encoding techniques that can reduce the data size and improve the query performance. For example, Parquet supports dictionary encoding, which replaces repeated values with numeric codes, and run- length encoding, which replaces consecutive identical values with a single value and a count. Parquet also supports various compression algorithms, such as Snappy, GZIP, and ZSTD, that can further reduce the data size and improve the query performance.
Therefore, changing the data format from CSV to Parquet and applying Snappy compression will most speed up the Athena query performance. Parquet is a column-oriented format that allows Athena to scan only the relevant columns and skip the rest, reducing the amount of data read from S3. Snappy is a compression algorithm that reduces the data size without compromising the query speed, as it is splittable and does not require decompression before reading. This solution will also reduce the cost of Athena queries, as Athena charges based on the amount of data scanned from S3.
The other options are not as effective as changing the data format to Parquet and applying Snappy compression. Changing the data format from CSV to JSON and applying Snappy compression will not improve the query performance significantly, as JSON is also a row-oriented format that does not support columnar access or encoding techniques. Compressing the CSV files by using Snappy compression will reduce the data size, but it will not improve the query performance significantly, as CSV is still a row-oriented format that does not support columnar access or encoding techniques. Compressing the CSV files by using gzjg compression will reduce the data size, but it will degrade the query performance, as gzjg is not a splittable compression algorithm and requires decompression before reading. References:
* Amazon Athena
* Choosing the Right Data Format
* AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide, Chapter 5: Data Analysis and Visualization, Section 5.1: Amazon Athena
NEW QUESTION # 54
A company stores CSV files in an Amazon S3 bucket. A data engineer needs to process the data in the CSV files and store the processed data in a new S3 bucket.
The process needs to rename a column, remove specific columns, ignore the second row of each file, create a new column based on the values of the first row of the data, and filter the results by a numeric value of a column.
Which solution will meet these requirements with the LEAST development effort?
Answer: C
Explanation:
The requirement involves transforming CSV files by renaming columns, removing rows, and other operations with minimal development effort. AWS Glue DataBrew is the best solution here because it allows you to visually create transformation recipes without writing extensive code.
Option D: Use AWS Glue DataBrew recipes to read and transform the CSV files.
DataBrew provides a visual interface where you can build transformation steps (e.g., renaming columns, filtering rows, creating new columns, etc.) as a "recipe" that can be applied to datasets, making it easy to handle complex transformations on CSV files with minimal coding.
Other options (A, B, C) involve more manual development and configuration effort (e.g., writing Python jobs or creating custom workflows in Glue) compared to the low-code/no-code approach of DataBrew.
Reference:
AWS Glue DataBrew Documentation
NEW QUESTION # 55
......
A minor mistake may result you to lose chance even losing out on your Data-Engineer-Associate Exam. So we hold responsible tents when compiling the Data-Engineer-Associate learning guide. The principles of our Data-Engineer-Associatepractice materials can be expressed in words like clarity, correction and completeness. Experts expressed their meaning with clarity by knowledgeable and understandable words which cannot be misunderstood.
Data-Engineer-Associate Discount: https://www.testkingit.com/Amazon/latest-Data-Engineer-Associate-exam-dumps.html
DOWNLOAD the newest TestKingIT Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1Ko7HFVzig_z34etg9Q_OkhbRZq8-Qz1u