By focusing on how to help you more effectively, we encourage exam candidates to buy our DP-750 study braindumps with high passing rate up to 98 to 100 percent all these years. Our experts designed three versions for you rather than simply congregate points of questions into DP-750 Real Questions. Efforts conducted in an effort to relieve you of any losses or stress. So our activities are not just about profitable transactions to occur but enable exam candidates win this exam with the least time and get the most useful contents.
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
Purchasing our DP-750 training test is not complicated, there are mainly four steps: first, you can choose corresponding version according to the needs you like. Next, you need to fill in the correct email address. And if the user changes the email during the subsequent release, you need to update the email. Then, the user needs to enter the payment page of the DP-750 Learning Materials to buy it. Finally, within ten minutes of payment, the system automatically sends the DP-750 study materials to the user's email address. And then you can quickly study and pass the DP-750 exam.
NEW QUESTION # 27
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a Lakeflow Connect pipeline and connect it to DB1. Does this meet the goal?
Answer: B
Explanation:
The correct answer is B - No.
Lakeflow Connect is an ingestion service that physically copies data from external databases into Delta tables managed by Databricks. It's designed for scenarios where you want a replicated, writable Delta copy of external data - essentially a CDC-based ingestion pipeline.
That's the opposite of what's required here. The requirement states 'the data is NOT copied into Databricks- managed storage.' Lakeflow Connect would create Delta tables in Databricks and copy DB1's data into them
- a direct violation.
Additionally, Lakeflow Connect creates Databricks-native Delta tables rather than exposing DB1's original schemas and tables as virtual objects. Analysts querying through a Lakeflow Connect pipeline are querying a replicated copy, not the live source.
For zero-copy, live query federation of an external SQL Server into Unity Catalog, Lakehouse Federation (foreign catalog) is the correct tool.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/lakeflow-connect/
NEW QUESTION # 28
Hotspot Question
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming. The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.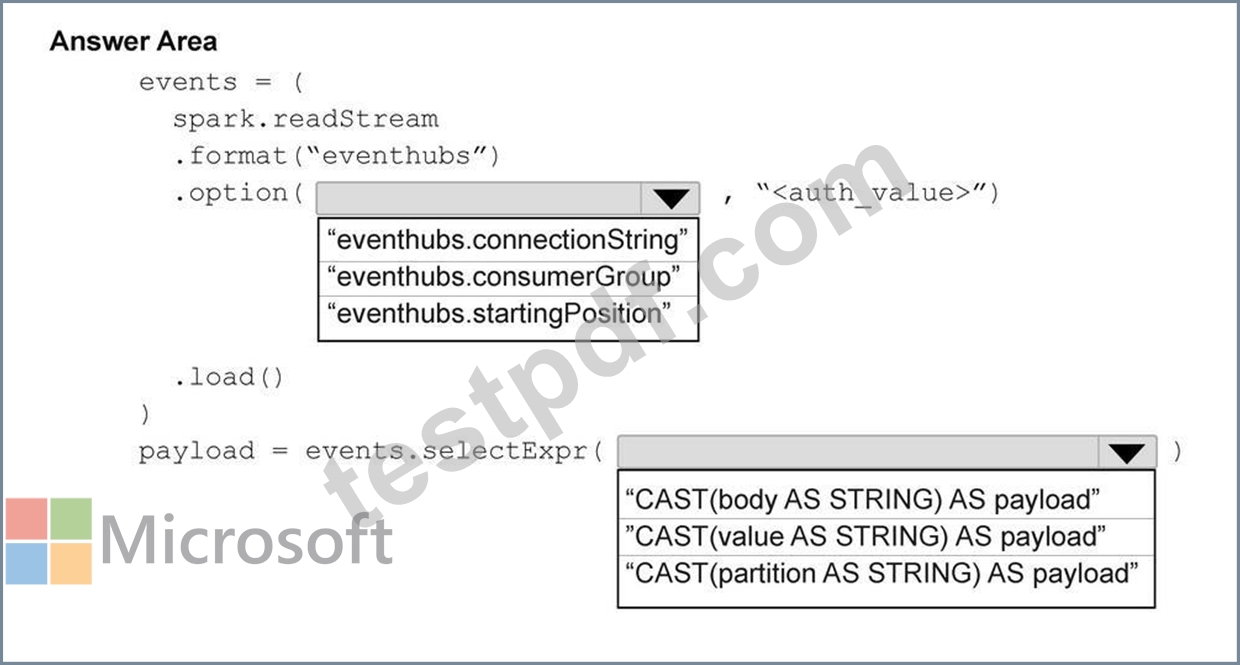
Answer:
Explanation: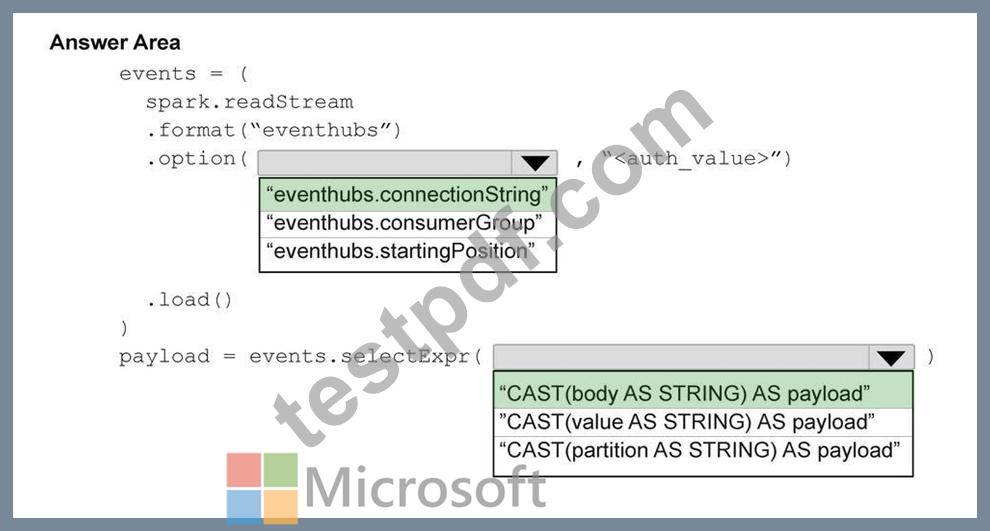
NEW QUESTION # 29
You have an Azure Databricks workspace that is enabled for Unity Catalog You plan to ingest data from CSV files stored in Azure Data Lake Storage Gen2. New rows are appended frequently.
You need to implement a data ingestion solution that meets the following requirements:
* New data must be available in near-real time (NRT).
* The data must be stored in managed Delta tables.
* The solution must minimize custom code and maintenance effort.
What should you include in the solution?
Answer: C
Explanation:
The correct answer is A - Auto Loader.
Auto Loader is exactly the right tool for this scenario: new CSV files land in ADLS Gen2, and they need to be ingested into managed Delta tables in near-real time with minimal custom code. Auto Loader uses file-system notifications or incremental directory listing to detect new arrivals, processes only the newly added files (skipping previously ingested ones), and writes results into Delta tables - all with schema inference and evolution support built in.
Option B (scheduled Spark batch jobs) adds latency tied to the schedule interval and requires custom 'what files have I already processed' tracking. Option C (external table referencing CSV files) exposes the raw files for querying but doesn't load data into managed Delta tables - it also can't provide NRT updates as files change. Option D (Azure Data Factory pipeline) introduces external orchestration overhead and is a heavier solution for something Auto Loader handles natively in a few lines of PySpark.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/
NEW QUESTION # 30
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a complex job named Job1 that contains eight tasks. Job1 takes multiple hours to complete.
During the last job run, the final task fails due to a transient issue.
You need to retry the last task without rerunning tasks that have already completed.
What should you do?
Answer: C
Explanation:
Repairing the current job run allows Lakeflow Jobs to rerun the failed task while preserving the successful status of tasks that already completed. This prevents several hours of successful processing from being repeated and reduces both recovery time and compute consumption. If downstream tasks had been skipped because of the failure, they can also be included in the repair operation as appropriate. Updating job parameters changes configuration but does not retry the failed task in the existing run. Restarting Job1 creates a new run and ordinarily executes the workflow again from its beginning. Disabling and reenabling the schedule only changes whether future scheduled runs can start; it does not repair the failed execution. Repair Run is specifically designed for recovering selected failed or skipped tasks in a multi-task workflow.
NEW QUESTION # 31
You have an Azure Databricks workspace named Workspace! that uses a Git repository. The repository contains a Databricks notebook named Notebook1.
From the main branch, you create a feature branch named Branch! and commit changes to Notebooks Another user commits changes to Notebook1 in main.
When you attempt to merge Branch! into main, the merge fails due to conflicts.
You need to merge Branch! into the main branch. The solution must ensure that Notebook1 includes all the changes from both the branches.
What should you do?
Answer: B
Explanation:
The correct answer is D - apply the main branch changes to Branch1 and resolve the conflicts.
When a merge fails due to conflicts, the right workflow is to bring main's changes into the feature branch, resolve conflicts there, and then merge the clean feature branch into main. This is the standard Git conflict resolution pattern - resolve in the feature branch, not in main - because it protects the main branch from partial or broken states during resolution.
Option A (clone Branch1 as a new repository) creates a disconnected copy; it doesn't resolve the conflict and breaks the relationship with the remote. Option B (apply changes directly to main) bypasses the feature branch entirely and risks overwriting the other developer's work. Option C (clone main as a new repository) again creates a disconnected copy - none of Branch1's changes would be incorporated, and history would be lost.
Reference: https://learn.microsoft.com/en-us/azure/databricks/repos/git-operations-with-repos
NEW QUESTION # 32
......
At the time when people are hesitating about that which kind of DP-750 study material should be chosen in order to prepare for the important exam I would like to recommend the DP-750 training materials compiled by our company for you to complete the task. We have put substantial amount of money and effort into upgrading the quality of our DP-750 Preparation material. There are so many advantages of our DP-750 actual exam, such as free demo available, multiple choices, and practice test available to name but a few.
Valid Exam DP-750 Practice: https://www.testpdf.com/DP-750-exam-braindumps.html