What's more, part of that ITExamDownload DP-800 dumps now are free: https://drive.google.com/open?id=1p8IBtTLQjOhf5FolHYPDLT0NhMv6DO9Y
If you buy our DP-800 preparation questions, we can promise that you can use our study materials for study in anytime and anywhere. Because our study system can support you study when you are in an offline state. In addition, Our DP-800 training quiz will be very useful for you to improve your learning efficiency, because you can make full use of your all spare time to do test. It will bring a lot of benefits for you beyond your imagination if you buy our DP-800 Study Materials.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> DP-800 Certification Cost <<
In fact, a number of qualifying exams and qualifications will improve your confidence and sense of accomplishment to some extent, so our DP-800 learning materials can be your new target. When we get into the job, our DP-800 learning materials may bring you a bright career prospect. Companies need employees who can create more value for the company, but your ability to work directly proves your value. Our DP-800 Learning Materials can help you improve your ability to work in the shortest amount of time, thereby surpassing other colleagues in your company, for more promotion opportunities and space for development.
NEW QUESTION # 63
You have an Azure SQL database that contains the following SQL graph tables:
* A NODE table named dbo.Person
* An EDGE table named dbo.Knows
Each row in dbo.Person contains the following columns:
* Personid (int)
* DisplayName (nvarchar(100))
You need to use a HATCH operator and exactly two directed Knows relationships to return the Personid and DisplayName of people that are reachable from the person identified by an input parameter named
@startPersonid.
Which Transact-SQL query should you use?
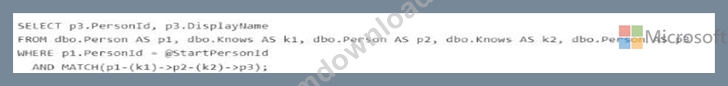
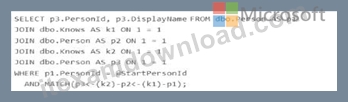
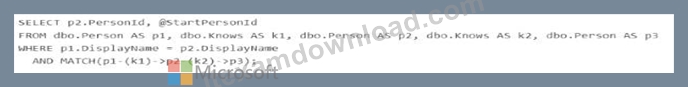
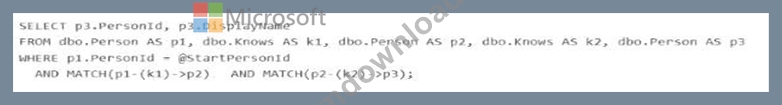
Answer: A
Explanation:
The correct query is Option D because it starts from the input person and uses exactly two directed Knows edges in a single MATCH pattern:
MATCH(p1-(k1)- > p2-(k2)- > p3)
Microsoft documents that SQL Graph uses the MATCH predicate in the WHERE clause to express graph traversal patterns over node and edge tables, and directed relationships are written with arrow syntax such as node1-(edge)- > node2.
Why D is correct:
* It anchors the starting node with p1.PersonId = @StartPersonId.
* It traverses two directed hops : p1 - > p2 - > p3.
* It returns p3.PersonId, p3.DisplayName, which are the people reachable in exactly two Knows relationships.
Why the others are wrong:
* A filters on DisplayName = DisplayName, which is unrelated to the required input parameter and does not correctly anchor the start node.
* B reverses the traversal direction in the pattern.
* C uses two separate MATCH predicates instead of the required single two-hop directed pattern. The proper graph pattern syntax supports chaining the hops directly in one MATCH expression.
Topic 1, Contoso Case Study
Existing Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure. The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.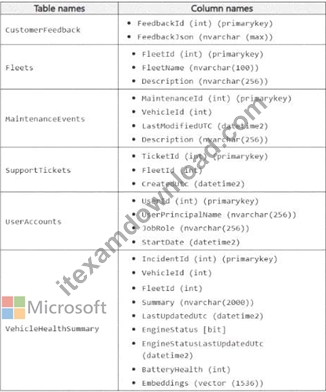
The FeedbackJson column has a full-text index and stores JSON documents in the following format.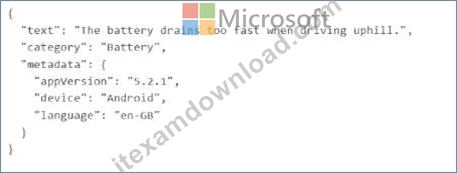
The support staff at Contoso never has the unmask permission.
Requirements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following;
* Al workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.
SELECT VehicleTd, Lastupdatedutc, EngineStatus, BatteryHealth FROM dbo.VehicleHealthSumary where fleetld - gFleetld ORDER BV LastUpdatedUtc DESC; You review the execution plan and discover that the plan shows a clustered index scan.
vehicleincidentReports often contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support Al-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracy JSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEvents table updates the corresponding value in the LastModif reduce column to the time of the change.
* Avoid recursive updates.
AI Search, Embedding's, and Vector indexing
The development learn at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases. Contoso identifies the following requirements for querying data in the FeedbackJson column of the customer-Feedback table:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
NEW QUESTION # 64
Case Study 2 - Fabrikam
Existing Environment
Azure Environment
Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables:
* Patients
* Employees
* Procedures
* Transactions
* UsefulPrompts
* ProcedureDocuments
You store a column master key as a secret in Azure Key Vault.
You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements
Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent.
Requirements
Planned Changes
Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration.
Security Requirements
Fabrikam identifies the following security requirements:
* The TransactionProcessing application must use a passwordless connection to DB1.
* The Employees table contains two columns named TaxID and Salary that must be encrypted at rest.
* Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data.
Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing
Fabrikam identifies the following AI-related requirements:
* Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
* Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric.
* The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements
Fabrikam identifies the following development requirements:
* Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total.
* Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API:
- Read data from the procedures table without authentication.
- Read and insert data into the Transactions table once authenticated.
- Execute the sp_UpdateProcedurePatient stored procedure.
* Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days.
* Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.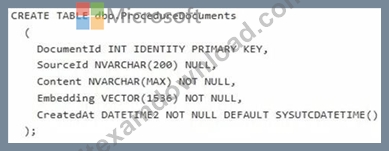
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.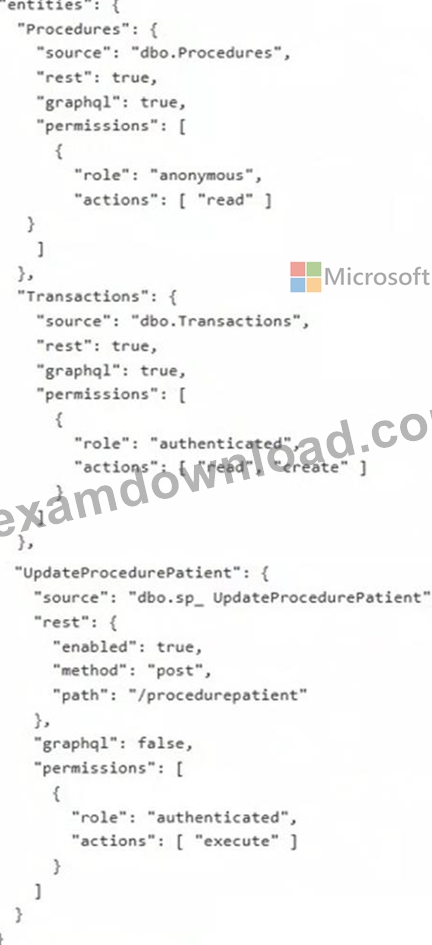
You plan to implement changes to sp_UpdateProcedureForPatient to meet the performance requirements.
You change the stored procedure to run all its code within a transaction.
Which transaction level should you use?
Answer: B
Explanation:
Scenario: Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
To prevent other transactions from changing records while your stored procedure runs, you should use the Repeatable Read isolation level.
Repeatable ReadMechanism: Places shared locks on all data read by the query.
Prevention: Prevents other transactions from modifying or deleting the rows you have accessed.
Consistency: Ensures that if you read the same data twice within the procedure, the values remain identical.
Incorrect:
[Not C]
Serializable
Strictness: This is the highest level of isolation.
Phantom Protection: In addition to preventing changes to existing records, it prevents other transactions from inserting new records that would fall into the range of your query (phantom reads).
Usage: Use this if your procedure relies on aggregate counts or specific ranges that must remain absolutely static.
Key Considerations
Concurrency: Both levels reduce system performance because they hold locks longer, potentially causing other users to wait.
Deadlocks: Higher isolation levels increase the risk of deadlocks in busy databases.
Reference:
https://learn.microsoft.com/en-us/sql/connect/jdbc/understanding-isolation-levels
NEW QUESTION # 65
You need to meet the database performance requirements for maintenance data How should you complete the Transact-SQL code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.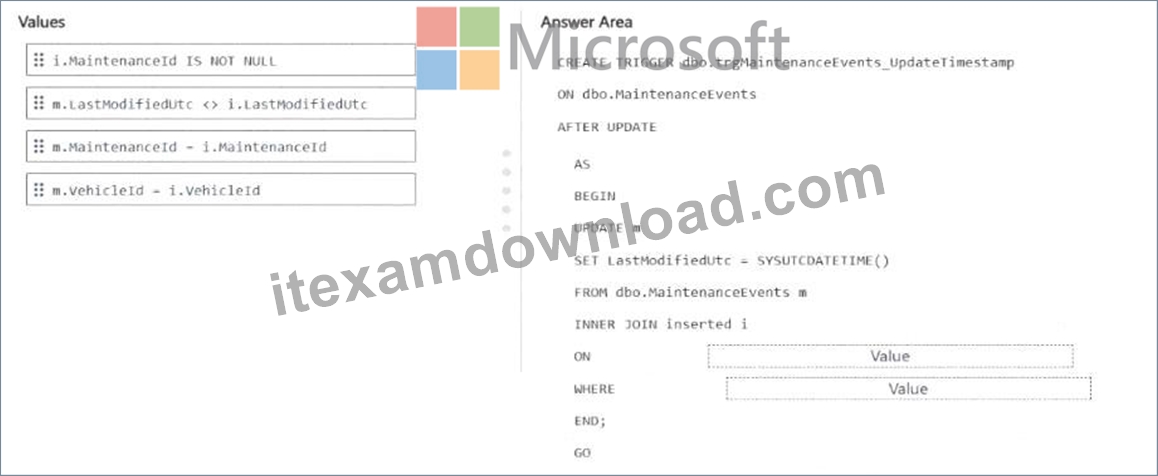
Answer:
Explanation: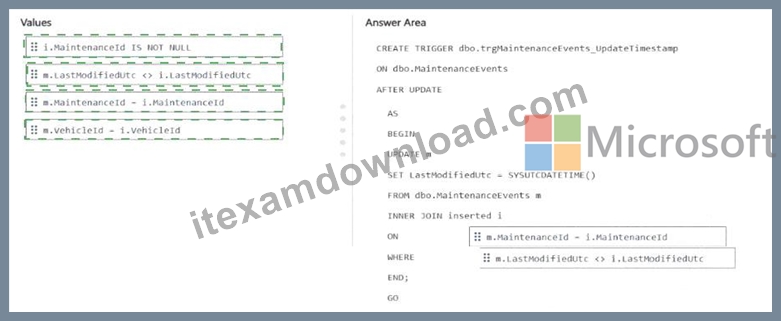
Explanation:
* ON # m.maintenanceId = i.maintenanceId
* WHERE # m.LastModifiedUtc < > i.LastModifiedUtc
The correct drag-and-drop completion is:
* ON m.maintenanceId = i.maintenanceId
* WHERE m.LastModifiedUtc < > i.LastModifiedUtc
This satisfies the requirement to ensure that when a row in MaintenanceEvents changes, the corresponding LastModifiedUtc value is updated to the current system time, while also helping avoid unnecessary repeat updates.
The inserted pseudo-table in a SQL Server AFTER UPDATE trigger contains the rows that were just updated.
To update the matching row in the base table correctly, the trigger must join the target table row to the corresponding row in inserted by the table's primary key. In this schema, MaintenanceId is the primary key for MaintenanceEvents, so the correct join is m.maintenanceId = i.maintenanceId . Joining on VehicleId would be incorrect because multiple maintenance rows could exist for the same vehicle, which could update unintended rows. Microsoft's trigger documentation explains that inserted and deleted are used to work with the affected rows and that multi-row logic should be based on proper key matching.
The WHERE m.LastModifiedUtc < > i.LastModifiedUtc predicate is used to prevent the trigger from re- updating rows where the timestamp already matches the value in inserted. That reduces redundant writes and supports the requirement to avoid recursive or repeated update behavior. In practice, this means the trigger updates only rows whose current stored timestamp differs from the just-updated version. This is the exam- appropriate pattern for a self-updating timestamp column in an AFTER UPDATE trigger.
NEW QUESTION # 66
You need to design a generative Al solution that uses a Microsoft SOL Server 2025 database named DB1 as a data source. The solution must generate responses that meet the following requirements:
* Ait ' grounded In the latest transactional and reference data stored in D61
* Do NOT require retraining or fine-tuning the language model when the data changes
* Can include citations or references to the source data used in the response Which scenario is the best use case for implementing a Retrieval Augmented Generation (RAG) pattern?
More than one answer choice may achieve the goal. Select the BEST answer
Answer: D
Explanation:
The best use case for RAG is answering user questions based on company-specific knowledge . Microsoft defines RAG as a pattern that augments a language model with a retrieval system that provides grounding data at inference time, which is exactly what you need when responses must be based on the latest transactional and reference data , must avoid retraining/fine-tuning , and should be able to include citations or references to source data.
The other options do not fit as well:
* summarizing free-form user input does not inherently require retrieval from DB1,
* training a custom model contradicts the requirement to avoid retraining/fine-tuning,
* generating marketing slogans is a creative generation task, not a grounding-and-citation scenario. RAG is specifically strong when answers must come from your organization's own changing knowledge.
NEW QUESTION # 67
You need to recommend a solution for the development team to retrieve the live metadata. The solution must meet the development requirements.
What should you include in the recommendation?
Answer: D
Explanation:
The best recommendation is to use an MCP server . In the official DP-800 study guide , Microsoft explicitly lists skills such as configuring Model Context Protocol (MCP) tool options in a GitHub Copilot session and connecting to MCP server endpoints, including Microsoft SQL Server and Fabric Lakehouse . That makes MCP the exam-aligned mechanism for enabling AI-assisted tools to work with live database context rather than static snapshots.
This also matches the stated development requirement: the team will use Visual Studio Code and GitHub Copilot and needs to retrieve live metadata from the databases . Microsoft's documentation for GitHub Copilot with the MSSQL extension explains that Copilot works with an active database connection , provides schema-aware suggestions , supports chatting with a connected database, and adapts responses based on the current database context . Microsoft also documents MCP as the standard way for AI tools to connect to external systems and data sources through discoverable tools and endpoints.
The other options do not satisfy the "live metadata" requirement as well:
* A .dacpac is a point-in-time schema artifact, not live metadata.
* A Copilot instruction file provides guidance, not live database discovery.
* Including the database project in the repository helps source control and deployment, but it still does not provide live database metadata by itself.
NEW QUESTION # 68
......
Don't ask me why you should purchase DP-800 valid exam prep, yes, of course it is because of its passing rate. As every one knows IT certificaiton is difficult to pass, its passing rate is low, if you want to save exam cost and money, choosing a DP-800 Valid Exam Prep will be a nice option. ITExamDownload release the best exam preparation materials to help you exam at the first attempt. A good DP-800 valid exam prep will make you half the work with doubt the results.
Study Materials DP-800 Review: https://www.itexamdownload.com/DP-800-valid-questions.html
P.S. Free 2026 Microsoft DP-800 dumps are available on Google Drive shared by ITExamDownload: https://drive.google.com/open?id=1p8IBtTLQjOhf5FolHYPDLT0NhMv6DO9Y