2026 KoreaDumps 최신 HPE7-J01 PDF 버전 시험 문제집과 HPE7-J01 시험 문제 및 답변 무료 공유: https://drive.google.com/open?id=17yJf8l5vvEIFGk0YmwEC0yz2tYq-YMlN
많은 사이트에서 HP인증 HPE7-J01시험대비덤프를 제공해드리는데KoreaDumps를 최강 추천합니다. KoreaDumps의HP인증 HPE7-J01덤프에는 실제시험문제의 기출문제와 예상문제가 수록되어있어 그 품질 하나 끝내줍니다.적중율 좋고 가격저렴한 고품질 덤프는KoreaDumps에 있습니다.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Storage Architecture and Design | 30% | - HPE storage portfolio architecture
|
| Topic 2: Data Protection and Availability | 25% | - High availability solutions
|
| Topic 3: Management and Optimization | 15% | - Troubleshooting and problem resolution
|
| Topic 4: Deployment and Integration | 20% | - Networking and connectivity
|
| Topic 5: Emerging Technologies and Solutions | 10% | - Software-defined storage and modern architectures
|
>> HP HPE7-J01퍼펙트 덤프데모문제 다운 <<
만약 여러분은HP HPE7-J01인증시험취득으로 이 치열한 IT업계경쟁 속에서 자기만의 자리를 잡고, 스펙을 쌓고, 전문적인 지식을 높이고 싶으십니까? 하지만HP HPE7-J01패스는 쉬운 일은 아닙니다.HP HPE7-J01패스는 여러분이 IT업계에 한발작 더 가까워졌다는 뜻이죠. 하지만 이렇게 중요한 시험이라고 많은 시간과 정력을 낭비할필요는 없습니다. KoreaDumps의 완벽한 자료만으로도 가능합니다. KoreaDumps의 덤프들은 모두 전문적으로 IT관련인증시험에 대하여 연구하여 만들어진것이기 때문입니다.
질문 # 52
Refer to the exhibit.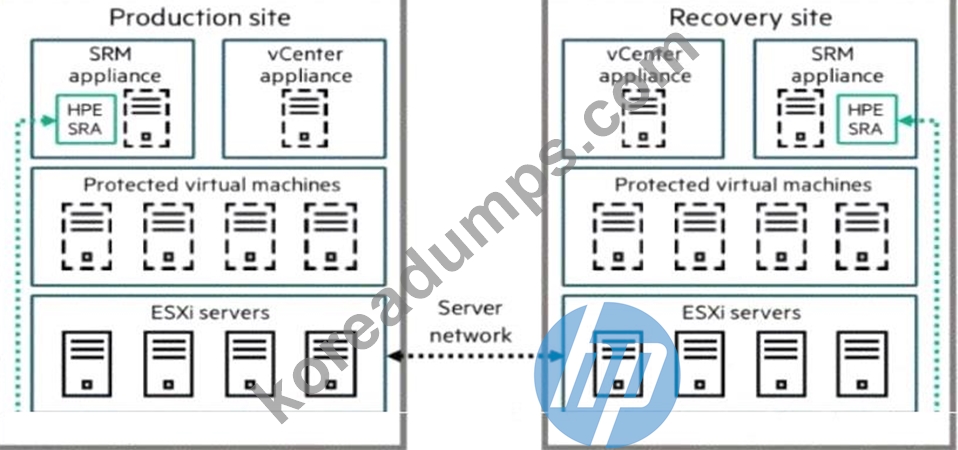
A company is implementing a disaster recovery solution. The Asynchronous Remote Copy feature has been implemented between the HPE AUetra 9000 arrays at both sites. The customer Is interested in providing a disaster recovery (DR) solution that allows for business connectivity of their VMware VMs.
Which VMware solution should the company implement?
정답:C
설명:
To provide automated orchestration and business continuity for VMware virtual machines in a disaster recovery scenario, the industry-standard solution integrated with HPE storage is VMware Live Site Recovery (formerly known as VMware Site Recovery Manager or SRM).
When a customer utilizes Asynchronous Remote Copy on HPE Alletra 9000 arrays, the storage layer handles the data replication between the production and recovery sites. However, the storage array alone cannot automate the re-registration of virtual machines, the mapping of network port groups, or the specific power-on sequencing required for complex applications at the secondary site. VMware Live Site Recovery serves as the orchestration engine that bridges this gap. It works in conjunction with a Storage Replication Adapter (SRA) provided by HPE. The HPE SRA allows the VMware software to communicate directly with the Alletra 9000 arrays to initiate tasks such as promoting recovery volumes to a read-write state, taking temporary snapshots for DR testing, and automating the "failover" and "failback" workflows.
As shown in the exhibit (image_6601ef.jpg), a complete solution requires an SRM appliance and a vCenter appliance at both the production and recovery sites. This architecture ensures that even if the primary site is completely lost, the recovery site has all the necessary metadata and orchestration instructions to bring the business-critical VMs online with minimal manual intervention. Option A (Lifecycle Management) is for patching and updates, Option D (Storage DRS) is for load balancing within a cluster, and Option C refers to operational monitoring rather than disaster recovery orchestration. For a customer already invested in Alletra
9000 Remote Copy, VMware Live Site Recovery is the "Better Together" choice for achieving low Recovery Time Objectives (RTO).
질문 # 53
Which HPE system can be integrated into a factory-built HPE Qumulo solution for a customer?
정답:B
설명:
The HPE Solutions for Qumulo are a result of a strategic partnership designed to provide a high-performance, scale-out NAS (Network Attached Storage) platform for unstructured data. According to the HPE Solutions with Qumulo Reference Architecture, the primary hardware platform utilized for these factory-built, integrated solutions is the HPE Apollo 4000 series, specifically the HPE Apollo 4200.
The Apollo 4200 is chosen for this role because it is a density-optimized, storage-centric server that provides an ideal balance of compute and massive internal storage capacity within a standard 2U rack footprint.
Architecturally, the Apollo 4200 supports an "SSD-first" hybrid configuration or an all-flash configuration, which aligns perfectly with Qumulo's file system requirements. Qumulo's software uses the SSDs for a high- speed metadata layer and write-cache, while utilizing high-capacity HDDs for the data plane, ensuring that even with billions of files, the system maintains near-flash performance.
While the HPE ProLiant DL325 is also used for specific all-NVMe nodes in the Qumulo portfolio, the Apollo
4200 remains the foundational building block for the hybrid and archive nodes that comprise the bulk of enterprise deployments. The HPE Apollo 4500 (Option D) is a 4U system that, while part of the Apollo family, is not the standard integrated platform for the mainstream Qumulo joint offering. The HPE Alletra
5000 (Option B) is a block-storage-focused platform derived from the Nimble lineage, and the ProLiant DL360 (Option C) is a general-purpose 1U compute server that lacks the internal drive density required for a high-capacity scale-out file storage solution. By selecting the Apollo 4200, customers benefit from a pre- validated, factory-integrated solution that simplifies the deployment of massive file lakes for workloads like video surveillance, medical imaging, and big data analytics.
질문 # 54
A customer is concerned about the long distances between their data centers and significant latencies that might exist between the SAN fabrics at the two data centers. Since SCSI write operations can involve multiple handshake messages between the target and initiator, which Brocade feature should be used to double the recommended distance, but maintain the same latency as a shorter haul link?
정답:B
설명:
Standard SCSI write operations are inherently sensitive to distance because they require multiple round-trip handshakes before data is actually transmitted. A typical write involves: 1) the Command, 2) a Transfer Ready (XFER_RDY) response from the target, 3) the Data, and 4) the Status. In a long-distance SAN, each of these round trips adds significant "latency wait time," severely degrading performance as distance increases.
To solve this, Brocade (HPE B-series) utilizes a protocol optimization feature known as FastWrite. FastWrite works by creating a Proxy Target (PT) local to the initiator host and a Proxy Initiator (PI) local to the target storage device. When the host issues a SCSI write command, the local Brocade switch (acting as the Proxy Target) immediately sends the XFER_RDY back to the host without waiting for the signal to travel across the long-distance link. This allows the host to send the data segment immediately.
By eliminating the need for every handshake message to traverse the distance multiple times, FastWrite significantly reduces the aggregate latency felt by the application. Architecturally, this enables customers to extend their SAN fabrics over double the distance (and often much further) while maintaining performance comparable to a significantly shorter link. This is critical for asynchronous replication and remote copy applications that issue large I/O blocks. Option C (Write Acceleration) is a generic term often used by other vendors, while FastWrite is the specific, validated Brocade feature name used in HPE Master ASE documentation for this protocol optimization.
질문 # 55
Match the Brocade virtual fabric term with its description.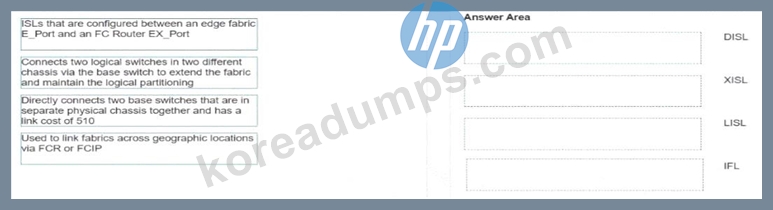
정답:
설명: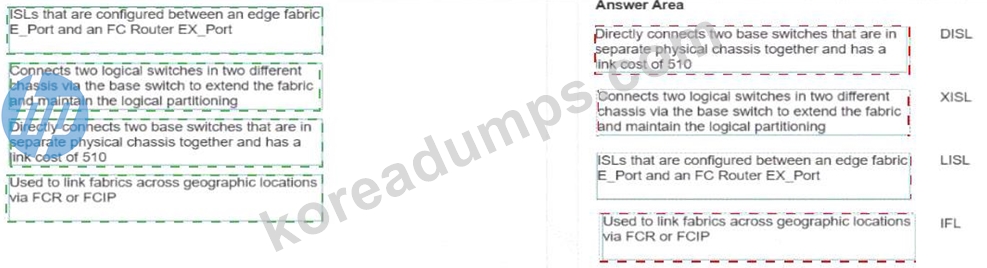
Explanation:
LISL: Directly connects two base switches that are in separate physical chassis together and has a link cost of
510
XISL: Connects two logical switches in two different chassis via the base switch to extend the fabric and maintain the logical partitioning DISL: ISLs that are configured between an edge fabric E_Port and an FC Router EX_Port IFL: Used to link fabrics across geographic locations via FCR or FCIP Brocade Virtual Fabrics (VF) allow a single physical switch to be partitioned into multiple logical switches, each with its own data and control planes. This architectural flexibility requires specialized Inter-Switch Link (ISL) types to maintain logical isolation across physical chassis.
LISL (Logical ISL): These are logical links that directly connect two Base Switches located in separate physical chassis. A defining characteristic of an LISL in Brocade Fabric OS is its default link cost of 510, which ensures it is typically used only for specific inter-fabric control traffic unless manually adjusted.
XISL (Extended ISL): An XISL is a transport link used to connect two logical switches residing in different physical chassis by tunneling through the Base Fabric. This allows the administrator to extend a single logical fabric across multiple physical devices while maintaining strict logical partitioning and reducing the number of physical cables required between chassis.
DISL (Dedicated ISL): These links are specifically configured between an edge fabric E_Port and an FC Router EX_Port. They are used in Fibre Channel Routing (FCR) topologies to provide a dedicated path for inter-fabric traffic between a standard fabric and a meta-fabric router.
IFL (Inter-Fabric Link): IFLs are the foundational links used to connect disparate fabrics across geographic locations. They utilize either Fibre Channel Routing (FCR) or FCIP tunneling to enable communication between devices in different fabrics without merging them into a single logical entity. This is a key component for large-scale disaster recovery and data distribution architectures where fabric stability and distance are primary concerns.
질문 # 56
A customer requires the highest possible random read IOPS for an OLTP database while maintaining sub-millisecond latency. Which storage media should be prioritized?
정답:D
설명:
NVMe Storage Class Memory (SCM) delivers extremely low latency and exceptional random IOPS, making it ideal for OLTP workloads. SAS HDD and SATA SSD cannot match its latency profile, while tape is irrelevant for transactional applications.
질문 # 57
......
많은 사이트에서HP 인증HPE7-J01 인증시험대비자료를 제공하고 있습니다. 그중에서 KoreaDumps를 선택한 분들은HP 인증HPE7-J01시험통과의 지름길에 오른것과 같습니다. KoreaDumps는 시험에서 불합격성적표를 받으시면 덤프비용을 환불하는 서비스를 제공해드려 아무런 걱정없이 시험에 도전하도록 힘이 되어드립니다. KoreaDumps덤프를 사용하여 시험에서 통과하신 분이 전해주신 희소식이 KoreaDumps 덤프품질을 증명해드립니다.
HPE7-J01최신버전 인기 덤프자료: https://www.koreadumps.com/HPE7-J01_exam-braindumps.html
BONUS!!! KoreaDumps HPE7-J01 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=17yJf8l5vvEIFGk0YmwEC0yz2tYq-YMlN