DOWNLOAD the newest Itcertking MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1IHsLntuwQVd-gdUobI0PVu6J2x0LO-2A
Will you feel nervous when you are in the exam, and if you do, you can try our exam dumps.MLA-C01 Soft test engine can stimulate the real environment, through this , you can know the procedure of the real exam, so that you can release your nervous . And you can build up your confidence when you face the real exam. Besides, MLA-C01 Exam Dumps of us offer you free update for one year after purchasing, and our system will send the latest version to you automatically. We have online and offline chat service stuff, and if you have any questions, just have chat with them.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Real Exam Qty: | 65 (50 scored, 15 unscored) |
| Exam Price: | 150 USD |
| Exam Duration: | 130 minutes |
| Exam Format: | Multiple response, Ordering, Case study, Matching, Multiple choice |
| Passing Score: | 720 (scaled score 100–1000) |
| Available Languages: | Simplified Chinese, English, Japanese, Korean |
| Related Certifications: | AWS Certified Machine Learning - Specialty AWS Certified AI Practitioner |
| Certificate Validity Period: | 3 years |
| Recommended Training: | AWS Training and Certification AWS Certified Machine Learning Engineer - Associate Official Exam Guide |
| Exam Registration: | Pearson VUE Registration AWS Certification Portal |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE testing centers |
| Pre Condition: | Recommended: 1+ year hands-on experience with AWS services and machine learning engineering; familiarity with Amazon SageMaker and related ML services. No mandatory prerequisite exams. |
| Official Syllabus URL: | https://docs.aws.amazon.com/aws-certification/latest/machine-learning-engineer-associate-01/machine-learning-engineer-associate-01.html |
>> MLA-C01 Valid Test Notes <<
Do you feel that you are always nervous in your actual MLA-C01 exam and difficult to adapt yourself to the real exam? If you answer is yes, I think you can try to use the software version of our MLA-C01 exam quiz. I believe the software version of our MLA-C01 trianing guide will be best choice for you, because the software version can simulate real test environment, you can feel the atmosphere of the MLA-C01 exam in advance by the software version.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 82
A company is building an enterprise AI platform. The company must catalog models for production, manage model versions, and associate metadata such as training metrics with models. The company needs to eliminate the burden of managing different versions of models.
Which solution will meet these requirements?
Answer: B
Explanation:
The correct answer is B. Use the Amazon SageMaker Model Registry to catalog the models. Create model groups for each model to manage the model versions and to maintain associated metadata.
The Amazon SageMaker Model Registry is a managed repository within SageMaker designed specifically for production-grade ML model lifecycle management. It allows organizations to catalog models, track multiple versions of a model, associate rich metadata, and manage deployment workflows in a scalable, controlled manner. Each model can belong to a model group, which acts as a container for all versions of that particular model. Versions can store training metrics, hyperparameters, model artifacts, and other key metadata, enabling reproducibility, auditing, and automated promotion between stages (e.g., Staging # Production).
Option A, while using the Model Registry, relies on manually tagging versions and creating key-value pairs to store metadata. This approach is error-prone, lacks structured versioning, and does not integrate with SageMaker's deployment pipelines.
Options C and D suggest using Amazon ECR repositories. While ECR can store containerized model artifacts, it is not designed for ML-specific metadata, versioning, or automated model stage transitions. Using ECR alone would require custom-built solutions for metadata management, auditing, and version tracking, adding unnecessary operational overhead.
By leveraging the Model Registry with model groups, organizations can automate promotions, apply approval workflows, and track lineage efficiently, fully aligning with AWS best practices for ML model development and production readiness. This ensures compliance, reproducibility, and reduces operational complexity in enterprise AI platforms.
Using the Model Registry and model groups is the standard AWS-recommended approach for enterprise-scale model cataloging and version control, enabling teams to focus on model improvement rather than infrastructure management.
NEW QUESTION # 83
An ML engineer has developed a binary classification model outside of Amazon SageMaker. The ML engineer needs to make the model accessible to a SageMaker Canvas user for additional tuning.
The model artifacts are stored in an Amazon S3 bucket. The ML engineer and the Canvas user are part of the same SageMaker domain.
Which combination of requirements must be met so that the ML engineer can share the model with the Canvas user? (Choose two.)
Answer: D,E
NEW QUESTION # 84
An ML engineer needs to deploy ML models to get inferences from large datasets in an asynchronous manner. The ML engineer also needs to implement scheduled monitoring of data quality for the models and must receive alerts when changes in data quality occur.
Which solution will meet these requirements?
Answer: B
Explanation:
This requirement combines asynchronous inference on large datasets with automated data quality monitoring and alerting. AWS documentation explicitly recommends Amazon SageMaker batch transform for large- scale, asynchronous inference workloads. Batch transform jobs process large datasets stored in Amazon S3 without requiring a persistent endpoint, making them cost-effective and scalable.
For data quality monitoring, Amazon SageMaker Model Monitor is the AWS-native solution. Model Monitor can be scheduled to analyze inference data, compare it against a baseline, and detect data quality issues such as missing values, schema changes, or statistical drift. When violations occur, Model Monitor emits metrics to Amazon CloudWatch, where alarms can trigger alerts.
Options A, B, and C lack ML-aware data quality monitoring capabilities. AWS Glue and Batch are not designed for model data quality analysis, and CloudTrail tracks API activity-not data quality.
AWS best practices clearly position Batch Transform + Model Monitor as the correct architecture for asynchronous inference with automated monitoring and alerting.
Therefore, Option D is the correct and AWS-verified solution.
NEW QUESTION # 85
A data scientist is evaluating different binary classification models. A false positive result is 5 times more expensive (from a business perspective) than a false negative result.
The models should be evaluated based on the following criteria:
1) Must have a recall rate of at least 80%
2) Must have a false positive rate of 10% or less
3) Must minimize business costs
After creating each binary classification model, the data scientist generates the corresponding confusion matrix.
Which confusion matrix represents the model that satisfies the requirements?
Answer: A
Explanation:
The following calculations are required:
TP = True Positive
FP = False Positive
FN = False Negative
TN = True Negative
FN = False Negative
Recall = TP / (TP + FN)
False Positive Rate (FPR) = FP / (FP + TN)
Cost = 5 * FP + FN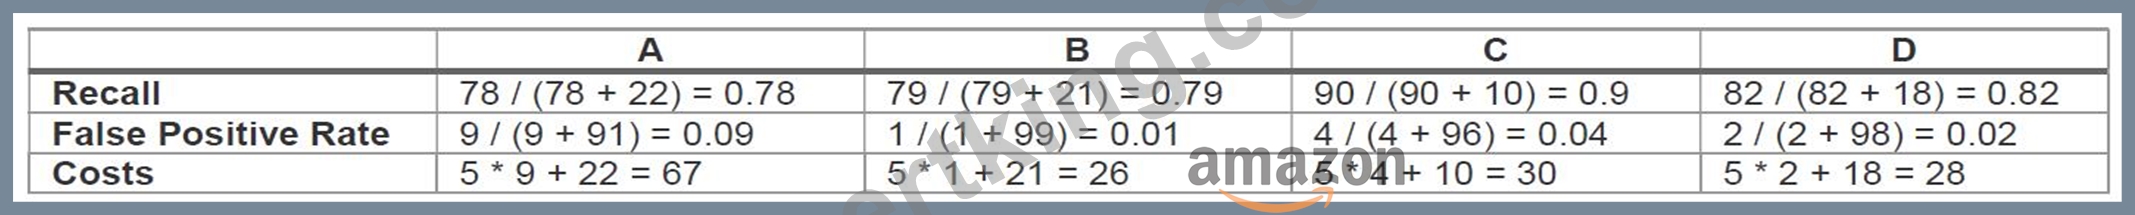
NEW QUESTION # 86
A company has implemented a data ingestion pipeline for sales transactions from its ecommerce website. The company uses Amazon Data Firehose to ingest data into Amazon OpenSearch Service. The buffer interval of the Firehose stream is set for 60 seconds. An OpenSearch linear model generates real-time sales forecasts based on the data and presents the data in an OpenSearch dashboard.
The company needs to optimize the data ingestion pipeline to support sub-second latency for the real-time dashboard.
Which change to the architecture will meet these requirements?
Answer: A
NEW QUESTION # 87
......
New MLA-C01 Braindumps Pdf: https://www.itcertking.com/MLA-C01_exam.html
BTW, DOWNLOAD part of Itcertking MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1IHsLntuwQVd-gdUobI0PVu6J2x0LO-2A