The top personal and professional Microsoft DP-750 certification exam benefits are recognition of skills, updated knowledge, more career opportunities, instant promotion, and increase in salary, etc. If your answer is yes first of all you have to enroll in the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exam and put all your efforts to pass this career advancement certification exam. Are you looking for the right and recommended way to pass the Microsoft DP-750 exam?
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
>> Valid Braindumps DP-750 Ppt <<
This DP-750 certification assists you to put your career on the right track and helps you to achieve your career goals in a short time period. There are several personal and professional benefits that you can gain after passing the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exam. The prominent DP-750 certification benefits include validation of skills and knowledge, more career opportunities, instant rise in salary, quick promotion, etc.
NEW QUESTION # 39
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements.
What should you do?
Answer: A
Explanation:
The correct answer is A. Photon is Azure Databricks ' native vectorized query engine, written in C++, designed to accelerate data ingestion and SQL-heavy workloads significantly over the standard Spark JVM path. Enabling it on a job compute cluster directly addresses Contoso ' s requirement for ' fast and consistent performance for BI workloads ' and ' production ingestion workloads that can scale automatically during telemetry spikes. ' Photon integrates transparently - no code changes are needed - and pairs well with autoscaling job clusters to handle the bursty 40,000-sensor telemetry load.
Option B contradicts the isolation requirement: Contoso explicitly needs production and development separated, not merged onto shared compute. Option C with a fixed large node gives peak capacity at all times, driving up costs even during quiet periods. Option D disabling autoscaling is the opposite of what ' s needed
- telemetry spikes require elastic scaling, not a locked node count.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/photon
NEW QUESTION # 40
You need to deploy Declarative Automation Bundles to a development environment. The solution must support automated and repeatable deployments across environments.
What should you use?
Answer: C
Explanation:
The Databricks CLI contains the bundle command group for validating, deploying, and running Declarative Automation Bundles. CLI commands can be executed consistently from developer terminals or CI/CD pipelines, making deployments automated, repeatable, and suitable for multiple target environments. The Databricks SDK for Python can manage workspace APIs programmatically, but it is not the standard bundle deployment interface required here. Git folders provide source-control integration inside the workspace but do not deploy bundle-defined resources. The Jobs UI supports interactive creation and management of jobs, which introduces manual steps and does not provide the same infrastructure-as-code workflow. Using commands such as databricks bundle validate and databricks bundle deploy -t dev directly satisfies the automated development deployment requirement. Microsoft Learn
NEW QUESTION # 41
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Tabid.
Table! is written by batch jobs every hour and is queried frequently by filtering two columns named Customerld and EventDate.
You expect Table1 to grow significantly over time.
The rows in Table1 are frequently updated and deleted to support compliance requests.
You need to keep query performance consistent as Table1 grows. The solution must minimize update and deletion effort.
What should you include in the solution? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.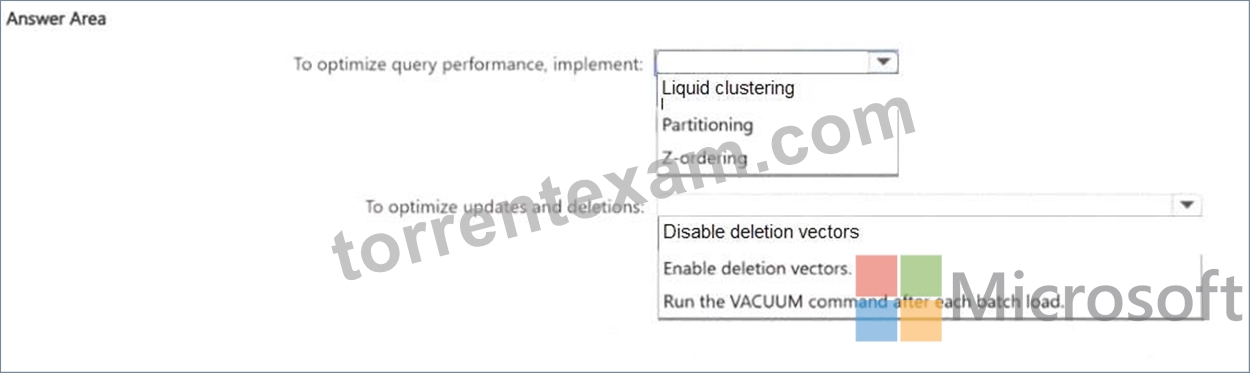
Answer:
Explanation: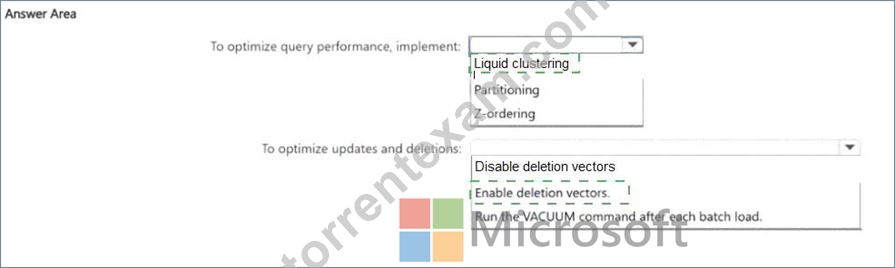
Explanation:
Two features work together to keep performance consistent and update costs low:
OPTIMIZE with ZORDER BY (CustomerId, EventDate). Z-Ordering co-locates rows with the same CustomerId and EventDate values in the same Parquet files. When a query filters on those columns, the Delta engine uses file statistics to skip files that can't possibly contain matching rows (data skipping). As the table grows, skipping scales proportionally - query time stays consistent.
Deletion Vectors (delta.enableDeletionVectors = true). When a row is updated or deleted, instead of rewriting the entire Parquet file, Delta marks the affected row in a small companion deletion vector file. This dramatically reduces write amplification for the frequent compliance-driven updates and deletions the question describes. Actual file rewrites are deferred to the next OPTIMIZE run.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/data-skipping
NEW QUESTION # 42
What happens if incoming data violates Delta table schema?
Answer: C
Explanation:
Delta Lake enforces schema by default. If incoming data does not match schema, the write operation fails unless schema evolution is explicitly enabled. It does not auto-cast or append invalid data. Overwriting would require explicit command.
NEW QUESTION # 43
You use Declarative Automation Bundles to manage two jobs and an app.
You need to deploy the bundle to development and production environments. The solution must meet the following requirements:
* Deploy the app to both environments.
* Deploy only one job to development.
* Minimize administrative effort.
What should you use?
Answer: C
Explanation:
The targets mapping defines environment-specific deployment configurations within one databricks.yml file.
Development and production targets can apply different resource settings or exclusions while sharing the bundle's common definitions. This allows the app to be deployed to both environments and limits the development deployment to the required job without maintaining duplicate configuration files. Separate YAML files would duplicate shared settings and increase maintenance effort. The resources mapping declares jobs, pipelines, apps, and other Databricks resources but does not independently provide environment-specific deployment behavior. Variables provide reusable values and substitutions; they are not the primary mechanism for defining deployment environments. Declarative Automation Bundle targets are explicitly intended to model configurations such as development, staging, and production in a single bundle. Microsoft Learn
NEW QUESTION # 44
......
There are a number of distinctions of our DP-750 Exam Questions that make it superior to those offered in the market. Firstly, you will find that there are three different vesions of our DP-750 learning guide: the PDF, Software and APP online. Though the content is the same, but the displays are all different. And you can study in all kind of conditions if you have three of them. Secondly, the prices of every version are favourable. And you can buy the Value Pack with discounted price.
Valid Dumps DP-750 Files: https://www.torrentexam.com/DP-750-exam-latest-torrent.html