What's more, part of that Real4dumps Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=1yVPdqbwUrjeF57PyYdsqo2TTwfTWciaE
Never was it so easier to get through an exam like Professional-Machine-Learning-Engineer exam as it has become now with the help of our high quality Professional-Machine-Learning-Engineer exam questions by our company. You can get the certification just as easy as pie. As a company which has been in this field for over ten year, we have become a famous brand. And our Professional-Machine-Learning-Engineer Study Materials can stand the test of the market and the candidates all over the world. Besides, the prices for our Professional-Machine-Learning-Engineer learning guide are quite favourable.
| Section | Weight | Objectives |
|---|---|---|
| Collaborate to manage data and models | 16% | - Address data privacy, compliance, and governance - Manage datasets and features in Vertex AI - Organize and prepare enterprise data
|
| Train and deploy models | 20% | - Configure training jobs and environments - Deploy models for online, batch, and streaming prediction - Implement generative AI deployment patterns - Use Vertex AI deployment features and infrastructure |
| Automate and orchestrate ML pipelines | 18% | - Use Vertex AI Pipelines, TFX, and other orchestration tools - Automate retraining and model updates - Design end-to-end ML workflows - Implement CI/CD for ML systems |
| Monitor and optimize AI solutions | 16% | - Optimize cost, latency, and resource usage - Monitor model performance, fairness, and drift - Troubleshoot and maintain production systems - Monitor data quality and pipeline health |
| Architect low-code AI solutions | 12% | - Design solutions using Vertex AI Studio, Model Garden, and Agent Builder - Apply responsible AI principles to low-code designs - Identify use cases for low-code/no-code AI tools |
| Scale prototypes into AI models | 18% | - Design and run experiments - Select appropriate model architectures and frameworks - Work with foundation models and generative AI techniques - Optimize model performance and generalization |
>> Study Professional-Machine-Learning-Engineer Reference <<
Our latest training material about Google certification Professional-Machine-Learning-Engineer exam is developed by Real4dumps's professional team's constantly study the outline. It can help a lot of people achieve their dream. In today's competitive IT profession, if you want to stabilize your own position, you will have to prove your professional knowledge and technology level. Google Certification Professional-Machine-Learning-Engineer Exam is a very good test to prove your ability. If you have a Google Professional-Machine-Learning-Engineer certification, your work will have a lot of change that wages and work position will increase quickly.
NEW QUESTION # 300
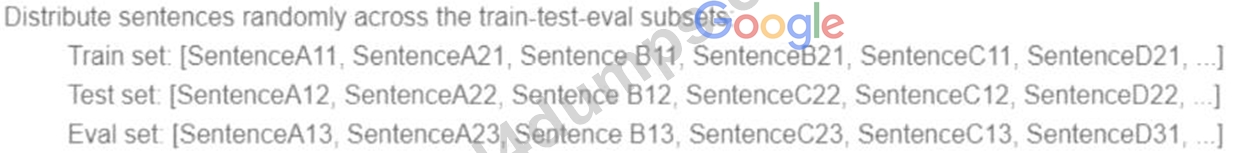
Your team is working on an NLP research project to predict political affiliation of authors based on articles they have written. You have a large training dataset that is structured like this: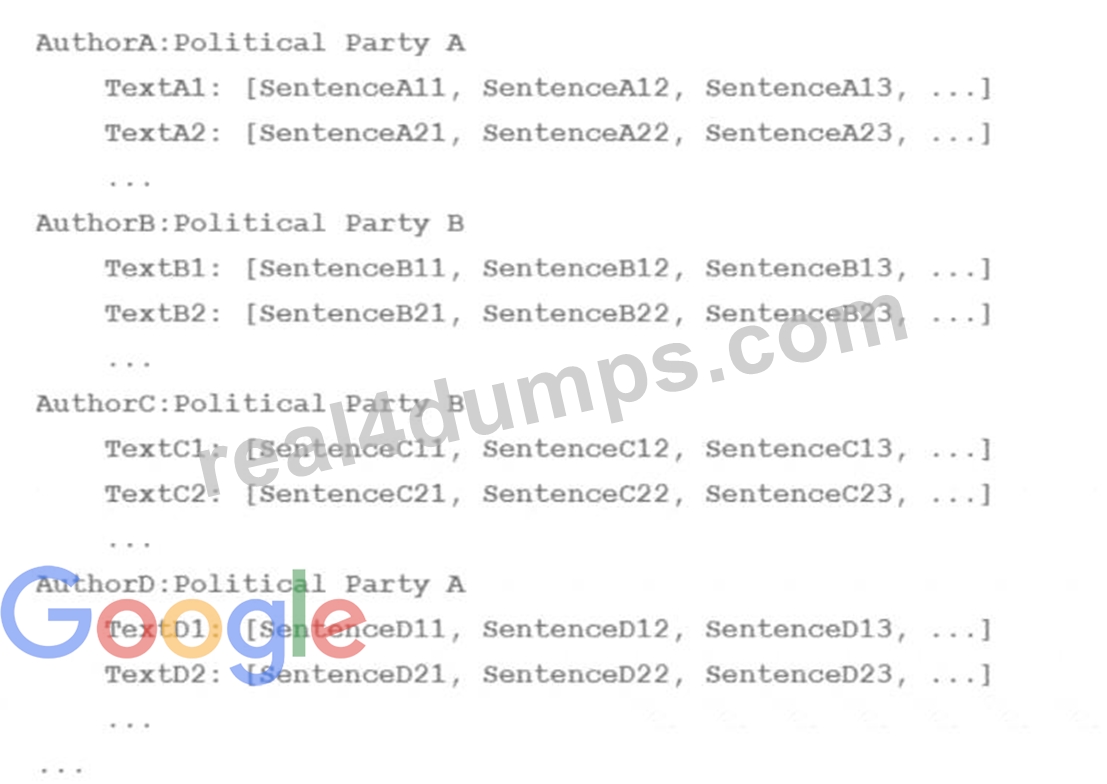
You followed the standard 80%-10%-10% data distribution across the training, testing, and evaluation subsets.
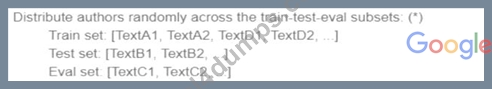
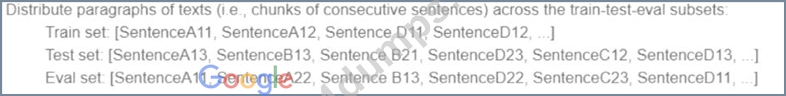
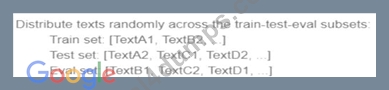
How should you distribute the training examples across the train-test-eval subsets while maintaining the
80-10-10 proportion?
Answer: D
Explanation:
The best way to distribute the training examples across the train-test-eval subsets while maintaining the
80-10-10 proportion is to use option C. This option ensures that each subset contains a balanced and representative sample of the different classes (Democrat and Republican) and the different authors. This way, the model can learn from a diverse and comprehensive set of articles and avoid overfitting or underfitting.
Option C also avoids the problem of data leakage, which occurs when thesame author appears in more than one subset, potentially biasing the model and inflating its performance. Therefore, option C is the most suitable technique for this use case.
NEW QUESTION # 301
You work for a magazine publisher and have been tasked with predicting whether customers will cancel their annual subscription. In your exploratory data analysis, you find that 90% of individuals renew their subscription every year, and only 10% of individuals cancel their subscription. After training a NN Classifier, your model predicts those who cancel their subscription with 99% accuracy and predicts those who renew their subscription with 82% accuracy. How should you interpret these results?
Answer: B
Explanation:
This is not a good result because the model is performing worse than predicting that people will always renew their subscription. This option has the following reasons:
* It indicates that the model is not learning from the data, but rather memorizing the majority class. Since
90% of the individuals renew their subscription every year, the model can achieve a 90% accuracy by simply predicting that everyone will renew their subscription, without considering the features or the patterns in the data. However, the model's accuracy for predicting those who renew their subscription is
* only 82%, which is lower than the baseline accuracy of 90%. This suggests that the model is overfitting to the minority class (those who cancel their subscription), and underfitting to the majority class (those who renew their subscription).
* It implies that the model is not useful for the business problem, as it cannot identify the customers who are at risk of churning. The goal of predicting whether customers will cancel their annual subscription is to prevent customer churn and increase customer retention. However, the model's accuracy for predicting those who cancel their subscription is 99%, which is too high and unrealistic, as it means that the model can almost perfectly identify the customers who will churn, without any false positives or false negatives. This may indicate that the model is cheating or exploiting some leakage in the data, such as a feature that reveals the outcome of the prediction. Moreover, the model's accuracy for predicting those who renew their subscription is 82%, which is too low and unreliable, as it means that the model can miss many customers who will churn, and falsely label them as renewing customers. This can lead to losing customers and revenue, and failing to take proactive actions to retain them.
References:
* How to Evaluate Machine Learning Models: Classification Metrics | Machine Learning Mastery
* Imbalanced Classification: Predicting Subscription Churn | Machine Learning Mastery
NEW QUESTION # 302
You are an AI engineer working for a popular video streaming platform. You built a classification model using PyTorch to predict customer churn. Each week, the customer retention team plans to contact customers identified as at-risk for churning with personalized offers. You want to deploy the model while minimizing maintenance effort. What should you do?
Answer: C
Explanation:
Deploying the model on Vertex AI with a batch prediction configuration is ideal for weekly inference jobs since the retention team needs predictions once per week. Scheduling batch predictions minimizes computational costs, and Vertex AI's endpoint management simplifies infrastructure setup without needing additional maintenance. Using Vertex AI's prebuilt containers also provides a flexible deployment pipeline for any future model updates. Options A and D do not suit batch needs, and GKE (Option B) requires more manual maintenance.
NEW QUESTION # 303
You need to execute a batch prediction on 100 million records in a BigQuery table with a custom TensorFlow DNN regressor model, and then store the predicted results in a BigQuery table. You want to minimize the effort required to build this inference pipeline. What should you do?
Answer: B
Explanation:
https://cloud.google.com/bigquery-ml/docs/reference/standard-sql/bigqueryml-syntax-inference-overview Predict the label, either a numerical value for regression tasks or a categorical value for classification tasks on DNN regresion.
NEW QUESTION # 304
Your company manages an ecommerce platform and has a large dataset of customer reviews. Each review has a positive, negative, or neutral label. You need to quickly prototype a sentiment analysis model that accurately predicts the sentiment labels of new customer reviews while minimizing time and cost. What should you do?
Answer: D
Explanation:
The keywords here are " quickly prototype " and " minimize time and cost. "
* Natural Language API: Google's pre-trained Natural Language API provides out-of-the-box sentiment analysis. It requires zero training time, zero infrastructure management, and no labeling effort. This is the fastest and most cost-effective way to get a baseline/prototype.
* Why other options are incorrect:
* Option A: Fine-tuning a BERT model is computationally expensive and requires significant engineering time.
* Option C: AutoML is a great secondary step if the API is not accurate enough, but it still requires time to train and evaluate, making it slower than the pre-trained API.
* Option D: Vectorizing text and training a regression model is unnecessarily complex for a standard sentiment classification task.
NEW QUESTION # 305
......
Do you want to choose a lifetime of mediocrity or become better and pursue your dreams? I believe you will have your own pursuit. Perhaps you do not know how to go better our Professional-Machine-Learning-Engineer learning engine will give you some help. The choice is like if a person is at a fork, and which way to go depends on his own decision. Our Professional-Machine-Learning-Engineer Study Materials have successfully helped a lot of candidates achieve their certifications and become better. Our Professional-Machine-Learning-Engineer learning guide will be your best choice.
Professional-Machine-Learning-Engineer Vce Files: https://www.real4dumps.com/Professional-Machine-Learning-Engineer_examcollection.html
What's more, part of that Real4dumps Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=1yVPdqbwUrjeF57PyYdsqo2TTwfTWciaE